PDF Reference sixth edition, Adobe Portable Document Format Version 1.7 (book 1) — page 2
44
CHAPTER 2
Overview
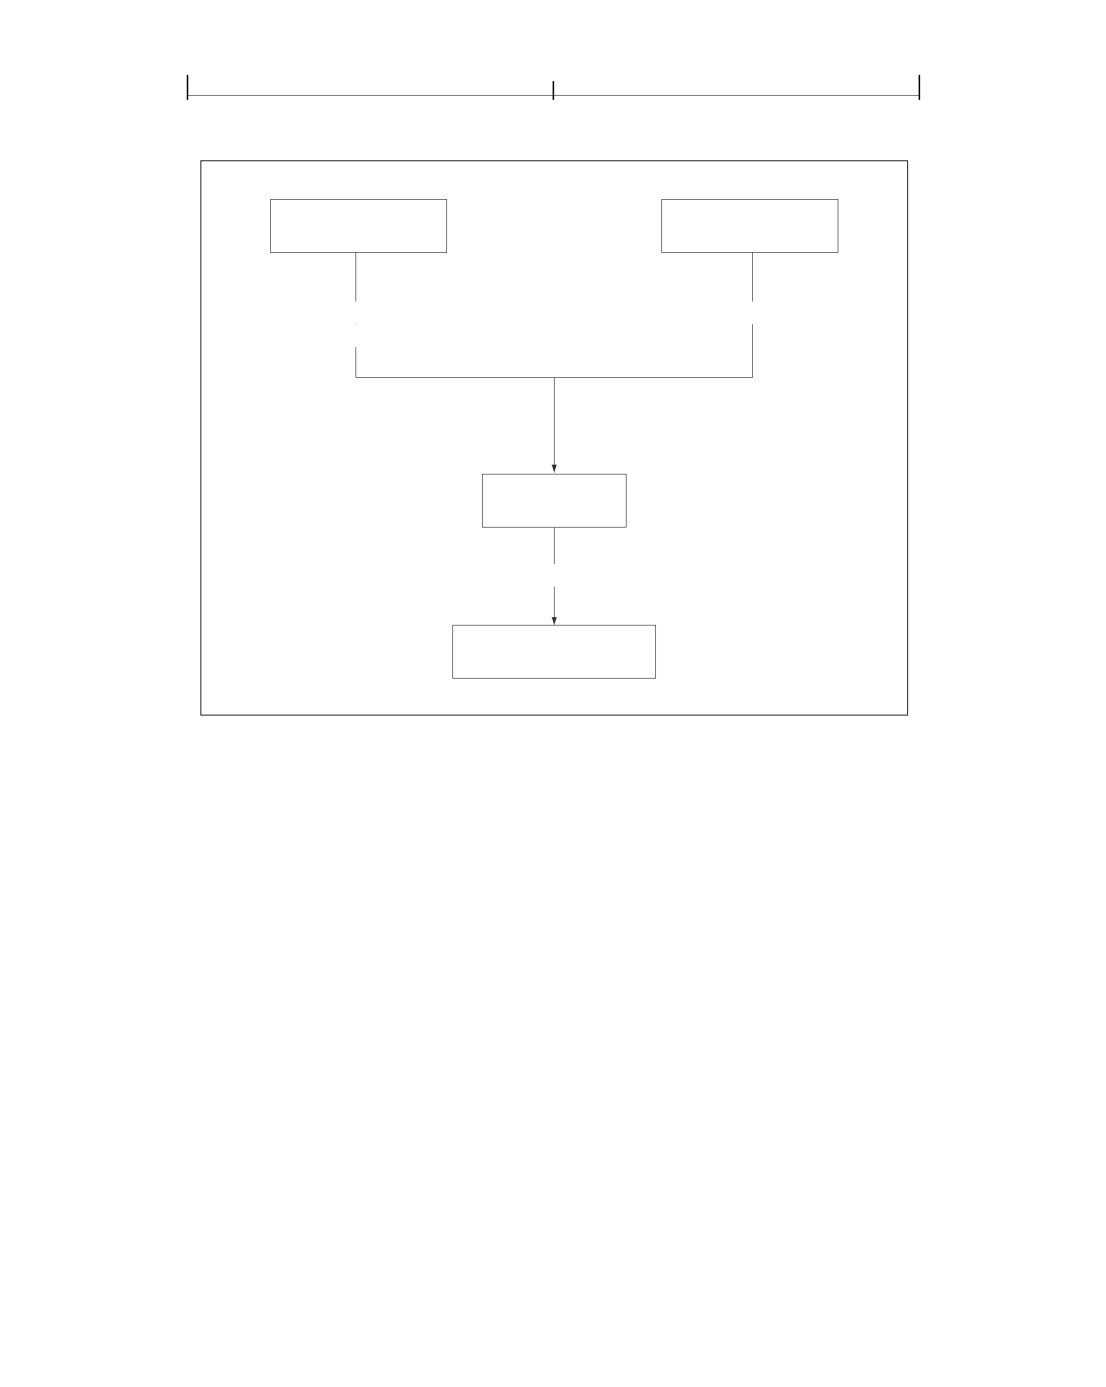
Macintosh application
Windows application
QuickDraw/
GDI
CoreGraphics
Adobe PDF
printer
PDF
Acrobat
FIGURE 2.1 Creating PDF files using the Adobe PDF printer
Instead of describing their printable output through API calls, some applications
produce PostScript page descriptions directly—either because of limitations in
the QuickDraw or GDI imaging models or because the applications run on plat-
forms such as DOS or UNIX®, where no system-level printer driver exists. Post-
Script files generated by such applications can be converted to PDF files using the
Acrobat Distiller® application (see Figure 2.2). Because PostScript and PDF share
the same Adobe imaging model, Distiller can preserve the exact graphical con-
tent of the PostScript file in the translation to PDF. Additionally, Distiller sup-
ports a PostScript language extension, called pdfmark, that allows the producing
application to embed instructions in the PostScript file for creating hypertext
links, logical structure, and other interactive and document interchange features
of PDF. Again, the resulting PDF file can be viewed with a viewer application,
such as Acrobat, on any supported platform.
45
SECTION 2.4
PDF and the PostScript Language
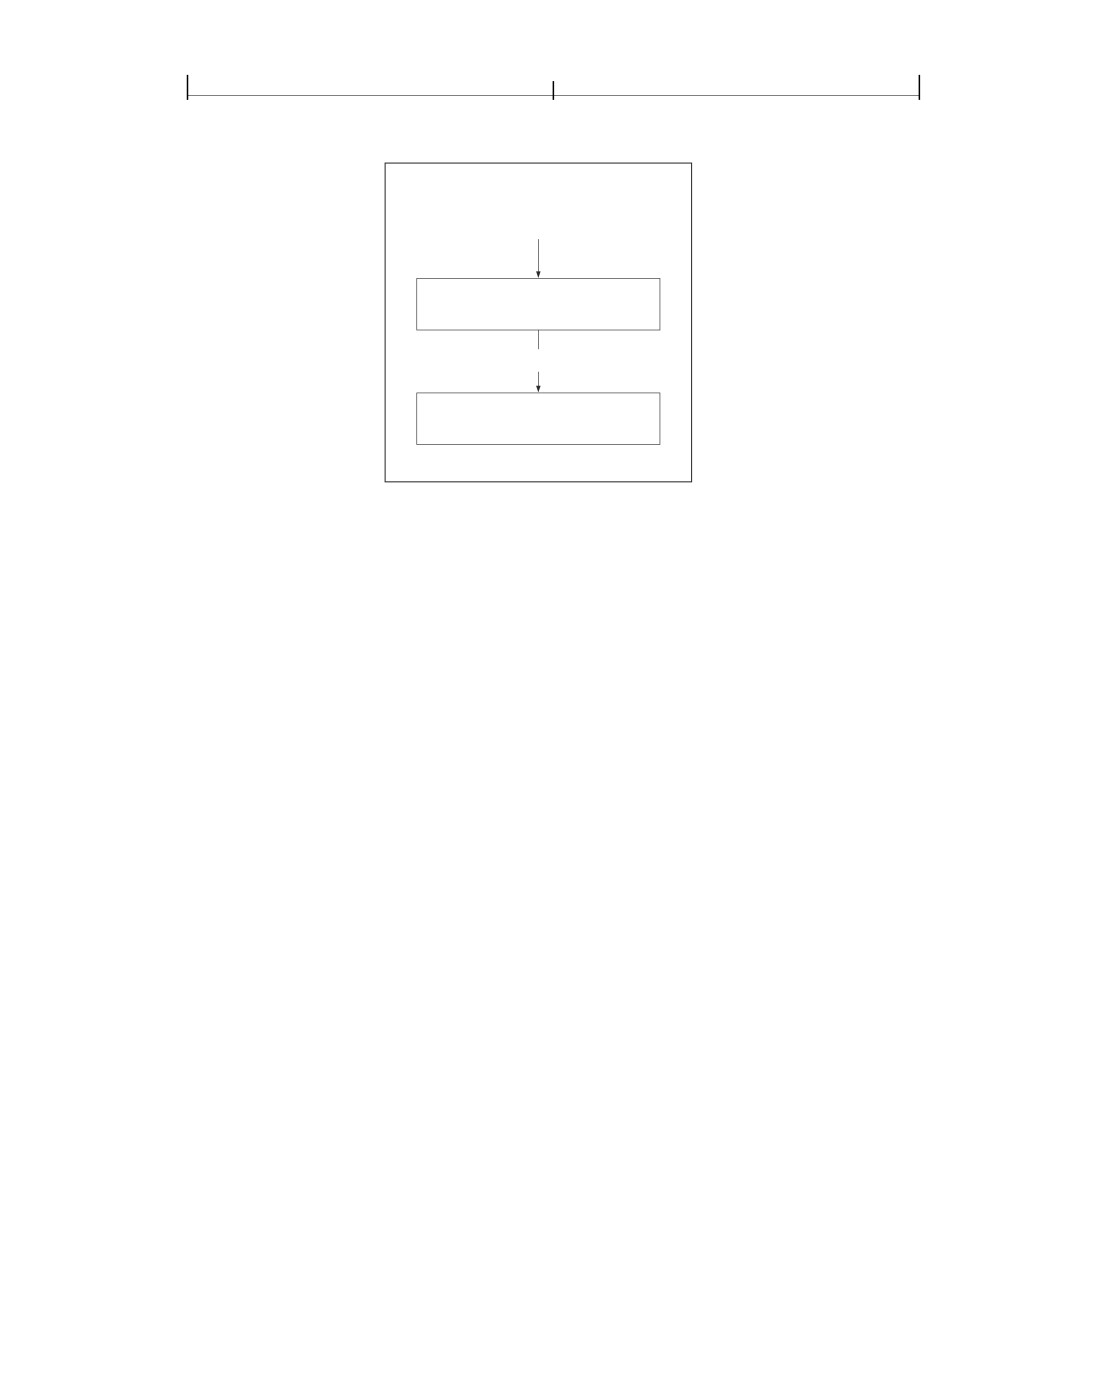
PostScript
page description
Acrobat Distiller
PDF
Acrobat
FIGURE 2.2 Creating PDF files using Acrobat Distiller
2.4
PDF and the PostScript Language
The PDF operators for setting the graphics state and painting graphics objects are
similar to the corresponding operators in the PostScript language. Unlike Post-
Script, however, PDF is not a full-scale programming language; it trades reduced
flexibility for improved efficiency and predictability. PDF therefore differs from
PostScript in the following significant ways:
• PDF enforces a strictly defined file structure that allows an application to ac-
cess parts of a document in arbitrary order.
• To simplify the processing of content streams, PDF does not include common
programming language features such as procedures, variables, and control con-
structs.
• PDF files contain information such as font metrics to ensure viewing fidelity.
• A PDF file may contain additional information that is not directly connected
with the imaging model, such as hypertext links for interactive viewing and
logical structure information for document interchange.
Because of these differences, a PDF file generally cannot be transmitted directly
to a PostScript output device for printing (although a few such devices do also
46
CHAPTER 2
Overview
support PDF directly). An application printing a PDF document to a PostScript
device must follow these steps:
1. Insert procedure sets containing PostScript procedure definitions to implement
the PDF operators.
2. Extract the content for each page. Each content stream is essentially the script
portion of a traditional PostScript program using very specific procedures,
such as m for moveto and l for lineto.
3. Decode compressed text, graphics, and image data as necessary. The compres-
sion filters used in PDF are compatible with those used in PostScript; they may
or may not be supported, depending on the LanguageLevel of the target output
device.
4. Insert any needed resources, such as fonts, into the PostScript file. These can
be either the original fonts or suitable substitute fonts based on the font met-
rics in the PDF file. Fonts may need to be converted to a format that the Post-
Script interpreter recognizes, such as Type 1 or Type 42.
5. Put the information in the correct order. The result is a traditional PostScript
program that fully represents the visual aspects of the document but no longer
contains PDF elements such as hypertext links, annotations, and bookmarks.
6. Transmit the PostScript program to the output device.
CHAPTER 3
Syntax
3
This chapter covers everything about the syntax of PDF at the object, file, and
document level. It sets the stage for subsequent chapters, which describe how the
contents of a PDF file are interpreted as page descriptions, interactive
navigational aids, and application-level logical structure.
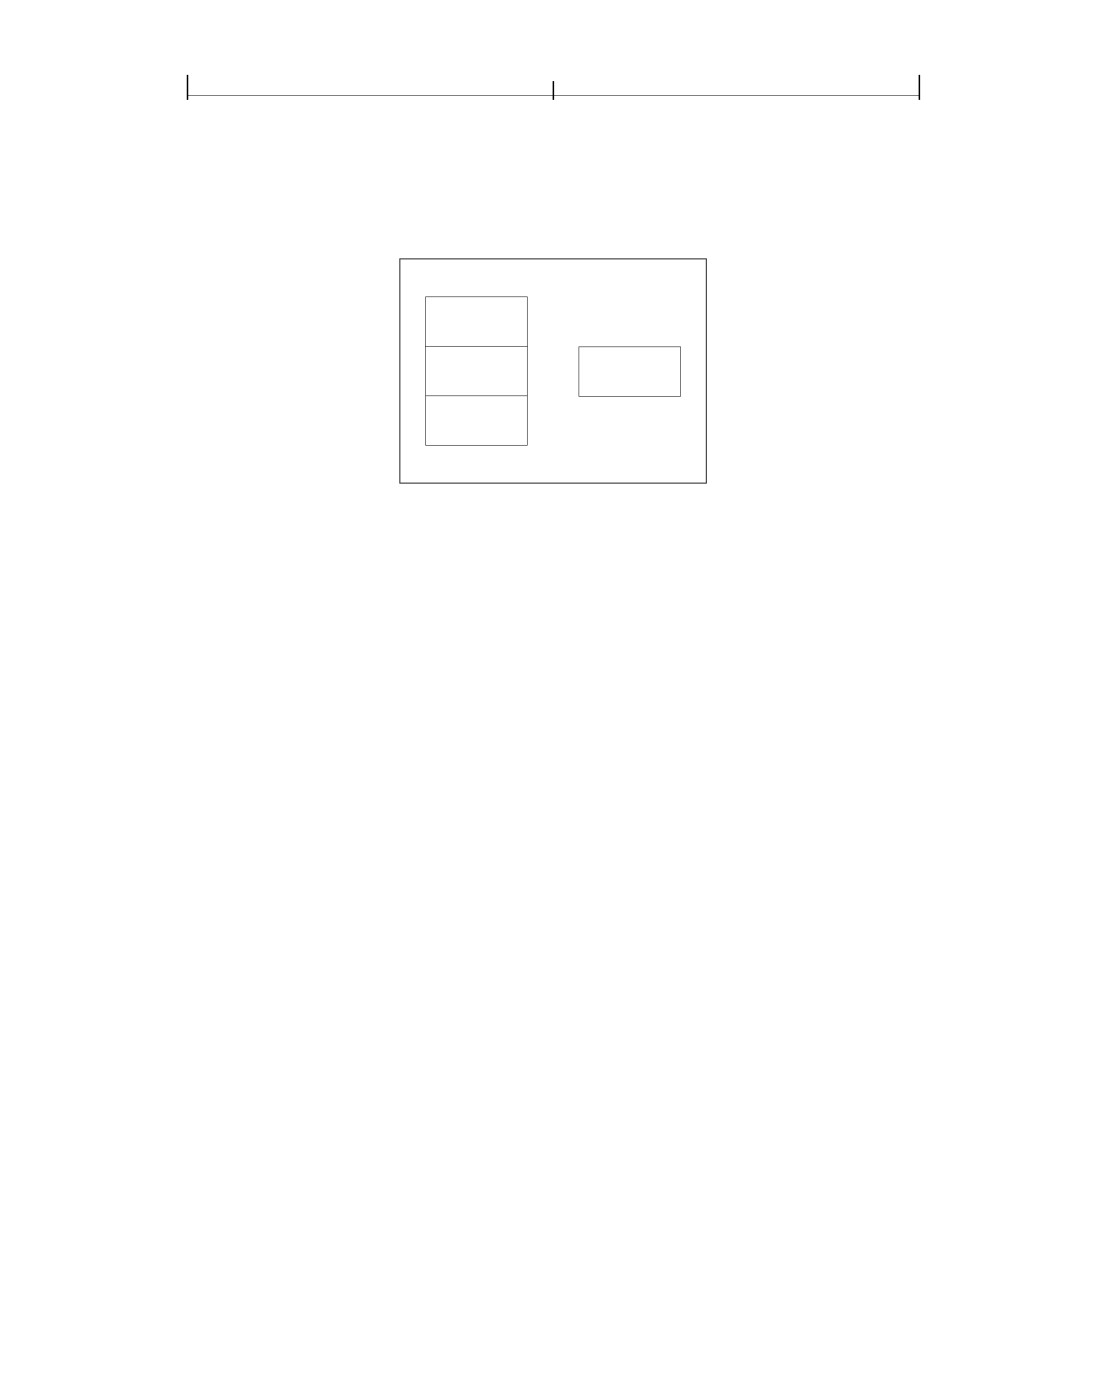
PDF syntax is best understood by thinking of it in four parts, as shown in Figure
3.1:
• Objects. A PDF document is a data structure composed from a small set of
basic types of data objects. Section 3.1, “Lexical Conventions,” describes the
character set used to write objects and other syntactic elements. Section 3.2,
“Objects,” describes the syntax and essential properties of the objects. Section
3.2.7, “Stream Objects,” provides complete details of the most complex data
type, the stream object.
• File structure. The PDF file structure determines how objects are stored in a
PDF file, how they are accessed, and how they are updated. This structure is
independent of the semantics of the objects. Section 3.4, “File Structure,” de-
scribes the file structure. Section 3.5, “Encryption,” describes a file-level mech-
anism for protecting a document’s contents from unauthorized access.
• Document structure. The PDF document structure specifies how the basic ob-
ject types are used to represent components of a PDF document: pages, fonts,
annotations, and so forth. Section 3.6, “Document Structure,” describes the
overall document structure; later chapters address the detailed semantics of the
components.
• Content streams. A PDF content stream contains a sequence of instructions de-
scribing the appearance of a page or other graphical entity. These instructions,
while also represented as objects, are conceptually distinct from the objects that
47
48
CHAPTER 3
Syntax
represent the document structure and are described separately. Section 3.7,
“Content Streams and Resources,” discusses PDF content streams and their as-
sociated resources.
Objects
File
Content
structure
stream
Document
structure
FIGURE 3.1 PDF components
In addition, this chapter describes some data structures, built from basic objects,
that are so widely used that they can almost be considered basic object types in
their own right. These objects are covered in Sections 3.8, “Common Data
Structures”; 3.9, “Functions”; and 3.10, “File Specifications.”
PDF’s object and file syntax is also used as the basis for other file formats. These
include the Forms Data Format (FDF), described in Section 8.6.6, “Forms Data
Format,” and the Portable Job Ticket Format
(PJTF), described in Adobe
Technical Note #5620, Portable Job Ticket Format.
3.1
Lexical Conventions
At the most fundamental level, a PDF file is a sequence of 8-bit bytes. These bytes
can be grouped into tokens according to the syntax rules described below. One or
more tokens are assembled to form higher-level syntactic entities, principally
objects, which are the basic data values from which a PDF document is
constructed.
PDF can be entirely represented using byte values corresponding to the visible
printable subset of the ASCII character set, plus white space characters such as
space, tab, carriage return, and line feed characters. ASCII is the American
Standard Code for Information Interchange, a widely used convention for
49
SECTION 3.1
Lexical Conventions
encoding a specific set of 128 characters as binary numbers. However, a PDF file
is not restricted to the ASCII character set; it can contain arbitrary 8-bit bytes,
subject to the following considerations:
• The tokens that delimit objects and that describe the structure of a PDF file are
all written in the ASCII character set, as are all the reserved words and the
names used as keys in standard dictionaries.
• The data values of certain types of objects—strings and streams—can be but
need not be written entirely in ASCII. For the purpose of exposition (as in this
book), ASCII representation is preferred. However, in actual practice, data that
is naturally binary, such as sampled images, is represented directly in binary for
compactness and efficiency.
• A PDF file containing binary data must be transported and stored by means
that preserve all bytes of the file faithfully; that is, as a binary file rather than a
text file. Such a file is not portable to environments that impose reserved char-
acter codes, maximum line lengths, end-of-line conventions, or other restric-
tions.
Note: In this chapter, the term character is synonymous with byte and merely refers
to a particular 8-bit value. This usage is entirely independent of any logical meaning
that the value may have when it is treated as data in specific contexts, such as repre-
senting human-readable text or selecting a glyph from a font.
3.1.1
Character Set
The PDF character set is divided into three classes, called regular, delimiter, and
white-space characters. This classification determines the grouping of characters
into tokens, except within strings, streams, and comments; different rules apply
in those contexts.
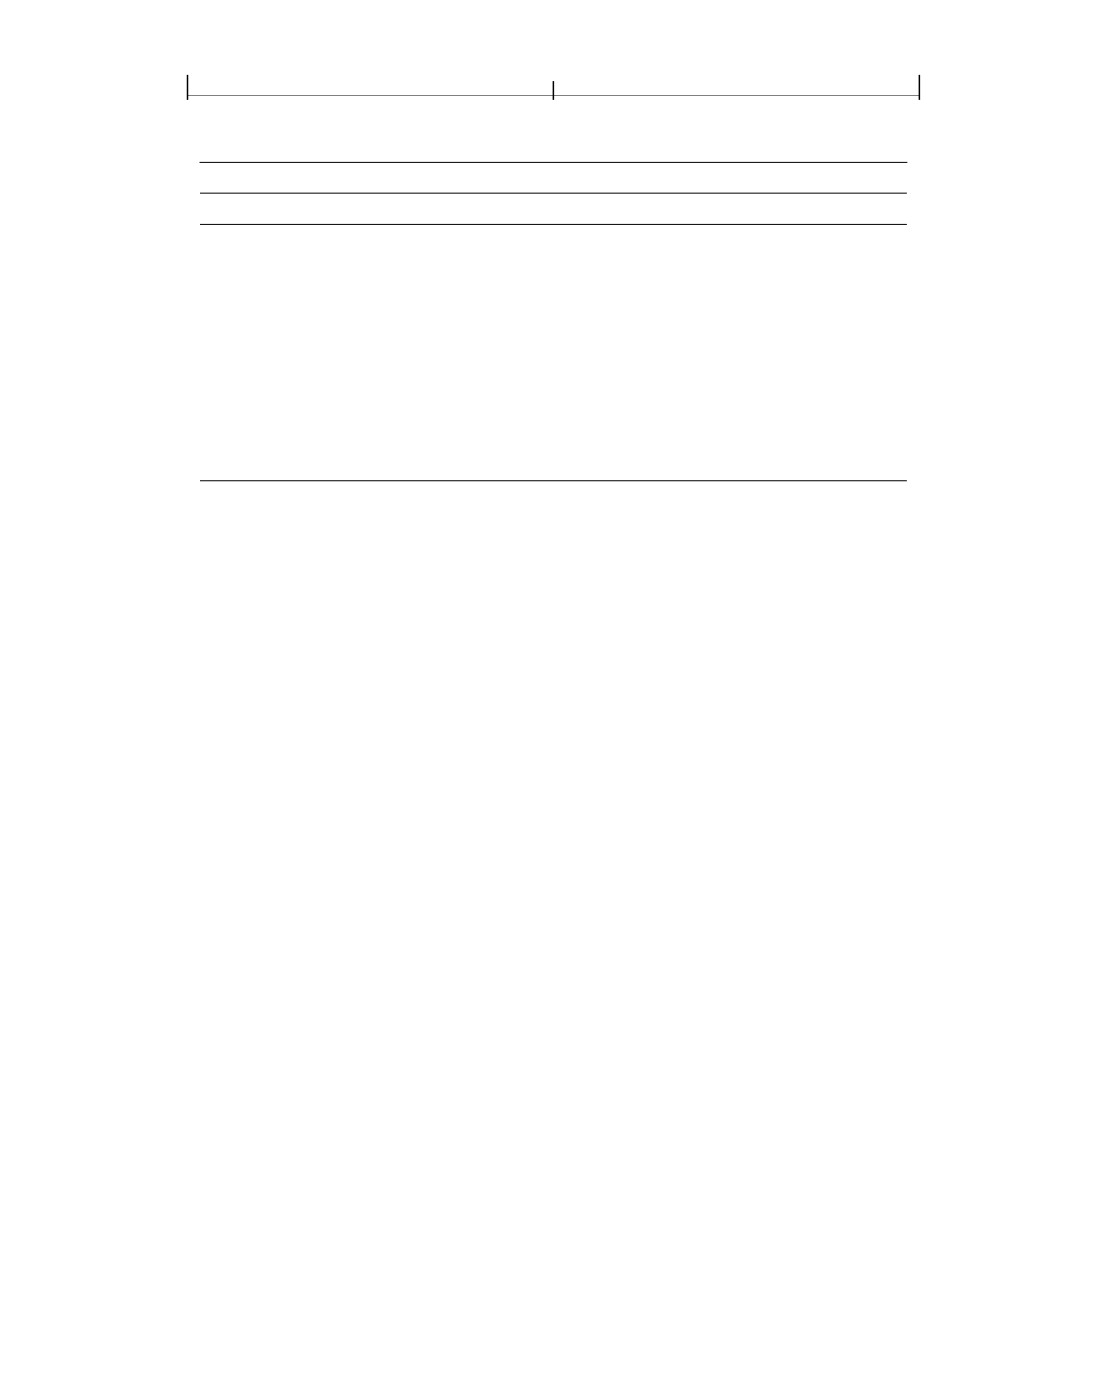
White-space characters (see Table 3.1) separate syntactic constructs such as names
and numbers from each other. All white-space characters are equivalent, except
in comments, strings, and streams. In all other contexts, PDF treats any sequence
of consecutive white-space characters as one character.
50
CHAPTER 3
Syntax
TABLE 3.1 White-space characters
DECIMAL
HEXADECIMAL
OCTAL
NAME
0
00
000
Null (NUL)
9
09
011
Tab (HT)
10
0A
012
Line feed (LF)
12
0C
014
Form feed (FF)
13
0D
015
Carriage return (CR)
32
20
040
Space (SP)
The carriage return (CR) and line feed (LF) characters, also called newline
characters, are treated as end-of-line
(EOL) markers. The combination of a
carriage return followed immediately by a line feed is treated as one EOL marker.
For the most part, EOL markers are treated the same as any other white-space
characters. However, sometimes an EOL marker is required or recommended—
that is, the following token must appear at the beginning of a line.
Note: The examples in this book illustrate a recommended convention for arranging
tokens into lines. However, the examples’ use of white space for indentation is purely
for clarity of exposition and is not recommended for practical use.
The delimiter characters (, ), <, >, [, ], {, }, /, and % are special. They delimit
syntactic entities such as strings, arrays, names, and comments. Any of these
characters terminates the entity preceding it and is not included in the entity.
All characters except the white-space characters and delimiters are referred to as
regular characters. These characters include 8-bit binary characters that are
outside the ASCII character set. A sequence of consecutive regular characters
comprises a single token.
Note: PDF is case-sensitive; corresponding uppercase and lowercase letters are con-
sidered distinct.
51
SECTION 3.2
Objects
3.1.2
Comments
Any occurrence of the percent sign character (%) outside a string or stream
introduces a comment. The comment consists of all characters between the
percent sign and the end of the line, including regular, delimiter, space, and tab
characters. PDF ignores comments, treating them as if they were single white-
space characters. That is, a comment separates the token preceding it from the
one following it; thus, the PDF fragment
abc% comment { /% ) blah blah blah
123
is syntactically equivalent to just the tokens abc and 123.
Comments (other than the %PDF−n.m and %%EOF comments described in
Section
3.4,
“File Structure”) have no semantics. They are not necessarily
preserved by applications that edit PDF files (see implementation note 2 in
Appendix H). In particular, there is no PDF equivalent of the PostScript
document structuring conventions (DSC).
3.2
Objects
PDF supports eight basic types of objects:
• Boolean values
• Integer and real numbers
• Strings
• Names
• Arrays
• Dictionaries
• Streams
• The null object
Objects may be labeled so that they can be referred to by other objects. A labeled
object is called an indirect object.
52
CHAPTER 3
Syntax
The following sections describe each object type, as well as how to create and
refer to indirect objects.
3.2.1
Boolean Objects
PDF provides boolean objects identified by the keywords true and false. Boolean
objects can be used as the values of array elements and dictionary entries, and can
also occur in PostScript calculator functions as the results of boolean and
relational operators and as operands to the conditional operators if and ifelse (see
Section 3.9.4, “Type 4 (PostScript Calculator) Functions”).
3.2.2
Numeric Objects
PDF provides two types of numeric objects: integer and real. Integer objects rep-
resent mathematical integers within a certain interval centered at 0. Real objects
approximate mathematical real numbers, but with limited range and precision;
they are typically represented in fixed-point form rather than floating-point
form. The range and precision of numbers are limited by the internal
representations used in the computer on which the PDF consumer application is
running; Appendix C gives these limits for typical implementations.
An integer is written as one or more decimal digits optionally preceded by a sign:
123
43445
+17
−98
0
The value is interpreted as a signed decimal integer and is converted to an integer
object. If it exceeds the implementation limit for integers, it is converted to a real
object.
A real value is written as one or more decimal digits with an optional sign and a
leading, trailing, or embedded period (decimal point):
34.5
−3.62
+123.6
4.
−.002
0.0
The value is interpreted as a real number and is converted to a real object. If it
exceeds the implementation limit for real numbers, an error occurs.
Note: PDF does not support the PostScript syntax for numbers with nondecimal
radices (such as 16#FFFE) or in exponential format (such as 6.02E23).
53
SECTION 3.2
Objects
Throughout this book, the term number refers to an object whose type may be
either integer or real. Wherever a real number is expected, an integer may be used
instead and is automatically converted to an equivalent real value. For example, it
is not necessary to write the number 1.0 in real format; the integer 1 is sufficient.
3.2.3
String Objects
A string object consists of a series of bytes—unsigned integer values in the range 0
to 255. String objects are not integer objects, but are stored in a more compact
format. The length of a string may be subject to implementation limits; see
Appendix C.
String objects can be written in two ways:
• As a sequence of literal characters enclosed in parentheses ( ); see “Literal
Strings,” below”
• As hexadecimal data enclosed in angle brackets < >; see “Hexadecimal Strings”
on page 56
This section describes only the basic syntax for writing a string as a sequence of
bytes. Strings can be used for many purposes and can be formatted in a variety of
ways. When a string is used for a specific purpose (to represent a date, for ex-
ample), it is useful to have a standard format for that purpose (see Section 3.8.3,
“Dates”). Such formats are merely conventions for interpreting the contents of a
string and are not separate object types. The use of a particular format is
described with the definition of the string object that uses that format.
Section
3.8.1,
“String Types” describes the encoding schemes used for the
contents of string objects.
Literal Strings
A literal string is written as an arbitrary number of characters enclosed in
parentheses. Any characters may appear in a string except unbalanced
parentheses and the backslash, which must be treated specially. Balanced pairs of
parentheses within a string require no special treatment.
54
CHAPTER 3
Syntax
The following are valid literal strings:
( This is a string )
( Strings may contain newlines
and such . )
( Strings may contain balanced parentheses ( ) and
special characters ( * ! & } ^ % and so on ) . )
( The following is an empty string . )
( )
( It has zero ( 0 ) length . )
Within a literal string, the backslash (\) is used as an escape character for various
purposes, such as to include newline characters, nonprinting ASCII characters,
unbalanced parentheses, or the backslash character itself in the string. The
character immediately following the backslash determines its precise
interpretation (see Table 3.2). If the character following the backslash is not one
of those shown in the table, the backslash is ignored.
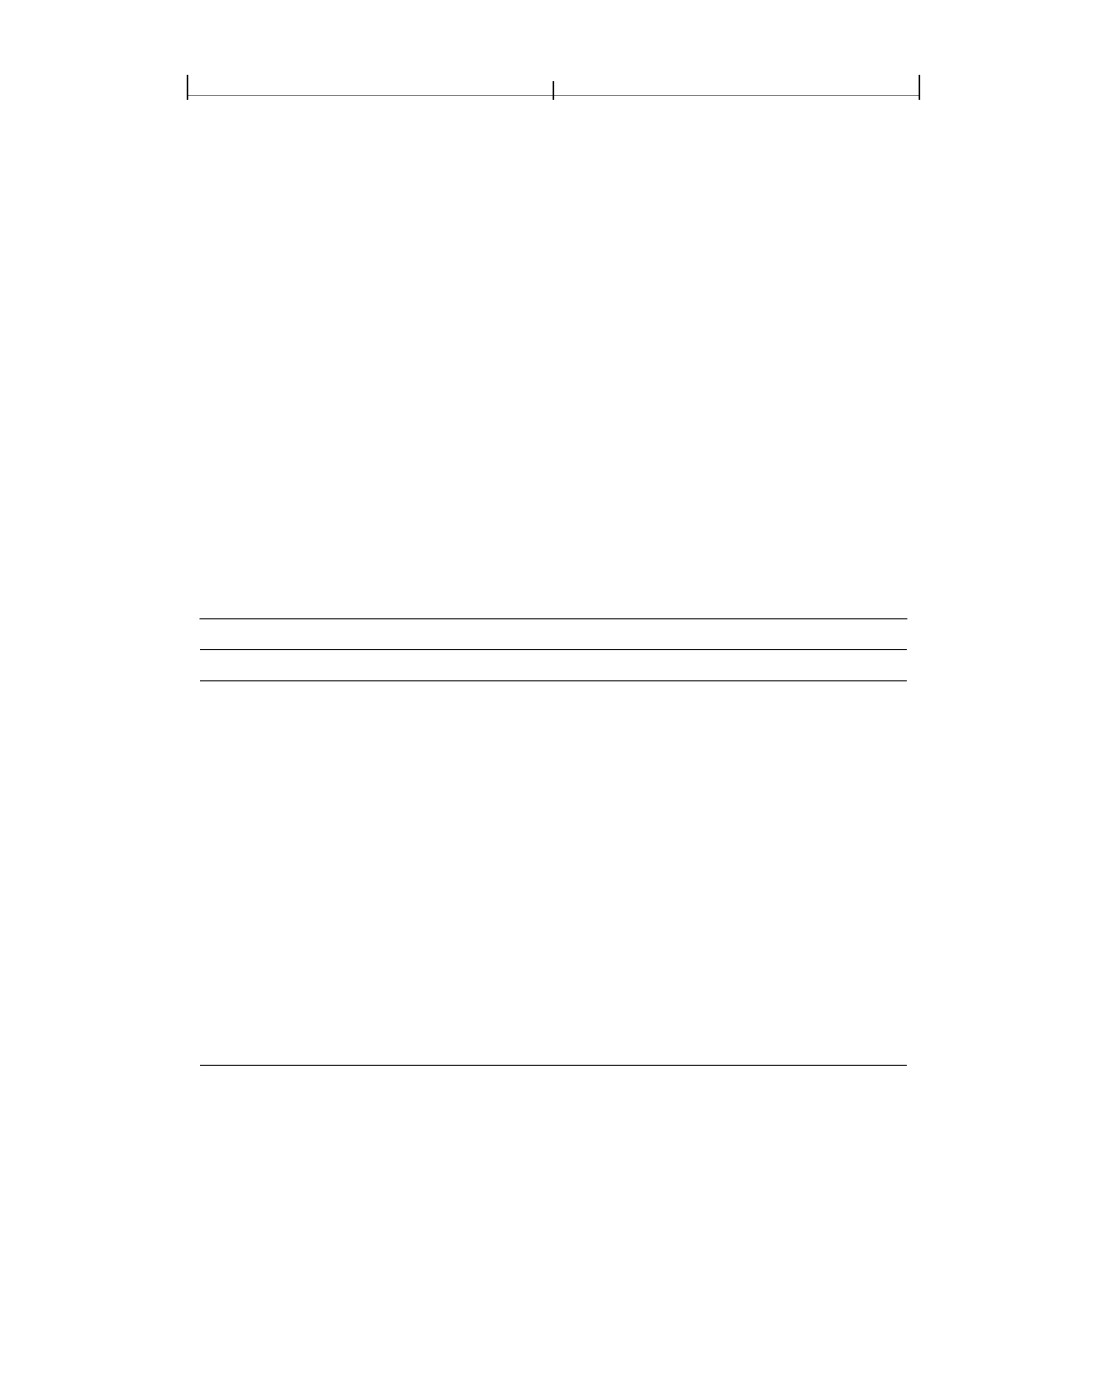
TABLE 3.2 Escape sequences in literal strings
SEQUENCE
MEANING
\n
Line feed (LF)
\r
Carriage return (CR)
\t
Horizontal tab (HT)
\b
Backspace (BS)
\f
Form feed (FF)
\(
Left parenthesis
\)
Right parenthesis
\\
Backslash
\ddd
Character code ddd (octal)
If a string is too long to be conveniently placed on a single line, it may be split
across multiple lines by using the backslash character at the end of a line to
55
SECTION 3.2
Objects
indicate that the string continues on the following line. The backslash and the
end-of-line marker following it are not considered part of the string. For example:
( These \
two strings \
are the same . )
( These two strings are the same . )
If an end-of-line marker appears within a literal string without a preceding
backslash, the result is equivalent to \n (regardless of whether the end-of-line
marker was a carriage return, a line feed, or both). For example:
( This string has an end−of−line at the end of it .
)
( So does this one .\n )
The \ddd escape sequence provides a way to represent characters outside the
printable ASCII character set. For example:
( This string contains \245two octal characters\307 . )
The number ddd may consist of one, two, or three octal digits, with high-order
overflow ignored. It is required that three octal digits be used, with leading zeros
as needed, if the next character of the string is also a digit. For example, the literal
( \0053 )
denotes a string containing two characters, \005 (Control-E) followed by the digit
3, whereas both
( \053 )
and
( \53 )
denote strings containing the single character \053, a plus sign (+).
This notation provides a way to specify characters outside the 7-bit ASCII
character set by using ASCII characters only. However, any 8-bit value may
appear in a string. In particular, when a document is encrypted (see Section 3.5,
“Encryption”), all of its strings are encrypted and often contain arbitrary 8-bit
56
CHAPTER 3
Syntax
values. Note that the backslash character is still required as an escape to specify
unbalanced parentheses or the backslash character itself.
Hexadecimal Strings
Strings may also be written in hexadecimal form, which is useful for including
arbitrary binary data in a PDF file. A hexadecimal string is written as a sequence
of hexadecimal digits (0-9 and either A-F or a-f) enclosed within angle brackets
(< and >):
< 4E6F762073686D6F7A206B6120706F702E >
Each pair of hexadecimal digits defines one byte of the string. White-space
characters (such as space, tab, carriage return, line feed, and form feed) are
ignored.
If the final digit of a hexadecimal string is missing—that is, if there is an odd
number of digits—the final digit is assumed to be 0. For example:
< 901FA3 >
is a 3-byte string consisting of the characters whose hexadecimal codes are 90, 1F,
and A3, but
< 901FA >
is a 3-byte string containing the characters whose hexadecimal codes are 90, 1F,
and A0.
3.2.4
Name Objects
A name object is an atomic symbol uniquely defined by a sequence of characters.
Uniquely defined means that any two name objects made up of the same sequence
of characters are identically the same object. Atomic means that a name has no
internal structure; although it is defined by a sequence of characters, those
characters are not considered elements of the name.
A slash character (/) introduces a name. The slash is not part of the name but is a
prefix indicating that the following sequence of characters constitutes a name.
There can be no white-space characters between the slash and the first character
57
SECTION 3.2
Objects
in the name. The name may include any regular characters, but not delimiter or
white-space characters (see Section 3.1, “Lexical Conventions”). Uppercase and
lowercase letters are considered distinct: /A and /a are different names. The
following examples are valid literal names:
/Name1
/ASomewhatLongerName
/A;Name_With−Various***Characters?
/1 . 2
/$$
/@pattern
/. notdef
Note: The token / (a slash followed by no regular characters) is a valid name.
Beginning with PDF 1.2, any character except null (character code 0) may be
included in a name by writing its 2-digit hexadecimal code, preceded by the
number sign character (#); see implementation notes 3 and 4 in Appendix H.
This syntax is required to represent any of the delimiter or white-space characters
or the number sign character itself; it is recommended but not required for
characters whose codes are outside the range 33 (!) to 126 (~). The examples
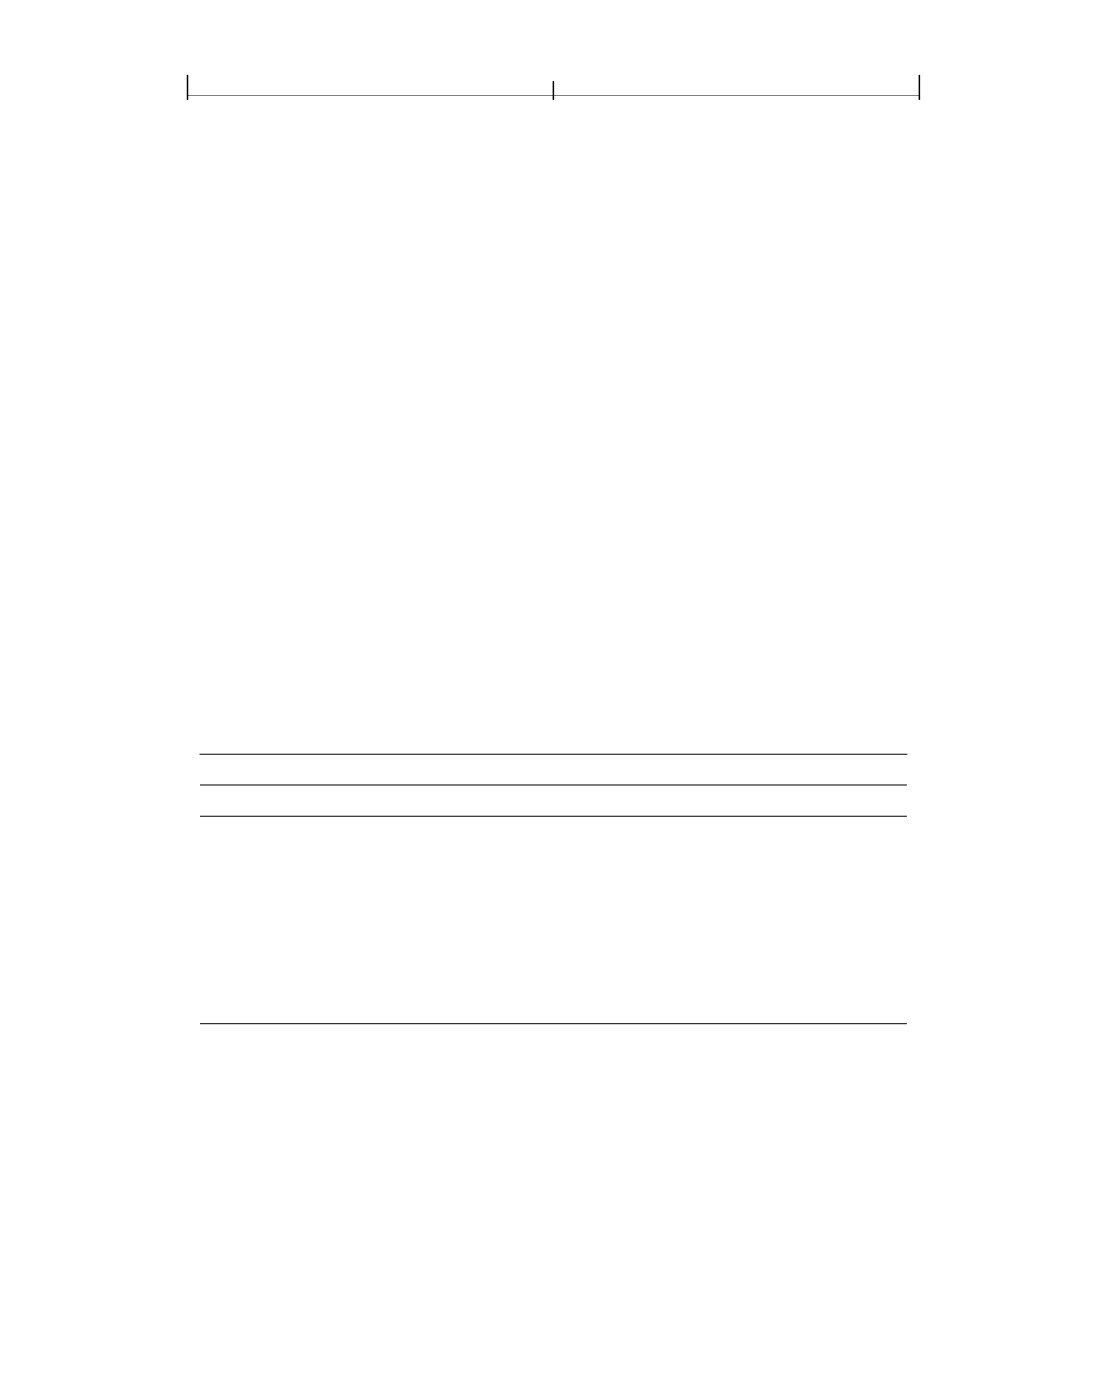
shown in Table 3.3 are valid literal names in PDF 1.2 and later.
TABLE 3.3 Examples of literal names using the # character
LITERAL NAME
RESULT
/Adobe#20Green
Adobe Green
/PANTONE#205757#20CV
PANTONE 5757 CV
/paired#28#29parentheses
paired( )parentheses
/The_Key_of_F#23_Minor
The_Key_of_F#_Minor
/A#42
AB
The length of a name is subject to an implementation limit; see Appendix C. The
limit applies to the number of characters in the name’s internal representation.
For example, the name /A#20B has four characters (/, A, space, B), not six.
As stated above, name objects are treated as atomic symbols within a PDF file.
Ordinarily, the bytes making up the name are never treated as text to be presented
to a human user or to an application external to a PDF consumer. However,
58
CHAPTER 3
Syntax
occasionally the need arises to treat a name object as text, such as one that
represents a font name (see the BaseFont entry in Table 5.8 on page 413) or a
structure type (see Section 10.6.2, “Structure Types”).
In such situations, it is recommended that the sequence of bytes (after expansion
of # sequences, if any) be interpreted according to UTF-8, a variable-length byte-
encoded representation of Unicode in which the printable ASCII characters have
the same representations as in ASCII. This enables a name object to represent text
in any natural language, subject to the implementation limit on the length of a
name. (See implementation note 5 in Appendix H.)
Note: PDF does not prescribe what UTF-8 sequence to choose for representing any
given piece of externally specified text as a name object. In some cases, multiple
UTF-8 sequences could represent the same logical text. Name objects defined by dif-
ferent sequences of bytes constitute distinct name objects in PDF, even though the
UTF-8 sequences might have identical external interpretations.
In PDF, name objects always begin with the slash character (/), unlike keywords
such as true, false, and obj. This book follows a typographic convention of
writing names without the leading slash when they appear in running text and
tables. For example, Type and FullScreen denote names that would actually be
written in a PDF file (and in code examples in this book) as /Type and /FullScreen.
3.2.5
Array Objects
An array object is a one-dimensional collection of objects arranged sequentially.
Unlike arrays in many other computer languages, PDF arrays may be hetero-
geneous; that is, an array’s elements may be any combination of numbers, strings,
dictionaries, or any other objects, including other arrays. The number of
elements in an array is subject to an implementation limit; see Appendix C.
An array is written as a sequence of objects enclosed in square brackets ([ and ]):
[ 549 3.14 false
( Ralph )
/SomeName ]
PDF directly supports only one-dimensional arrays. Arrays of higher dimension
can be constructed by using arrays as elements of arrays, nested to any depth.
59
SECTION 3.2
Objects
3.2.6
Dictionary Objects
A dictionary object is an associative table containing pairs of objects, known as
the dictionary’s entries. The first element of each entry is the key and the second
element is the value. The key must be a name (unlike dictionary keys in
PostScript, which may be objects of any type). The value can be any kind of
object, including another dictionary. A dictionary entry whose value is null (see
Section 3.2.8, “Null Object”) is equivalent to an absent entry. (This differs from
PostScript, where null behaves like any other object as the value of a dictionary
entry.) The number of entries in a dictionary is subject to an implementation
limit; see Appendix C.
Note: No two entries in the same dictionary should have the same key. If a key does
appear more than once, its value is undefined.
A dictionary is written as a sequence of key-value pairs enclosed in double angle
brackets (<<… >>). For example:
<< /Type /Example
/Subtype /DictionaryExample
/Version 0 . 01
/IntegerItem 12
/StringItem ( a string )
/Subdictionary << /Item1 0 . 4
/Item2 true
/LastItem ( not ! )
/VeryLastItem ( OK )
>>
>>
Note: Do not confuse the double angle brackets with single angle brackets (< and >),
which delimit a hexadecimal string (see “Hexadecimal Strings” on page 56).
Dictionary objects are the main building blocks of a PDF document. They are
commonly used to collect and tie together the attributes of a complex object, such
as a font or a page of the document, with each entry in the dictionary specifying
the name and value of an attribute. By convention, the Type entry of such a
dictionary identifies the type of object the dictionary describes. In some cases, a
Subtype entry (sometimes abbreviated S) is used to further identify a specialized
subcategory of the general type. The value of the Type or Subtype entry is always
60
CHAPTER 3
Syntax
a name. For example, in a font dictionary, the value of the Type entry is always
Font, whereas that of the Subtype entry may be Type1, TrueType, or one of
several other values.
The value of the Type entry can almost always be inferred from context. The
operand of the Tf operator, for example, must be a font object; therefore, the Type
entry in a font dictionary serves primarily as documentation and as information
for error checking. The Type entry is not required unless so stated in its
description; however, if the entry is present, it must have the correct value. In
addition, the value of the Type entry in any dictionary, even in private data, must
be either a name defined in this book or a registered name; see Appendix E for
details.
3.2.7
Stream Objects
A stream object, like a string object, is a sequence of bytes. However, a PDF
application can read a stream incrementally, while a string must be read in its
entirety. Furthermore, a stream can be of unlimited length, whereas a string is
subject to an implementation limit. For this reason, objects with potentially large
amounts of data, such as images and page descriptions, are represented as
streams.
Note: As with strings, this section describes only the syntax for writing a stream as a
sequence of bytes. What those bytes represent is determined by the context in which
the stream is referenced.
A stream consists of a dictionary followed by zero or more bytes bracketed
between the keywords stream and endstream:
dictionary
stream
… Zero or more bytes…
endstream
All streams must be indirect objects (see Section 3.2.9, “Indirect Objects”) and
the stream dictionary must be a direct object. The keyword stream that follows
the stream dictionary should be followed by an end-of-line marker consisting of
either a carriage return and a line feed or just a line feed, and not by a carriage
61
SECTION 3.2
Objects
return alone. The sequence of bytes that make up a stream lie between the stream
and endstream keywords; the stream dictionary specifies the exact number of
bytes. It is recommended that there be an end-of-line marker after the data and
before endstream; this marker is not included in the stream length.
Alternatively, beginning with PDF 1.2, the bytes may be contained in an external
file, in which case the stream dictionary specifies the file, and any bytes between
stream and endstream are ignored. (See implementation note 6 in Appendix H.)
Note: Without the restriction against following the keyword stream by a carriage re-
turn alone, it would be impossible to differentiate a stream that uses carriage return
as its end-of-line marker and has a line feed as its first byte of data from one that
uses a carriage return-line feed sequence to denote end-of-line.
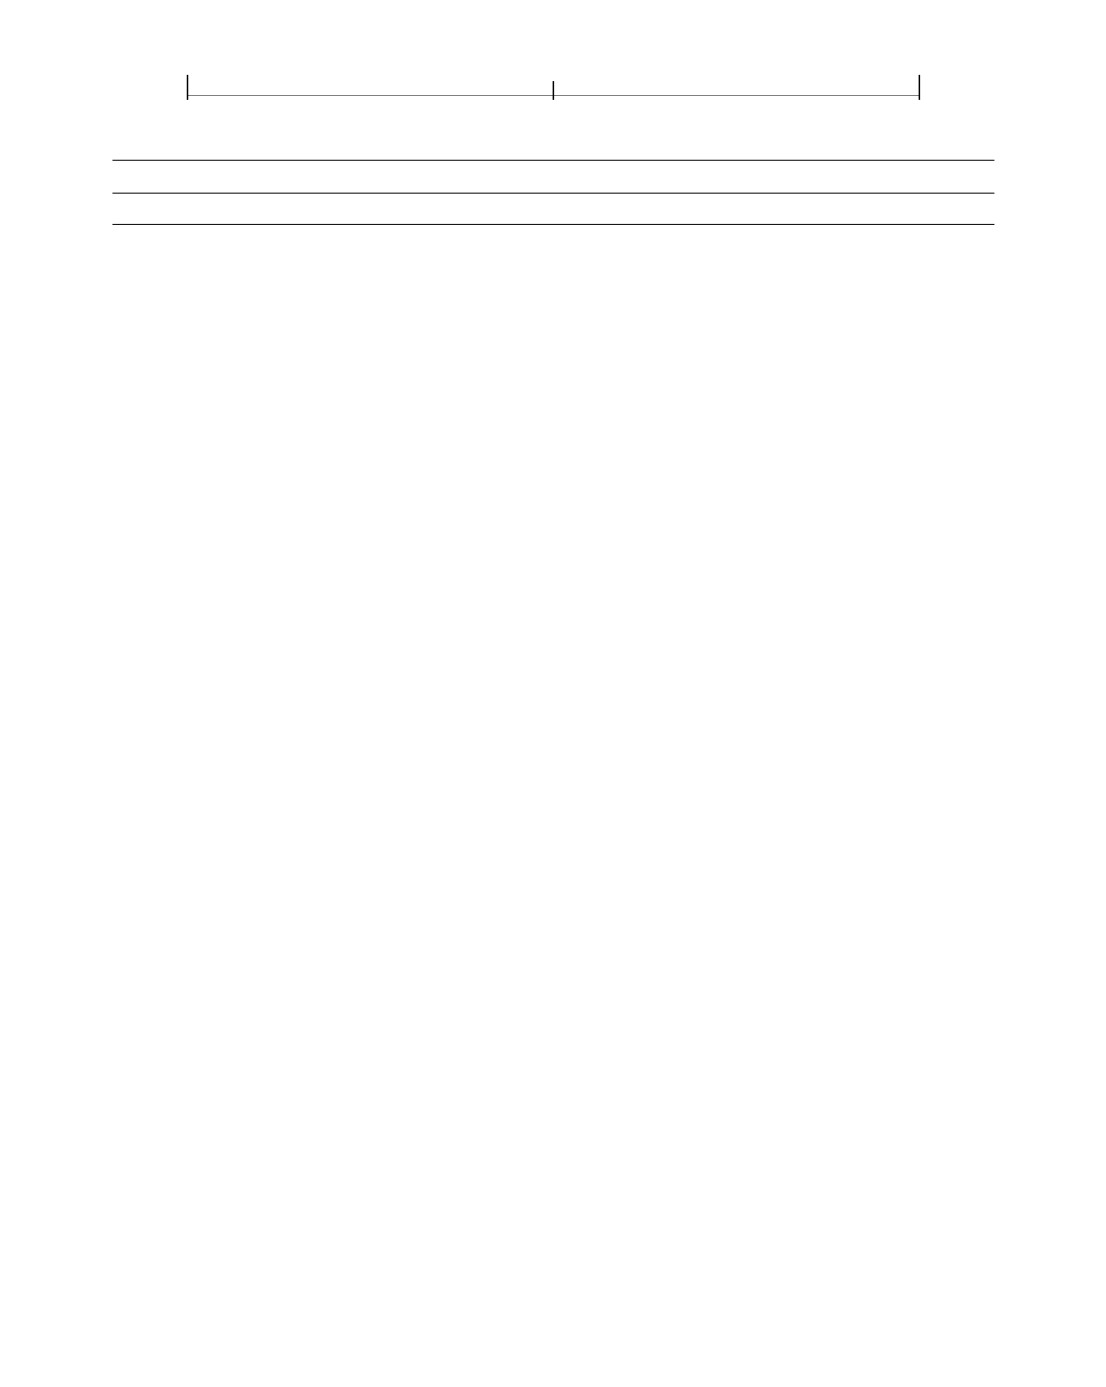
Table 3.4 lists the entries common to all stream dictionaries; certain types of
streams may have additional dictionary entries, as indicated where those streams
are described. The optional entries regarding filters for the stream indicate
whether and how the data in the stream must be transformed (decoded) before it
is used. Filters are described further in Section 3.3, “Filters.”
Stream Extent
Every stream dictionary has a Length entry that indicates how many bytes of the
PDF file are used for the stream’s data. (If the stream has a filter, Length is the
number of bytes of encoded data.) In addition, most filters are defined so that the
data is self-limiting; that is, they use an encoding scheme in which an explicit
end-of-data (EOD) marker delimits the extent of the data. Finally, streams are
used to represent many objects from whose attributes a length can be inferred. All
of these constraints must be consistent.
For example, an image with 10 rows and 20 columns, using a single color
component and 8 bits per component, requires exactly 200 bytes of image data. If
the stream uses a filter, there must be enough bytes of encoded data in the PDF
file to produce those 200 bytes. An error occurs if Length is too small, if an
explicit EOD marker occurs too soon, or if the decoded data does not contain 200
bytes.
It is also an error if the stream contains too much data, with the exception that
there may be an extra end-of-line marker in the PDF file before the keyword
endstream.
62
CHAPTER 3
Syntax
TABLE 3.4
Entries common to all stream dictionaries
KEY
TYPE
VALUE
Length
integer
(Required) The number of bytes from the beginning of the line fol-
lowing the keyword stream to the last byte just before the keyword
endstream. (There may be an additional EOL marker, preceding
endstream, that is not included in the count and is not logically part
of the stream data.) See “Stream Extent,” above, for further discus-
sion.
Filter
name or array
(Optional) The name of a filter to be applied in processing the stream
data found between the keywords stream and endstream, or an array
of such names. Multiple filters should be specified in the order in
which they are to be applied.
DecodeParms
dictionary or array
(Optional) A parameter dictionary or an array of such dictionaries,
used by the filters specified by Filter. If there is only one filter and that
filter has parameters, DecodeParms must be set to the filter’s parame-
ter dictionary unless all the filter’s parameters have their default
values, in which case the DecodeParms entry may be omitted. If there
are multiple filters and any of the filters has parameters set to non-
default values, DecodeParms must be an array with one entry for
each filter: either the parameter dictionary for that filter, or the null
object if that filter has no parameters (or if all of its parameters have
their default values). If none of the filters have parameters, or if all
their parameters have default values, the DecodeParms entry may be
omitted. (See implementation note 7 in Appendix H.)
F
file specification
(Optional; PDF 1.2) The file containing the stream data. If this entry
is present, the bytes between stream and endstream are ignored, the
filters are specified by FFilter rather than Filter, and the filter parame-
ters are specified by FDecodeParms rather than DecodeParms. How-
ever, the Length entry should still specify the number of those bytes.
(Usually, there are no bytes and Length is 0.) (See implementation
note 46 in Appendix H.)
FFilter
name or array
(Optional; PDF 1.2) The name of a filter to be applied in processing
the data found in the stream’s external file, or an array of such names.
The same rules apply as for Filter.
FDecodeParms
dictionary or array
(Optional; PDF 1.2) A parameter dictionary, or an array of such dic-
tionaries, used by the filters specified by FFilter. The same rules apply
as for DecodeParms.
63
SECTION 3.2
Objects
KEY
TYPE
VALUE
DL
integer
(Optional; PDF 1.5) A non-negative integer representing the number
of bytes in the decoded (defiltered) stream. It can be used to deter-
mine, for example, whether enough disk space is available to write a
stream to a file.
This value should be considered a hint only; for some stream filters, it
may not be possible to determine this value precisely.
3.2.8
Null Object
The null object has a type and value that are unequal to those of any other object.
There is only one object of type null, denoted by the keyword null. An indirect
object reference (see Section 3.2.9, “Indirect Objects”) to a nonexistent object is
treated the same as a null object. Specifying the null object as the value of a
dictionary entry (Section 3.2.6, “Dictionary Objects”) is equivalent to omitting
the entry entirely.
3.2.9
Indirect Objects
Any object in a PDF file may be labeled as an indirect object. This gives the object
a unique object identifier by which other objects can refer to it (for example, as an
element of an array or as the value of a dictionary entry). The object identifier
consists of two parts:
• A positive integer object number. Indirect objects are often numbered sequen-
tially within a PDF file, but this is not required; object numbers may be
assigned in any arbitrary order.
• A non-negative integer generation number. In a newly created file, all indirect
objects have generation numbers of 0. Nonzero generation numbers may be in-
troduced when the file is later updated; see Sections 3.4.3, “Cross-Reference
Table,” and 3.4.5, “Incremental Updates.”
Together, the combination of an object number and a generation number
uniquely identifies an indirect object. The object retains the same object number
and generation number throughout its existence, even if its value is modified.
64
CHAPTER 3
Syntax
The definition of an indirect object in a PDF file consists of its object number and
generation number, followed by the value of the object bracketed between the
keywords obj and endobj. For example, the definition
12 0 obj
( Brillig )
endobj
defines an indirect string object with an object number of 12, a generation
number of 0, and the value Brillig.
The object can be referred to from elsewhere in the file by an indirect reference
consisting of the object number, the generation number, and the keyword R:
12 0 R
Beginning with PDF 1.5, indirect objects may reside in object streams (see
Section 3.4.6, “Object Streams”). They are referred to in the same way; however,
their definition does not include the keywords obj and endobj.
An indirect reference to an undefined object is not an error; it is simply treated as
a reference to the null object. For example, if a file contains the indirect reference
17 0 R but does not contain the corresponding definition
17 0 obj
…
endobj
then the indirect reference is considered to refer to the null object.
Note: In the data structures that make up a PDF document, certain values are re-
quired to be specified as indirect object references. Except where this is explicitly
called out, any object (other than a stream) may be specified either directly or as an
indirect object reference; the semantics are entirely equivalent. Note in particular
that content streams, which define the visible contents of the document, may not
contain indirect references (see Section 3.7.1, “Content Streams”). Also, see imple-
mentation note 8 in Appendix H.
Example 3.1 shows the use of an indirect object to specify the length of a stream.
The value of the stream’s Length entry is an integer object that follows the stream
65
SECTION 3.3
Filters
in the file. This allows applications that generate PDF in a single pass to defer
specifying the stream’s length until after its contents have been generated.
Example 3.1
7 0 obj
<< /Length 8 0 R >>
% An indirect reference to object 8
stream
BT
/F1 12 Tf
72 712 Td
( A stream with an indirect length ) Tj
ET
endstream
endobj
8 0 obj
77
% The length of the preceding stream
endobj
3.3
Filters
Stream filters are introduced in Section 3.2.7, “Stream Objects.” A filter is an
optional part of the specification of a stream, indicating how the data in the
stream must be decoded before it is used. For example, if a stream has an
ASCIIHexDecode filter, an application reading the data in that stream will
transform the ASCII hexadecimal-encoded data in the stream into binary data.
An application program that produces a PDF file can encode certain information
(for example, data for sampled images) to compress it or to convert it to a port-
able ASCII representation. Then an application that reads (consumes) the PDF
file can invoke the corresponding decoding filter to convert the information back
to its original form.
The filter or filters for a stream are specified by the Filter entry in the stream’s
dictionary (or the FFilter entry if the stream is external). Filters can be cascaded
to form a pipeline that passes the stream through two or more decoding
transformations in sequence. For example, data encoded using LZW and ASCII
base-85 encoding (in that order) can be decoded using the following entry in the
stream dictionary:
/Filter
[ /ASCII85Decode /LZWDecode ]
66
CHAPTER 3
Syntax
Some filters may take parameters to control how they operate. These optional
parameters are specified by the DecodeParms entry in the stream’s dictionary (or
the FDecodeParms entry if the stream is external).
PDF supports a standard set of filters that fall into two main categories:
• ASCII filters enable decoding of arbitrary 8-bit binary data that has been en-
coded as ASCII text. (See Section 3.1, “Lexical Conventions,” for an explanation
of why this type of encoding might be useful.) Note that ASCII filters serve no
useful purpose in a PDF file that is encrypted; see Section 3.5, “Encryption.”
• Decompression filters enable decoding of data that has been compressed. The
compressed data is always in 8-bit binary format, even if the original data is
ASCII text. (Compression is particularly valuable for large sampled images,
since it reduces storage requirements and transmission time. Some types of
compression are lossy, meaning that some data is lost during the encoding, re-
sulting in a loss of quality when the data is decompressed. Compression in
which no loss of data occurs is called lossless.)
The standard filters are summarized in Table 3.5, which also indicates whether
they accept any optional parameters. The following sections describe these filters
and their parameters
(if any) in greater detail, including specifications of
encoding algorithms for some filters. (See also implementation notes 9 and 10 in
Appendix H.)
Example 3.2 shows a stream, containing the marking instructions for a page, that
was compressed using the LZW compression method and then encoded in ASCII
base-85 representation. Example
3.3 shows the same stream without any
encoding.
(The stream’s contents are explained in Section
3.7.1,
“Content
Streams,” and the operators used there are further described in Chapter 5.)
67
SECTION 3.3
Filters
TABLE 3.5 Standard filters
FILTER NAME
PARAMETERS?
DESCRIPTION
ASCIIHexDecode
no
Decodes data encoded in an ASCII hexadecimal representation,
reproducing the original binary data.
ASCII85Decode
no
Decodes data encoded in an ASCII base-85 representation, repro-
ducing the original binary data.
LZWDecode
yes
Decompresses data encoded using the LZW (Lempel-Ziv-Welch)
adaptive compression method, reproducing the original text or bin-
ary data.
FlateDecode
yes
(PDF 1.2) Decompresses data encoded using the zlib/deflate com-
pression method, reproducing the original text or binary data.
RunLengthDecode
no
Decompresses data encoded using a byte-oriented run-length encod-
ing algorithm, reproducing the original text or binary data (typically
monochrome image data, or any data that contains frequent long
runs of a single byte value).
CCITTFaxDecode
yes
Decompresses data encoded using the CCITT facsimile standard,
reproducing the original data (typically monochrome image data at 1
bit per pixel).
JBIG2Decode
yes
(PDF 1.4) Decompresses data encoded using the JBIG2 standard,
reproducing the original monochrome (1 bit per pixel) image data
(or an approximation of that data).
DCTDecode
yes
Decompresses data encoded using a DCT (discrete cosine transform)
technique based on the JPEG standard, reproducing image sample
data that approximates the original data.
JPXDecode
no
(PDF 1.5) Decompresses data encoded using the wavelet-based
JPEG2000 standard, reproducing the original image data.
Crypt
yes
(PDF 1.5) Decrypts data encrypted by a security handler, reproduc-
ing the original data as it was before encryption.
68
CHAPTER 3
Syntax
Example 3.2
1 0 obj
<< /Length 534
/Filter
[ /ASCII85Decode /LZWDecode ]
>>
stream
J..)6T`?p&<!J9%_[umg"B7/Z7KNXbN'S+,*Q/&"OLT'F
LIDK#!n`$"<Atdi`\Vn%b%)&'cA*VnK\CJY(sF>c!Jnl@
RM]WM;jjH6Gnc75idkL5]+cPZKEBPWdR>FF(kj1_R%W_d
&/jS!;iuad7h?[L−F$+]]0A3Ck*$I0KZ?;<)CJtqi65Xb
Vc3\n5ua:Q/=0$W<#N3U;H,MQKqfg1?:lUpR;6oN[C2E4
ZNr8Udn.'p+?#X+1>0Kuk$bCDF/(3fL5]Oq)^kJZ!C2H1
'TO]Rl?Q:&'<5&iP!$Rq;BXRecDN[IJB`,)o8XJOSJ9sD
S]hQ;Rj@!ND)bD_q&C\g:inYC%)&u#:u,M6Bm%IY!Kb1+
":aAa'S`ViJglLb8<W9k6Yl\\0McJQkDeLWdPN?9A'jX*
al>iG1p&i;eVoK&juJHs9%;Xomop"5KatWRT"JQ#qYuL,
JD?M$0QP)lKn06l1apKDC@\qJ4B!!(5m+j.7F790m(Vj8
8l8Q:_CZ(Gm1%X\N1&u!FKHMB~>
endstream
endobj
Example 3.3
1 0 obj
<< /Length 568 >>
stream
2 J
BT
/F1 12 Tf
0 Tc
0 Tw
72.5 712 TD
[ ( Unencoded streams can be read easily ) 65 ( , ) ] TJ
0 −14 TD
[ ( b )
20 ( ut generally tak ) 10 ( e more space than \311 ) ] TJ
T* ( encoded streams . ) Tj
0 −28 TD
[ ( Se )
25 ( v ) 15 ( eral encoding methods are a ) 20 ( v) 25 ( ailable in PDF ) 80
( . ) ]
TJ
0 −14 TD
( Some are used for compression and others simply ) Tj
T* [ ( to represent binary data in an ) 55 ( ASCII format . ) ] TJ
T* ( Some of the compression encoding methods are \
suitable ) Tj
69
SECTION 3.3
Filters
T* ( for both data and images , while others are \
suitable only ) Tj
T* ( for continuous−tone images . ) Tj
ET
endstream
endobj
3.3.1
ASCIIHexDecode Filter
The ASCIIHexDecode filter decodes data that has been encoded in ASCII
hexadecimal form. ASCII hexadecimal encoding and ASCII base-85 encoding
(described in the next section) convert binary data, such as image data, to 7-bit
ASCII characters. In general, ASCII base-85 encoding is preferred to ASCII
hexadecimal encoding because it is more compact: it expands the data by a factor
of 4 : 5, compared with 1 : 2 for ASCII hexadecimal encoding.
The ASCIIHexDecode filter produces one byte of binary data for each pair of
ASCII hexadecimal digits (0-9 and A-F or a-f). All white-space characters (see
Section 3.1, “Lexical Conventions”) are ignored. A right angle bracket character
(>) indicates EOD. Any other characters cause an error. If the filter encounters
the EOD marker after reading an odd number of hexadecimal digits, it behaves as
if a 0 followed the last digit.
3.3.2
ASCII85Decode Filter
The ASCII85Decode filter decodes data that has been encoded in ASCII base-85
encoding and produces binary data. The following paragraphs describe the
process for encoding binary data in ASCII base-85; the ASCII85Decode filter
reverses this process.
The ASCII base-85 encoding uses the characters ! through u and the character z,
with the 2-character sequence ~> as its EOD marker. The ASCII85Decode filter
ignores all white-space characters (see Section 3.1, “Lexical Conventions”). Any
other characters, and any character sequences that represent impossible
combinations in the ASCII base-85 encoding, cause an error.
70
CHAPTER 3
Syntax
Specifically, ASCII base-85 encoding produces 5 ASCII characters for every 4
bytes of binary data. Each group of 4 binary input bytes, (b1 b2 b3 b4 ), is converted
to a group of 5 output bytes, (c1 c2 c3 c4 c5 ), using the relation
(
b1
×
2563
)
+
(
b2
×
2562
)
+
(
b3
×
2561
)+ b4
=
(
c1
×
854
)
+
(
c2
×
853
)
+
(
c3
×
852
)
+
(
c4
×
851
)+ c5
In other words, 4 bytes of binary data are interpreted as a base-256 number and
then converted to a base-85 number. The five bytes of the base-85 number are
then converted to ASCII characters by adding 33 (the ASCII code for the
character ! ) to each. The resulting encoded data contains only printable ASCII
characters with codes in the range 33 ( ! ) to 117 (u). As a special case, if all five
bytes are 0, they are represented by the character with code 122 (z) instead of by
five exclamation points ( ! ! ! ! ! ).
If the length of the binary data to be encoded is not a multiple of 4 bytes, the last,
partial group of 4 is used to produce a last, partial group of 5 output characters.
Given n (1, 2, or 3) bytes of binary data, the encoder first appends 4 − n zero bytes
to make a complete group of 4. It then encodes this group in the usual way, but
without applying the special z case. Finally, it writes only the first n + 1 characters
of the resulting group of 5. These characters are immediately followed by the ~>
EOD marker.
The following conditions
(which never occur in a correctly encoded byte
sequence) cause errors during decoding:
• The value represented by a group of 5 characters is greater than 232 − 1.
• A z character occurs in the middle of a group.
• A final partial group contains only one character.
71
SECTION 3.3
Filters
3.3.3
LZWDecode and FlateDecode Filters
The LZWDecode and (in PDF 1.2) FlateDecode filters have much in common and
are discussed together in this section. They decode data that has been encoded
using the LZW or Flate data compression method, respectively:
• LZW (Lempel-Ziv-Welch) is a variable-length, adaptive compression method
that has been adopted as one of the standard compression methods in the Tag
Image File Format (TIFF) standard. Details on LZW encoding follow in the
next section.
• The Flate method is based on the public-domain zlib/deflate compression
method, which is a variable-length Lempel-Ziv adaptive compression method
cascaded with adaptive Huffman coding. It is fully defined in Internet RFCs
1950, ZLIB Compressed Data Format Specification, and 1951, DEFLATE Com-
pressed Data Format Specification (see the Bibliography).
Both of these methods compress either binary data or ASCII text but (like all
compression methods) always produce binary data, even if the original data was
text.
The LZW and Flate compression methods can discover and exploit many
patterns in the input data, whether the data is text or images. As described later,
both filters support optional transformation by a predictor function, which
improves the compression of sampled image data. Because of its cascaded
adaptive Huffman coding, Flate-encoded output is usually much more compact
than LZW-encoded output for the same input. Flate and LZW decoding speeds
are comparable, but Flate encoding is considerably slower than LZW encoding.
Usually, both Flate and LZW encodings compress their input substantially.
However, in the worst case (in which no pair of adjacent characters appears
twice), Flate encoding expands its input by no more than 11 bytes or a factor of
1.003 (whichever is larger), plus the effects of algorithm tags added by PNG
predictors. For LZW encoding, the best case (all zeros) provides a compression
approaching 1365 : 1 for long files, but the worst-case expansion is at least a factor
of 1.125, which can increase to nearly 1.5 in some implementations, plus the
effects of PNG tags as with Flate encoding.
72
CHAPTER 3
Syntax
Details of LZW Encoding
Data encoded using the LZW compression method consists of a sequence of
codes that are 9 to 12 bits long. Each code represents a single character of input
data (0-255), a clear-table marker (256), an EOD marker (257), or a table entry
representing a multiple-character sequence that has been encountered previously
in the input (258 or greater).
Initially, the code length is 9 bits and the LZW table contains only entries for the
258 fixed codes. As encoding proceeds, entries are appended to the table, asso-
ciating new codes with longer and longer sequences of input characters. The
encoder and the decoder maintain identical copies of this table.
Whenever both the encoder and the decoder independently (but synchronously)
realize that the current code length is no longer sufficient to represent the
number of entries in the table, they increase the number of bits per code by 1. The
first output code that is 10 bits long is the one following the creation of table entry
511, and similarly for 11 (1023) and 12 (2047) bits. Codes are never longer than
12 bits; therefore, entry 4095 is the last entry of the LZW table.
The encoder executes the following sequence of steps to generate each output
code:
1. Accumulate a sequence of one or more input characters matching a sequence
already present in the table. For maximum compression, the encoder looks for
the longest such sequence.
2. Emit the code corresponding to that sequence.
3. Create a new table entry for the first unused code. Its value is the sequence
found in step 1 followed by the next input character.
For example, suppose the input consists of the following sequence of ASCII
character codes:
45 45 45 45 45 65 45 45 45 66
Starting with an empty table, the encoder proceeds as shown in Table 3.6.
73
SECTION 3.3
Filters
TABLE 3.6 Typical LZW encoding sequence
INPUT
OUTPUT
CODE ADDED
SEQUENCE REPRESENTED
SEQUENCE
CODE
TO TABLE
BY NEW CODE
–
256 (clear-table)
-
-
45
45
258
45 45
45 45
258
259
45 45 45
45 45
258
260
45 45 65
65
65
261
65 45
45 45 45
259
262
45 45 45 66
66
66
-
-
–
257 (EOD)
-
-
Codes are packed into a continuous bit stream, high-order bit first. This stream is
then divided into 8-bit bytes, high-order bit first. Thus, codes can straddle byte
boundaries arbitrarily. After the EOD marker (code value 257), any leftover bits
in the final byte are set to 0.
In the example above, all the output codes are 9 bits long; they would pack into
bytes as follows (represented in hexadecimal):
80 0B 60 50 22 0C 0C 85 01
To adapt to changing input sequences, the encoder may at any point issue a clear-
table code, which causes both the encoder and the decoder to restart with initial
tables and a 9-bit code length. By convention, the encoder begins by issuing a
clear-table code. It must issue a clear-table code when the table becomes full; it
may do so sooner.
LZWDecode and FlateDecode Parameters
The LZWDecode and FlateDecode filters accept optional parameters to control
the decoding process. Most of these parameters are related to techniques that
reduce the size of compressed sampled images (rectangular arrays of color values,
described in Section 4.8, “Images”). For example, image data typically changes
very little from sample to sample. Therefore, subtracting the values of adjacent
74
CHAPTER 3
Syntax
samples (a process called differencing), and encoding the differences rather than
the raw sample values, can reduce the size of the output data. Furthermore, when
the image data contains several color components (red-green-blue or cyan-
magenta-yellow-black) per sample, taking the difference between the values of
corresponding components in adjacent samples, rather than between different
color components in the same sample, often reduces the output data size.
Table 3.7 shows the parameters that can optionally be specified for LZWDecode
and FlateDecode filters. Except where otherwise noted, all values supplied to the
decoding filter for any optional parameters must match those used when the data
was encoded.
TABLE 3.7 Optional parameters for LZWDecode and FlateDecode filters
KEY
TYPE
VALUE
Predictor
integer
A code that selects the predictor algorithm, if any. If the value of this entry
is 1, the filter assumes that the normal algorithm was used to encode the data,
without prediction. If the value is greater than 1, the filter assumes that the
data was differenced before being encoded, and Predictor selects the predic-
tor algorithm. For more information regarding Predictor values greater
than 1, see “LZW and Flate Predictor Functions,” below. Default value: 1.
Colors
integer
(Used only if Predictor is greater than 1) The number of interleaved color com-
ponents per sample. Valid values are 1 to 4 in PDF 1.2 or earlier and 1 or
greater in PDF 1.3 or later. Default value: 1.
BitsPerComponent
integer
(Used only if Predictor is greater than 1) The number of bits used to represent
each color component in a sample. Valid values are 1, 2, 4, 8, and (in PDF 1.5)
16. Default value: 8.
Columns
integer
(Used only if Predictor is greater than 1) The number of samples in each row.
Default value: 1.
EarlyChange
integer
(LZWDecode only) An indication of when to increase the code length. If the
value of this entry is 0, code length increases are postponed as long as pos-
sible. If the value is 1, code length increases occur one code early. This pa-
rameter is included because LZW sample code distributed by some vendors
increases the code length one code earlier than necessary. Default value: 1.
75
SECTION 3.3
Filters
LZW and Flate Predictor Functions
LZW and Flate encoding compress more compactly if their input data is highly
predictable. One way of increasing the predictability of many continuous-tone
sampled images is to replace each sample with the difference between that sample
and a predictor function applied to earlier neighboring samples. If the predictor
function works well, the postprediction data clusters toward 0.
Two groups of predictor functions are supported. The first, the TIFF group,
consists of the single function that is Predictor 2 in the TIFF standard. (In the
TIFF standard, Predictor 2 applies only to LZW compression, but here it applies
to Flate compression as well.) TIFF Predictor
2 predicts that each color
component of a sample is the same as the corresponding color component of the
sample immediately to its left.
The second supported group of predictor functions, the PNG group, consists of
the filters of the World Wide Web Consortium’s Portable Network Graphics
recommendation, documented in Internet RFC 2083, PNG (Portable Network
Graphics) Specification (see the Bibliography). The term predictors is used here
instead of filters to avoid confusion. There are five basic PNG predictor
algorithms (and a sixth that chooses the optimum predictor function separately
for each row):
None
No prediction
Sub
Predicts the same as the sample to the left
Up
Predicts the same as the sample above
Average
Predicts the average of the sample to the left and the sample above
Paeth
A nonlinear function of the sample above, the sample to the left,
and the sample to the upper left
The predictor algorithm to be used, if any, is indicated by the Predictor filter
parameter (see Table 3.7), which can have any of the values listed in Table 3.8.
For LZWDecode and FlateDecode, a Predictor value greater than or equal to 10
merely indicates that a PNG predictor is in use; the specific predictor function
used is explicitly encoded in the incoming data. The value of Predictor supplied
by the decoding filter need not match the value used when the data was encoded
if they are both greater than or equal to 10.
76
CHAPTER 3
Syntax
TABLE 3.8 Predictor values
VALUE
MEANING
1
No prediction (the default value)
2
TIFF Predictor 2
10
PNG prediction (on encoding, PNG None on all rows)
11
PNG prediction (on encoding, PNG Sub on all rows)
12
PNG prediction (on encoding, PNG Up on all rows)
13
PNG prediction (on encoding, PNG Average on all rows)
14
PNG prediction (on encoding, PNG Paeth on all rows)
15
PNG prediction (on encoding, PNG optimum)
The two groups of predictor functions have some commonalities. Both make the
following assumptions:
• Data is presented in order, from the top row to the bottom row and, within a
row, from left to right.
• A row occupies a whole number of bytes, rounded up if necessary.
• Samples and their components are packed into bytes from high-order to low-
order bits.
• All color components of samples outside the image (which are necessary for
predictions near the boundaries) are 0.
The predictor function groups also differ in significant ways:
• The postprediction data for each PNG-predicted row begins with an explicit
algorithm tag; therefore, different rows can be predicted with different algo-
rithms to improve compression. TIFF Predictor 2 has no such identifier; the
same algorithm applies to all rows.
• The TIFF function group predicts each color component from the prior in-
stance of that component, taking into account the number of bits per com-
ponent and components per sample. In contrast, the PNG function group
predicts each byte of data as a function of the corresponding byte of one or
77
SECTION 3.3
Filters
more previous image samples, regardless of whether there are multiple color
components in a byte or whether a single color component spans multiple
bytes. This can yield significantly better speed at the cost of somewhat worse
compression.
3.3.4
RunLengthDecode Filter
The RunLengthDecode filter decodes data that has been encoded in a simple
byte-oriented format based on run length. The encoded data is a sequence of
runs, where each run consists of a length byte followed by 1 to 128 bytes of data. If
the length byte is in the range 0 to 127, the following length + 1 (1 to 128) bytes
are copied literally during decompression. If length is in the range 129 to 255, the
following single byte is to be copied
257 − length (2 to 128) times during
decompression. A length value of 128 denotes EOD.
The compression achieved by run-length encoding depends on the input data. In
the best case (all zeros), a compression of approximately 64 : 1 is achieved for long
files. The worst case (the hexadecimal sequence 00 alternating with FF) results in
an expansion of 127 : 128.
3.3.5
CCITTFaxDecode Filter
The CCITTFaxDecode filter decodes image data that has been encoded using
either Group 3 or Group 4 CCITT facsimile (fax) encoding. CCITT encoding is
designed to achieve efficient compression of monochrome (1 bit per pixel) image
data at relatively low resolutions, and so is useful only for bitmap image data, not
for color images, grayscale images, or general data.
The CCITT encoding standard is defined by the International
Telecommunications Union (ITU), formerly known as the Comité Consultatif
International Téléphonique et Télégraphique
(International Coordinating
Committee for Telephony and Telegraphy). The encoding algorithm is not
described in detail in this book but can be found in ITU Recommendations T.4
and T.6
(see the Bibliography). For historical reasons, we refer to these
documents as the CCITT standard.
78
CHAPTER 3
Syntax
CCITT encoding is bit-oriented, not byte-oriented. Therefore, in principle,
encoded or decoded data might not end at a byte boundary. This problem is dealt
with in the following ways:
• Unencoded data is treated as complete scan lines, with unused bits inserted at
the end of each scan line to fill out the last byte. This approach is compatible
with the PDF convention for sampled image data.
• Encoded data is ordinarily treated as a continuous, unbroken bit stream. The
EncodedByteAlign parameter (described in Table 3.9) can be used to cause
each encoded scan line to be filled to a byte boundary. Although this is not pre-
scribed by the CCITT standard and fax machines never do this, some software
packages find it convenient to encode data this way.
• When a filter reaches EOD, it always skips to the next byte boundary following
the encoded data.
If the CCITTFaxDecode filter encounters improperly encoded source data, an
error occurs. The filter does not perform any error correction or
resynchronization, except as noted for the DamagedRowsBeforeError parameter
in Table 3.9.
Table 3.9 lists the optional parameters that can be used to control the decoding.
Except where noted otherwise, all values supplied to the decoding filter by any of
these parameters must match those used when the data was encoded.
TABLE 3.9 Optional parameters for the CCITTFaxDecode filter
KEY
TYPE
VALUE
K
integer
A code identifying the encoding scheme used:
< 0
Pure two-dimensional encoding (Group 4)
0
Pure one-dimensional encoding (Group 3, 1-D)
> 0
Mixed one- and two-dimensional encoding (Group 3, 2-D),
in which a line encoded one-dimensionally can be followed
by at most K − 1 lines encoded two-dimensionally
The filter distinguishes among negative, zero, and positive values of
K to determine how to interpret the encoded data; however, it does
not distinguish between different positive K values. Default value: 0.
79
SECTION 3.3
Filters
KEY
TYPE
VALUE
EndOfLine
boolean
A flag indicating whether end-of-line bit patterns are required to be
present in the encoding. The CCITTFaxDecode filter always accepts
end-of-line bit patterns, but requires them only if EndOfLine is true.
Default value: false.
EncodedByteAlign
boolean
A flag indicating whether the filter expects extra 0 bits before each
encoded line so that the line begins on a byte boundary. If true, the
filter skips over encoded bits to begin decoding each line at a byte
boundary. If false, the filter does not expect extra bits in the encod-
ed representation. Default value: false.
Columns
integer
The width of the image in pixels. If the value is not a multiple of 8,
the filter adjusts the width of the unencoded image to the next mul-
tiple of 8 so that each line starts on a byte boundary. Default value:
1728.
Rows
integer
The height of the image in scan lines. If the value is 0 or absent, the
image’s height is not predetermined, and the encoded data must be
terminated by an end-of-block bit pattern or by the end of the fil-
ter’s data. Default value: 0.
EndOfBlock
boolean
A flag indicating whether the filter expects the encoded data to be
terminated by an end-of-block pattern, overriding the Rows param-
eter. If false, the filter stops when it has decoded the number of lines
indicated by Rows or when its data has been exhausted, whichever
occurs first. The end-of-block pattern is the CCITT end-of-facsim-
ile-block (EOFB) or return-to-control (RTC) appropriate for the K
parameter. Default value: true.
BlackIs1
boolean
A flag indicating whether 1 bits are to be interpreted as black pixels
and 0 bits as white pixels, the reverse of the normal PDF convention
for image data. Default value: false.
DamagedRowsBeforeError
integer
The number of damaged rows of data to be tolerated before an error
occurs. This entry applies only if EndOfLine is true and K is non-
negative. Tolerating a damaged row means locating its end in the
encoded data by searching for an EndOfLine pattern and then sub-
stituting decoded data from the previous row if the previous row
was not damaged, or a white scan line if the previous row was also
damaged. Default value: 0.
80
CHAPTER 3
Syntax
The compression achieved using CCITT encoding depends on the data, as well as
on the value of various optional parameters. For Group 3 one-dimensional
encoding, in the best case (all zeros), each scan line compresses to 4 bytes, and the
compression factor depends on the length of a scan line. If the scan line is 300
bytes long, a compression ratio of approximately 75 : 1 is achieved. The worst case,
an image of alternating ones and zeros, produces an expansion of 2 : 9.
3.3.6
JBIG2Decode Filter
The JBIG2Decode filter (PDF 1.4) decodes monochrome (1 bit per pixel) image
data that has been encoded using JBIG2 encoding. JBIG stands for the Joint Bi-
Level Image Experts Group, a group within the International Organization for
Standardization (ISO) that developed the format. JBIG2 is the second version of a
standard originally released as JBIG1.
JBIG2 encoding, which provides for both lossy and lossless compression, is useful
only for monochrome images, not for color images, grayscale images, or general
data. The algorithms used by the encoder, and the details of the format, are not
described here. A working draft of the JBIG2 specification can be found through
the Web site for the JBIG and JPEG (Joint Photographic Experts Group)
committees at < http://www.jpeg.org >.
In general, JBIG2 provides considerably better compression than the existing
CCITT standard (discussed in Section 3.3.5). The compression it achieves
depends strongly on the nature of the image. Images of pages containing text in
any language compress particularly well, with typical compression ratios of 20:1
to 50:1 for a page full of text. The JBIG2 encoder builds a table of unique symbol
bitmaps found in the image, and other symbols found later in the image are
matched against the table. Matching symbols are replaced by an index into the
table, and symbols that fail to match are added to the table. The table itself is
compressed using other means. This method results in high compression ratios
for documents in which the same symbol is repeated often, as is typical for
images created by scanning text pages. It also results in high compression of white
space in the image, which does not need to be encoded because it contains no
symbols.
While best compression is achieved for images of text, the JBIG2 standard also
includes algorithms for compressing regions of an image that contain dithered
halftone images (for example, photographs).
81
SECTION 3.3
Filters
The JBIG2 compression method can also be used for encoding multiple images
into a single JBIG2 bit stream. Typically, these images are scanned pages of a
multiple-page document. Since a single table of symbol bitmaps is used to match
symbols across multiple pages, this type of encoding can result in higher
compression ratios than if each of the pages had been individually encoded using
JBIG2.
In general, an image may be specified in PDF as either an image XObject or an
inline image (as described in Section 4.8, “Images”); however, the JBIG2Decode
filter can be applied only to image XObjects.
This filter addresses both single-page and multiple-page JBIG2 bit streams by
representing each JBIG2 page as a PDF image, as follows:
• The filter uses the embedded file organization of JBIG2. (The details of this and
the other types of file organization are provided in an annex of the ISO specifi-
cation.) The optional 2-byte combination (marker) mentioned in the specifica-
tion is not used in PDF. JBIG2 bit streams in random-access organization
should be converted to the embedded file organization. Bit streams in sequen-
tial organization need no reorganization, except for the mappings described
below.
• The JBIG2 file header, end-of-page segments, and end-of-file segment are not
used in PDF. These should be removed before the PDF objects described below
are created.
• The image XObject to which the JBIG2Decode filter is applied contains all seg-
ments that are associated with the JBIG2 page represented by that image; that
is, all segments whose segment page association field contains the page number
of the JBIG2 page represented by the image. In the image XObject, however, the
segment’s page number should always be 1; that is, when each such segment is
written to the XObject, the value of its segment page association field should be
set to 1.
• If the bit stream contains global segments (segments whose segment page asso-
ciation field contains 0), these segments must be placed in a separate PDF
stream, and the filter parameter listed in Table 3.10 should refer to that stream.
The stream can be shared by multiple image XObjects whose JBIG2 encodings
use the same global segments.
82
CHAPTER 3
Syntax
TABLE 3.10 Optional parameter for the JBIG2Decode filter
KEY
TYPE
VALUE
JBIG2Globals
stream
A stream containing the JBIG2 global (page 0) segments. Global segments
must be placed in this stream even if only a single JBIG2 image XObject re-
fers to it.
Example 3.4 shows an image that was compressed using the JBIG2 compression
method and then encoded in ASCII hexadecimal representation. Since the JBIG2
bit stream contains global segments, these segments are placed in a separate PDF
stream, as indicated by the JBIG2Globals filter parameter.
Example 3.4
5 0 obj
<< /Type /XObject
/Subtype /Image
/Width 52
/Height 66
/ColorSpace /DeviceGray
/BitsPerComponent 1
/Length 224
/Filter
[ /ASCIIHexDecode /JBIG2Decode ]
/DecodeParms [ null << /JBIG2Globals 6 0 R >> ]
>>
stream
000000013000010000001300000034000000420000000000
00000040000000000002062000010000001e000000340000
004200000000000000000200100000000231db51ce51ffac >
endstream
endobj
6 0 obj
<< /Length 126
/Filter
/ASCIIHexDecode
>>
stream
0000000000010000000032000003fffdff02fefefe000000
01000000012ae225aea9a5a538b4d9999c5c8e56ef0f872
7f2b53d4e37ef795cc5506dffac >
endstream
endobj
83
SECTION 3.3
Filters
The JBIG2 bit stream for this example is as follows:
97 4A 42 32 0D 0A 1A 0A 01 00 00 00 01 00 00 00 00 00 01 00 00 00 00 32
00 00 03 FF FD FF 02 FE FE FE 00 00 00 01 00 00 00 01 2A E2 25 AE A9 A5
A5 38 B4 D9 99 9C 5C 8E 56 EF 0F 87 27 F2 B5 3D 4E 37 EF 79 5C C5 50 6D
FF AC 00 00 00 01 30 00 01 00 00 00 13 00 00 00 34 00 00 00 42 00 00 00
00 00 00 00 00 40 00 00 00 00 00 02 06 20 00 01 00 00 00 1E 00 00 00 34
00 00 00 42 00 00 00 00 00 00 00 00 02 00 10 00 00 00 02 31 DB 51 CE 51
FF AC 00 00 00 03 31 00 01 00 00 00 00 00 00 00 04 33 01 00 00 00 00
This bit stream is made up of the following parts (in the order listed):
1.
The JBIG2 file header
97 4A 42 32 0D 0A 1A 0A 01 00 00 00 01
Since the JBIG2 file header is not used in PDF, this header is not placed in the
JBIG2 stream object and is discarded.
2.
The first JBIG2 segment (segment 0)—in this case, the symbol dictionary seg-
ment
00 00 00 00 00 01 00 00 00 00 32 00 00 03 FF FD FF 02 FE FE FE 00 00 00
01 00 00 00 01 2A E2 25 AE A9 A5 A5 38 B4 D9 99 9C 5C 8E 56 EF 0F 87
27 F2 B5 3D 4E 37 EF 79 5C C5 50 6D FF AC
This is a global segment (segment page association = 0) and so is placed in the
JBIG2Globals stream.
3.
The page information segment
00 00 00 01 30 00 01 00 00 00 13 00 00 00 34 00 00 00 42 00 00 00 00
00 00 00 00 40 00 00
and the immediate text region segment
00 00 00 02 06 20 00 01 00 00 00 1E 00 00 00 34 00 00 00 42 00 00 00
00 00 00 00 00 02 00 10 00 00 00 02 31 DB 51 CE 51 FF AC
These two segments constitute the contents of the JBIG2 page and are placed
in the PDF XObject representing this image.
4.
The end-of-page segment
00 00 00 03 31 00 01 00 00 00 00
and the end-of-file segment
00 00 00 04 33 01 00 00 00 00
Since these segments are not used in PDF, they are discarded.
84
CHAPTER 3
Syntax
The resulting PDF image object, then, contains the page information segment
and the immediate text region segment and refers to a JBIG2Globals stream that
contains the symbol dictionary segment.
3.3.7
DCTDecode Filter
The DCTDecode filter decodes grayscale or color image data that has been
encoded in the JPEG baseline format. (JPEG stands for the Joint Photographic
Experts Group, a group within the International Organization for
Standardization that developed the format; DCT stands for discrete cosine
transform, the primary technique used in the encoding.)
JPEG encoding is a lossy compression method, designed specifically for
compression of sampled continuous-tone images and not for general data
compression. Data to be encoded using JPEG consists of a stream of image
samples, each consisting of one, two, three, or four color components. The color
component values for a particular sample must appear consecutively. Each
component value occupies an 8-bit byte.
During encoding, several parameters control the algorithm and the information
loss. The values of these parameters, which include the dimensions of the image
and the number of components per sample, are entirely under the control of the
encoder and are stored in the encoded data. DCTDecode generally obtains the
parameter values it requires directly from the encoded data. However, in one
instance, the parameter might not be present in the encoded data but must be
specified in the filter parameter dictionary; see Table 3.11.
The details of the encoding algorithm are not presented here but are in the ISO
specification and in JPEG: Still Image Data Compression Standard, by Pennebaker
and Mitchell (see the Bibliography). Briefly, the JPEG algorithm breaks an image
up into blocks that are 8 samples wide by 8 samples shigh. Each color component
in an image is treated separately. A two-dimensional DCT is performed on each
block. This operation produces 64 coefficients, which are then quantized. Each
coefficient may be quantized with a different step size. It is this quantization that
results in the loss of information in the JPEG algorithm. The quantized coef-
ficients are then compressed.
Большое спасибо!
Ваше мнение очень важно для нас.
Нет комментариевНе стесняйтесь поделиться с нами вашим ценным мнением.
Текст