PDF Reference sixth edition, Adobe Portable Document Format Version 1.7 (book 1) — page 11
413
SECTION 5.5
Simple Fonts
lutions. Details on this format are provided in a separate book, Adobe Type 1 Font
Format. An alternative, more compact but functionally equivalent representation
of a Type 1 font program is documented in Adobe Technical Note #5176, The
Compact Font Format Specification.
Note: Although a Type 1 font program uses PostScript language syntax, using it does
not require a full PostScript interpreter; a specialized Type 1 font interpreter suffices.
A Type 1 font dictionary contains the entries listed in Table 5.8. Some entries are
optional for the standard 14 fonts listed under “Standard Type 1 Fonts (Standard
14 Fonts)” on page 416, but are required otherwise.
TABLE 5.8 Entries in a Type 1 font dictionary
KEY
TYPE
VALUE
Type
name
(Required) The type of PDF object that this dictionary describes; must be
Font for a font dictionary.
Subtype
name
(Required) The type of font; must be Type1 for a Type 1 font.
Name
name
(Required in PDF 1.0; optional otherwise) The name by which this font is ref-
erenced in the Font subdictionary of the current resource dictionary.
Note: This entry is obsolescent and its use is no longer recommended. (See
implementation note 60 in Appendix H.)
BaseFont
name
(Required) The PostScript name of the font. For Type 1 fonts, this is usually
the value of the FontName entry in the font program; for more information,
see Section 5.2 of the PostScript Language Reference, Third Edition. The Post-
Script name of the font can be used to find the font’s definition in the con-
sumer application or its environment. It is also the name that is used when
printing to a PostScript output device.
FirstChar
integer
(Required except for the standard 14 fonts) The first character code defined in
the font’s Widths array.
Note: Beginning with PDF 1.5, the special treatment given to the standard 14
fonts is deprecated. All fonts used in a PDF document should be represented us-
ing a complete font descriptor. For backwards capability, viewer applications
must still provide the special treatment identified for the standard 14 fonts.
414
CHAPTER 5
Text
KEY
TYPE
VALUE
LastChar
integer
(Required except for the standard 14 fonts) The last character code defined in
the font’s Widths array.
Note: Beginning with PDF 1.5, the special treatment given to the standard 14
fonts is deprecated. All fonts used in a PDF document should be represented us-
ing a complete font descriptor. For backwards capability, viewer applications
must still provide the special treatment identified for the standard 14 fonts.
Widths
array
(Required except for the standard 14 fonts; indirect reference preferred) An ar-
ray of (LastChar − FirstChar + 1) widths, each element being the glyph width
for the character code that equals FirstChar plus the array index. For charac-
ter codes outside the range FirstChar to LastChar, the value of MissingWidth
from the FontDescriptor entry for this font is used. The glyph widths are
measured in units in which 1000 units corresponds to 1 unit in text space.
These widths must be consistent with the actual widths given in the font pro-
gram. (See implementation note 61 in Appendix H.) For more information
on glyph widths and other glyph metrics, see Section 5.1.3, “Glyph Position-
ing and Metrics.”
Note: Beginning with PDF 1.5, the special treatment given to the standard 14
fonts is deprecated. All fonts used in a PDF document should be represented us-
ing a complete font descriptor. For backwards capability, viewer applications
must still provide the special treatment identified for the standard 14 fonts.
FontDescriptor
dictionary
(Required except for the standard 14 fonts; must be an indirect reference) A font
descriptor describing the font’s metrics other than its glyph widths (see Sec-
tion 5.7, “Font Descriptors”).
Note: For the standard 14 fonts, the entries FirstChar, LastChar, Widths, and
FontDescriptor must either all be present or all be absent. Ordinarily, they are
absent; specifying them enables a standard font to be overridden (see “Standard
Type 1 Fonts (Standard 14 Fonts),” below).
Note: Beginning with PDF 1.5, the special treatment given to the standard 14
fonts is deprecated. All fonts used in a PDF document should be represented us-
ing a complete font descriptor. For backwards capability, viewer applications
must still provide the special treatment identified for the standard 14 fonts.
Encoding
name or
(Optional) A specification of the font’s character encoding if different from its
dictionary
built-in encoding. The value of Encoding is either the name of a predefined
encoding (MacRomanEncoding, MacExpertEncoding, or WinAnsiEncoding,
as described in Appendix D) or an encoding dictionary that specifies differ-
ences from the font’s built-in encoding or from a specified predefined encod-
ing (see Section 5.5.5, “Character Encoding”).
415
SECTION 5.5
Simple Fonts
KEY
TYPE
VALUE
ToUnicode
stream
(Optional; PDF 1.2) A stream containing a CMap file that maps character
codes to Unicode values (see Section 5.9, “Extraction of Text Content”).
Example 5.6 shows the font dictionary for the Adobe Garamond® Semibold font.
The font has an encoding dictionary (object 25), although neither the encoding
dictionary nor the font descriptor (object 7) is shown in the example.
Example 5.6
14 0 obj
<< /Type /Font
/Subtype /Type1
/BaseFont /AGaramond−Semibold
/FirstChar
0
/LastChar 255
/Widths 21 0 R
/FontDescriptor 7 0 R
/Encoding 25 0 R
>>
endobj
21 0 obj
[
255 255 255 255 255 255 255 255 255 255 255 255 255 255 255 255
255 255 255 255 255 255 255 255 255 255 255 255 255 255 255 255
255 280 438 510 510 868 834 248 320 320 420 510 255 320 255 347
510 510 510 510 510 510 510 510 510 510 255 255 510 510 510 330
781 627 627 694 784 580 533 743 812 354 354 684 560 921 780 792
588 792 656 504 682 744 650 968 648 590 638 320 329 320 510 500
380 420 510 400 513 409 301 464 522 268 259 484 258 798 533 492
516 503 349 346 321 520 434 684 439 448 390 320 255 320 510 255
627 627 694 580 780 792 744 420 420 420 420 420 420 402 409 409
409 409 268 268 268 268 533 492 492 492 492 492 520 520 520 520
486 400 510 510 506 398 520 555 800 800 1044 360 380 549 846 792
713 510 549 549 510 522 494 713 823 549 274 354 387 768 615 496
330 280 510 549 510 549 612 421 421 1000 255 627 627 792 1016 730
500 1000 438 438 248 248 510 494 448 590 100 510 256 256 539 539
486 255 248 438 1174 627 580 627 580 580 354 354 354 354 792 792
790 792 744 744 744 268 380 380 380 380 380 380 380 380 380 380
]
endobj
416
CHAPTER 5
Text
Standard Type 1 Fonts (Standard 14 Fonts)
The PostScript names of 14 Type 1 fonts, known as the standard 14 fonts, are as
follows:
Times−Roman
Helvetica
Courier
Symbol
Times−Bold
Helvetica−Bold
Courier−Bold
ZapfDingbats
Times−Italic
Helvetica−Oblique
Courier−Oblique
Times−BoldItalic
Helvetica−BoldOblique
Courier−BoldOblique
These fonts, or their font metrics and suitable substitution fonts, must be avail-
able to the consumer application. The character sets and encodings for these
fonts are listed in Appendix D. The Adobe font metrics (AFM) files for the stan-
dard 14 fonts are available from the ASN Web site (see the Bibliography). For
more information on font metrics, see Adobe Technical Note #5004, Adobe Font
Metrics File Format Specification.
Ordinarily, a font dictionary that refers to one of the standard fonts should omit
the FirstChar, LastChar, Widths, and FontDescriptor entries. However, it is per-
missible to override a standard font by including these entries and embedding the
font program in the PDF file. (See implementation note 62 in Appendix H.)
Note: Beginning with PDF 1.5, the special treatment given to the standard 14 fonts
is deprecated. All fonts used in a PDF document should be represented using a com-
plete font descriptor. For backwards capability, viewer applications must still pro-
vide the special treatment identified for the standard 14 fonts.
Multiple Master Fonts
The multiple master font format is an extension of the Type 1 font format that al-
lows the generation of a wide variety of typeface styles from a single font pro-
gram. This is accomplished through the presence of various design dimensions in
the font. Examples of design dimensions are weight (light to extra-bold) and
width (condensed to expanded). Coordinates along these design dimensions
(such as the degree of boldness) are specified by numbers. A particular choice of
numbers selects an instance of the multiple master font. Adobe Technical Note
#5015, Type 1 Font Format Supplement, describes multiple master fonts in detail.
417
SECTION 5.5
Simple Fonts
The font dictionary for a multiple master font instance has the same entries as a
Type 1 font dictionary (Table 5.8 on page 413), with the following differences:
• The value of Subtype is MMType1.
• If the PostScript name of the instance contains spaces, the spaces are replaced
by underscores in the value of BaseFont. For instance, as illustrated in Example
5.7, the name “MinionMM 366 465 11 ” (which ends with a space character)
becomes /MinionMM_366_465_11_.
Example 5.7
7 0 obj
<< /Type /Font
/Subtype /MMType1
/BaseFont /MinionMM_366_465_11_
/FirstChar
32
/LastChar 255
/Widths 19 0 R
/FontDescriptor 6 0 R
/Encoding 5 0 R
>>
endobj
19 0 obj
[
187 235 317 430 427 717 607 168 326 326 421 619 219 317 219 282 427
… Omitted data…
569 0 569 607 607 607 239 400 400 400 400 253 400 400 400 400 400
]
endobj
This example illustrates a convention for including the numeric values of the
design coordinates as part of the instance’s BaseFont name. This convention is
commonly used for accessing multiple master font instances from an external
source in the consumer application’s environment; it is documented in Adobe
Technical Note #5088, Font Naming Issues. However, this convention is not pre-
scribed as part of the PDF specification. In particular, if the font program for this
instance is embedded in the PDF file, it must be an ordinary Type 1 font program,
not a multiple master font program. This font program is called a snapshot of the
multiple master font instance that incorporates the chosen values of the design
coordinates.
418
CHAPTER 5
Text
5.5.2
TrueType Fonts
The TrueType font format was developed by Apple Computer, Inc., and has been
adopted as a standard font format for the Microsoft Windows operating system.
Specifications for the TrueType font file format are available in Apple’s TrueType
Reference Manual and Microsoft’s TrueType 1.0 Font Files Technical Specification.
Note: A TrueType font program can be embedded directly in a PDF file as a stream
object. The Type 42 font format that is defined for PostScript does not apply to PDF.
A TrueType font dictionary can contain the same entries as a Type 1 font dictio-
nary (Table 5.8 on page 413), with the following differences:
• The value of Subtype is TrueType.
• The value of BaseFont is derived differently, as described below.
• The value of Encoding is subject to limitations that are described in Section
5.5.5, “Character Encoding.”
The PostScript name for the value of BaseFont is determined in one of two ways:
• Use the PostScript name that is an optional entry in the “name” table of the
TrueType font.
• In the absence of such an entry in the “name” table, derive a PostScript name
from the name by which the font is known in the host operating system. On a
Windows system, the name is based on the lfFaceName field in a LOGFONT
structure; in the Mac OS, it is based on the name of the FOND resource. If the
name contains any spaces, the spaces are removed.
If the font in a source document uses a bold or italic style but there is no font data
for that style, the host operating system synthesizes the style. In this case, a com-
ma and the style name (one of Bold, Italic, or BoldItalic) are appended to the font
name. For example, for a TrueType font that is a bold variant of the New York
font, the BaseFont value is written as /NewYork , Bold (as illustrated in Example
5.8).
419
SECTION 5.5
Simple Fonts
Example 5.8
17 0 obj
<< /Type /Font
/Subtype /TrueType
/BaseFont /NewYork , Bold
/FirstChar
0
/LastChar 255
/Widths 23 0 R
/FontDescriptor 7 0 R
/Encoding /MacRomanEncoding
>>
endobj
23 0 obj
[
0 333 333 333 333 333 333 333 0 333 333 333 333 333 333 333 333 333
… Omitted data…
803 790 803 780 780 780 340 636 636 636 636 636 636 636 636 636 636
]
endobj
Note that for CJK (Chinese, Japanese, and Korean) fonts, the host font system’s
font name is often encoded in the host operating system’s script. For instance, a
Japanese font may have a name that is written in Japanese using some (unidenti-
fied) Japanese encoding. Thus, TrueType font names may contain multiple-byte
character codes, each of which requires multiple characters to represent in a PDF
name object (using the # notation to quote special characters as needed).
5.5.3
Font Subsets
PDF 1.1 permits documents to include subsets of Type 1 and TrueType fonts.
The font and font descriptor that describe a font subset are slightly different
from those of ordinary fonts. These differences allow an application to recog-
nize font subsets and to merge documents containing different subsets of the
same font. (For more information on font descriptors, see Section 5.7, “Font De-
scriptors.”)
For a font subset, the PostScript name of the font—the value of the font’s
BaseFont entry and the font descriptor’s FontName entry—begins with a tag
followed by a plus sign (+). The tag consists of exactly six uppercase letters; the
choice of letters is arbitrary, but different subsets in the same PDF file must have
different tags. For example, EOODIA+Poetica is the name of a subset of Poetica®, a
Type 1 font. (See implementation note 63 in Appendix H.)
420
CHAPTER 5
Text
5.5.4
Type 3 Fonts
Type 3 fonts differ from the other fonts supported by PDF. A Type 3 font dictio-
nary defines the font; font dictionaries for other fonts simply contain information
about the font and refer to a separate font program for the actual glyph descrip-
tions. In Type 3 fonts, glyphs are defined by streams of PDF graphics operators.
These streams are associated with character names. A separate encoding entry
maps character codes to the appropriate character names for the glyphs.
Type 3 fonts are more flexible than Type 1 fonts because the glyph descriptions
may contain arbitrary PDF graphics operators. However, Type 3 fonts have no
hinting mechanism for improving output at small sizes or low resolutions. A Type
3 font dictionary contains the entries listed in Table 5.9.
TABLE 5.9 Entries in a Type 3 font dictionary
KEY
TYPE
VALUE
Type
name
(Required) The type of PDF object that this dictionary describes; must be
Font for a font dictionary.
Subtype
name
(Required) The type of font; must be Type3 for a Type 3 font.
Name
name
(Required in PDF 1.0; optional otherwise) See Table 5.8 on page 413.
FontBBox
rectangle
(Required) A rectangle (see Section 3.8.4, “Rectangles”) expressed in the
glyph coordinate system, specifying the font bounding box. This is the small-
est rectangle enclosing the shape that would result if all of the glyphs of the
font were placed with their origins coincident and then filled.
If all four elements of the rectangle are zero, no assumptions are made based
on the font bounding box. If any element is nonzero, it is essential that the
font bounding box be accurate. If any glyph’s marks fall outside this bounding
box, incorrect behavior may result.
FontMatrix
array
(Required) An array of six numbers specifying the font matrix, mapping
glyph space to text space
(see Section
5.1.3,
“Glyph Positioning and
Metrics”). A common practice is to define glyphs in terms of a 1000-unit
glyph coordinate system, in which case the font matrix is
[ 0.001
0 0 0.001 0 0 ].
421
SECTION 5.5
Simple Fonts
KEY
TYPE
VALUE
CharProcs
dictionary
(Required) A dictionary in which each key is a character name and the value
associated with that key is a content stream that constructs and paints the
glyph for that character. The stream must include as its first operator either
d0 or d1, followed by operators describing one or more graphics objects,
which may include path, text, or image objects. See below for more details
about Type 3 glyph descriptions.
Encoding
name or
(Required) An encoding dictionary whose Differences array specifies the
dictionary
complete character encoding for this font (see Section 5.5.5, “Character
Encoding”; also see implementation note 64 in Appendix H).
FirstChar
integer
(Required) The first character code defined in the font’s Widths array.
LastChar
integer
(Required) The last character code defined in the font’s Widths array.
Widths
array
(Required; indirect reference preferred) An array of (LastChar − FirstChar + 1)
widths, each element being the glyph width for the character code that equals
FirstChar plus the array index. For character codes outside the range FirstChar
to LastChar, the width is 0. These widths are interpreted in glyph space as
specified by FontMatrix (unlike the widths of a Type 1 font, which are in
thousandths of a unit of text space).
Note: If FontMatrix specifies a rotation, only the horizontal component of the
transformed width is used. That is, the resulting displacement is always hori-
zontal in text space, as is the case for all simple fonts.
FontDescriptor
dictionary
(Required in Tagged PDF documents; must be an indirect reference) A font de-
scriptor describing the font’s default metrics other than its glyph widths (see
Section 5.7, “Font Descriptors”).
Resources
dictionary
(Optional but strongly recommended; PDF 1.2) A list of the named resources,
such as fonts and images, required by the glyph descriptions in this font (see
Section 3.7.2, “Resource Dictionaries”). If any glyph descriptions refer to
named resources but this dictionary is absent, the names are looked up in the
resource dictionary of the page on which the font is used. (See implementa-
tion note 65 in Appendix H.)
ToUnicode
stream
(Optional; PDF 1.2) A stream containing a CMap file that maps character
codes to Unicode values (see Section 5.9, “Extraction of Text Content”).
422
CHAPTER 5
Text
For each character code shown by a text-showing operator that uses a Type 3 font,
the consumer application does the following:
1. Looks up the character code in the font’s Encoding entry, as described in Sec-
tion 5.5.5, “Character Encoding,” to obtain a character name.
2. Looks up the character name in the font’s CharProcs dictionary to obtain a
stream object containing a glyph description. (If the name is not present as a
key in CharProcs, no glyph is painted.)
3. Invokes the glyph description, as described below. The graphics state is saved
before this invocation and restored afterward; therefore, any changes the glyph
description makes to the graphics state do not persist after it finishes.
When the glyph description begins execution, the current transformation matrix
(CTM) is the concatenation of the font matrix (FontMatrix in the current font
dictionary) and the text space that was in effect at the time the text-showing op-
erator was invoked (see Section 5.3.3, “Text Space Details”). This means that
shapes described in the glyph coordinate system are transformed into the user
coordinate system and appear in the appropriate size and orientation on the page.
The glyph description should describe the glyph in terms of absolute coordinates
in the glyph coordinate system, placing the glyph origin at (0, 0) in this space. It
should make no assumptions about the initial text position.
Aside from the CTM, the graphics state is inherited from the environment of the
text-showing operator that caused the glyph description to be invoked. To ensure
predictable results, the glyph description must initialize any graphics state
parameters on which it depends. In particular, if it invokes the S (stroke) opera-
tor, it should explicitly set the line width, line join, line cap, and dash pattern to
appropriate values. Normally, it is unnecessary and undesirable to initialize the
current color parameter because the text-showing operators are designed to paint
glyphs with the current color.
The glyph description must execute one of the operators described in Table 5.10
to pass width and bounding box information to the font machinery. This must
precede the execution of any path construction or path-painting operators de-
scribing the glyph.
Note: Type 3 fonts in PDF are very similar to those in PostScript. Some of the in-
formation provided in Type 3 font dictionaries and glyph descriptions, while seem-
ingly redundant or unnecessary, is nevertheless required for correct results when a
423
SECTION 5.5
Simple Fonts
PDF consumer application prints to a PostScript output device. This applies par-
ticularly to the operands of the d0 and d1 operators, which in PostScript are
named setcharwidth and setcachedevice. For further explanation, see Section 5.7
of the PostScript Language Reference, Third Edition.
TABLE 5.10 Type 3 font operators
OPERANDS
OPERATOR
DESCRIPTION
wx wy
d0
Set width information for the glyph and declare that the glyph descrip-
tion specifies both its shape and its color. (Note that this operator name
ends in the digit 0.) wx specifies the horizontal displacement in the glyph
coordinate system; it must be consistent with the corresponding width
in the font’s Widths array. wy must be 0 (see Section 5.1.3, “Glyph Posi-
tioning and Metrics”).
This operator is permitted only in a content stream appearing in a
Type 3 font’s CharProcs dictionary. It is typically used only if the glyph
description executes operators to set the color explicitly.
w
ll
ur
ur
d1
Set width and bounding box information for the glyph and declare that
x wy llx
y
x
y
the glyph description specifies only shape, not color. (Note that this
operator name ends in the digit 1.) wx specifies the horizontal displace-
ment in the glyph coordinate system; it must be consistent with the
corresponding width in the font’s Widths array. wy must be 0 (see Section
5.1.3, “Glyph Positioning and Metrics”).
ll
x and lly are the coordinates of the lower-left corner, and urx and ury the
upper-right corner, of the glyph bounding box. The glyph bounding box
is the smallest rectangle, oriented with the axes of the glyph coordinate
system, that completely encloses all marks placed on the page as a result
of executing the glyph’s description. The declared bounding box must be
correct—in other words, sufficiently large to enclose the entire glyph. If
any marks fall outside this bounding box, the result is unpredictable.
A glyph description that begins with the d1 operator should not execute
any operators that set the color (or other color-related parameters) in the
graphics state; any use of such operators is ignored. The glyph descrip-
tion is executed solely to determine the glyph’s shape. Its color is deter-
mined by the graphics state in effect each time this glyph is painted by a
text-showing operator. For the same reason, the glyph description may
not include an image; however, an image mask is acceptable, since it
merely defines a region of the page to be painted with the current color.
This operator is permitted only in a content stream appearing in a
Type 3 font’s CharProcs dictionary.
424
CHAPTER 5
Text
Example of a Type 3 Font
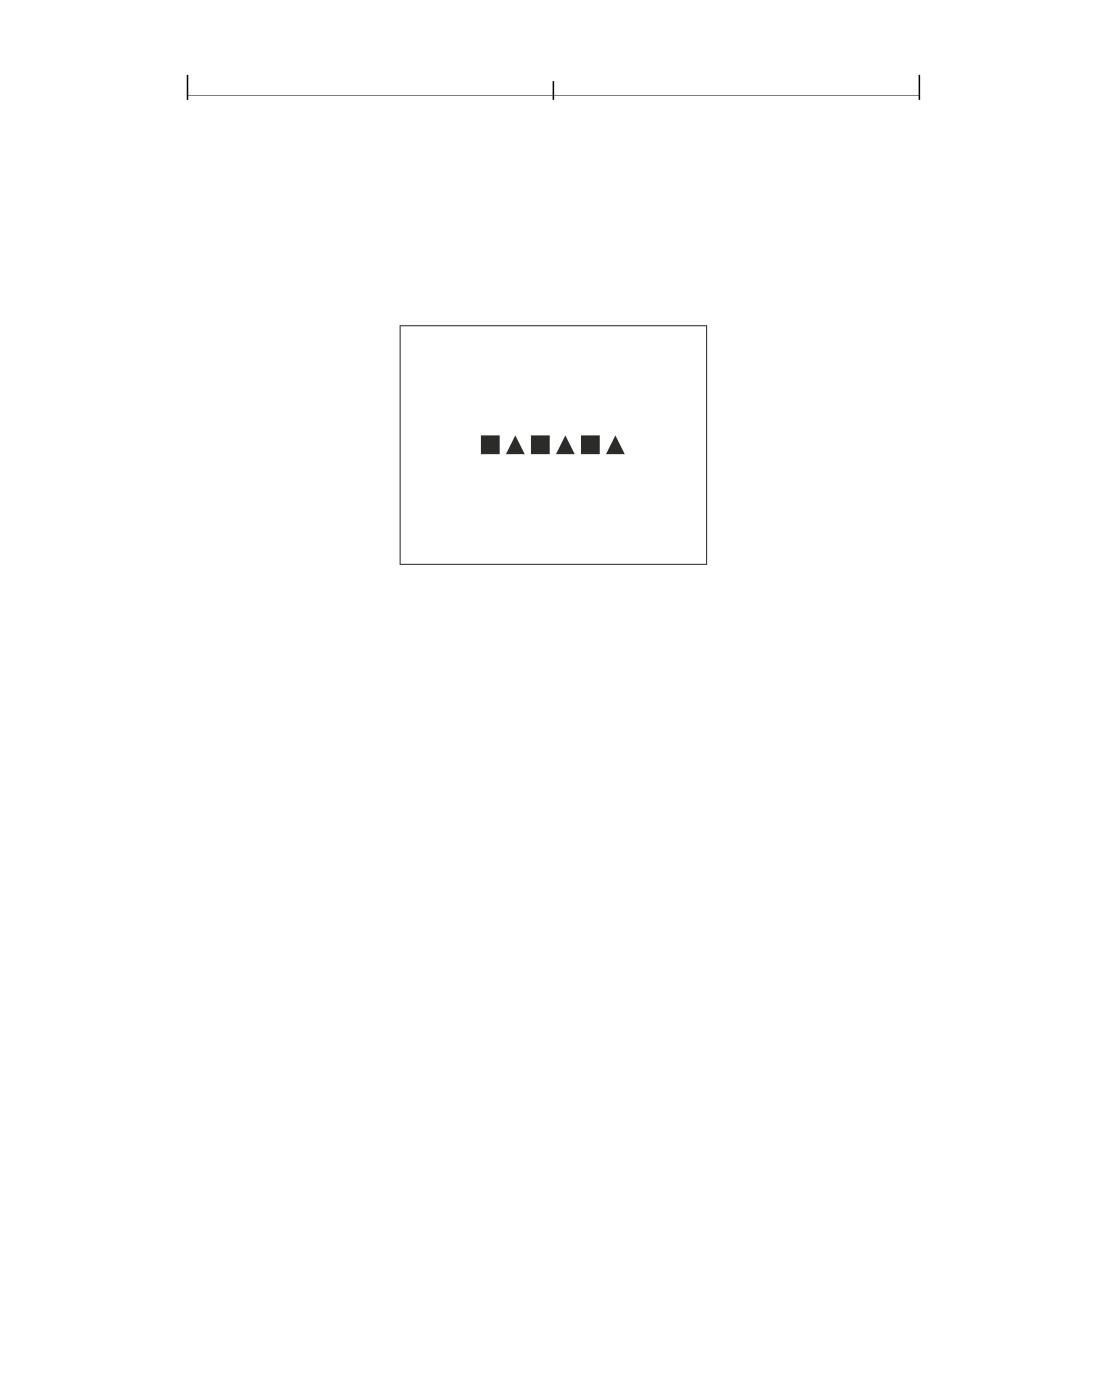
Example shows the definition of a Type 3 font with only two glyphs—a filled
square and a filled triangle, selected by the character codes a and b. Figure 5.12
shows the result of showing the string ( ababab ) using this font.
FIGURE 5.12 Output from Example
4 0 obj
<< /Type /Font
/Subtype /Type3
/FontBBox [ 0 0 750 750 ]
/FontMatrix [ 0.001 0 0 0.001 0 0 ]
/CharProcs 10 0 R
/Encoding 9 0 R
/FirstChar
97
/LastChar 98
/Widths [ 1000 1000 ]
>>
endobj
9 0 obj
<< /Type /Encoding
/Differences [ 97 /square /triangle ]
>>
endobj
10 0 obj
<< /square 11 0 R
/triangle
12 0 R
>>
endobj
425
SECTION 5.5
Simple Fonts
11 0 obj
<< /Length 39 >>
stream
1000 0 0 0 750 750 d1
0 0 750 750 re
f
endstream
endobj
12 0 obj
<< /Length 48 >>
stream
1000 0 0 0 750 750 d1
0 0 m
375 750 l
750 0 l
f
endstream
endobj
5.5.5
Character Encoding
A font’s encoding is the association between character codes (obtained from text
strings that are shown) and glyph descriptions. This section describes the charac-
ter encoding scheme used with simple PDF fonts. Composite fonts (Type 0) use a
different character mapping algorithm, as discussed in Section 5.6, “Composite
Fonts.”
Except for Type 3 fonts, every font program has a built-in encoding. Under cer-
tain circumstances, a PDF font dictionary can change a font’s built-in encoding to
match the requirements of the application generating the text being shown. This
flexibility in character encoding is valuable for two reasons:
• It permits showing text that is encoded according to any of the various existing
conventions. For example, the Microsoft Windows and Apple Mac OS oper-
ating systems use different standard encodings for Latin text, and many appli-
cations use their own special-purpose encodings.
• It permits applications to specify how characters selected from a large character
set are to be encoded. Some character sets consist of more than 256 characters,
including ligatures, accented characters, and other symbols required for high-
426
CHAPTER 5
Text
quality typography or non-Latin writing systems. Different encodings can se-
lect different subsets of the same character set.
Latin-text font programs produced by Adobe Systems use the Adobe standard
encoding, often referred to as StandardEncoding. The name StandardEncoding
has no special meaning in PDF, but this encoding does play a role as a default en-
coding (as shown in Table 5.11 below). The regular encodings used for Latin-text
fonts on Mac OS and Windows systems are named MacRomanEncoding and
WinAnsiEncoding, respectively. An encoding named MacExpertEncoding is used
with “expert” fonts that contain additional characters useful for sophisticated ty-
pography. Complete details of these encodings and of the characters present in
typical fonts are provided in Appendix D.
In PDF, a font is classified as either nonsymbolic or symbolic according to whether
all of its characters are members of the Adobe standard Latin character set. This
is indicated by flags in the font descriptor; see Section 5.7.1, “Font Descriptor
Flags.” Symbolic fonts contain other character sets, to which the encodings men-
tioned above ordinarily do not apply. Such font programs have built-in encodings
that are usually unique to each font. The standard 14 fonts include two symbolic
fonts, Symbol and ZapfDingbats, whose encodings and character sets are docu-
mented in Appendix D.
A font program’s built-in encoding can be overridden or altered by including an
Encoding entry in the PDF font dictionary. The possible encoding modifications
depend on the font type, as discussed below. The value of the Encoding entry is
either a named encoding
(the name of one of the predefined encodings
MacRomanEncoding, MacExpertEncoding, or WinAnsiEncoding) or an encoding
dictionary. An encoding dictionary contains the entries listed in Table 5.11.
427
SECTION 5.5
Simple Fonts
TABLE 5.11 Entries in an encoding dictionary
KEY
TYPE
VALUE
Type
name
(Optional) The type of PDF object that this dictionary describes; if present, must
be Encoding for an encoding dictionary.
BaseEncoding
name
(Optional) The base encoding—that is, the encoding from which the Differences
entry (if present) describes differences—specified as the name of a predefined
encoding MacRomanEncoding, MacExpertEncoding, or WinAnsiEncoding (see
Appendix D).
If this entry is absent, the Differences entry describes differences from an im-
plicit base encoding. For a font program that is embedded in the PDF file, the
implicit base encoding is the font program’s built-in encoding, as described
above and further elaborated in the sections on specific font types below. Other-
wise, for a nonsymbolic font, it is StandardEncoding, and for a symbolic font, it
is the font’s built-in encoding.
Differences
array
(Optional; not recommended with TrueType fonts) An array describing the differ-
ences from the encoding specified by BaseEncoding or, if BaseEncoding is ab-
sent, from an implicit base encoding. The Differences array is described below.
The value of the Differences entry is an array of character codes and character
names organized as follows:
code1 name1,1 name1,2 …
code2 name2,1 name2,2 …
…
coden namen,1 namen,2 …
Each code is the first index in a sequence of character codes to be changed. The
first character name after the code becomes the name corresponding to that code.
Subsequent names replace consecutive code indices until the next code appears
in the array or the array ends. These sequences may be specified in any order but
should not overlap.
For example, in the encoding dictionary in Example 5.9, the name quotesingle (' )
is associated with character code 39, Adieresis (Ä) with code 128, Aring (Å) with
129, and trademark (™) with 170.
428
CHAPTER 5
Text
Example 5.9
25 0 obj
<< /Type /Encoding
/Differences
[
39 /quotesingle
96 /grave
128 /Adieresis /Aring /Ccedilla /Eacute /Ntilde /Odieresis /Udieresis
/aacute /agrave /acircumflex /adieresis /atilde /aring /ccedilla
/eacute /egrave /ecircumflex /edieresis /iacute /igrave /icircumflex
/idieresis
/ntilde
/oacute /ograve /ocircumflex /odieresis /otilde
/uacute /ugrave /ucircumflex /udieresis /dagger /degree /cent
/sterling
/section /bullet
/paragraph /germandbls /registered
/copyright /trademark /acute /dieresis
174 /AE /Oslash
177 /plusminus
180 /yen /mu
187 /ordfeminine /ordmasculine
190 /ae /oslash /questiondown /exclamdown /logicalnot
196 /florin
199 /guillemotleft /guillemotright /ellipsis
203 /Agrave /Atilde /Otilde /OE /oe /endash /emdash /quotedblleft
/quotedblright /quoteleft /quoteright /divide
216 /ydieresis /Ydieresis /fraction /currency /guilsinglleft /guilsinglright
/fi
/fl
/daggerdbl
/periodcentered /quotesinglbase /quotedblbase
/perthousand /Acircumflex /Ecircumflex /Aacute /Edieresis /Egrave
/Iacute
/Icircumflex
/Idieresis
/Igrave /Oacute /Ocircumflex
241 /Ograve /Uacute /Ucircumflex /Ugrave /dotlessi /circumflex /tilde
/macron /breve /dotaccent
/ring
/cedilla
/hungarumlaut /ogonek
/caron
]
>>
endobj
By convention, the name . notdef can be used to indicate that no character name
is associated with a given character code.
Encodings for Type 1 Fonts
A Type 1 font program’s glyph descriptions are keyed by character names, not by
character codes. Character names are ordinary PDF name objects. Descriptions of
Latin alphabetic characters are normally associated with names consisting of
single letters, such as A or a. Other characters are associated with names com-
429
SECTION 5.5
Simple Fonts
posed of words, such as three, ampersand, or parenleft. A Type 1 font’s built-in
encoding is defined by an Encoding array that is part of the font program, not to
be confused with the Encoding entry in the PDF font dictionary.
An Encoding entry can alter a Type 1 font’s mapping from character codes to
character names. The Differences array can map a code to the name of any glyph
description that exists in the font program, regardless of whether that glyph is ref-
erenced by the font’s built-in encoding or by the encoding specified in the
BaseEncoding entry.
All Type 1 font programs contain an actual glyph named . notdef. The effect pro-
duced by showing the . notdef glyph is at the discretion of the font designer; in
Type 1 font programs produced by Adobe, it is the same as the space character. If
an encoding maps to a character name that does not exist in the Type 1 font pro-
gram, the . notdef glyph is substituted.
Encodings for Type 3 Fonts
A Type 3 font, like a Type 1 font, contains glyph descriptions that are keyed by
character names; in this case, they appear as explicit keys in the font’s CharProcs
dictionary. A Type 3 font’s mapping from character codes to character names is
entirely defined by its Encoding entry, which is required in this case.
Encodings for TrueType Fonts
A TrueType font program’s built-in encoding maps directly from character codes
to glyph descriptions by means of an internal data structure called a “cmap” (not
to be confused with the CMap described in Section 5.6.4, “CMaps”). This section
describes how the PDF font dictionary’s Encoding entry is used in conjunction
with a “cmap” to map from a character code in a string to a glyph description in a
TrueType font program.
A “cmap” table may contain one or more subtables that represent multiple encod-
ings intended for use on different platforms (such as Mac OS and Windows).
Each subtable is identified by the two numbers, such as (3, 1), that represent a
combination of a platform ID and a platform-specific encoding ID, respectively.
Glyph names are not mandatory in TrueType fonts, although some font programs
have an optional “post” table listing glyph names for the glyphs. If the consumer
430
CHAPTER 5
Text
application needs to select glyph descriptions by name, it translates from glyph
names to codes in one of the encodings given in the font program’s “cmap” table.
When there is no character code in the “cmap” that corresponds to a glyph name,
the “post” table is used to select a glyph description directly from the glyph name.
Because some aspects of TrueType glyph selection are dependent on the consum-
er implementation or the operating system, PDF files that use TrueType fonts
should follow certain guidelines to ensure predictable behavior across all applica-
tions:
• The font program should be embedded.
• A nonsymbolic font should specify MacRomanEncoding or WinAnsiEncoding
as the value of its Encoding entry, with no Differences array.
• A font that is used to display glyphs that do not use MacRomanEncoding or
WinAnsiEncoding should not specify an Encoding entry. The font descriptor’s
Symbolic flag (see Table 5.20) should be set, and its font program’s “cmap” table
should contain a (1, 0) subtable. It may also contain a (3, 0) subtable; if present,
this subtable should map from character codes in the range 0xF000 to 0xF0FF
by prepending the single-byte codes in the (1, 0) subtable with 0xF0 and map-
ping to the corresponding glyph descriptions.
Note: Some popular TrueType font programs contain incorrect encoding informa-
tion. Implementations of TrueType font interpreters have evolved heuristics for deal-
ing with such problems; those heuristics are not described here. For maximum
portability, only well-formed TrueType font programs should be used in PDF files.
Therefore, a TrueType font program in a PDF file may need to be modified to con-
form to the guidelines described above.
The following paragraphs describe the treatment of TrueType font encodings be-
ginning with PDF 1.3, as implemented in Acrobat 5.0 and later viewers. This in-
formation does not necessarily apply to earlier versions or implementations.
If the font has a named Encoding entry of either MacRomanEncoding or
WinAnsiEncoding, or if the font descriptor’s Nonsymbolic flag (see Table 5.20) is
set, the viewer creates a table that maps from character codes to glyph names:
• If the Encoding entry is one of the names MacRomanEncoding or WinAnsiEn-
coding, the table is initialized with the mappings described in Appendix D.
431
SECTION 5.5
Simple Fonts
• If the Encoding entry is a dictionary, the table is initialized with the entries
from the dictionary’s BaseEncoding entry (see Table 5.11). Any entries in the
Differences array are used to update the table. Finally, any undefined entries in
the table are filled using StandardEncoding.
If a (3, 1) “cmap” subtable (Microsoft Unicode) is present:
• A character code is first mapped to a glyph name using the table described
above.
• The glyph name is then mapped to a Unicode value by consulting the Adobe
Glyph List (see the Bibliography).
• Finally, the Unicode value is mapped to a glyph description according to the
(3, 1) subtable.
If no (3, 1) subtable is present but a (1, 0) subtable (Macintosh Roman) is present:
• A character code is first mapped to a glyph name using the table described
above.
• The glyph name is then mapped back to a character code according to the stan-
dard Roman encoding used on Mac OS (see note below).
• Finally, the code is mapped to a glyph description according to the (1, 0) sub-
table.
In either of the cases above, if the glyph name cannot be mapped as specified, the
glyph name is looked up in the font program’s “post” table (if one is present) and
the associated glyph description is used.
Note: The standard Roman encoding that is used on Mac OS is the same as the
MacRomanEncoding described in Appendix D, with the addition of following 15 en-
tries and the replacement of the currency glyph with the Euro glyph, as shown in Ta-
ble 5.12.
TABLE 5.12 Differences between MacRomanEncoding and Mac OS Roman encoding
NAME
CODE (OCTAL)
CODE (DECIMAL)
notequal
255
173
infinity
260
176
432
CHAPTER 5
Text
NAME
CODE (OCTAL)
CODE (DECIMAL)
lessequal
262
178
greaterequal
263
179
partialdiff
266
182
summation
267
183
product
270
184
pi
271
185
integral
272
186
Omega
275
189
radical
303
195
approxequal
305
197
Delta
306
198
lozenge
327
215
Euro
333
219
apple
360
240
When the font has no Encoding entry, or the font descriptor’s Symbolic flag is set
(in which case the Encoding entry is ignored), the following occurs:
• If the font contains a (3, 0) subtable, the range of character codes must be one
of the following:
0x0000 - 0x00FF,
0xF000 - 0xF0FF,
0xF100 - 0xF1FF, or
0xF200 - 0xF2FF. Depending on the range of codes, each byte from the string is
prepended with the high byte of the range, to form a two-byte character, which
is used to select the associated glyph description from the subtable.
• Otherwise, if the font contains a (1, 0) subtable, single bytes from the string are
used to look up the associated glyph descriptions from the subtable.
If a character cannot be mapped in any of the ways described above, the results
are implementation-dependent.
433
SECTION 5.6
Composite Fonts
5.6
Composite Fonts
A composite font, also called a Type 0 font, is one whose glyphs are obtained from
a fontlike object called a CIDFont. A composite font is represented by a font dic-
tionary whose Subtype value is Type0. The Type 0 font is known as the root font,
and its associated CIDFont is called its descendant.
Note: Composite fonts in PDF are analogous to composite fonts in PostScript but
with some limitations. In particular, PDF requires that the character encoding be
defined by a CMap (described below), which is only one of several encoding methods
available in PostScript.Also, PostScript allows a Type 0 font to have multiple descen-
dants, which might also be Type 0 fonts. PDF supports only a single descendant,
which must be a CIDFont.
When the current font is composite, the text-showing operators behave different-
ly than with simple fonts. For simple fonts, each byte of a string to be shown se-
lects one glyph, whereas for composite fonts, a sequence of one or more bytes can
be decoded to select a glyph from the descendant CIDFont. This facility supports
the use of very large character sets, such as those for the Chinese, Japanese, and
Korean languages. It also simplifies the organization of fonts that have complex
encoding requirements.
This section first introduces the architecture of CID-keyed fonts, which are the
only kind of composite font supported in PDF. Then it describes the CIDFont and
CMap dictionaries, which are the PDF objects that represent the correspondingly
named components of a CID-keyed font. Finally, it describes the Type 0 font dic-
tionary, which combines a CIDFont and a CMap to produce a font whose glyphs
can be accessed by means of variable-length character codes in a string to be
shown.
5.6.1
CID-Keyed Fonts Overview
CID-keyed fonts provide a convenient and efficient method for defining
multiple-byte character encodings, fonts with a large number of glyphs, and fonts
that incorporate glyphs obtained from other fonts. These capabilities provide
great flexibility for representing text in writing systems for languages with large
character sets, such as Chinese, Japanese, and Korean (CJK).
The CID-keyed font architecture specifies the external representation of certain
font programs, called CMap and CIDFont files, along with some conventions for
434
CHAPTER 5
Text
combining and using those files. As mentioned earlier, PDF does not support the
entire CID-keyed font architecture, which is independent of PDF; CID-keyed
fonts can be used in other environments. For complete documentation on the ar-
chitecture and the file formats, see Adobe Technical Notes #5092, CID-Keyed
Font Technology Overview, and #5014, Adobe CMap and CIDFont Files Specifica-
tion. This section describes only the PDF objects that represent these font pro-
grams.
The term CID-keyed font reflects the fact that CID (character identifier) numbers
are used to index and access the glyph descriptions in the font. This method is
more efficient for large fonts than the method of accessing by character name, as
is used for some simple fonts. CIDs range from 0 to a maximum value that is sub-
ject to an implementation limit (see Table C.1 on page 992).
A character collection is an ordered set of all glyphs needed to support one or
more popular character sets for a particular language. The order of the glyphs in
the character collection determines the CID number for each glyph. Each CID-
keyed font must explicitly reference the character collection on which its CID
numbers are based; see Section 5.6.2, “CIDSystemInfo Dictionaries.”
A CMap (character map) file specifies the correspondence between character
codes and the CID numbers used to identify glyphs. It is equivalent to the con-
cept of an encoding in simple fonts. Whereas a simple font allows a maximum of
256 glyphs to be encoded and accessible at one time, a CMap can describe a map-
ping from multiple-byte codes to thousands of glyphs in a large CID-keyed font.
For example, it can describe Shift-JIS, one of several widely used encodings for
Japanese.
A CMap can reference an entire character collection, a subset, or multiple charac-
ter collections. It can also reference characters in other fonts by character code or
character name. The CMap mapping yields a font number (which in PDF is al-
ways 0) and a character selector (which in PDF is always a CID). Furthermore, a
CMap can incorporate another CMap by reference, without having to duplicate it.
These features enable character collections to be combined or supplemented and
make all the constituent characters accessible to text-showing operations through
a single encoding.
A CIDFont file contains the glyph descriptions for a character collection. The
glyph descriptions themselves are typically in a format similar to those used in
simple fonts, such as Type 1. However, they are identified by CIDs rather than by
names, and they are organized differently.
435
SECTION 5.6
Composite Fonts
In PDF, the CMap and CIDFont are represented by PDF objects, which are de-
scribed below. The CMap and CIDFont programs themselves can be either refer-
enced by name or embedded as stream objects in the PDF file. As stated earlier,
the external file formats are documented in Adobe Technical Note #5014, Adobe
CMap and CIDFont Files Specification.
A CID-keyed font, then, is the combination of a CMap with a CIDFont contain-
ing glyph descriptions. It is represented as a Type 0 font. It contains an Encoding
entry whose value is a CMap dictionary, and its DescendantFonts entry refer-
ences the CIDFont dictionary with which the CMap has been combined.
5.6.2
CIDSystemInfo Dictionaries
CIDFont and CMap dictionaries contain a CIDSystemInfo entry specifying the
character collection assumed by the CIDFont associated with the CMap—that is,
the interpretation of the CID numbers used by the CIDFont. A character collec-
tion is uniquely identified by the Registry, Ordering, and Supplement entries in
the CIDSystemInfo dictionary, as described in Table 5.13. Character collections
whose Registry and Ordering values are the same are compatible.
The CIDSystemInfo entry in a CIDFont is a dictionary that specifies the
CIDFont’s character collection. The CIDFont need not contain glyph descriptions
for all the CIDs in a collection; it can contain a subset. The CIDSystemInfo entry
in a CMap is either a single dictionary or an array of dictionaries, depending on
whether it associates codes with a single character collection or with multiple
character collections; see Section 5.6.4, “CMaps.”
For proper behavior, the CIDSystemInfo entry of a CMap should be compatible
with that of the CIDFont or CIDFonts with which it is used. If they are incompat-
ible, the effects produced are unpredictable.
TABLE 5.13 Entries in a CIDSystemInfo dictionary
KEY
TYPE
VALUE
Registry
ASCII
(Required) A string identifying the issuer of the character collection—for example,
string
Adobe. For information about assigning a registry identifier, contact the Adobe
Solutions Network or consult the ASN Web site (see the Bibliography).
Ordering
ASCII
(Required) A string that uniquely names the character collection within the speci-
string
fied registry—for example, Japan1.
436
CHAPTER 5
Text
KEY
TYPE
VALUE
Supplement
integer
(Required) The supplement number of the character collection. An original charac-
ter collection has a supplement number of 0. Whenever additional CIDs are
assigned in a character collection, the supplement number is increased. Supple-
ments do not alter the ordering of existing CIDs in the character collection. This
value is not used in determining compatibility between character collections.
5.6.3
CIDFonts
A CIDFont program contains glyph descriptions that are accessed using a CID as
the character selector. There are two types of CIDFonts:
• A Type 0 CIDFont contains glyph descriptions based on the Adobe Type 1 font
format
Note: The term “Type 0” when applied to a CIDFont has a different meaning than
for a “Type 0 font”.
• A Type 2 CIDFont contains glyph descriptions based on the TrueType font format
A CIDFont dictionary is a PDF object that contains information about a CIDFont
program. Although its Type value is Font, a CIDFont is not actually a font. It does
not have an Encoding entry, it cannot be listed in the Font subdictionary of a re-
source dictionary, and it cannot be used as the operand of the Tf operator. It is
used only as a descendant of a Type 0 font. The CMap in the Type 0 font is what
defines the encoding that maps character codes to CIDs in the CIDFont. Table
5.14 lists the entries in a CIDFont dictionary.
TABLE 5.14 Entries in a CIDFont dictionary
KEY
TYPE
VALUE
Type
name
(Required) The type of PDF object that this dictionary describes; must be
Font for a CIDFont dictionary.
Subtype
name
(Required) The type of CIDFont; CIDFontType0 or CIDFontType2.
BaseFont
name
(Required) The PostScript name of the CIDFont. For Type 0 CIDFonts, this
is usually the value of the CIDFontName entry in the CIDFont program. For
Type 2 CIDFonts, it is derived the same way as for a simple TrueType font;
see Section 5.5.2, “TrueType Fonts.” In either case, the name can have a sub-
set prefix if appropriate; see Section 5.5.3, “Font Subsets.”
437
SECTION 5.6
Composite Fonts
KEY
TYPE
VALUE
CIDSystemInfo
dictionary
(Required) A dictionary containing entries that define the character collec-
tion of the CIDFont. See Table 5.13 on page 435.
FontDescriptor
dictionary
(Required; must be an indirect reference) A font descriptor describing the
CIDFont’s default metrics other than its glyph widths (see Section 5.7, “Font
Descriptors”).
DW
integer
(Optional) The default width for glyphs in the CIDFont (see “Glyph Metrics
in CIDFonts” on page 439). Default value: 1000.
W
array
(Optional) A description of the widths for the glyphs in the CIDFont. The
array’s elements have a variable format that can specify individual widths
for consecutive CIDs or one width for a range of CIDs (see “Glyph Metrics
in CIDFonts” on page 439). Default value: none (the DW value is used for all
glyphs).
DW2
array
(Optional; applies only to CIDFonts used for vertical writing) An array of two
numbers specifying the default metrics for vertical writing (see “Glyph
Metrics in CIDFonts” on page 439). Default value: [ 880 −1000 ].
W2
array
(Optional; applies only to CIDFonts used for vertical writing) A description
of the metrics for vertical writing for the glyphs in the CIDFont (see “Glyph
Metrics in CIDFonts” on page 439). Default value: none (the DW2 value is
used for all glyphs).
CIDToGIDMap
stream
(Optional; Type 2 CIDFonts only) A specification of the mapping from CIDs
or name
to glyph indices. If the value is a stream, the bytes in the stream contain the
mapping from CIDs to glyph indices: the glyph index for a particular CID
value c is a 2-byte value stored in bytes 2 × c and 2 × c + 1, where the first
byte is the high-order byte. If the value of CIDToGIDMap is a name, it must
be Identity, indicating that the mapping between CIDs and glyph indices is
the identity mapping. Default value: Identity.
This entry may appear only in a Type 2 CIDFont whose associated True-
Type font program is embedded in the PDF file (see the next section).
Glyph Selection in CIDFonts
Type 0 and Type 2 CIDFonts handle the mapping from CIDs to glyph descrip-
tions in somewhat different ways.
438
CHAPTER 5
Text
For Type 0, the CIDFont program contains glyph descriptions that are identified
by CIDs. The CIDFont program identifies the character collection by a
CIDSystemInfo dictionary, which should simply be copied into the PDF CIDFont
dictionary. CIDs are interpreted uniformly in all CIDFont programs supporting a
given character collection, whether the program is embedded in the PDF file or
obtained from an external source.
When the CIDFont contains an embedded font program that is represented in
the Compact Font Format (CFF), the FontFile3 entry in the font descriptor (see
Table 5.23) can be CIDFontType0C or OpenType. There are two cases, depending
on the contents of the font program:
• The “CFF” font program has a Top DICT that uses CIDFont operators: The CIDs
are used to determine the GID value for the glyph procedure using the charset
table in the CFF program. The GID value is then used to look up the glyph pro-
cedure using the CharStrings INDEX table. Although in many fonts the CID val-
ue and GID value are the same, the CID and GID values may differ.
• The “CFF” font program has a Top DICT that does not use CIDFont operators:
The CIDs are used directly as GID values, and the glyph procedure is retrieved
using the CharStrings INDEX.
For Type 2, the CIDFont program is actually a TrueType font program, which has
no native notion of CIDs. In a TrueType font program, glyph descriptions are
identified by glyph index values. Glyph indices are internal to the font and are not
defined consistently from one font to another. Instead, a TrueType font program
contains a “cmap” table that provides mappings directly from character codes to
glyph indices for one or more predefined encodings.
TrueType font programs are integrated with the CID-keyed font architecture in
one of two ways, depending on whether the font program is embedded in the
PDF file:
• If the TrueType font program is embedded, the Type 2 CIDFont dictionary
must contain a CIDToGIDMap entry that maps CIDs to the glyph indices for the
appropriate glyph descriptions in that font program.
• If the TrueType font program is not embedded but is referenced by name, the
Type 2 CIDFont dictionary must not contain a CIDToGIDMap entry, since it is
not meaningful to refer to glyph indices in an external font program. In this
case, CIDs do not participate in glyph selection, and only predefined CMaps
439
SECTION 5.6
Composite Fonts
may be used with this CIDFont (see Section 5.6.4, “CMaps”). The consumer
application selects glyphs by translating characters from the encoding specified
by the predefined CMap to one of the encodings in the TrueType font’s “cmap”
table. The means by which this is accomplished are implementation-depen-
dent.
Even though the CIDs are sometimes not used to select glyphs in a Type 2
CIDFont, they are always used to determine the glyph metrics, as described in the
next section.
Every CIDFont must contain a glyph description for CID 0, which is analogous to
the . notdef character name in simple fonts (see “Handling Undefined Characters”
on page 454).
Glyph Metrics in CIDFonts
As discussed in Section 5.1.3, “Glyph Positioning and Metrics,” the width of a
glyph refers to the horizontal displacement between the origin of the glyph and
the origin of the next glyph when writing in horizontal mode. In this mode, the
vertical displacement between origins is always 0. Widths for a CIDFont are de-
fined using the DW and W entries in the CIDFont dictionary. These widths must
be consistent with the actual widths given in the CIDFont program. (See imple-
mentation note 61 in Appendix H.)
The DW entry defines the default width, which is used for all glyphs whose widths
are not specified individually. This entry is particularly useful for Chinese, Japa-
nese, and Korean fonts, in which many of the glyphs have the same width.
The W array allows the definition of widths for individual CIDs. The elements of
the array are organized in groups of two or three, where each group is in one of
the following two formats:
c [ w1 w2 … wn ]
cfirst clast w
In the first format, c is an integer specifying a starting CID value; it is followed by
an array of n numbers that specify the widths for n consecutive CIDs, starting
with c. The second format defines the same width, w, for all CIDs in the range
cfirst to clast .
440
CHAPTER 5
Text
The following is an example of a W entry:
/W [ 120 [ 400 325 500 ]
7080 8032 1000
]
In this example, the glyphs having CIDs 120, 121, and 122 are 400, 325, and 500
units wide, respectively. CIDs in the range 7080 through 8032 all have a width of
1000 units.
Glyphs from a CIDFont can be shown in vertical writing mode. (This is selected
by the WMode entry in the associated CMap dictionary; see Section 5.6.4,
“CMaps.”) To be used in this way, the CIDFont must define the vertical dis-
placement for each glyph and the position vector that relates the horizontal and
vertical writing origins.
The default position vector and vertical displacement vector are specified by the
DW2 entry in the CIDFont dictionary. DW2 is an array of two values: the vertical
component of the position vector v and the vertical component of the displace-
ment vector w1 (see Figure 5.5 on page 396). The horizontal component of the
position vector is always half the glyph width, and that of the displacement vector
is always 0. For example, if the DW2 entry is
/ DW2 [ 880 −1000 ]
then a glyph’s position vector and vertical displacement vector are
v = (w0 ÷ 2,880)
w1 = (0, -1000)
where w0 is the width (horizontal displacement) for the same glyph. Note that a
negative value for the vertical component places the origin of the next glyph be-
low the current glyph because vertical coordinates in a standard coordinate sys-
tem increase from bottom to top.
The W2 array allows the definition of vertical metrics for individual CIDs. The
elements of the array are organized in groups of two or five, where each group is
in one of the following two formats:
c [ w11y v1x v1y w12y v2x v2y
… ]
cfirst clast w11y v1x v1y
441
SECTION 5.6
Composite Fonts
In the first format, c is a starting CID and is followed by an array containing num-
bers interpreted in groups of three. Each group consists of the vertical component
of the vertical displacement vector w1 (whose horizontal component is always 0)
followed by the horizontal and vertical components for the position vector v. Suc-
cessive groups define the vertical metrics for consecutive CIDs starting with c.
The second format defines a range of CIDs from cfirst to clast , followed by three
numbers that define the vertical metrics for all CIDs in this range. For example:
/W2 [ 120 [ −1000 250 772 ]
7080 8032 −1000 500 900
]
This W2 entry defines the vertical displacement vector for the glyph with CID
120 as (0, −1000) and the position vector as (250, 772). It also defines the dis-
placement vector for CIDs in the range 7080 through 8032 as (0, −1000) and the
position vector as (500, 900).
5.6.4
CMaps
A CMap specifies the mapping from character codes to character selectors. In
PDF, the character selectors are always CIDs in a CIDFont (as mentioned earlier,
PostScript CMaps may use names or codes as well). A CMap serves a function
analogous to the Encoding dictionary for a simple font. The CMap does not refer
directly to a specific CIDFont; instead, it is combined with it as part of a CID-
keyed font, represented in PDF as a Type 0 font dictionary (see Section 5.6.5,
“Type 0 Font Dictionaries”). Within the CMap, the character mappings refer to
the associated CIDFont by font number, which in PDF is always 0.
Note: PDF also uses a special type of CMap to map character codes to Unicode val-
ues (see Section 5.9.2, “ToUnicode CMaps”).
A CMap also specifies the writing mode—horizontal or vertical—for any
CIDFont with which the CMap is combined. The writing mode determines
which metrics are to be used when glyphs are painted from that font. (Writing
mode is specified as part of the CMap because, in some cases, different shapes are
used when writing horizontally and vertically. In such cases, the horizontal and
vertical variants of a CMap specify different CIDs for a given character code.)
442
CHAPTER 5
Text
A CMap may be specified in two ways:
• As a name object identifying a predefined CMap, whose definition is known to
the consumer application
• As a stream object whose contents are a CMap file (see implementation note 66
in Appendix H)
Predefined CMaps
Table 5.15 lists the names of the predefined CMaps. These CMaps map character
codes to CIDs in a single descendant CIDFont. CMaps whose names end in H
specify horizontal writing mode; those ending in V specify vertical writing mode.
Note: Several of the CMaps define mappings from Unicode encodings to character
collections. Unicode values appearing in a text string are represented in big-endian
order (high-order byte first). CMap names containing "UCS2" use UCS-2 encoding;
names containing "UTF16" use UTF-16BE (big-endian) encoding.
TABLE 5.15 Predefined CJK CMap names
NAME
DESCRIPTION
Chinese (Simplified)
GB−EUC−H
Microsoft Code Page 936 (lfCharSet 0x86), GB 2312-80 character set, EUC-CN encoding
GB−EUC−V
Vertical version of GB−EUC−H
GBpc−EUC−H
Mac OS, GB 2312-80 character set, EUC-CN encoding, Script Manager code 19
GBpc−EUC−V
Vertical version of GBpc−EUC−H
GBK−EUC−H
Microsoft Code Page 936 (lfCharSet 0x86), GBK character set, GBK encoding
GBK−EUC−V
Vertical version of GBK−EUC−H
GBKp−EUC−H
Same as GBK−EUC−H but replaces half-width Latin characters with proportional forms
and maps character code 0x24 to a dollar sign ($) instead of a yuan symbol (¥)
GBKp−EUC−V
Vertical version of GBKp−EUC−H
GBK2K−H
GB 18030-2000 character set, mixed 1-, 2-, and 4-byte encoding
443
SECTION 5.6
Composite Fonts
NAME
DESCRIPTION
GBK2K−V
Vertical version of GBK2K−H
UniGB−UCS2−H
Unicode (UCS-2) encoding for the Adobe-GB1 character collection
UniGB−UCS2−V
Vertical version of UniGB−UCS2−H
UniGB−UTF16−H
Unicode (UTF-16BE) encoding for the Adobe-GB1 character collection; contains map-
pings for all characters in the GB18030-2000 character set
UniGB−UTF16−V
Vertical version of UniGB−UTF16−H
Chinese (Traditional)
B5pc−H
Mac OS, Big Five character set, Big Five encoding, Script Manager code 2
B5pc−V
Vertical version of B5pc−H
HKscs−B5−H
Hong Kong SCS, an extension to the Big Five character set and encoding
HKscs−B5−V
Vertical version of HKscs−B5−H
ETen−B5−H
Microsoft Code Page 950 (lfCharSet 0x88), Big Five character set with ETen extensions
ETen−B5−V
Vertical version of ETen−B5−H
ETenms−B5−H
Same as ETen−B5−H but replaces half-width Latin characters with proportional forms
ETenms−B5−V
Vertical version of ETenms−B5−H
CNS−EUC−H
CNS 11643-1992 character set, EUC-TW encoding
CNS−EUC−V
Vertical version of CNS−EUC−H
UniCNS−UCS2−H
Unicode (UCS-2) encoding for the Adobe-CNS1 character collection
UniCNS−UCS2−V
Vertical version of UniCNS−UCS2−H
UniCNS−UTF16−H
Unicode (UTF-16BE) encoding for the Adobe-CNS1 character collection; contains
mappings for all the characters in the HKSCS-2001 character set and contains both 2-
and 4-byte character codes
UniCNS−UTF16−V
Vertical version of UniCNS−UTF16−H
444
CHAPTER 5
Text
NAME
DESCRIPTION
Japanese
83pv−RKSJ−H
Mac OS, JIS X 0208 character set with KanjiTalk6 extensions, Shift-JIS encoding, Script
Manager code 1
90ms−RKSJ−H
Microsoft Code Page 932 (lfCharSet 0x80), JIS X 0208 character set with NEC and IBM®
extensions
90ms−RKSJ−V
Vertical version of 90ms−RKSJ−H
90msp−RKSJ−H
Same as 90ms−RKSJ−H but replaces half-width Latin characters with proportional forms
90msp−RKSJ−V
Vertical version of 90msp−RKSJ−H
90pv−RKSJ−H
Mac OS, JIS X 0208 character set with KanjiTalk7 extensions, Shift-JIS encoding, Script
Manager code 1
Add−RKSJ−H
JIS X 0208 character set with Fujitsu FMR extensions, Shift-JIS encoding
Add−RKSJ−V
Vertical version of Add−RKSJ−H
EUC−H
JIS X 0208 character set, EUC-JP encoding
EUC−V
Vertical version of EUC−H
Ext−RKSJ−H
JIS C 6226 (JIS78) character set with NEC extensions, Shift-JIS encoding
Ext−RKSJ−V
Vertical version of Ext−RKSJ−H
H
JIS X 0208 character set, ISO-2022-JP encoding
V
Vertical version of H
UniJIS−UCS2−H
Unicode (UCS-2) encoding for the Adobe-Japan1 character collection
UniJIS−UCS2−V
Vertical version of UniJIS−UCS2−H
UniJIS−UCS2−HW−H
Same as UniJIS−UCS2−H but replaces proportional Latin characters with half-width
forms
UniJIS−UCS2−HW−V
Vertical version of UniJIS−UCS2−HW−H
UniJIS−UTF16-H
Unicode (UTF-16BE) encoding for the Adobe-Japan1 character collection; contains
mappings for all characters in the JIS X 0213:1000 character set
UniJIS−UTF16-V
Vertical version of UniJIS−UTF16-H
445
SECTION 5.6
Composite Fonts
NAME
DESCRIPTION
Korean
KSC−EUC−H
KS X 1001:1992 character set, EUC-KR encoding
KSC−EUC−V
Vertical version of KSC−EUC−H
KSCms−UHC−H
Microsoft Code Page 949 (lfCharSet 0x81), KS X 1001:1992 character set plus 8822 addi-
tional hangul, Unified Hangul Code (UHC) encoding
KSCms−UHC−V
Vertical version of KSCms−UHC−H
KSCms−UHC−HW−H
Same as KSCms−UHC−H but replaces proportional Latin characters with half-width forms
KSCms−UHC−HW−V
Vertical version of KSCms−UHC−HW−H
KSCpc−EUC−H
Mac OS, KS X 1001:1992 character set with Mac OS KH extensions, Script Manager
Code 3
UniKS−UCS2−H
Unicode (UCS-2) encoding for the Adobe-Korea1 character collection
UniKS−UCS2−V
Vertical version of UniKS−UCS2−H
UniKS−UTF16−H
Unicode (UTF-16BE) encoding for the Adobe-Korea1 character collection
UniKS−UTF16−V
Vertical version of UniKS−UTF16−H
Generic
Identity−H
The horizontal identity mapping for 2-byte CIDs; may be used with CIDFonts using any
Registry, Ordering, and Supplement values. It maps 2-byte character codes ranging from
0 to 65,535 to the same 2-byte CID value, interpreted high-order byte first (see below).
Identity−V
Vertical version of Identity−H. The mapping is the same as for Identity−H.
The Identity−H and Identity−V CMaps can be used to refer to glyphs directly by
their CIDs when showing a text string. When the current font is a Type 0 font
whose Encoding entry is Identity−H or Identity−V, the string to be shown is inter-
preted as pairs of bytes representing CIDs, high-order byte first. This works with
any CIDFont, independently of its character collection. Additionally, when used
in conjunction with a Type 2 CIDFont whose CIDToGIDMap entry is Identity, the
2-byte CID values represent glyph indices for the glyph descriptions in the True-
Type font program. This works only if the TrueType font program is embedded in
the PDF file.
446
CHAPTER 5
Text
Table 5.16 lists the character collections referenced by the predefined CMaps for
the different versions of PDF. A dash (—) indicates that the CMap is not pre-
defined in that PDF version.
TABLE 5.16 Character collections for predefined CMaps, by PDF version
CMAP
PDF 1.2
PDF 1.3
PDF 1.4
PDF 1.5
Chinese (Simplified)
GB−EUC−H/V
Adobe-GB1-0
Adobe-GB1-0
Adobe-GB1-0
Adobe-GB1-0
GBpc−EUC−H
Adobe-GB1-0
Adobe-GB1-0
Adobe-GB1-0
Adobe-GB1-0
GBpc−EUC−V
—
Adobe-GB1-0
Adobe-GB1-0
Adobe-GB1-0
GBK−EUC−H/V
—
Adobe-GB1-2
Adobe-GB1-2
Adobe-GB1-2
GBKp−EUC−H/V
—
—
Adobe-GB1-2
Adobe-GB1-2
GBK2K−H/V
—
—
Adobe-GB1-4
Adobe-GB1-4
UniGB−UCS2−H/V
—
Adobe-GB1-2
Adobe-GB1-4
Adobe-GB1-4
UniGB−UTF16-H/V
—
—
—
Adobe-GB1-4
Chinese (Traditional)
B5pc−H/V
Adobe-CNS1-0
Adobe-CNS1-0
Adobe-CNS1-0
Adobe-CNS1-0
HKscs−B5−H/V
—
—
Adobe-CNS1-3
Adobe-CNS1-3
ETen−B5−H/V
Adobe-CNS1-0
Adobe-CNS1-0
Adobe-CNS1-0
Adobe-CNS1-0
ETenms−B5−H/V
—
Adobe-CNS1-0
Adobe-CNS1-0
Adobe-CNS1-0
CNS−EUC−H/V
Adobe-CNS1-0
Adobe-CNS1-0
Adobe-CNS1-0
Adobe-CNS1-0
UniCNS−UCS2−H/V
—
Adobe-CNS1-0
Adobe-CNS1-3
Adobe-CNS1-3
UniCNS−UTF16-H/V
—
—
—
Adobe-CNS1-4
Japanese
83pv−RKSJ−H
Adobe-Japan1-1
Adobe-Japan1-1
Adobe-Japan1-1
Adobe-Japan1-1
90ms−RKSJ−H/V
Adobe-Japan1-2
Adobe-Japan1-2
Adobe-Japan1-2
Adobe-Japan1-2
90msp−RKSJ−H/V
—
Adobe-Japan1-2
Adobe-Japan1-2
Adobe-Japan1-2
90pv−RKSJ−H
Adobe-Japan1-1
Adobe-Japan1-1
Adobe-Japan1-1
Adobe-Japan1-1
447
SECTION 5.6
Composite Fonts
CMAP
PDF 1.2
PDF 1.3
PDF 1.4
PDF 1.5
Add−RKSJ−H/V
Adobe-Japan1-1
Adobe-Japan1-1
Adobe-Japan1-1
Adobe-Japan1-1
EUC−H/V
—
Adobe-Japan1-1
Adobe-Japan1-1
Adobe-Japan1-1
Ext−RKSJ−H/V
Adobe-Japan1-2
Adobe-Japan1-2
Adobe-Japan1-2
Adobe-Japan1-2
H/V
Adobe-Japan1-1
Adobe-Japan1-1
Adobe-Japan1-1
Adobe-Japan1-1
UniJIS−UCS2−H/V
—
Adobe-Japan1-2
Adobe-Japan1-4
Adobe-Japan1-4
UniJIS−UCS2−HW−H/V
—
Adobe-Japan1-2
Adobe-Japan1-4
Adobe-Japan1-4
UniJIS−UTF16−H/V
—
—
—
Adobe-Japan1-5
Korean
KSC−EUC−H/V
Adobe-Korea1-0
Adobe-Korea1-0
Adobe-Korea1-0
Adobe-Korea1-0
KSCms−UHC−H/V
Adobe-Korea1-1
Adobe-Korea1-1
Adobe-Korea1-1
Adobe-Korea1-1
KSCms−UHC−HW−H/V
—
Adobe-Korea1-1
Adobe-Korea1-1
Adobe-Korea1-1
KSCpc−EUC−H
Adobe-Korea1-0
Adobe-Korea1-0
Adobe-Korea1-0
Adobe-Korea1-0
UniKS−UCS2−H/V
—
Adobe-Korea1-1
Adobe-Korea1-1
Adobe-Korea1-1
UniKS−UTF16−H/V
—
—
—
Adobe-Korea1-2
Generic
Identity−H/V
Adobe-Identity-0
Adobe-Identity-0
Adobe-Identity-0
Adobe-Identity-0
As noted in Section 5.6.2, “CIDSystemInfo Dictionaries,” a character collection is
identified by registry, ordering, and supplement number, and supplements are
cumulative; that is, a higher-numbered supplement includes the CIDs contained
in lower-numbered supplements, as well as some additional CIDs. Consequently,
text encoded according to the predefined CMaps for a given PDF version is valid
when interpreted by a consumer application supporting the same or a later PDF
version. When interpreted by an application supporting an earlier PDF version,
such text causes an error if a CMap is encountered that is not predefined for that
PDF version. If character codes are encountered that were added in a higher-
numbered supplement than the one corresponding to the supported PDF ver-
sion, no characters are displayed for those codes; see “Handling Undefined Char-
acters” on page 454. See also implementation note 67 in Appendix H.
448
CHAPTER 5
Text
Note: If an application producing a PDF file encounters text to be included that
uses CIDs from a higher-numbered supplement than the one corresponding to the
PDF version being generated, the application should embed the CMap for the
higher-numbered supplement rather than refer to the predefined CMap (see the
next section).
The CMap programs that define the predefined CMaps are available through the
ASN Web site and are also provided in conjunction with the book CJKV Informa-
tion Processing by Ken Lunde. Details on the character collections, including sam-
ple glyphs for all the CIDs, can be found in a number of Adobe Technical Notes.
For more information about these Notes and the aforementioned book, see the
Bibliography.
Embedded CMap Files
For character encodings that are not predefined, the PDF file must contain a
stream that defines the CMap. In addition to the standard entries for streams
(listed in Table 3.4 on page 62), the CMap stream dictionary contains the entries
listed in Table 5.17. The data in the stream defines the mapping from character
codes to a font number and a character selector. The data must follow the syntax
defined in Adobe Technical Note #5014, Adobe CMap and CIDFont Files Specifi-
cation.
TABLE 5.17 Additional entries in a CMap dictionary
KEY
TYPE
VALUE
Type
name
(Required) The type of PDF object that this dictionary describes; must be
CMap for a CMap dictionary. (Although this object is the value of an entry
named Encoding in a Type 0 font, its type is CMap.)
CMapName
name
(Required) The PostScript name of the CMap. It should be the same as the
value of CMapName in the CMap file.
CIDSystemInfo
dictionary
(Required) A dictionary (see Section 5.6.2, “CIDSystemInfo Dictionaries”)
containing entries that define the character collection for the CIDFont or
CIDFonts associated with the CMap.
The value of this entry should be the same as the value of CIDSystemInfo in
the CMap file.
(However, it does not need to match the values of
CIDSystemInfo for the Identity-H or Identity-V CMaps.)
449
SECTION 5.6
Composite Fonts
KEY
TYPE
VALUE
WMode
integer
(Optional) A code that determines the writing mode for any CIDFont with
which this CMap is combined. The possible values are 0 for horizontal and 1
for vertical. Default value: 0.
The value of this entry should be the same as the value of WMode in the
CMap file.
UseCMap
name or
(Optional) The name of a predefined CMap, or a stream containing a CMap,
stream
that is to be used as the base for this CMap. This base allows the CMap to be
defined differentially, specifying only the character mappings that differ from
the base CMap.
CMap Example and Operator Summary
CMap files are fully documented in Adobe Technical Note #5014, Adobe CMap
and CIDFont Files Specification. The following example of a CMap stream object
illustrates and partially explains the contents of a CMap file. There are several
reasons for including this material here:
• It documents some restrictions on the contents of a CMap file that can be
embedded in a PDF file.
• It provides background to aid in understanding subsequent material, particu-
larly “CMap Mapping” on page 453.
• It is the basis for a PDF feature, the ToUnicode CMap, which is a minor exten-
sion of the CMap file format. This extension is described in Section 5.9,
“Extraction of Text Content.”
Example 5.10 is a sample CMap for a Japanese Shift-JIS encoding. Character
codes in this encoding can be either 1 or 2 bytes in length. This CMap could be
used with a CIDFont that uses the same CID ordering as specified in the
CIDSystemInfo entry. Note that several of the entries in the stream dictionary are
also replicated in the stream data.
450
CHAPTER 5
Text
Example 5.10
22 0 obj
<< /Type /CMap
/CMapName /90ms−RKSJ−H
/CIDSystemInfo << /Registry ( Adobe )
/Ordering ( Japan1 )
/Supplement 2
>>
/WMode 0
/Length 23 0 R
>>
stream
%!PS−Adobe−3 . 0 Resource−CMap
%%DocumentNeededResources : ProcSet ( CIDInit )
%%IncludeResource : ProcSet ( CIDInit )
%%BeginResource : CMap ( 90ms−RKSJ−H )
%%Title : ( 90ms−RKSJ−H Adobe Japan1 2 )
%%Version : 10 . 001
%%Copyright : Copyright 1990−2001 Adobe Systems Inc .
%%Copyright : All Rights Reserved .
%%EndComments
/CIDInit
/ProcSet findresource begin
12 dict begin
begincmap
/CIDSystemInfo
3 dict dup begin
/Registry
( Adobe ) def
/Ordering ( Japan1 ) def
/Supplement 2 def
end def
/CMapName /90ms−RKSJ−H def
/CMapVersion 10 . 001 def
/CMapType 1 def
/UIDOffset 950 def
/XUID [ 1 10 25343 ] def
/WMode 0 def
4 begincodespacerange
< 00 >
< 80 >
< 8140 >
< 9FFC >
< A0 >
< DF >
< E040 >
< FCFC >
endcodespacerange
451
SECTION 5.6
Composite Fonts
1 beginnotdefrange
< 00 >
< 1F >
231
endnotdefrange
100 begincidrange
< 20 >
< 7D >
231
< 7E >
< 7E >
631
< 8140 >
< 817E >
633
< 8180 >
< 81AC > 696
< 81B8 > < 81BF >
741
< 81C8 > < 81CE > 749
… Additional ranges…
< FB40 >
< FB7E >
8518
< FB80 >
< FBFC > 8581
< FC40 > < FC4B > 8706
endcidrange
endcmap
CMapName currentdict /CMap defineresource pop
end
end
%%EndResource
%%EOF
endstream
endobj
As can be seen from this example, a CMap file conforms to PostScript language
syntax; however, a full PostScript interpreter is not needed to interpret it. Aside
from some required boilerplate, the CMap file consists of one or more occur-
rences of several special CMap construction operators, invoked in a specific
order. Following is a summary of these operators:
• begincmap and endcmap enclose the CMap definition.
• usecmap incorporates the code mappings from another CMap file. In PDF, the
other CMap must also be identified in the UseCMap entry in the CMap dictio-
nary (see Table 5.17 on page 448).
• begincodespacerange and endcodespacerange define codespace ranges—the
valid input character code ranges—by specifying a pair of codes of some partic-
ular length giving the lower and upper bounds of each range; see “CMap Map-
ping” on page 453.
452
CHAPTER 5
Text
• usefont specifies a font number that is an implicit operand of all the character
code mapping operations that follow. In PDF, the font number must be 0;
therefore, usefont typically does not actually appear.
• beginbfchar and endbfchar define mappings of individual input character
codes to character codes or character names in the associated font.
beginbfrange and endbfrange do the same for ranges of input codes. In PDF,
these operators may not appear in a CMap that is used as the Encoding entry of
a Type 0 font; however, they may appear in the definition of a ToUnicode CMap
(see Section 5.9, “Extraction of Text Content”).
• begincidchar and endcidchar define mappings of individual input character
codes to CIDs in the associated CIDFont. begincidrange and endcidrange do
the same, but for ranges of input codes.
• beginnotdefchar, endnotdefchar, beginnotdefrange, and endnotdefrange
define notdef mappings from character codes to CIDs. As described in the
section “Handling Undefined Characters” on page 454, a notdef mapping is
used if the normal mapping produces a CID for which no glyph is present in
the associated CIDFont.
The beginrearrangedfont, endrearrangedfont, beginusematrix, and
endusematrix operators, described in Adobe Technical Note #5014, Adobe CMap
and CIDFont Files Specification, cannot be used in CMap files embedded in a
PDF file.
5.6.5
Type 0 Font Dictionaries
A Type 0 font dictionary contains the entries listed in Table 5.18.
Example 5.11 shows a Type 0 font that refers to a single CIDFont. The CMap used
is one of the predefined CMaps listed in Table 5.15 on page 442 and is referenced
by name.
TABLE 5.18 Entries in a Type 0 font dictionary
KEY
TYPE
VALUE
Type
name
(Required) The type of PDF object that this dictionary describes; must be
Font for a font dictionary.
Subtype
name
(Required) The type of font; must be Type0 for a Type 0 font.
453
SECTION 5.6
Composite Fonts
KEY
TYPE
VALUE
BaseFont
name
(Required) The PostScript name of the font. In principle, this is an arbitrary
name, since there is no font program associated directly with a Type 0 font
dictionary. The conventions described here ensure maximum compatibility
with existing Acrobat products.
If the descendant is a Type 0 CIDFont, this name should be the concatenation
of the CIDFont’s BaseFont name, a hyphen, and the CMap name given in the
Encoding entry (or the CMapName entry in the CMap). If the descendant is a
Type 2 CIDFont, this name should be the same as the CIDFont’s BaseFont
name.
Encoding
name or
(Required) The name of a predefined CMap, or a stream containing a CMap
stream
that maps character codes to font numbers and CIDs. If the descendant is a
Type 2 CIDFont whose associated TrueType font program is not embedded
in the PDF file, the Encoding entry must be a predefined CMap name (see
“Glyph Selection in CIDFonts” on page 437).
DescendantFonts
array
(Required) A one-element array specifying the CIDFont dictionary that is the
descendant of this Type 0 font.
ToUnicode
stream
(Optional) A stream containing a CMap file that maps character codes to
Unicode values (see Section 5.9, “Extraction of Text Content”).
Example 5.11
14 0 obj
<< /Type /Font
/Subtype /Type0
/BaseFont /HeiseiMin−W5−90ms−RKSJ−H
/Encoding /90ms−RKSJ−H
/DescendantFonts [ 15 0 R ]
>>
endobj
CMap Mapping
The Encoding entry of a Type 0 font dictionary specifies a CMap that determines
how text-showing operators (such as Tj) interpret the bytes in the string to be
shown when the current font is the Type 0 font. The following paragraphs
describe how the characters in the string are decoded and mapped into character
selectors (which in PDF must always be CIDs).
Большое спасибо!
Ваше мнение очень важно для нас.
Нет комментариевНе стесняйтесь поделиться с нами вашим ценным мнением.
Текст