PDF Reference sixth edition, Adobe Portable Document Format Version 1.7 (book 1) — page 12
454
CHAPTER 5
Text
The codespace ranges in the CMap (delimited by begincodespacerange and
endcodespacerange) determine how many bytes are extracted from the string for
each successive character code. A codespace range is specified by a pair of codes
of some particular length giving the lower and upper bounds of that range. A
code is considered to match the range if it is the same length as the bounding
codes and the value of each of its bytes lies between the corresponding bytes of
the lower and upper bounds. The code length cannot exceed the number of bytes
representable in an integer (see Appendix C).
A sequence of one or more bytes is extracted from the string and matched against
the codespace ranges in the CMap. That is, the first byte is matched against 1-byte
codespace ranges; if no match is found, a second byte is extracted, and the 2-byte
code is matched against 2-byte codespace ranges. This process continues for suc-
cessively longer codes until a match is found or all codespace ranges have been
tested. There will be at most one match because codespace ranges do not overlap.
The code extracted from the string is looked up in the character code mappings
for codes of that length. (These are the mappings defined by beginbfchar,
endbfchar, begincidchar, endcidchar, and corresponding operators for ranges.)
Failing that, it is looked up in the notdef mappings, as described in the next
section.
The results of the CMap mapping algorithm are a font number and a character
selector. The font number is used as an index into the Type
0 font’s
DescendantFonts array to select a CIDFont. In PDF, the font number is always 0
and the character selector is always a CID; this is the only case described here.
The CID is then used to select a glyph in the CIDFont. If the CIDFont contains
no glyph for that CID, the notdef mappings are consulted, as described in the
next section.
Handling Undefined Characters
A CMap mapping operation can fail to select a glyph for a variety of reasons. This
section describes those reasons and what happens when they occur.
If a code maps to a CID for which no such glyph exists in the descendant
CIDFont, the notdef mappings in the CMap are consulted to obtain a substitute
character selector. These mappings (so called by analogy with the . notdef charac-
ter mechanism in simple fonts) are delimited by the operators beginnotdefchar,
endnotdefchar, beginnotdefrange, and endnotdefrange. They always map to a
455
SECTION 5.7
Font Descriptors
CID. If a matching notdef mapping is found, the CID selects a glyph in the associ-
ated descendant, which must be a CIDFont. If no glyph exists for that CID, the
glyph for CID 0 (which is required to be present) is substituted.
If the CMap does not contain either a character mapping or a notdef mapping for
the code, descendant 0 is selected and the glyph for CID 0 is substituted from the
associated CIDFont.
If the code is invalid—that is, the bytes extracted from the string to be shown do
not match any codespace range in the CMap—a substitute glyph is chosen as just
described. The character mapping algorithm is reset to its original position in the
string, and a modified mapping algorithm chooses the best partially matching
codespace range:
1. If the first byte extracted from the string to be shown does not match the first
byte of any codespace range, the range having the shortest codes is chosen.
2. Otherwise (that is, if there is a partial match), for each additional byte extract-
ed, the code accumulated so far is matched against the beginnings of all longer
codespace ranges until the longest such partial match has been found. If multi-
ple codespace ranges have partial matches of the same length, the one having
the shortest codes is chosen.
The length of the codes in the chosen codespace range determines the total num-
ber of bytes to consume from the string for the current mapping operation.
5.7
Font Descriptors
A font descriptor specifies metrics and other attributes of a simple font or a
CIDFont as a whole, as distinct from the metrics of individual glyphs. These font
metrics provide information that enables a consumer application to synthesize a
substitute font or select a similar font when the font program is unavailable. The
font descriptor may also be used to embed the font program in the PDF file.
Font descriptors are not used with Type 0 fonts. Beginning with PDF 1.5, font de-
scriptors may be used with Type 3 fonts in Tagged PDF documents (see Section
10.7, “Tagged PDF”).
A font descriptor is a dictionary whose entries specify various font attributes. The
entries common to all font descriptors—for both simple fonts and CIDFonts—are
456
CHAPTER 5
Text
listed in Table 5.19. Additional entries in the font descriptor for a CIDFont are de-
scribed in Section 5.7.2, “Font Descriptors for CIDFonts.” All integer values are
units in glyph space. The conversion from glyph space to text space is described
in Section 5.1.3, “Glyph Positioning and Metrics.”
TABLE 5.19 Entries common to all font descriptors
KEY
TYPE
VALUE
Type
name
(Required) The type of PDF object that this dictionary describes; must be
FontDescriptor for a font descriptor.
FontName
name
(Required) The PostScript name of the font. This name should be the same as
the value of BaseFont in the font or CIDFont dictionary that refers to this
font descriptor.
FontFamily
byte string
(Optional; PDF 1.5; strongly recommended for Type 3 fonts in Tagged PDF doc-
uments) A byte string specifying the preferred font family name. For example,
for the font Times Bold Italic, the FontFamily is Times.
FontStretch
name
(Optional; PDF 1.5; strongly recommended for Type 3 fonts in Tagged PDF doc-
uments) The font stretch value. It must be one of the following names (or-
dered from narrowest to widest): UltraCondensed, ExtraCondensed,
Condensed, SemiCondensed, Normal, SemiExpanded, Expanded, ExtraExpand-
ed or UltraExpanded.
Note: The specific interpretation of these values varies from font to font. For ex-
ample, Condensed in one font may appear most similar to Normal in another.
FontWeight
number
(Optional; PDF 1.5; strongly recommended for Type 3 fonts in Tagged PDF doc-
uments) The weight (thickness) component of the fully-qualified font name
or font specifier. The possible values are 100, 200, 300, 400, 500, 600, 700,
800, or 900, where each number indicates a weight that is at least as dark as its
predecessor. A value of 400 indicates a normal weight; 700 indicates bold.
Note: The specific interpretation of these values varies from font to font. For ex-
ample, 300 in one font may appear most similar to 500 in another.
Flags
integer
(Required) A collection of flags defining various characteristics of the font
(see Section 5.7.1, “Font Descriptor Flags”).
FontBBox
rectangle
(Required, except for Type 3 fonts) A rectangle (see Section 3.8.4, “Rectan-
gles”), expressed in the glyph coordinate system, specifying the font bounding
box. This is the smallest rectangle enclosing the shape that would result if all
of the glyphs of the font were placed with their origins coincident and then
filled.
457
SECTION 5.7
Font Descriptors
KEY
TYPE
VALUE
ItalicAngle
number
(Required) The angle, expressed in degrees counterclockwise from the verti-
cal, of the dominant vertical strokes of the font. (For example, the 9-o’clock
position is 90 degrees, and the 3-o’clock position is -90 degrees.) The value is
negative for fonts that slope to the right, as almost all italic fonts do.
Ascent
number
(Required, except for Type 3 fonts) The maximum height above the baseline
reached by glyphs in this font, excluding the height of glyphs for accented
characters.
Descent
number
(Required, except for Type 3 fonts) The maximum depth below the baseline
reached by glyphs in this font. The value is a negative number.
Leading
number
(Optional) The spacing between baselines of consecutive lines of text. Default
value: 0.
CapHeight
number
(Required for fonts that have Latin characters, except for Type 3 fonts) The ver-
tical coordinate of the top of flat capital letters, measured from the baseline.
XHeight
number
(Optional) The font’s x height: the vertical coordinate of the top of flat non-
ascending lowercase letters (like the letter x), measured from the baseline, in
fonts that have Latin characters. Default value: 0.
StemV
number
(Required, except for Type 3 fonts) The thickness, measured horizontally, of
the dominant vertical stems of glyphs in the font.
StemH
number
(Optional) The thickness, measured vertically, of the dominant horizontal
stems of glyphs in the font. Default value: 0.
AvgWidth
number
(Optional) The average width of glyphs in the font. Default value: 0.
MaxWidth
number
(Optional) The maximum width of glyphs in the font. Default value: 0.
MissingWidth
number
(Optional) The width to use for character codes whose widths are not speci-
fied in a font dictionary’s Widths array. This has a predictable effect only if all
such codes map to glyphs whose actual widths are the same as the value of
the MissingWidth entry. Default value: 0.
FontFile
stream
(Optional) A stream containing a Type 1 font program (see Section 5.8,
“Embedded Font Programs”).
FontFile2
stream
(Optional; PDF 1.1) A stream containing a TrueType font program (see Sec-
tion 5.8, “Embedded Font Programs”).
458
CHAPTER 5
Text
KEY
TYPE
VALUE
FontFile3
stream
(Optional; PDF 1.2) A stream containing a font program whose format is
specified by the Subtype entry in the stream dictionary (see Table 5.23 and
implementation note 68 in Appendix H).
At most, only one of the FontFile, FontFile2, and FontFile3 entries may be
present.
CharSet
ASCII string
(Optional; meaningful only in Type 1 fonts; PDF 1.1) A string listing the char-
or byte string acter names defined in a font subset. The names in this string must be in PDF
syntax—that is, each name preceded by a slash (/). The names can appear in
any order. The name . notdef should be omitted; it is assumed to exist in the
font subset. If this entry is absent, the only indication of a font subset is the
subset tag in the FontName entry (see Section 5.5.3, “Font Subsets”).
5.7.1
Font Descriptor Flags
The value of the Flags entry in a font descriptor is an unsigned 32-bit integer con-
taining flags specifying various characteristics of the font. Bit positions within the
flag word are numbered from 1 (low-order) to 32 (high-order). Table 5.20 shows
the meanings of the flags; all undefined flag bits are reserved and must be set to 0.
Figure 5.13 shows examples of fonts with these characteristics.
TABLE 5.20 Font flags
BIT POSITION
NAME
MEANING
1
FixedPitch
All glyphs have the same width (as opposed to proportional or variable-pitch
fonts, which have different widths).
2
Serif
Glyphs have serifs, which are short strokes drawn at an angle on the top and
bottom of glyph stems. (Sans serif fonts do not have serifs.)
3
Symbolic
Font contains glyphs outside the Adobe standard Latin character set. This
flag and the Nonsymbolic flag cannot both be set or both be clear (see be-
low).
4
Script
Glyphs resemble cursive handwriting.
6
Nonsymbolic Font uses the Adobe standard Latin character set or a subset of it (see below).
7
Italic
Glyphs have dominant vertical strokes that are slanted.
459
SECTION 5.7
Font Descriptors
BIT POSITION
NAME
MEANING
17
AllCap
Font contains no lowercase letters; typically used for display purposes, such
as for titles or headlines.
18
SmallCap
Font contains both uppercase and lowercase letters. The uppercase letters are
similar to those in the regular version of the same typeface family. The glyphs
for the lowercase letters have the same shapes as the corresponding uppercase
letters, but they are sized and their proportions adjusted so that they have the
same size and stroke weight as lowercase glyphs in the same typeface family.
19
ForceBold
See below.
The Nonsymbolic flag (bit 6 in the Flags entry) indicates that the font’s character
set is the Adobe standard Latin character set (or a subset of it) and that it uses the
standard names for those glyphs. This character set is shown in Section D.1, “Lat-
in Character Set and Encodings.” If the font contains any glyphs outside this set,
the Symbolic flag should be set and the Nonsymbolic flag clear. In other words,
any font whose character set is not a subset of the Adobe standard character set is
considered to be symbolic. This influences the font’s implicit base encoding and
may affect a consumer application’s font substitution strategies.
Fixed-pitch font
The quick brown fox jumped.
Serif font
The quick brown fox jumped.
Sans serif font
The quick brown fox jumped.
Symbolic font
✴❈❅ ❑◆❉❃❋ ❂❒❏◗■ ❆❏❘ ❊◆❍❐❅❄✎
Script font
The quick brown fox jumped.
Italic font
The quick brown fox jumped.
All-cap font
The quick brown fox jumped
Small-cap font
The quick brown fox jumped.
FIGURE 5.13 Characteristics represented in the Flags entry of a font descriptor
460
CHAPTER 5
Text
Note: This classification of nonsymbolic and symbolic fonts is peculiar to PDF. A
font may contain additional characters that are used in Latin writing systems but
are outside the Adobe standard Latin character set; PDF considers such a font to be
symbolic. The use of two flags to represent a single binary choice is a historical acci-
dent.
The ForceBold flag (bit 19) determines whether bold glyphs are painted with
extra pixels even at very small text sizes. Typically, when glyphs are painted at
small sizes on very low-resolution devices such as display screens, features of bold
glyphs may appear only 1 pixel wide. Because this is the minimum feature width
on a pixel-based device, ordinary (nonbold) glyphs also appear with 1-pixel-wide
features and therefore cannot be distinguished from bold glyphs. If the ForceBold
flag is set, features of bold glyphs may be thickened at small text sizes.
Example 5.12 illustrates a font descriptor whose Flags entry
has
the
Serif,
Nonsymbolic, and ForceBold flags (bits 2, 6, and 19) set.
Example 5.12
7 0 obj
<< /Type /FontDescriptor
/FontName /AGaramond−Semibold
/Flags 262178
% Bits 2, 6, and 19
/FontBBox [ −177 −269 1123 866 ]
/MissingWidth 255
/StemV 105
/StemH 45
/CapHeight 660
/XHeight 394
/Ascent 720
/Descent −270
/Leading 83
/MaxWidth 1212
/AvgWidth 478
/ItalicAngle
0
>>
endobj
5.7.2
Font Descriptors for CIDFonts
In addition to the entries in Table 5.19 on page 456, the FontDescriptor dictionar-
ies of CIDFonts may contain the entries listed in Table 5.21.
461
SECTION 5.7
Font Descriptors
TABLE 5.21 Additional font descriptor entries for CIDFonts
KEY
TYPE
VALUE
Style
dictionary
(Optional) A dictionary containing entries that describe the style of the glyphs in the
font (see “Style” on page 461).
Lang
name
(Optional) A name specifying the language of the font, used for encodings where the
language is not implied by the encoding itself. The possible values are the codes de-
fined by Internet RFC 3066, Tags for the Identification of Languages (see the Bibliogra-
phy). If this entry is absent, the language is considered to be unknown.
Note: This specification for the allowable language codes is introduced in PDF 1.5. Prior
versions supported a subset: the 2-character language codes defined by ISO 639 (see the
Bibliography).
FD
dictionary
(Optional) A dictionary whose keys identify a class of glyphs in a CIDFont. Each value
is a dictionary containing entries that override the corresponding values in the main
font descriptor dictionary for that class of glyphs (see “FD” on page 462).
CIDSet
stream
(Optional) A stream identifying which CIDs are present in the CIDFont file. If this en-
try is present, the CIDFont contains only a subset of the glyphs in the character collec-
tion defined by the CIDSystemInfo dictionary. If it is absent, the only indication of a
CIDFont subset is the subset tag in the FontName entry (see Section 5.5.3, “Font Sub-
sets”).
The stream’s data is organized as a table of bits indexed by CID. The bits should be
stored in bytes with the high-order bit first. Each bit corresponds to a CID. The most
significant bit of the first byte corresponds to CID 0, the next bit to CID 1, and so on.
Style
The Style dictionary contains entries that define style attributes and values for the
CIDFont. Currently, only the Panose entry is defined. The value of Panose is a
12-byte string consisting of the following elements:
• The font family class and subclass ID bytes, given in the sFamilyClass field of the
“OS/2” table in a TrueType font. This field is documented in Microsoft’s True-
Type 1.0 Font Files Technical Specification.
• Ten bytes for the PANOSE classification number for the font. The PANOSE
classification system is documented in Hewlett-Packard Company’s PANOSE
Classification Metrics Guide.
See the Bibliography for more information about these documents.
462
CHAPTER 5
Text
The following is an example of a Style entry in the font descriptor:
/Style
<< /Panose < 01 05 02 02 03 00 00 00 00 00 00 00 > >>
FD
A CIDFont may be made up of different classes of glyphs, each class requiring
different sets of the font-wide attributes that appear in font descriptors. Latin
glyphs, for example, may require different attributes than kanji glyphs. The font
descriptor defines a set of default attributes that apply to all glyphs in the
CIDFont. The FD entry in the font descriptor contains exceptions to these de-
faults.
The key for each entry in an FD dictionary is the name of a class of glyphs—that
is, a particular subset of the CIDFont’s character collection. The entry’s value is a
font descriptor whose contents are to override the font-wide attributes for that
class only. This font descriptor should contain entries for metric information
only; it should not include FontFile, FontFile2, FontFile3, or any of the entries list-
ed in Table 5.21.
It is strongly recommended that the FD dictionary contain at least the metrics for
the proportional Latin glyphs. With the information for these glyphs, a more ac-
curate substitution font can be created.
The names of the glyph classes depend on the character collection, as identified
by the Registry, Ordering, and Supplement entries in the CIDSystemInfo
dictionary. Table 5.22 lists the valid keys for the Adobe-GB1, Adobe-CNS1, Ado-
be-Japan1, Adobe-Japan2, and Adobe-Korea1 character collections.
463
SECTION 5.7
Font Descriptors
TABLE 5.22 Glyph classes in CJK fonts
CHARACTER COLLECTION
CLASS
GLYPHS IN CLASS
Adobe-GB1
Alphabetic
Full-width Latin, Greek, and Cyrillic glyphs
Dingbats
Special symbols
Generic
Typeface-independent glyphs, such as line-drawing
Hanzi
Full-width hanzi (Chinese) glyphs
HRoman
Half-width Latin glyphs
HRomanRot
Same as HRoman but rotated for use in vertical writing
Kana
Proportional
Japanese kana (katakana and hiragana) glyphs
ProportionalRot
Proportional Latin glyphs
Same as Proportional but rotated for use in vertical writing
Adobe-CNS1
Alphabetic
Full-width Latin, Greek, and Cyrillic glyphs
Dingbats
Special symbols
Generic
Typeface-independent glyphs, such as line-drawing
Hanzi
Full-width hanzi (Chinese) glyphs
HRoman
Half-width Latin glyphs
HRomanRot
Same as HRoman but rotated for use in vertical writing
Kana
Japanese kana (katakana and hiragana) glyphs
Proportional
ProportionalRot
Proportional Latin glyphs
Same as Proportional but rotated for use in vertical writing
Adobe-Japan1
Alphabetic
Full-width Latin, Greek, and Cyrillic glyphs
AlphaNum
Numeric glyphs
Dingbats
Special symbols
DingbatsRot
Same as Dingbats but rotated for use in vertical writing
Generic
Typeface-independent glyphs, such as line-drawing
GenericRot
Same as Generic but rotated for use in vertical writing
HKana
Half-width kana (katakana and hiragana) glyphs
HKanaRot
HRoman
Same as HKana but rotated for use in vertical writing
HRomanRot
Half-width Latin glyphs
Kana
Same as HRoman but rotated for use in vertical writing
Kanji
Full-width kana (katakana and hiragana) glyphs
Proportional
Full-width kanji (Chinese) glyphs
ProportionalRot
Proportional Latin glyphs
Ruby
Same as Proportional but rotated for use in vertical writing
Glyphs used for setting ruby (small glyphs that serve to annotate
other glyphs with meanings or readings)
Adobe-Japan2
Alphabetic
Full-width Latin, Greek, and Cyrillic glyphs
Dingbats
Special symbols
HojoKanji
Full-width kanji glyphs
464
CHAPTER 5
Text
CHARACTER COLLECTION
CLASS
GLYPHS IN CLASS
Adobe-Korea1
Alphabetic
Full-width Latin, Greek, and Cyrillic glyphs
Dingbats
Special symbols
Generic
Typeface-independent glyphs, such as line-drawing
Hangul
Hangul and jamo glyphs
Hanja
Full-width hanja (Chinese) glyphs
HRoman
Half-width Latin glyphs
HRomanRot
Same as HRoman but rotated for use in vertical writing
Kana
Japanese kana (katakana and hiragana) glyphs
Proportional
ProportionalRot Proportional Latin glyphs
Same as Proportional but rotated for use in vertical writing
Example 5.13 illustrates an FD dictionary containing two entries.
Example 5.13
/FD
<< /Proportional 25 0 R
/HKana 26 0 R
>>
25 0 obj
<< /Type /FontDescriptor
/FontName /HeiseiMin−W3−Proportional
/Flags 2
/AvgWidth 478
/MaxWidth 1212
/MissingWidth 250
/StemV 105
/StemH 45
/CapHeight 660
/XHeight 394
/Ascent 720
/Descent −270
/Leading 83
>>
endobj
26 0 obj
<< /Type /FontDescriptor
/FontName /HeiseiMin−W3−HKana
/Flags 3
/AvgWidth 500
/MaxWidth 500
/MissingWidth 500
465
SECTION 5.8
Embedded Font Programs
/StemV 50
/StemH 75
/Ascent 720
/Descent 0
/Leading 83
>>
endobj
5.8
Embedded Font Programs
A font program can be embedded in a PDF file as data contained in a PDF stream
object. Such a stream object is also called a font file by analogy with font programs
that are available from sources external to the consumer application. (See also
implementation note 69 in Appendix H.)
Font programs are subject to copyright, and the copyright owner may impose
conditions under which a font program can be used. These permissions are re-
corded either in the font program or as part of a separate license. One of the con-
ditions may be that the font program cannot be embedded, in which case it
should not be incorporated into a PDF file. A font program may allow embed-
ding for the sole purpose of viewing and printing the document but not for creat-
ing new or modified text that uses the font (in either the same document or other
documents). The latter operation would require the user performing the opera-
tion to have a licensed copy of the font program, not a copy extracted from the
PDF file. In the absence of explicit information to the contrary, a PDF consumer
should assume that any embedded font programs are to be used only to view and
print the document and not for any other purposes.
Table 5.23 summarizes the ways in which font programs are embedded in a PDF
file, depending on the representation of the font program. The key is the name
used in the font descriptor to refer to the font file stream; the subtype is the value
of the Subtype key, if present, in the font file stream dictionary. Further details of
specific font program representations are given below.
TABLE 5.23 Embedded font organization for various font types
KEY
SUBTYPE
DESCRIPTION
FontFile
—
Type 1 font program, in the original (noncompact) format described in
Adobe Type 1 Font Format. This entry can appear in the font descriptor for
a Type1 or MMType1 font dictionary.
466
CHAPTER 5
Text
KEY
SUBTYPE
DESCRIPTION
FontFile2
—
(PDF 1.1) TrueType font program, as described in the TrueType Reference
Manual. This entry can appear in the font descriptor for a TrueType font
dictionary or (in PDF 1.3) for a CIDFontType2 CIDFont dictionary.
FontFile3
Type1C
(PDF 1.2) Type 1-equivalent font program represented in the Compact
Font Format (CFF), as described in Adobe Technical Note #5176, The
Compact Font Format Specification. This entry can appear in the font de-
scriptor for a Type1 or MMType1 font dictionary.
CIDFontType0C
(PDF 1.3) Type 0 CIDFont program represented in the Compact Font For-
mat (CFF), as described in Adobe Technical Note #5176, The Compact
Font Format Specification. This entry can appear in the font descriptor for
a CIDFontType0 CIDFont dictionary.
OpenType
(PDF 1.6) OpenType font program, as described in the OpenType Font
Specification (see the Bibliography). OpenType is an extension of True-
Type that allows inclusion of font programs that use the Compact Font
Format (CFF).
This entry can appear in the font descriptor for the following types of font
dictionaries:
• A TrueType font dictionary or a CIDFontType2 CIDFont dictionary, if
the embedded font program contains a “glyf ” table.
• A CIDFontType0 CIDFont dictionary, if the embedded font program
contains a “CFF” table with a Top DICT that uses CIDFont operators
(this is equivalent to subtype CIDFontType0C above).
• A Type1 font dictionary or CIDFontType0 CIDFont dictionary, if the
embedded font program contains a “CFF” table without CIDFont oper-
ators.
The stream dictionary for a font file contains the normal entries for a stream,
such as Length and Filter (listed in Table 3.4 on page 62), plus the additional
entries listed in Table 5.24.
TABLE 5.24 Additional entries in an embedded font stream dictionary
KEY
TYPE
VALUE
Length1
integer
(Required for Type 1 and TrueType fonts) The length in bytes of the clear-text portion of the
Type 1 font program (see below), or the entire TrueType font program, after it has been de-
coded using the filters specified by the stream’s Filter entry, if any.
467
SECTION 5.8
Embedded Font Programs
KEY
TYPE
VALUE
Length2
integer
(Required for Type 1 fonts) The length in bytes of the encrypted portion of the Type 1 font
program (see below) after it has been decoded using the filters specified by the stream’s Fil-
ter entry.
Length3
integer
(Required for Type 1 fonts) The length in bytes of the fixed-content portion of the Type 1
font program (see below) after it has been decoded using the filters specified by the stream’s
Filter entry. If Length3 is 0, it indicates that the 512 zeros and cleartomark have not been in-
cluded in the FontFile font program and must be added.
Subtype
name
(Required if referenced from FontFile3; PDF 1.2) A name specifying the format of the embed-
ded font program. The name must be Type1C for Type 1 compact fonts, CIDFontType0C for
Type 0 compact CIDFonts, or OpenType for OpenType fonts. When additional font formats
are added to PDF, more values will be defined for Subtype.
Metadata
stream
(Optional; PDF 1.4) A metadata stream containing metadata for the embedded font pro-
gram (see Section 10.2.2, “Metadata Streams”).
A standard Type 1 font program, as described in the Adobe Type 1 Font Format
specification, consists of three parts: a clear-text portion (written using PostScript
syntax), an encrypted portion, and a fixed-content portion. The fixed-content
portion contains 512 ASCII zeros followed by a cleartomark operator, and per-
haps followed by additional data. Although the encrypted portion of a standard
Type 1 font may be in binary or ASCII hexadecimal format, PDF supports only the
binary format. However, the entire font program may be encoded using any filters.
Example 5.14 shows the structure of an embedded standard Type 1 font.
Example 5.14
12 0 obj
<< /Filter /ASCII85Decode
/Length 41116
/Length1 2526
/Length2 32393
/Length3 570
>>
stream
,p>`rDKJj'E+LaU0eP.@+AH9dBOu$hFD55nC
… Omitted data…
JJQ&Nt')<=^p&mGf(%:%h1%9c//K(/*o=.C>UXkbVGTrr~>
endstream
endobj
468
CHAPTER 5
Text
As noted in Table 5.23, a Type 1-equivalent font program or a Type 0 CIDFont
program can be represented in the Compact Font Format (CFF). The Length1,
Length2, and Length3 entries are not needed in that case. Although CFF enables
multiple font or CIDFont programs to be bundled together in a single file, an em-
bedded CFF font file in PDF must consist of exactly one font or CIDFont (as ap-
propriate for the associated font dictionary).
Note: According to the Adobe Type 1 Font Format specification, a Type 1 font pro-
gram may contain a PaintType entry specifying whether the glyphs’ outlines are to
be filled or stroked. For fonts embedded in a PDF file, this entry is ignored; the deci-
sion whether to fill or stroke glyph outlines is entirely determined by the PDF text
rendering mode parameter (see Section 5.2.5, “Text Rendering Mode”). This also
applies to Type 1 compact fonts and Type 0 compact CIDFonts.
A TrueType font program may be used as part of either a font or a CIDFont.
Although the basic font file format is the same in both cases, there are different
requirements for what information must be present in the font program. The fol-
lowing TrueType tables are always required: “head,” “hhea,” “loca,” “maxp,” “cvt ,”
“prep,” “glyf,” “hmtx,” and “fpgm.” If used with a simple font dictionary, the font
program must additionally contain a “cmap” table defining one or more encod-
ings, as discussed in “Encodings for TrueType Fonts” on page 429. If used with a
CIDFont dictionary, the “cmap” table is not needed, since the mapping from
character codes to glyph descriptions is provided separately.
Note: The “vhea” and “vmtx” tables that specify vertical metrics are never used by a
PDF consumer application. The only way to specify vertical metrics in PDF is by
means of the DW2 and W2 entries in a CIDFont dictionary.
Beginning with PDF 1.6, font programs may be embedded using the OpenType
format, which is an extension of the TrueType format that allows inclusion of font
programs using the Compact Font Format (CFF). It also allows inclusion of data
to describe glyph substitutions, kerning, and baseline adjustments. In addition to
rendering glyphs, applications can use the data in OpenType fonts to do advanced
line layout, automatically substitute ligatures, provide selections of alternate
glyphs to users, and handle complicated writing scripts.
Like TrueType, OpenType font programs contain a number of tables, as defined
in the OpenType Font Specification (see the Bibliography). For OpenType fonts
based on TrueType, the “glyf ” table contains the glyph descriptions. For Open-
Type fonts based on CFF, the “CFF” table is a complete font program containing
469
SECTION 5.9
Extraction of Text Content
the glyph descriptions. These tables, as well as the “cmap” table, are required to be
present when embedding fonts. In addition, for OpenType fonts based on True-
Type, the “head,” “hhea,” “loca,” “maxp,” “cvt ,” “prep,” “hmtx,” and “fpgm” tables
are required.
Note: Other tables, such as those used for advanced line layout, need not be present;
however, their absence may prevent editing of text containing the font.
The process of finding glyph descriptions in OpenType fonts is the following:
• For Type 1 fonts using “CFF” tables, the process is as described in “Encodings
for Type 1 Fonts” on page 428.
• For TrueType fonts using “glyf ” tables, the process is as described in “Encod-
ings for TrueType Fonts” on page 429. Since this process sometimes produces
ambiguous results, it is strongly recommended that PDF creators, instead of us-
ing a simple font, use a Type 0 font with an Identity-H encoding and use the
glyph indices as character codes, as described following Table 5.15 on page 442.
• For CIDFontType0 fonts using “CFF” tables, the process is as described in the
discussion of embedded Type 0 CIDFonts in “Glyph Selection in CIDFonts” on
page 437.
• For CIDFontType2 fonts using “glyf ” tables, the process is as described in the
discussion of embedded Type 2 CIDFonts in “Glyph Selection in CIDFonts” on
page 437.
As discussed in Section 5.5.3, “Font Subsets,” an embedded font program may
contain only the subset of glyphs that are used in the PDF document. This may be
indicated by the presence of a CharSet or CIDSet entry in the font descriptor that
refers to the font file, although subset fonts are not always so identified.
5.9
Extraction of Text Content
The preceding sections describe all the facilities for showing text and causing
glyphs to be painted on the page. In addition to displaying text, consumer appli-
cations sometimes need to determine the information content of text—that is, its
meaning according to some standard character identification as opposed to its
rendered appearance. This need arises during operations such as searching, in-
dexing, and exporting of text to other applications.
470
CHAPTER 5
Text
The Unicode standard defines a system for numbering all of the common charac-
ters used in a large number of languages. It is a suitable scheme for representing
the information content of text, but not its appearance, since Unicode values
identify characters, not glyphs. For information about Unicode, see the Unicode
Standard by the Unicode Consortium (see the Bibliography).
When extracting character content, a consumer application can easily convert
text to Unicode values if a font’s characters are identified according to a standard
character set that is known to the application. This character identification can
occur if either the font uses a standard named encoding or the characters in the
font are identified by standard character names or CIDs in a well-known collec-
tion. Section 5.9.1, “Mapping Character Codes to Unicode Values,” describes in
detail the overall algorithm for mapping character codes to Unicode values.
If a font is not defined in one of these ways, the glyphs can still be shown, but the
characters cannot be converted to Unicode values without additional informa-
tion:
• This information can be provided as an optional ToUnicode entry in the font
dictionary (PDF 1.2; see Section 5.9.2, “ToUnicode CMaps”), whose value is a
stream object containing a special kind of CMap file that maps character codes
to Unicode values.
• An ActualText entry for a structure element or marked-content sequence (see
Section 10.8.3, “Replacement Text”) can be used to specify the text content di-
rectly.
5.9.1
Mapping Character Codes to Unicode Values
A consumer application can use the following methods, in the priority given, to
map a character code to a Unicode value. Tagged PDF documents, in particular,
must provide at least one of these methods (see “Unicode Mapping in Tagged
PDF” on page 892):
• If the font dictionary contains a ToUnicode CMap
(see Section
5.9.2,
“ToUnicode CMaps”), use that CMap to convert the character code to Unicode.
• If the font is a simple font that uses one of the predefined encodings
MacRomanEncoding, MacExpertEncoding, or WinAnsiEncoding, or that has an
encoding whose Differences array includes only character names taken from
471
SECTION 5.9
Extraction of Text Content
the Adobe standard Latin character set and the set of named characters in the
Symbol font (see Appendix D):
1. Map the character code to a character name according to Table D.1 on
page 996 and the font’s Differences array.
2. Look up the character name in the Adobe Glyph List (see the Bibliography)
to obtain the corresponding Unicode value.
• If the font is a composite font that uses one of the predefined CMaps listed in
Table 5.15 on page 442 (except Identity-H and Identity-V) or whose descendant
CIDFont uses the Adobe-GB1, Adobe-CNS1, Adobe-Japan1, or Adobe-Korea1
character collection:
1. Map the character code to a character identifier (CID) according to the
font’s CMap.
2. Obtain the registry and ordering of the character collection used by the
font’s CMap (for example, Adobe and Japan1) from its CIDSystemInfo dic-
tionary.
3. Construct a second CMap name by concatenating the registry and order-
ing obtained in step 2 in the format registry-ordering-UCS2 (for example,
Adobe-Japan1-UCS2).
4. Obtain the CMap with the name constructed in step 3 (available from the
ASN Web site; see the Bibliography).
5. Map the CID obtained in step 1 according to the CMap obtained in step 4,
producing a Unicode value.
Note: Type 0 fonts whose descendant CIDFonts use the Adobe-GB1, Adobe-CNS1,
Adobe-Japan1, or Adobe-Korea1 character collection
(as specified in the
CIDSystemInfo dictionary) must have a supplement number corresponding to the
version of PDF supported by the application. See Table 5.16 on page 446 for a list of
the character collections corresponding to a given PDF version. (Other supplements
of these character collections can be used, but if the supplement is higher-numbered
than the one corresponding to the supported PDF version, only the CIDs in the latter
supplement are considered to be standard CIDs.)
If these methods fail to produce a Unicode value, there is no way to determine
what the character code represents.
472
CHAPTER 5
Text
5.9.2
ToUnicode CMaps
The CMap defined in the ToUnicode entry of the font dictionary must follow the
syntax for CMaps introduced in Section 5.6.4, “CMaps” and fully documented in
Adobe Technical Note #5014, Adobe CMap and CIDFont Files Specification. Addi-
tional guidance regarding the CMap defined in this entry is provided in Adobe
Technical Note #5411, ToUnicode Mapping File Tutorial. This CMap differs from
an ordinary one in the following ways:
• The only pertinent entry in the CMap stream dictionary (see Table 5.17 on
page 448) is UseCMap, which may be used if the CMap is based on another
ToUnicode CMap.
• The CMap file must contain begincodespacerange and endcodespacerange
operators that are consistent with the encoding that the font uses. In particular,
for a simple font, the codespace must be one byte long.
• It must use the beginbfchar, endbfchar, beginbfrange, and endbfrange opera-
tors to define the mapping from character codes to Unicode character sequenc-
es expressed in UTF-16BE encoding.
Example 5.15 illustrates a Type 0 font that uses the Identity−H CMap to map from
character codes to CIDs and whose descendant CIDFont uses the Identity map-
ping from CIDs to TrueType glyph indices. Text strings shown using this font
simply use a 2-byte glyph index for each glyph. In the absence of a ToUnicode en-
try, no information would be available about what the glyphs mean.
Example 5.15
14 0 obj
<< /Type /Font
/Subtype /Type0
/BaseFont /Ryumin−Light
/Encoding /Identity−H
/DescendantFonts [ 15 0 R ]
/ToUnicode 16 0 R
>>
endobj
15 0 obj
<< /Type /Font
/Subtype /CIDFontType2
/BaseFont /Ryumin−Light
473
SECTION 5.9
Extraction of Text Content
/CIDSystemInfo 17 0 R
/FontDescriptor 18 0 R
/CIDToGIDMap /Identity
>>
endobj
The value of the ToUnicode entry is a stream object that contains the definition of
the CMap, as shown in Example 5.16.
Example 5.16
16 0 obj
<< /Length 433 >>
stream
/CIDInit
/ProcSet findresource begin
12 dict begin
begincmap
/CIDSystemInfo
<< /Registry ( Adobe )
/Ordering ( UCS )
/Supplement 0
>> def
/CMapName /Adobe−Identity−UCS def
/CMapType 2 def
1 begincodespacerange
< 0000 >
< FFFF >
endcodespacerange
2 beginbfrange
< 0000 >
< 005E >
< 0020 >
< 005F >
< 0061 >
[ < 00660066 > < 00660069 > < 00660066006C > ]
endbfrange
1 beginbfchar
<3A51>
<D840DC3E>
endbfchar
endcmap
CMapName currentdict /CMap defineresource pop
end
end
endstream
endobj
474
CHAPTER 5
Text
The begincodespacerange and endcodespacerange operators in Example 5.16
define the source character code range to be the 2-byte character codes from
< 00 00 > to < FF FF >. The specific mappings for several of the character codes are
shown. For example, < 00 00 > to < 00 5E > are mapped to the Unicode values
U+0020 to U+007E (where Unicode values are conventionally written as U+ fol-
lowed by four to six hexadecimal digits). This is followed by the definition of a
mapping where each character code represents more than one Unicode value:
< 005F > < 0061 > [ < 00660066 > < 00660069 > < 00660066006C > ]
In this case, the original character codes are the glyph indices for the ligatures ff,
fi, and ffl. The entry defines the mapping from the character codes < 00 5F >,
< 00 60 >, and < 00 61 > to the strings of Unicode values with a Unicode scalar val-
ue for each character in the ligature: U+0066 U+0066 are the Unicode values for
the character sequence f f, U+0066 U+0069 for f i, and U+0066 U+0066 U+006c for
f f l.
Finally, the character code < 3A 51> is mapped to the Unicode value U+2003E,
which is expressed by the byte sequence <D840DC3E> in UTF-16BE encoding.
Example 5.16 illustrates several extensions to the way destination values can be
defined. To support mappings from a source code to a string of destination codes,
the following extension has been made to the ranges defined after a beginbfchar
operator:
n beginbfchar
srcCode dstString
endbfchar
where dstString can be a string of up to 512 bytes. Likewise, mappings after the
beginbfrange operator may be defined as
n beginbfrange
srcCode1 srcCode2 dstString
endbfrange
In this case, the last byte of the string is incremented for each consecutive code in
the source code range. When defining ranges of this type, care must be taken to
ensure that the value of the last byte in the string is less than or equal to 255 −
(srcCode2 − srcCode1). This ensures that the last byte of the string is not incre-
475
SECTION 5.9
Extraction of Text Content
mented past 255; otherwise, the result of mapping is undefined and an error oc-
curs.
To support more compact representations of mappings from a range of source
character codes to a discontiguous range of destination codes, the CMaps used
for the ToUnicode entry can use the following syntax for the mappings following
a beginbfrange definition:
n beginbfrange
srcCode1 srcCode2 [ dstString1 dstString2 … dstStringm ]
endbfrange
Consecutive codes starting with srcCode1 and ending with srcCode2 are mapped to
the destination strings in the array starting with dstString1 and ending with
dstStringm . The value of dstString can be a string of up to 512 bytes. The value of
m represents the number of continuous character codes in the source character
code range:
m = srcCode2 - srcCode1 + 1
476
CHAPTER 5
Text
CHAPTER 6
Rendering
6
The Adobe imaging model separates graphics (the specification of shapes and col-
ors) from rendering (controlling a raster output device). Figures 4.12 and 4.13 on
pages 238 and 239 illustrate this division. Chapter 4 describes the facilities for
specifying the appearance of pages in a device-independent way. This chapter de-
scribes the facilities for controlling how shapes and colors are rendered on the
raster output device. All of the facilities discussed here depend on the specific
characteristics of the output device. PDF documents that are intended to be de-
vice-independent should limit themselves to the general graphics facilities de-
scribed in Chapter 4.
Nearly all of the rendering facilities that are under the control of a PDF document
pertain to the reproduction of color. Colors are rendered by a multiple-step pro-
cess outlined below. (Depending on the current color space and on the character-
istics of the device, it is not always necessary to perform every step.)
1. If a color has been specified in a CIE-based color space (see Section 4.5.4,
“CIE-Based Color Spaces”), it must first be transformed to the native color
space of the raster output device (also called its process color model).
2. If a color has been specified in a device color space that is inappropriate for the
output device (for example, RGB color with a CMYK or grayscale device), a
color conversion function is invoked.
3. The device color values are now mapped through transfer functions, one for
each color component. The transfer functions compensate for peculiarities of
the output device, such as nonlinear gray-level response. This step is some-
times called gamma correction.
4. If the device cannot reproduce continuous tones, but only certain discrete
colors such as black and white pixels, a halftone function is invoked, which
approximates the desired colors by means of patterns of pixels.
477
478
CHAPTER 6
Rendering
5. Finally, scan conversion is performed to mark the appropriate pixels of the ras-
ter output device with the requested colors.
Once these operations have been performed for all graphics objects on the page,
the resulting raster data is used to mark the physical output medium, such as
pixels on a display or ink on a printed page. A PDF document specifies very little
about the properties of the physical medium on which the output will be pro-
duced; that information is obtained from the following sources:
• The media box and a few other entries in the page dictionary (see Section
10.10.1, “Page Boundaries”).
• An interactive dialog conducted when the user requests viewing or printing.
• A job ticket, either embedded in the PDF file or provided separately, specifying
detailed instructions for imposing PDF pages onto media and for controlling
special features of the output device. Various standards exist for the format of
job tickets. Two of them, JDF (Job Definition Format) and PJTF (Portable Job
Ticket Format), are described in the CIP4 document JDF Specification and in
Adobe Technical Note #5620, Portable Job Ticket Format (see the Bibliography).
Some of the rendering facilities described in this chapter are controlled by device-
dependent graphics state parameters, listed in Table 4.3 on page 212. These pa-
rameters can be changed by invoking the gs operator with a parameter dictionary
containing entries shown in Table 4.8 on page 220.
6.1
CIE-Based Color to Device Color
To render CIE-based colors on an output device, the consumer application must
convert from the specified CIE-based color space to the device’s native color
space (typically DeviceGray, DeviceRGB, or DeviceCMYK), taking into account the
known properties of the device. As discussed in Section 4.5.4, “CIE-Based Color
Spaces,” CIE-based color is based on a model of human color perception. The
goal of CIE-based color rendering is to produce output in the device’s native color
space that accurately reproduces the requested CIE-based color values as per-
ceived by a human observer. CIE-based color specification and rendering are a
feature of PDF 1.1 (CalGray, CalRGB, and Lab) and PDF 1.3 (ICCBased).
The conversion from CIE-based color to device color is complex, and the theory
on which it is based is beyond the scope of this book; see the Bibliography for
sources of further information. The algorithm has many parameters, including an
479
SECTION 6.1
CIE-Based Color to Device Color
optional, full three-dimensional color lookup table. The color fidelity of the out-
put depends on having these parameters properly set, usually by a method that
includes some form of calibration. The colors that a device can produce are char-
acterized by a device profile, which is usually specified by an ICC profile associat-
ed with the device (and entirely separate from the profile that is specified in an
ICCBased color space).
Note: PDF has no equivalent of the PostScript color rendering dictionary. The
means by which a device profile is associated with a consumer application’s output
device are implementation-dependent and cannot be specified in a PDF file. Typi-
cally, this is done through a color management system (CMS) that is provided by the
operating system. Beginning with PDF 1.4, a PDF document can also specify one or
more output intents providing possible profiles that might be used to process the
document (see Section 10.10.4, “Output Intents”).
Conversion from a CIE-based color value to a device color value requires two
main operations:
1. Adjust the CIE-based color value according to a CIE-based gamut mapping
function. A gamut is a subset of all possible colors in some color space. A page
description has a source gamut consisting of all the colors it uses. An output
device has a device gamut consisting of all the colors it can reproduce. This
step transforms colors from the source gamut to the device gamut in a way that
attempts to preserve color appearance, visual contrast, or some other explicitly
specified rendering intent (see “Rendering Intents” on page 260).
2. Generate a corresponding device color value according to a CIE-based color
mapping function. For a given CIE-based color value, this function computes a
color value in the device’s native color space.
The CIE-based gamut and color mapping functions are applied only to color
values presented in a CIE-based color space. By definition, color values in device
color spaces directly control the device color components (though this can be al-
tered by the DefaultGray, DefaultRGB, and DefaultCMYK color space resources;
see “Default Color Spaces” on page 257).
The source gamut is specified by a page description when it selects a CIE-based
color space. This specification is device-independent. The corresponding proper-
ties of the output device are given in the device profile associated with the device.
The gamut mapping and color mapping functions are part of the implementation
of the consumer application.
480
CHAPTER 6
Rendering
6.2
Conversions among Device Color Spaces
Each raster output device has a native color space, which typically is one of the
standard device color spaces (DeviceGray, DeviceRGB, or DeviceCMYK). In other
words, most devices support reproduction of colors according to a grayscale
(monochrome), RGB (red-green-blue), or CMYK (cyan-magenta-yellow-black)
model. If the device supports continuous-tone output, reproduction occurs di-
rectly. Otherwise, it is accomplished by means of halftoning.
A device’s native color space is also called its process color model. Process colors
are ones that are produced by combinations of one or more standard process
colorants. Colors specified in any device or CIE-based color space are rendered as
process colors. (A device can also support additional spot colorants, which can be
painted only by means of Separation or DeviceN color spaces. They are not in-
volved in the rendering of device or CIE-based color spaces, nor are they subject
to the conversions described below.)
Note: Some devices provide a native color space that is not one of the three named
above but consists of a different combination of colorants. In that case, conversion
from the standard device color spaces to the device’s native color space is performed
by device-dependent means.
Knowing the native color space and other output capabilities of the device, the
consumer application can automatically convert the color values specified in a
document to those appropriate for the device’s native color space. For example, if
a document specifies colors in the DeviceRGB color space but the device supports
grayscale (such as a monochrome display) or CMYK (such as a color printer), the
consumer application performs the necessary conversions. If the document spec-
ifies colors directly in the device’s native color space, no conversions are neces-
sary.
The algorithms used to convert among device color spaces are very simple. As
perceived by a human viewer, the conversions produce only crude approxima-
tions of the original colors. More sophisticated control over color conversion can
be achieved by means of CIE-based color specification and rendering. Addition-
ally, device color spaces can be remapped into CIE-based color spaces (see
“Default Color Spaces” on page 257).
481
SECTION 6.2
Conversions among Device Color Spaces
6.2.1
Conversion between DeviceGray and DeviceRGB
Black, white, and intermediate shades of gray can be considered special cases of
RGB color. A grayscale value is described by a single number: 0.0 corresponds to
black, 1.0 to white, and intermediate values to different gray levels.
A gray level is equivalent to an RGB value with all three components the same. In
other words, the RGB color value equivalent to a specific gray value is simply
red = gray
green = gray
blue = gray
The gray value for a given RGB value is computed according to the NTSC video
standard, which determines how a color television signal is rendered on a black-
and-white television set:
gray = 0.3 × red + 0.59 × green + 0.11 × blue
6.2.2
Conversion between DeviceGray and DeviceCMYK
Nominally, a gray level is the complement of the black component of CMYK.
Therefore, the CMYK color value equivalent to a specific gray level is simply
cyan = 0.0
magenta = 0.0
yellow = 0.0
black = 1.0 - gray
To obtain the equivalent gray level for a given CMYK value, the contributions of
all components must be taken into account:
·
gray
1.0
min(1.0
=
–
, 0.3 × cyan + 0.59 × magenta + 0.11 × yellow + black )
The interactions between the black component and the other three are elaborated
below.
6.2.3
Conversion from DeviceRGB to DeviceCMYK
Conversion of a color value from RGB to CMYK is a two-step process. The first
step is to convert the red-green-blue value to equivalent cyan, magenta, and yel-
482
CHAPTER 6
Rendering
low components. The second step is to generate a black component and alter the
other components to produce a better approximation of the original color.
The subtractive color primaries cyan, magenta, and yellow are the complements
of the additive primaries red, green, and blue. For example, a cyan ink subtracts
the red component of white light. In theory, the conversion is very simple:
cyan = 1.0 - red
magenta = 1.0 - green
yellow = 1.0 - blue
For example, a color that is 0.2 red, 0.7 green, and 0.4 blue can also be expressed
as 1.0 − 0.2 = 0.8 cyan, 1.0 − 0.7 = 0.3 magenta, and 1.0 − 0.4 = 0.6 yellow.
Logically, only cyan, magenta, and yellow are needed to generate a printing color.
An equal level of cyan, magenta, and yellow should create the equivalent level of
black. In practice, however, colored printing inks do not mix perfectly; such com-
binations often form dark brown shades instead of true black. To obtain a truer
color rendition on a printer, true black ink is often substituted for the mixed-
black portion of a color. Most color printers support a black component (the K
component of CMYK). Computing the quantity of this component requires some
additional steps:
1. Black generation calculates the amount of black to be used when trying to re-
produce a particular color.
2. Undercolor removal reduces the amounts of the cyan, magenta, and yellow
components to compensate for the amount of black that was added by black
generation.
The complete conversion from RGB to CMYK is as follows, where BG (k) and
UCR (k) are invocations of the black-generation and undercolor-removal func-
tions, respectively:
c
= 1.0 - red
m = 1.0 - green
y = 1.0 - blue
k = min(c, m, y)
cyan = min (1.0, max (0.0, c - UCR (k)))
magenta = min (1.0, max (0.0, m - UCR (k)))
yellow = min (1.0, max (0.0, y - UCR (k)))
black = min (1.0, max (0.0,BG(k)))
483
SECTION 6.2
Conversions among Device Color Spaces
In PDF 1.2, the black-generation and undercolor-removal functions are defined
as PDF function dictionaries (see Section 3.9, “Functions”) that are parameters in
the graphics state. They are specified as the values of the BG and UCR (or BG2 and
UCR2) entries in a graphics state parameter dictionary (see Table 4.8 on page
220). Each function is called with a single numeric operand and is expected to
return a single numeric result.
The input of both the black-generation and undercolor-removal functions is k,
the minimum of the intermediate c, m, and y values that have been computed by
subtracting the original red, green, and blue components from 1.0. Nominally, k is
the amount of black that can be removed from the cyan, magenta, and yellow
components and substituted as a separate black component.
The black-generation function computes the black component as a function of
the nominal k value. It can simply return its k operand unchanged, or it can re-
turn a larger value for extra black, a smaller value for less black, or 0.0 for no
black at all.
The undercolor-removal function computes the amount to subtract from each of
the intermediate c, m, and y values to produce the final cyan, magenta, and yellow
components. It can simply return its k operand unchanged, or it can return 0.0
(so that no color is removed), some fraction of the black amount, or even a nega-
tive amount, thereby adding to the total amount of colorant.
The final component values that result after applying black generation and un-
dercolor removal are expected to be in the range 0.0 to 1.0. If a value falls outside
this range, the nearest valid value is substituted automatically without error indi-
cation. This substitution is indicated explicitly by the min and max operations in
the formulas above.
The correct choice of black-generation and undercolor-removal functions de-
pends on the characteristics of the output device—for example, how inks mix.
Each device is configured with default values that are appropriate for that device.
See Section 7.6.4, “Rendering Parameters and Transparency,” and in particular,
“Rendering Intent and Color Conversions” on page 574, for further discussion of
the role of black-generation and undercolor-removal functions in the transparent
imaging model.
484
CHAPTER 6
Rendering
6.2.4
Conversion from DeviceCMYK to DeviceRGB
Conversion of a color value from CMYK to RGB is a simple operation that does
not involve black generation or undercolor removal:
red = 1.0 - min(1.0, cyan + black)
green = 1.0 - min(1.0, magenta + black)
blue = 1.0 - min(1.0, yellow + black)
In other words, the black component is simply added to each of the other compo-
nents, which are then converted to their complementary colors by subtracting
them each from 1.0.
6.3
Transfer Functions
In PDF 1.2, a transfer function adjusts the values of color components to compen-
sate for nonlinear response in an output device and in the human eye. Each com-
ponent of a device color space—for example, the red component of the
DeviceRGB space—is intended to represent the perceived lightness or intensity of
that color component in proportion to the component’s numeric value. Many de-
vices do not actually behave this way, however; the purpose of a transfer function
is to compensate for the device’s actual behavior. This operation is sometimes
called gamma correction (not to be confused with the CIE-based gamut mapping
function performed as part of CIE-based color rendering).
In the sequence of steps for processing colors, the consumer application applies
the transfer function after performing any needed conversions between color
spaces, but before applying a halftone function, if necessary. Each color compo-
nent has its own separate transfer function; there is no interaction between com-
ponents.
Transfer functions always operate in the native color space of the output device,
regardless of the color space in which colors were originally specified. (For exam-
ple, for a CMYK device, the transfer functions apply to the device’s cyan, magen-
ta, yellow, and black color components, even if the colors were originally
specified in, for example, a DeviceRGB or CalRGB color space.) The transfer func-
tion is called with a numeric operand in the range 0.0 to 1.0 and must return a
number in the same range. The input is the value of a color component in the de-
vice’s native color space, either specified directly or produced by conversion from
485
SECTION 6.3
Transfer Functions
some other color space. The output is the transformed component value to be
transmitted to the device (after halftoning, if necessary).
Both the input and the output of a transfer function are always interpreted as if
the corresponding color component were additive (red, green, blue, or gray): the
greater the numeric value, the lighter the color. If the component is subtractive
(cyan, magenta, yellow, black, or a spot color), it is converted to additive form by
subtracting it from 1.0 before it is passed to the transfer function. The output of
the function is always in additive form and is passed on to the halftone function
in that form.
In PDF 1.2, transfer functions are defined as PDF function objects (see Section
3.9, “Functions”). There are two ways to specify transfer functions:
• The current transfer function parameter in the graphics state consists of either a
single transfer function or an array of four separate transfer functions, one each
for red, green, blue, and gray or their complements cyan, magenta, yellow, and
black. (If only a single function is specified, it applies to all components.) An
RGB device uses the first three, a monochrome device uses the gray transfer
function only, and a CMYK device uses all four. The current transfer function
can be specified as the value of the TR or TR2 entry in a graphics state parameter
dictionary; see Table 4.8 on page 220.
• The current halftone parameter in the graphics state can specify transfer func-
tions as optional entries in halftone dictionaries (see Section 6.4.4, “Halftone
Dictionaries”). This is the only way to set transfer functions for nonprimary
color components or for any component in devices whose native color space
uses components other than the ones listed above. A transfer function specified
in a halftone dictionary overrides the corresponding one specified by the cur-
rent transfer function parameter in the graphics state.
In addition to their intended use for gamma correction, transfer functions can be
used to produce a variety of special, device-dependent effects. For example, on a
monochrome device, the PostScript calculator function
{ 1 exch sub }
inverts the output colors, producing a negative rendition of the page. In general,
this method does not work for color devices; inversion can be more complicated
than merely inverting each of the components. Because transfer functions pro-
486
CHAPTER 6
Rendering
duce device-dependent effects, a page description that is intended to be device-
independent should not alter them.
Note: When the current color space is DeviceGray and the output device’s native
color space is DeviceCMYK, the interpreter uses only the gray transfer function. The
normal conversion from DeviceGray to DeviceCMYK produces 0.0 for the cyan,
magenta, and yellow components. These components are not passed through their
respective transfer functions but are rendered directly, producing output containing
no colored inks. This special case exists for compatibility with existing applications
that use a transfer function to obtain special effects on monochrome devices, and
applies only to colors specified in the DeviceGray color space.
See Section 7.6.4, “Rendering Parameters and Transparency,” and in particular,
“Halftone and Transfer Function” on page 573, for further discussion of the role
of transfer functions in the transparent imaging model.
6.4
Halftones
Halftoning is a process by which continuous-tone colors are approximated on an
output device that can achieve only a limited number of discrete colors. Colors
that the device cannot produce directly are simulated by using patterns of pixels
in the colors available. Perhaps the most familiar example is the rendering of gray
tones with black and white pixels, as in a newspaper photograph.
Some output devices can reproduce continuous-tone colors directly. Halftoning is
not required for such devices; after gamma correction by the transfer functions,
the color components are transmitted directly to the device. On devices that do
require halftoning, it occurs after all color components have been transformed by
the applicable transfer functions. The input to the halftone function consists of
continuous-tone, gamma-corrected color components in the device’s native color
space. Its output consists of pixels in colors the device can reproduce.
PDF provides a high degree of control over details of the halftoning process. For
example, in color printing, independent halftone screens can be specified for each
of several colorants. When rendering on low-resolution displays, fine control
over halftone patterns is needed to achieve the best approximations of gray levels
or colors and to minimize visual artifacts.
Note: Remember that everything pertaining to halftones is, by definition, device-
dependent. In general, when a PDF document provides its own halftone specifica-
487
SECTION 6.4
Halftones
tions, it sacrifices portability. Associated with every output device is a default half-
tone definition that is appropriate for most purposes. Only relatively sophisticated
documents need to define their own halftones to achieve special effects.
All halftones are defined in device space, unaffected by the current transforma-
tion matrix. For correct results, a PDF document that defines a new halftone
must make assumptions about the resolution and orientation of device space. The
best choice of halftone parameters often depends on specific physical properties
of the output device, such as pixel shape, overlap between pixels, and the effects of
electronic or mechanical noise.
6.4.1
Halftone Screens
In general, halftoning methods are based on the notion of a halftone screen, which
divides the array of device pixels into cells that can be modified to produce the
desired halftone effects. A screen is defined by conceptually laying a uniform
rectangular grid over the device pixel array. Each pixel belongs to one cell of the
grid; a single cell typically contains many pixels. The screen grid is defined entire-
ly in device space and is unaffected by modifications to the current transforma-
tion matrix. This property is essential to ensure that adjacent areas colored by
halftones are properly stitched together without visible seams.
On a bilevel (black-and-white) device, each cell of a screen can be made to ap-
proximate a shade of gray by painting some of the cell’s pixels black and some
white. Numerically, the gray level produced within a cell is the ratio of white pix-
els to the total number of pixels in the cell. A cell containing n pixels can render
n + 1 different gray levels, ranging from all pixels black to all pixels white. A gray
value g in the range 0.0 to 1.0 is produced by making i pixels white, where
i = floor (g × n).
The foregoing description also applies to color output devices whose pixels con-
sist of primary colors that are either completely on or completely off. Most color
printers, but not color displays, work this way. Halftoning is applied to each color
component independently, producing shades of that color.
Color components are presented to the halftoning machinery in additive form,
regardless of whether they were originally specified additively (RGB or gray) or
subtractively (CMYK or tint). Larger values of a color component represent light-
er colors—greater intensity in an additive device such as a display or less ink in a
488
CHAPTER 6
Rendering
subtractive device such as a printer. Transfer functions produce color values in
additive form; see Section 6.3, “Transfer Functions.”
6.4.2
Spot Functions
A common way of defining a halftone screen is by specifying a frequency, angle,
and spot function. The frequency is the number of halftone cells per inch; the
angle indicates the orientation of the grid lines relative to the device coordinate
system. As a cell’s desired gray level varies from black to white, individual pixels
within the cell change from black to white in a well-defined sequence: if a partic-
ular gray level includes certain white pixels, lighter grays will include the same
white pixels along with some additional ones. The order in which pixels change
from black to white for increasing gray levels is determined by a spot function,
which specifies that order in an indirect way that minimizes interactions with the
screen frequency and angle.
Consider a halftone cell to have its own coordinate system: the center of the cell is
the origin and the corners are at coordinates ±1.0 horizontally and vertically.
Each pixel in the cell is centered at horizontal and vertical coordinates that both
lie in the range −1.0 to +1.0. For each pixel, the spot function is invoked with the
pixel’s coordinates as input and must return a single number in the range −1.0 to
+1.0, defining the pixel’s position in the whitening order.
The specific values the spot function returns are not significant; all that matters
are the relative values returned for different pixels. As a cell’s gray level varies
from black to white, the first pixel whitened is the one for which the spot function
returns the lowest value, the next pixel is the one with the next higher spot func-
tion value, and so on. If two pixels have the same spot function value, their rela-
tive order is chosen arbitrarily.
PDF provides built-in definitions for many of the most commonly used spot
functions. A halftone can simply specify any of these predefined spot functions
by name instead of giving an explicit function definition. For example, the name
SimpleDot designates a spot function whose value is inversely related to a pixel’s
distance from the center of the halftone cell. This produces a “dot screen” in
which the black pixels are clustered within a circle whose area is inversely pro-
portional to the gray level. The predefined function Line is a spot function whose
value is the distance from a given pixel to a line through the center of the cell,
producing a “line screen” in which the white pixels grow away from that line.
489
SECTION 6.4
Halftones
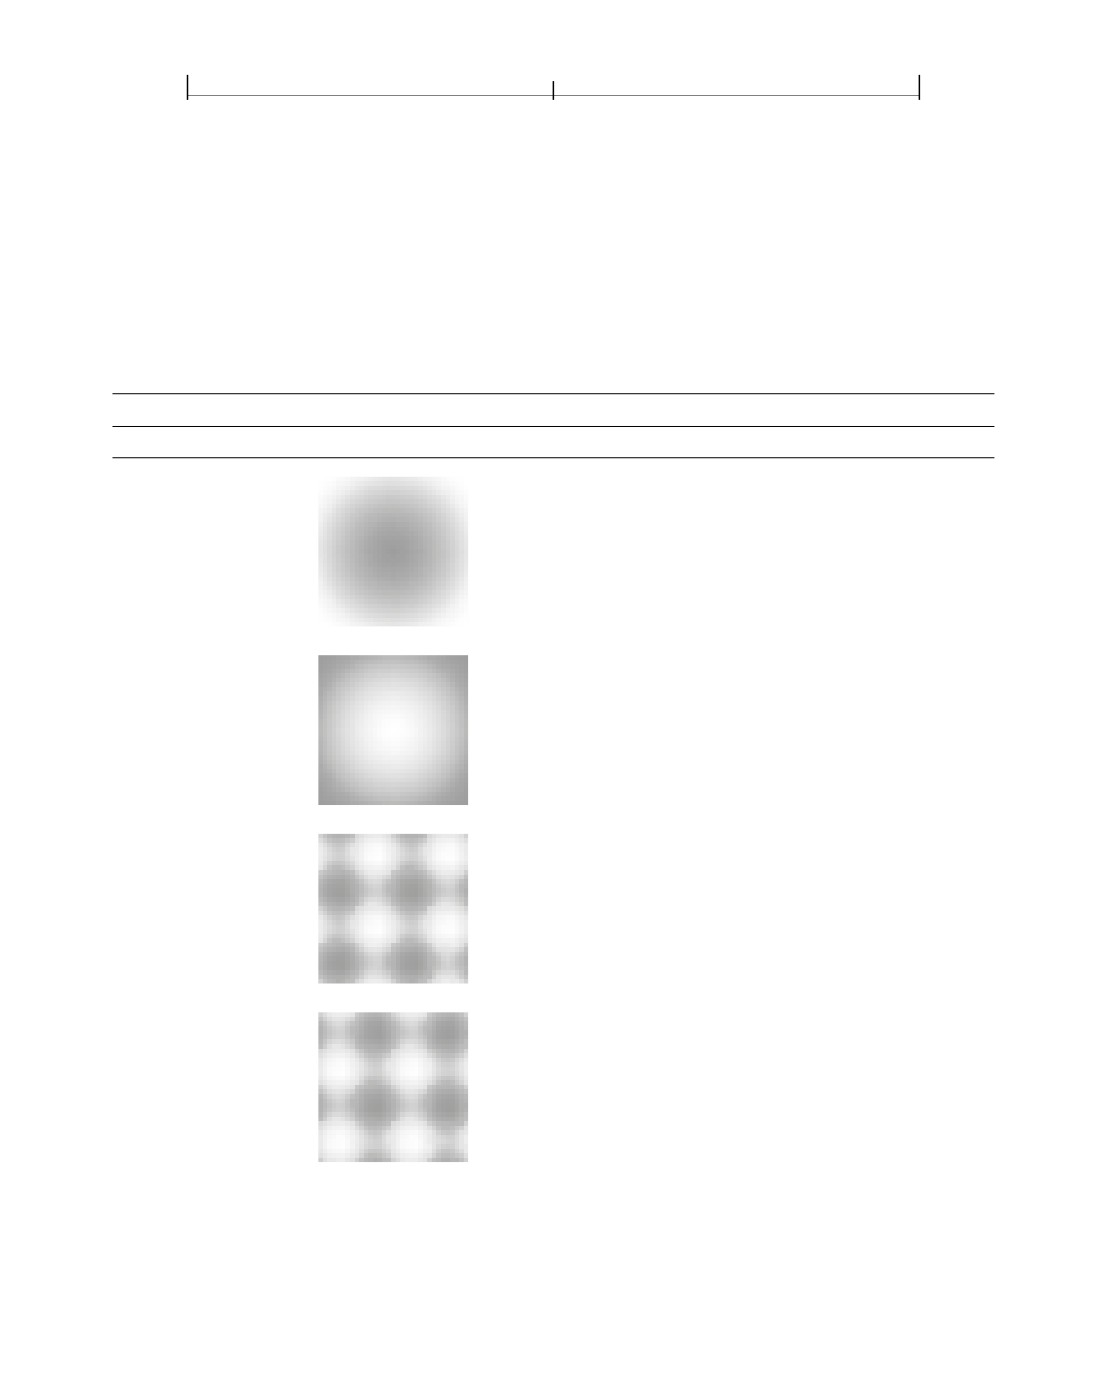
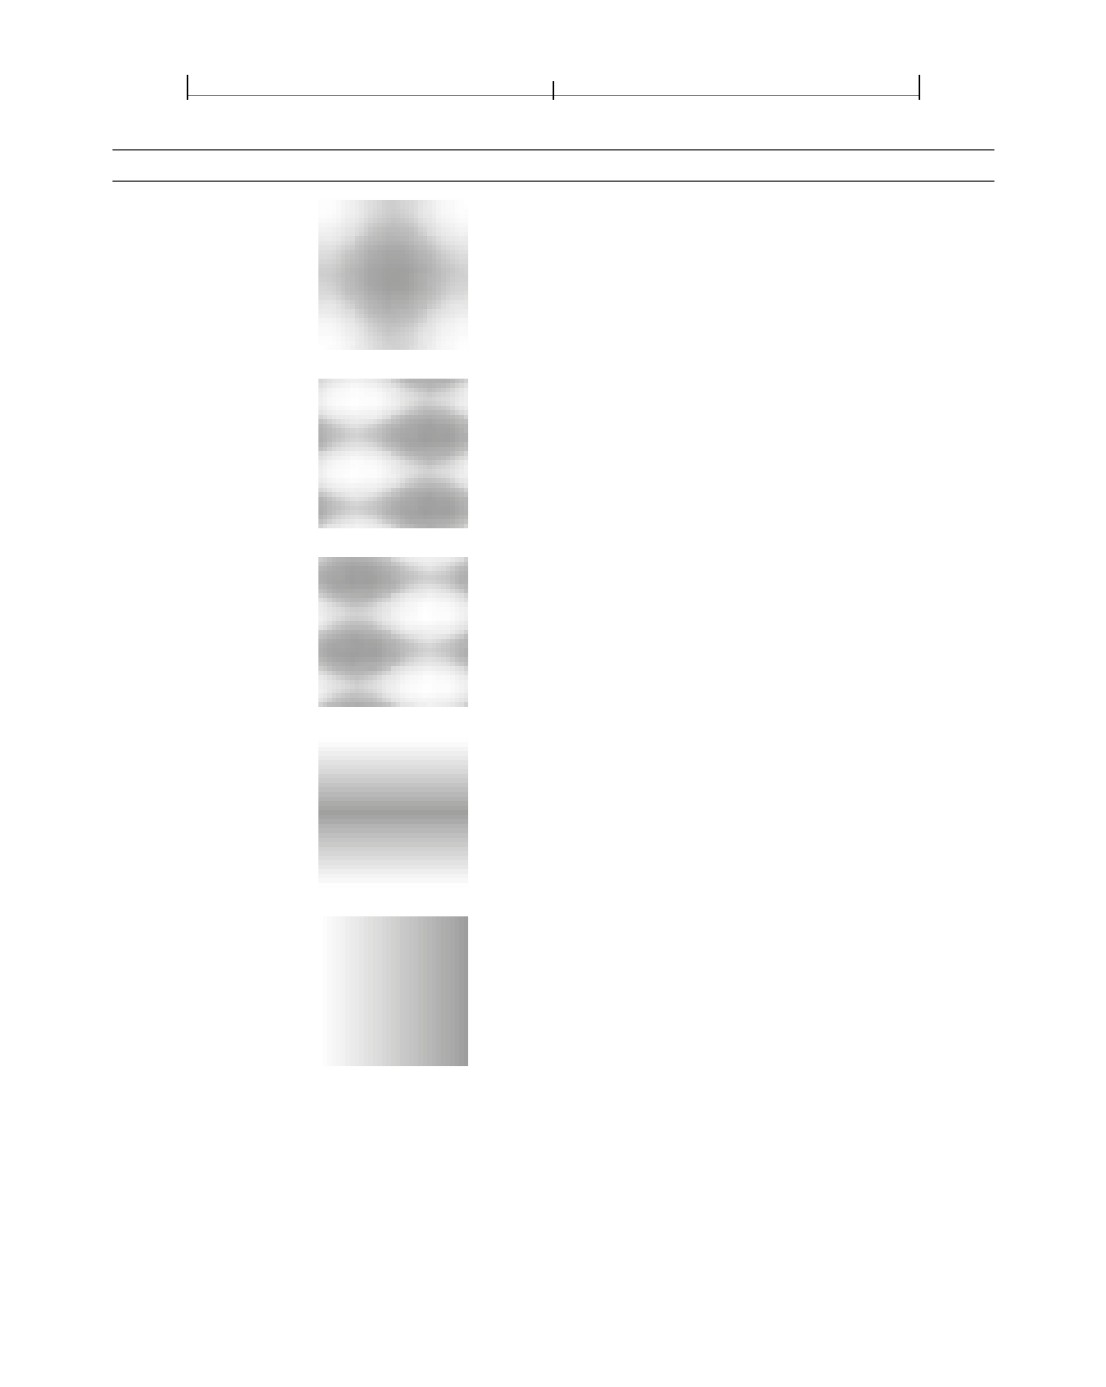
Table 6.1 shows the predefined spot functions. The table gives the mathematical
definition of each function along with the corresponding PostScript language
code as it would be defined in a PostScript calculator function (see Section 3.9.4,
“Type 4 (PostScript Calculator) Functions”). The image accompanying each
function shows how the relative values of the function are distributed over the
halftone cell, indicating the approximate order in which pixels are whitened. Pix-
els corresponding to darker points in the image are whitened later than those cor-
responding to lighter points. (See implementation note 70 in Appendix H.)
TABLE 6.1 Predefined spot functions
NAME
APPEARANCE
DEFINITION
SimpleDot
1 − (x 2 + y 2 )
{ dup mul exch dup mul add 1 exch sub }
InvertedSimpleDot
x 2 + y 2 − 1
{ dup mul exch dup mul add 1 sub }
DoubleDot
sin (360 × x)
sin(360 × y)
------------------------------
+ ------------------------------
2
2
{
360 mul sin 2 div exch 360 mul sin 2 div add }
InvertedDoubleDot
⎛sin(360 × x)
sin (360 × y)⎞
-
------------------------------
+ ------------------------------
⎝
2
2
⎠
{
360 mul sin 2 div exch 360 mul sin 2 div add neg }
490
CHAPTER 6
Rendering
NAME
APPEARANCE
DEFINITION
CosineDot
cos(180 × x)
cos (180 × y)
-------------------------------
+ ------------------------------
2
2
{
180 mul cos exch 180 mul cos add 2 div }
Double
⎛
x⎞
sin
360
× --
⎝
2⎠
sin (360 × y)
-------------------------------
+ ------------------------------
2
2
{
360 mul sin 2 div exch 2 div 360 mul sin 2 div add }
InvertedDouble
⎛
⎛
x⎞
⎞
sin
360
× --
⎜
⎝
2⎠
⎟
sin(360 × y)
-
⎜-------------------------------
+ ------------------------------⎟
⎜
2
2
⎟
⎝
⎠
{
360 mul sin 2 div exch 2 div 360 mul sin 2 div add neg }
Line
− | y |
{ exch pop abs neg }
LineX
x
{ pop }
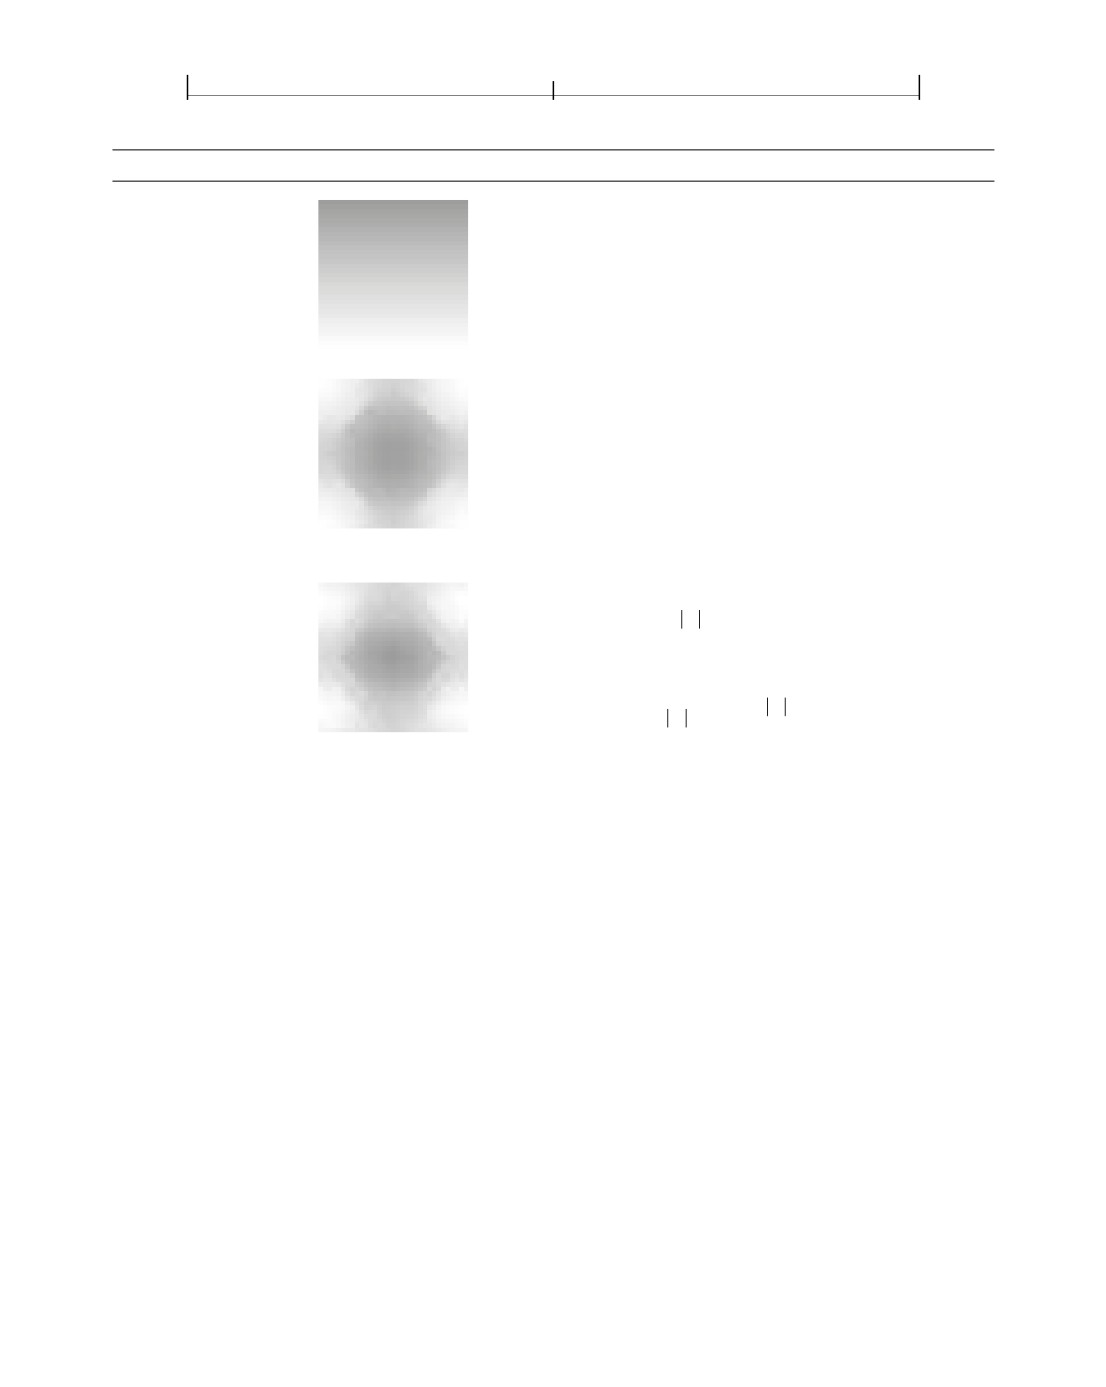
491
SECTION 6.4
Halftones
NAME
APPEARANCE
DEFINITION
LineY
y
{ exch pop }
Round
if | x | + | y | ≤ 1 then 1 − (x 2 + y 2)
else ( | x | − 1) 2 + ( | y | − 1) 2 − 1
{ abs exch abs
2 copy add 1 le
{ dup mul exch dup mul add 1 exch sub }
{
1 sub dup mul exch 1 sub dup mul add 1 sub }
ifelse
}
Ellipse
let w = (3 × | x | ) + (4 × | y | ) − 3
⎛
y
⎞2
x2
+
---------
⎝
0.75⎠
if w < 0 then
1
- -----------------------------
4
⎛1- y
⎞2
(1- x )2
+
---------------
⎝
0.75
⎠
else if w > 1 then
----------------------------------------------------- - 1
4
else 0.5 − w
{ abs exch abs 2 copy 3 mul exch 4 mul add 3 sub dup 0 lt
{ pop dup mul exch 0.75 div dup mul add
4 div 1 exch sub }
{ dup 1 gt
{ pop 1 exch sub dup mul
exch 1 exch sub 0.75 div dup mul add
4 div 1 sub }
{
0.5 exch sub exch pop exch pop }
ifelse
}
ifelse
}
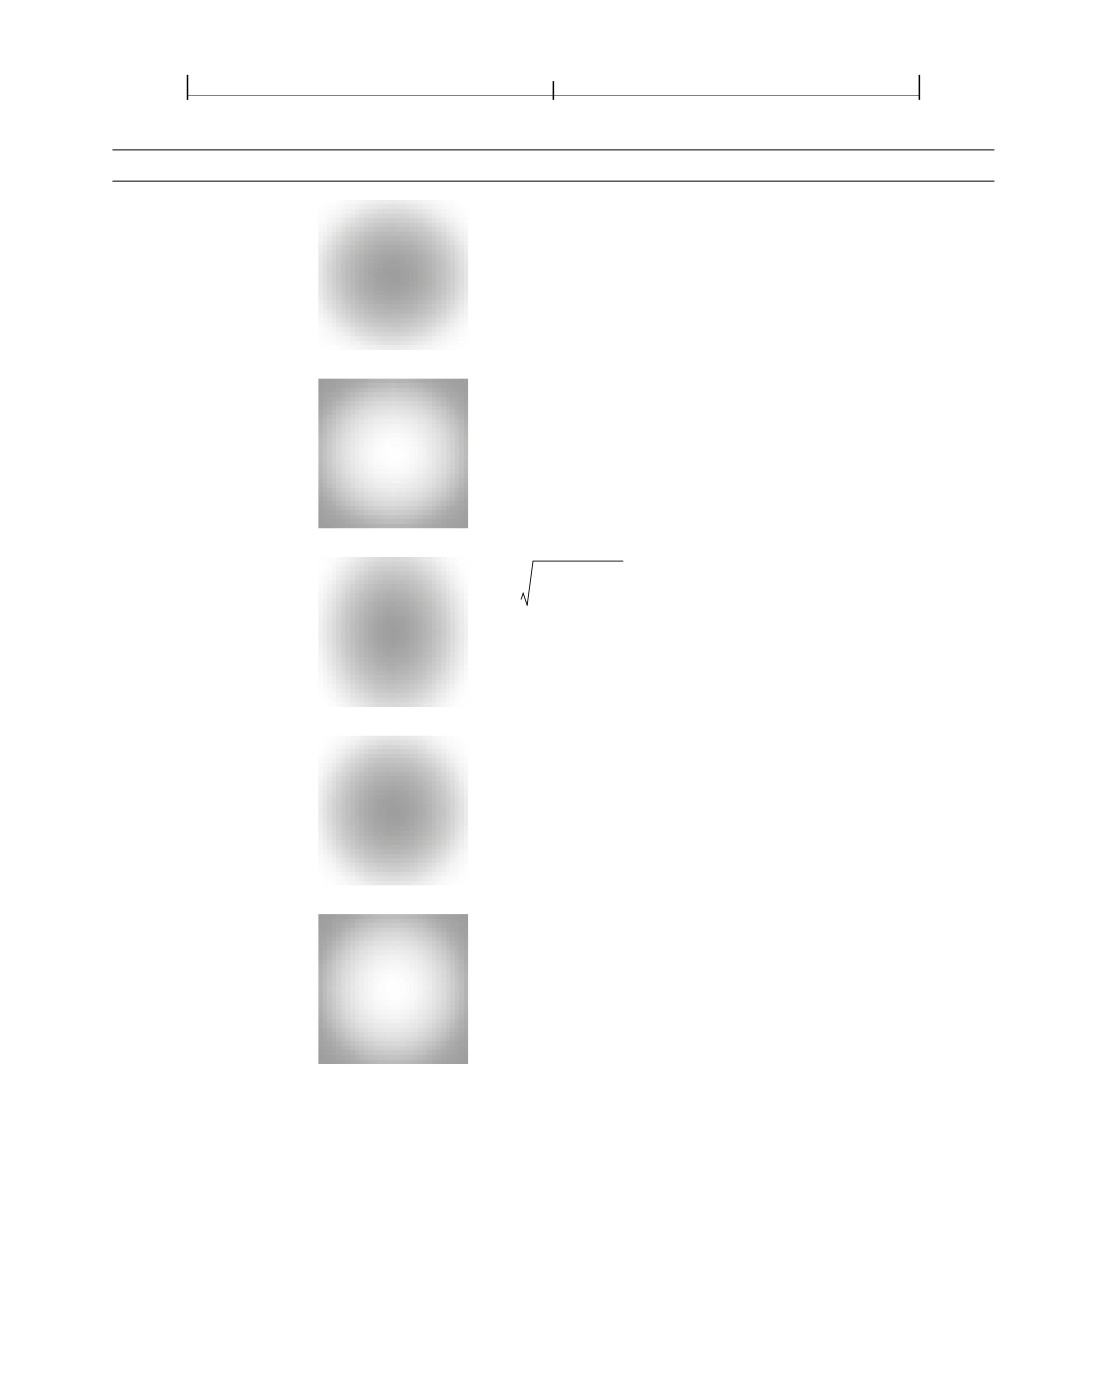
492
CHAPTER 6
Rendering
NAME
APPEARANCE
DEFINITION
EllipseA
1 − (x 2 + 0.9 × y 2 )
{ dup mul 0.9 mul exch dup mul add 1 exch sub }
InvertedEllipseA
x 2 + 0.9 × y 2 − 1
{ dup mul 0.9 mul exch dup mul add 1 sub }
EllipseB
5
1
-
x2
+
--
×
y2
8
{ dup 5 mul 8 div mul exch dup mul exch add sqrt
1 exch sub }
EllipseC
1 − (0.9 × x2 + y2 )
{ dup mul exch dup mul 0.9 mul add 1 exch sub }
InvertedEllipseC
0.9 × x 2 + y 2 − 1
{ dup mul exch dup mul 0.9 mul add 1 sub }
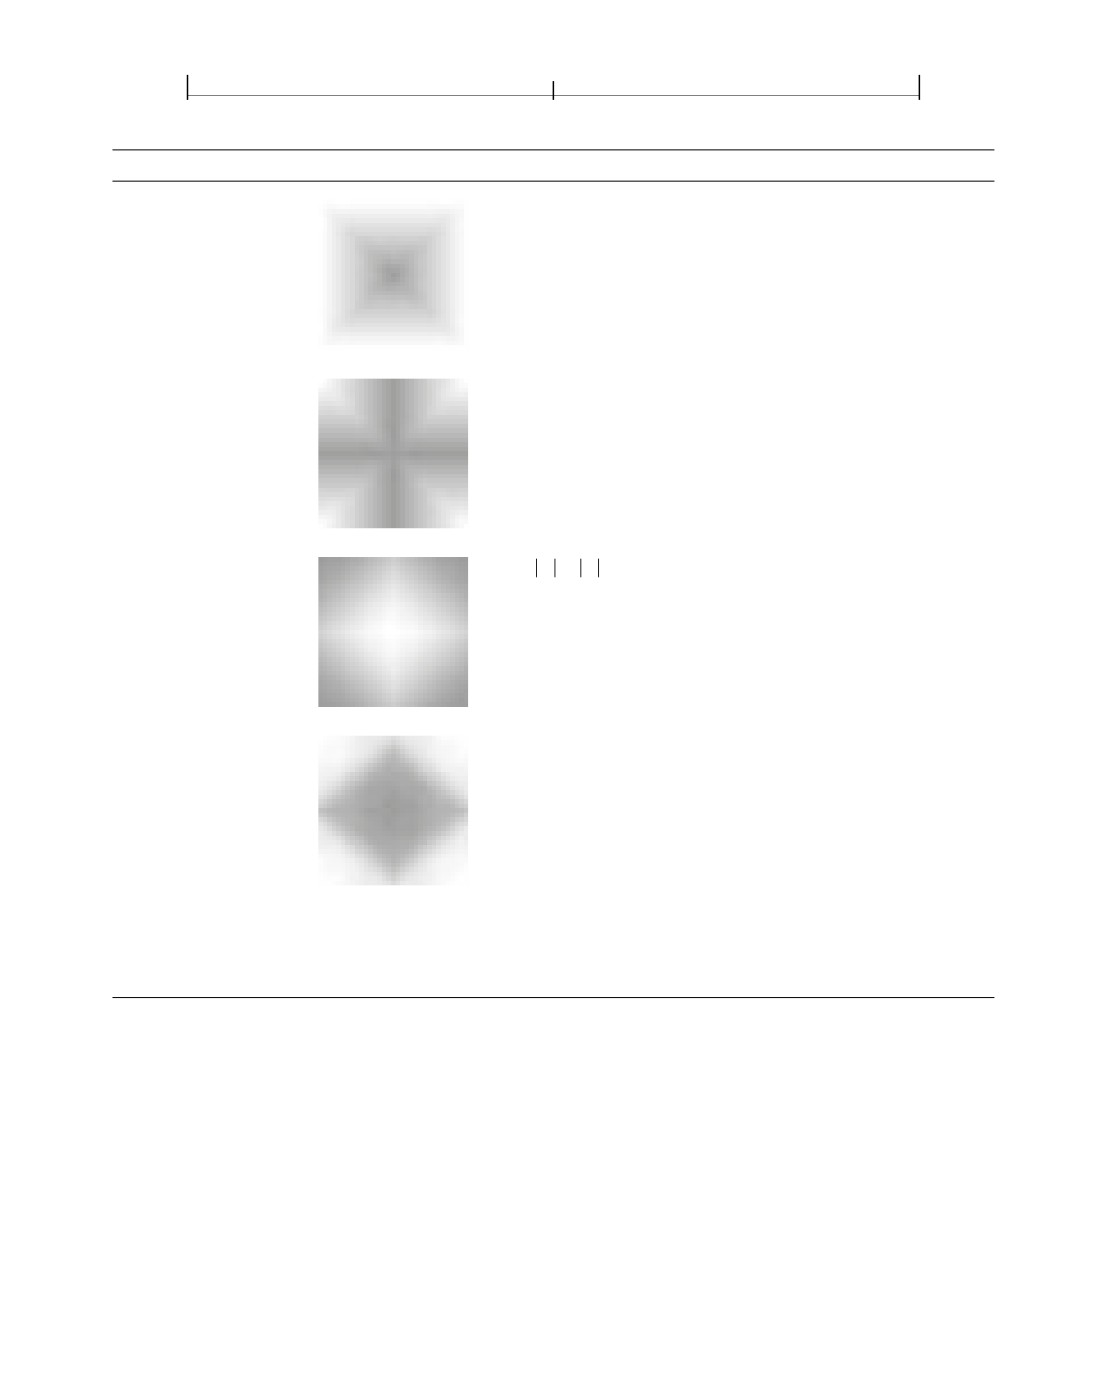
493
SECTION 6.4
Halftones
NAME
APPEARANCE
DEFINITION
Square
−max ( | x | , | y | )
{ abs exch abs 2 copy lt
{ exch }
if
pop neg }
Cross
−min ( | x | , | y | )
{ abs exch abs 2 copy gt
{ exch }
if
pop neg }
Rhomboid
x
+ y
2
{ abs exch abs 0.9 mul add 2 div }
Diamond
if | x | + | y | ≤ 0.75 then 1 − (x 2 + y 2)
else if | x | + | y | ≤ 1.23 then 1 − (0.85 × | x | + | y | )
else ( | x | - 1) 2 + ( | y | - 1) 2 - 1
{ abs exch abs 2 copy add 0.75 le
{ dup mul exch dup mul add 1 exch sub }
{
2 copy add 1.23 le
{
0.85 mul add 1 exch sub }
{
1 sub dup mul exch 1 sub dup mul add 1 sub }
ifelse
}
ifelse
}
Figure 6.1 illustrates the effects of some of the predefined spot functions.
494
CHAPTER 6
Rendering
150 per inch at 45
100 per inch at 45
50 per inch at 45
75 per inch at 45
Round dot screen Round dot screen Round dot screen
Line screen
FIGURE 6.1 Various halftoning effects
6.4.3
Threshold Arrays
Another way to define a halftone screen is with a threshold array that directly
controls individual device pixels in a halftone cell. This technique provides a high
degree of control over halftone rendering. It also permits halftone cells to be arbi-
trary rectangles, whereas those controlled by a spot function are always square.
A threshold array is much like a sampled image—a rectangular array of pixel
values—but is defined entirely in device space. Depending on the halftone type,
the threshold values occupy 8 or 16 bits each. Threshold values nominally repre-
sent gray levels in the usual way, from 0 for black up to the maximum (255 or
65,535) for white. The threshold array is replicated to tile the entire device space:
each pixel in device space is mapped to a particular sample in the threshold array.
On a bilevel device, where each pixel is either black or white, halftoning with a
threshold array proceeds as follows:
1. For each device pixel that is to be painted with some gray level, consult the
corresponding threshold value from the threshold array.
Большое спасибо!
Ваше мнение очень важно для нас.
Нет комментариевНе стесняйтесь поделиться с нами вашим ценным мнением.
Текст