PDF Reference sixth edition, Adobe Portable Document Format Version 1.7 (book 1) — page 5
167
SECTION 3.9
Functions
Functions in PDF represent static, self-contained numerical transformations. A
function to add two numbers has two input values and one output value:
f(x0
,
x1
)
=
x0
+
x1
Similarly, a function that computes the arithmetic and geometric mean of two
numbers could be viewed as a function of two input values and two output
values:
x0
+
x1
f(x0
,
x1
)
=
-----------------,
x0
×
x1
2
In general, a function can take any number (m) of input values and produce any
number (n) of output values:
f(x0
,
…,xm-1
)
=
y0
,
…,yn-1
In PDF functions, all the input values and all the output values are numbers, and
functions have no side effects.
Each function definition includes a domain, the set of legal values for the input.
Some types of functions also define a range, the set of legal values for the output.
Input values passed to the function are clipped to the domain, and output values
produced by the function are clipped to the range. For example, suppose the
function
f(x)
= x+2
is defined with a domain of [−1 1 ]. If the function is called with the input value 6,
that value is replaced with the nearest value in the defined domain, 1, before the
function is evaluated; the resulting output value is therefore 3. Similarly, if the
function
f(x0
,
x1
)
=
3
×
x0
+
x1
is defined with a range of [ 0 100 ], and if the input values −6 and 4 are passed to
the function (and are within its domain), then the output value produced by the
function, −14, is replaced with 0, the nearest value in the defined range.
A function object may be a dictionary or a stream, depending on the type of
function. The term function dictionary is used generically in this section to refer
to either a dictionary object or the dictionary portion of a stream object. A
168
CHAPTER 3
Syntax
function dictionary specifies the function’s representation, the set of attributes
that parameterize that representation, and the additional data needed by that
representation. Four types of functions are available, as indicated by the
dictionary’s FunctionType entry:
• (PDF 1.2) A sampled function (type 0) uses a table of sample values to define the
function. Various techniques are used to interpolate values between the sample
values (see Section 3.9.1, “Type 0 (Sampled) Functions”).
• (PDF 1.3) An exponential interpolation function (type 2) defines a set of coef-
ficients for an exponential function (see Section 3.9.2, “Type 2 (Exponential In-
terpolation) Functions”).
• (PDF 1.3) A stitching function (type 3) is a combination of other functions, par-
titioned across a domain (see Section 3.9.3, “Type 3 (Stitching) Functions”).
• (PDF 1.3) A PostScript calculator function (type 4) uses operators from the
PostScript language to describe an arithmetic expression (see Section 3.9.4,
“Type 4 (PostScript Calculator) Functions”).
All function dictionaries share the entries listed in Table 3.35.
TABLE 3.35 Entries common to all function dictionaries
KEY
TYPE
VALUE
FunctionType
integer
(Required) The function type:
0
Sampled function
2
Exponential interpolation function
3
Stitching function
4
PostScript calculator function
Domain
array
(Required) An array of 2 × m numbers, where m is the number of input val-
ues. For each i from 0 to m − 1, Domain2i must be less than or equal to
Domain2i+1 , and the ith input value, xi , must lie in the interval
Domain2i ≤ xi ≤ Domain2i+1 . Input values outside the declared domain are
clipped to the nearest boundary value.
Range
array
(Required for type 0 and type 4 functions, optional otherwise; see below) An
array of 2 × n numbers, where n is the number of output values. For each j
from 0 to n − 1, Range2j must be less than or equal to Range2j+1 , and the jth
output value, yj , must lie in the interval Range2j ≤ yj ≤ Range2j+1 . Output
values outside the declared range are clipped to the nearest boundary value. If
this entry is absent, no clipping is done.
169
SECTION 3.9
Functions
In addition, each type of function dictionary must include entries appropriate to
the particular function type. The number of output values can usually be inferred
from other attributes of the function; if not (as is always the case for type 0 and
type 4 functions), the Range entry is required. The dimensionality of the function
implied by the Domain and Range entries must be consistent with that implied by
other attributes of the function.
3.9.1
Type 0 (Sampled) Functions
Type 0 functions use a sequence of sample values (contained in a stream) to
provide an approximation for functions whose domains and ranges are bounded.
The samples are organized as an m-dimensional table in which each entry has n
components.
Sampled functions are highly general and offer reasonably accurate
representations of arbitrary analytic functions at low expense. For example, a
1-input sinusoidal function can be represented over the range [ 0 180 ] with an
average error of only 1 percent, using just ten samples and linear interpolation.
Two-input functions require significantly more samples but usually not a
prohibitive number if the function does not have high frequency variations.
The dimensionality of a sampled function is restricted only by implementation
limits. However, the number of samples required to represent functions with high
dimensionality multiplies rapidly unless the sampling resolution is very low. Also,
the process of multilinear interpolation becomes computationally intensive if the
number of inputs m is greater than 2. The multidimensional spline interpolation
is even more computationally intensive.
In addition to the entries in Table 3.35, a type 0 function dictionary includes
those shown in Table 3.36.
The Domain, Encode, and Size entries determine how the function’s input
variable values are mapped into the sample table. For example, if Size is [ 21 31 ],
the default Encode array is [ 0 20 0 30 ], which maps the entire domain into the
full set of sample table entries. Other values of Encode may be used.
170
CHAPTER 3
Syntax
To explain the relationship between Domain, Encode, Size, Decode, and Range,
we use the following notation:
y
=
Interpolate(x, xmin, xmax, ymin, ymax
)
⎛
ymax – ymin
⎞
=
ymin
+
⎜(
x xmin
)
× ----------------------------
⎟
x
⎝
max – xmin⎠
For a given value of x, Interpolate calculates the y value on the line defined by the
two points (xmin , ymin ) and (xmax , ymax ).
TABLE 3.36 Additional entries specific to a type 0 function dictionary
KEY
TYPE
VALUE
Size
array
(Required) An array of m positive integers specifying the number of samples
in each input dimension of the sample table.
BitsPerSample
integer
(Required) The number of bits used to represent each sample. (If the function
has multiple output values, each one occupies BitsPerSample bits.) Valid
values are 1, 2, 4, 8, 12, 16, 24, and 32.
Order
integer
(Optional) The order of interpolation between samples. Valid values are 1 and
3, specifying linear and cubic spline interpolation, respectively. (See imple-
mentation note 40 in Appendix H.) Default value: 1.
Encode
array
(Optional) An array of 2 × m numbers specifying the linear mapping of input
values into the domain of the function’s sample table. Default value:
[ 0
(Size0 − 1)
0 (Size1 − 1) … ].
Decode
array
(Optional) An array of 2 × n numbers specifying the linear mapping of sam-
ple values into the range appropriate for the function’s output values. Default
value: same as the value of Range.
other stream
(various)
(Optional) Other attributes of the stream that provides the sample values, as
attributes
appropriate (see Table 3.4 on page 62).
When a sampled function is called, each input value xi , for 0 ≤ i < m, is clipped to
the domain:
xi′
=
min(max(xi,Domain
), Domain
)
2i
2i + 1
171
SECTION 3.9
Functions
That value is encoded:
ei
=
Interpolate (xi′, Domain
,
Domain
,
Encode
,
Encode
)
2i
2i + 1
2i
2i + 1
That value is clipped to the size of the sample table in that dimension:
ei′
=
min(max(ei, 0), Sizei
-
1
)
The encoded input values are real numbers, not restricted to integers.
Interpolation is used to determine output values from the nearest surrounding
values in the sample table. Each output value rj , for 0 ≤ j < n, is then decoded:
rj′
=
Interpolate(rj
,
0, 2BitsPerSample
-
1
,
Decode2j, Decode2j+1
)
Finally, each decoded value is clipped to the range:
yj
=
min(max(rj′,Range2j ), Range2j+1
)
Sample data is represented as a stream of unsigned 8-bit bytes (integers in the
range 0 to 255). The bytes constitute a continuous bit stream, with the high-order
bit of each byte first. Each sample value is represented as a sequence of
BitsPerSample bits. Successive values are adjacent in the bit stream; there is no
padding at byte boundaries.
For a function with multidimensional input (more than one input variable), the
sample values in the first dimension vary fastest, and the values in the last
dimension vary slowest. For example, for a function f (a, b, c), where a, b, and c
vary from 0 to 9 in steps of 1, the sample values would appear in this order:
f (0, 0, 0), f (1, 0, 0),
… , f (9, 0, 0), f (0, 1, 0), f (1, 1, 0),
… , f (9, 1, 0), f (0, 2, 0),
f (1, 2, 0), … , f (9, 9, 0), f (0, 0, 1), f (1, 0, 1), and so on.
For a function with multidimensional output (more than one output value), the
values are stored in the same order as Range.
The stream data must be long enough to contain the entire sample array, as
indicated by Size, Range, and BitsPerSample; see “Stream Extent” on page 61.
Example 3.19 illustrates a sampled function with 4-bit samples in an array
containing 21 columns and 31 rows (651 values). The function takes two
arguments, x and y, in the domain [−1.0 1.0 ], and returns one value, z, in that
same range. The x argument is linearly transformed by the encoding to the
172
CHAPTER 3
Syntax
domain [ 0 20 ] and the y argument to the domain [ 0 30 ]. Using bilinear
interpolation between sample points, the function computes a value for z, which
(because BitsPerSample is 4) will be in the range [ 0 15 ], and the decoding
transforms z to a number in the range [ −1.0 1.0 ] for the result. The sample array
is stored in a string of 326 bytes, calculated as follows (rounded up):
326 bytes = 31 rows × 21 samples / row × 4 bits / sample ÷ 8 bits / byte
The first byte contains the sample for the point (−1.0, −1.0) in the high-order 4
bits and the sample for the point (−0.9, −1.0) in the low-order 4 bits.
Example 3.19
14 0 obj
<< /FunctionType 0
/Domain [−1.0 1.0
−1.0 1.0 ]
/Size
[ 21
31 ]
/Encode [ 0 20
0 30 ]
/BitsPerSample 4
/Range [ −1.0 1.0 ]
/Decode [ −1.0 1.0 ]
/Length …
/Filter
…
>>
stream
… 651 sample values…
endstream
endobj
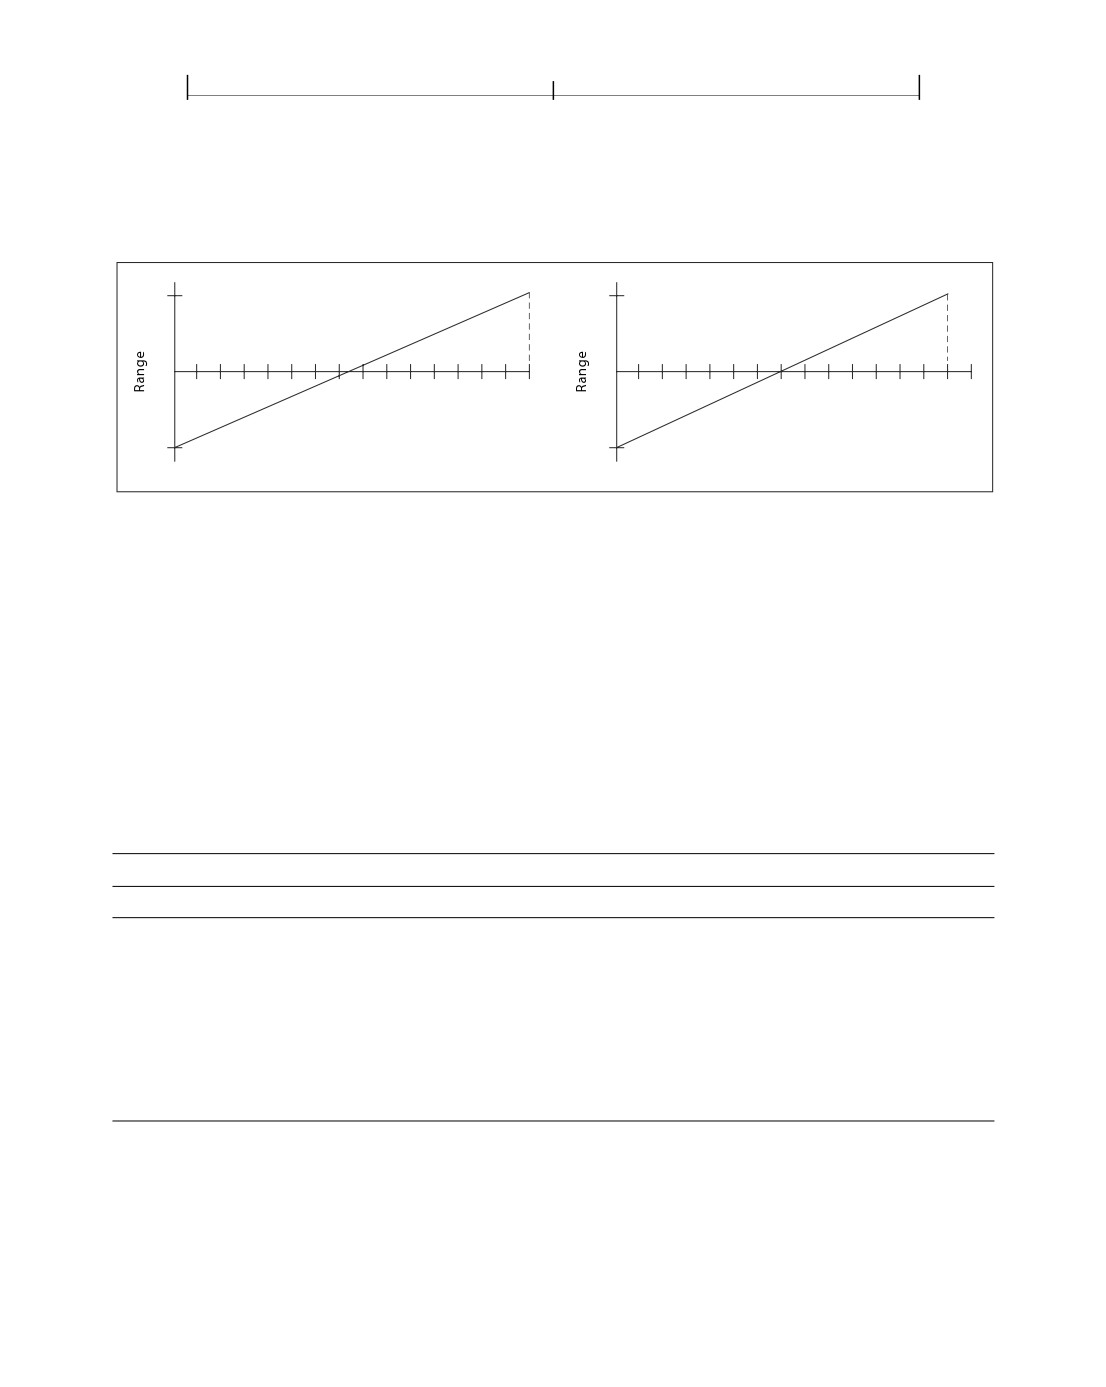
The Decode entry can be used creatively to increase the accuracy of encoded
samples corresponding to certain values in the range. For example, if the range of
the function is [ −1.0 1.0 ] and BitsPerSample is 4, the usual value of Decode
would be [ −1.0 1.0 ] and the sample values would be integers in the interval
[ 0
15 ] (as shown in Figure 3.8). But if these values are used, the midpoint of the
range, 0.0, is not represented exactly by any sample value, since it falls halfway
between 7 and 8. However, if the Decode array is [ −1.0 +1.1429 ] (1.1429 being
approximately equal to 16 ÷ 14) and the sample values supplied are in the interval
[ 0
14 ], the effective range of [ −1.0 1.0 ] is achieved, and the range value 0.0 is
represented by the sample value 7.
173
SECTION 3.9
Functions
The Size value for an input dimension can be 1, in which case all input values in
that dimension will be mapped to the single allowed value. If Size is less than 4,
cubic spline interpolation is not possible and Order 3 will be ignored if specified.
+1
+1
0
0
1
2
3
4
5
7
8
9
10 11 12 13 14 15
1
2
3
4
6
7
8
9
10 11 12 13 14 15
Samples
Samples
-1
-1
/Decode [-1 1]
/Decode [-1 1.1429]
FIGURE 3.8 Mapping with the Decode array
3.9.2
Type 2 (Exponential Interpolation) Functions
Type 2 functions (PDF 1.3) include a set of parameters that define an exponential
interpolation of one input value and n output values:
f(x)
=
y0
,
…,yn-1
In addition to the entries in Table 3.35 on page 168, a type 2 function dictionary
includes those listed in Table 3.37. (See implementation note 41 in Appendix H.)
TABLE 3.37 Additional entries specific to a type 2 function dictionary
KEY
TYPE
VALUE
C0
array
(Optional) An array of n numbers defining the function result when x = 0.0. Default value:
[ 0.0 ].
C1
array
(Optional) An array of n numbers defining the function result when x = 1.0. Default value:
[ 1.0 ].
N
number
(Required) The interpolation exponent. Each input value x will return n values, given by
yj = C0j + xN × (C1j − C0j ), for 0 ≤ j < n.
Values of Domain must constrain x in such a way that if N is not an integer, all
values of x must be non-negative, and if N is negative, no value of x may be zero.
Typically, Domain is declared as [ 0.0 1.0 ], and N is a positive number. The Range
174
CHAPTER 3
Syntax
attribute is optional and can be used to clip the output to a specified range. Note
that when N is 1, the function performs a linear interpolation between C0 and C1;
therefore, the function can also be expressed as a sampled function (type 0).
3.9.3
Type 3 (Stitching) Functions
Type 3 functions (PDF 1.3) define a stitching of the subdomains of several 1-input
functions to produce a single new 1-input function. Since the resulting stitching
function is a 1-input function, the domain is given by a two-element array,
[ Domain0 Domain1 ].
In addition to the entries in Table 3.35 on page 168, a type 3 function dictionary
includes those listed in Table 3.38. (See implementation note 42 in Appendix H.)
TABLE 3.38 Additional entries specific to a type 3 function dictionary
KEY
TYPE
VALUE
Functions
array
(Required) An array of k 1-input functions making up the stitching function. The out-
put dimensionality of all functions must be the same, and compatible with the value of
Range if Range is present.
Bounds
array
(Required) An array of k − 1 numbers that, in combination with Domain, define the
intervals to which each function from the Functions array applies. Bounds elements
must be in order of increasing value, and each value must be within the domain
defined by Domain.
Encode
array
(Required) An array of 2 × k numbers that, taken in pairs, map each subset of the do-
main defined by Domain and the Bounds array to the domain of the corresponding
function.
Domain must be of size 2 (that is, m = 1), and Domain0 must be strictly less than
Domain1 unless k = 1. The domain is partitioned into k subdomains, as indicated
by the dictionary’s Bounds entry, which is an array of k − 1 numbers that obey the
following relationships (with exceptions as noted below):
Domain0
<
Bounds0
<
Bounds1
<
…<Boundsk-2
<
Domain1
The Bounds array describes a series of half-open intervals, closed on the left and
open on the right (except the last, which is closed on the right as well). The value
of the Functions entry is an array of k functions. The first function applies to x
values in the first subdomain, Domain0 ≤ x < Bounds0 ; the second function
applies to x values in the second subdomain, Bounds0 ≤ x < Bounds1 ; and so on.
175
SECTION 3.9
Functions
The last function applies to x values in the last subdomain, which includes the
upper bound: Boundsk−2 ≤ x ≤ Domain1 . The value of k may be 1, in which case
the Bounds array is empty and the single item in the Functions array applies to all
x values, Domain0 ≤ x ≤ Domain1 .
The Encode array contains 2 × k numbers. A value x from the ith subdomain is
encoded as follows:
x′
=
Interpolate(x, Boundsi-1
,
Boundsi·, Encode2i, Encode2i+1
)
for 0 ≤ i < k. In this equation, Bounds−1 means Domain0 , and Boundsk−1 means
Domain1 . If the last bound, Boundsk−2 , is equal to Domain1 , then x ′ is defined to
be Encode2i .
The stitching function is designed to make it easy to combine several functions to
be used within one shading pattern over different parts of the shading’s domain.
(Shading patterns are discussed in Section 4.6.3, “Shading Patterns.”) The same
effect could be achieved by creating a separate shading dictionary for each of the
functions, with adjacent domains. However, since each shading would have
similar parameters, and because the overall effect is one shading, it is more con-
venient to have a single shading with multiple function definitions.
Also, type 3 functions provide a general mechanism for inverting the domains of
1-input functions. For example, consider a function f with a Domain of [ 0.0 1.0 ]
and a stitching function g with a Domain of
[ 0.0
1.0 ], a Functions array
containing f, and an Encode array of [ 1.0 0.0 ]. In effect, g (x) = f (1 − x).
3.9.4
Type 4 (PostScript Calculator) Functions
A type 4 function (PDF 1.3), also called a PostScript calculator function, is
represented as a stream containing code written in a small subset of the PostScript
language. Although any function can be sampled (in a type 0 PDF function) and
others can be described with exponential functions (type 2 in PDF), type 4
functions offer greater flexibility and potentially greater accuracy. For example, a
tint transformation function for a hexachrome (six-component) DeviceN color
space with an alternate color space of DeviceCMYK (see “DeviceN Color Spaces”
on page 268) requires a 6-in, 4-out function. If such a function were sampled with
m values for each input variable, the number of samples, 4 × m6, could be
prohibitively large. In practice, such functions are often written as short, simple
PostScript functions. (See implementation note 43 in Appendix H.)
176
CHAPTER 3
Syntax
Type 4 functions also make it possible to include a wide variety of halftone spot
functions without the loss of accuracy that comes from sampling, and without
adding to the list of predefined spot functions
(see Section
6.4.2,
“Spot
Functions”). All of the predefined spot functions can be written as type 4
functions.
The language that can be used in a type 4 function contains expressions involving
integers, real numbers, and boolean values only. There are no composite data
structures such as strings or arrays, no procedures, and no variables or names.
Table 3.39 lists the operators that can be used in this type of function. (For more
information on these operators, see Appendix B of the PostScript Language
Reference, Third Edition.) Although the semantics are those of the corresponding
PostScript operators, a PostScript interpreter is not required.
TABLE 3.39 Operators in type 4 functions
OPERATOR TYPE
OPERATORS
Arithmetic operators
abs
cvi
floor
mod
sin
add
cvr
idiv
mul
sqrt
atan
div
ln
neg
sub
ceiling
exp
log
round
truncate
cos
Relational, boolean,
and
false
le
not
true
and bitwise operators
bitshift
ge
lt
or
xor
eq
gt
ne
Conditional operators if
ifelse
Stack operators
copy
exch
pop
dup
index
roll
The operand syntax for type 4 functions follows PDF conventions rather than
PostScript conventions. The entire code stream defining the function is enclosed
in braces { }. Braces also delimit expressions that are executed conditionally by the
if and ifelse operators:
boolean { expression } if
boolean { expression1 } { expression2 } ifelse
This construct is purely syntactic; unlike in PostScript, no “procedure objects” are
involved.
177
SECTION 3.9
Functions
A type 4 function dictionary includes the entries in Table 3.35 on page 168, as
well as other appropriate stream attributes (see Table 3.4 on page 62). Example
3.20 shows a type
4 function equivalent to the predefined spot function
DoubleDot (see Section 6.4.2, “Spot Functions”).
Example 3.20
10 0 obj
<< /FunctionType 4
/Domain [ −1.0 1.0
−1.0 1.0 ]
/Range [ −1.0
1.0 ]
/Length 71
>>
stream
{
360 mul sin
2 div
exch 360 mul sin
2 div
add
}
endstream
endobj
The Domain and Range entries are both required. The input variables constitute
the initial operand stack; the items remaining on the operand stack after
execution of the function are the output variables. It is an error for the number of
remaining operands to differ from the number of output variables specified by
Range or for any of them to be objects other than numbers.
Implementations of type 4 functions must provide a stack with room for at least
100 entries. No implementation is required to provide a larger stack, and it is an
error to overflow the stack.
Although any integers or real numbers that may appear in the stream fall under
the same implementation limits (defined in Appendix C) as in other contexts, the
intermediate results in type 4 function computations do not. An implementation
may use a representation that exceeds those limits. Operations on real numbers,
for example, might use single-precision or double-precision floating-point
numbers. (See implementation note 44 in Appendix H.)
178
CHAPTER 3
Syntax
Errors in Type 4 Functions
The code that reads a type 4 function (analogous to the PostScript scanner) must
detect and report syntax errors. It may also be able to detect some errors that will
occur when the function is used, although this is not always possible. Any errors
detected by the scanner are considered to be errors in the PDF file and are
handled like other errors in the file.
The code that executes a type 4 function (analogous to the PostScript interpreter)
must detect and report errors. PDF does not define a representation for the
errors; those details are provided by the application that processes the PDF file.
The following types of errors can occur (among others):
• Stack overflow
• Stack underflow
• A type error (for example, applying not to a real number)
• A range error (for example, applying sqrt to a negative number)
• An undefined result (for example, dividing by 0)
3.10
File Specifications
A PDF file can refer to the contents of another file by using a file specification
(PDF 1.1), which can take either of two forms:
• A simple file specification gives just the name of the target file in a standard for-
mat, independent of the naming conventions of any particular file system. It
can take the form of either a string or a dictionary
• A full file specification includes information related to one or more specific file
systems. It can only be represented as a dictionary.
Although the file designated by a file specification is normally external to the
PDF file referring to it, PDF 1.3 permits a copy of the external file to be
embedded within the referring PDF file, allowing its contents to be stored or
transmitted along with the PDF file. However, embedding a file does not change
the presumption that it is external to the PDF file. Consequently, to ensure that
the PDF file can be processed correctly, it may be necessary to copy its embedded
files back into a local file system.
179
SECTION 3.10
File Specifications
3.10.1
File Specification Strings
The standard format for representing a simple file specification in string form
divides the string into component substrings separated by the slash character (/).
The slash is a generic component separator that is mapped to the appropriate
platform-specific separator when generating a platform-dependent file name.
Any of the components may be empty. If a component contains one or more
literal slashes, each must be preceded by a backslash (\), which in turn must be
preceded by another backslash to indicate that it is part of the string and not an
escape character. For example, the string
( in \ \ /out )
represents the file name
in / out
The backslashes are removed in processing the string; they are needed only to
distinguish the component values from the component separators. The
component substrings are stored as bytes and are passed to the operating system
without interpretation or conversion of any sort.
Absolute and Relative File Specifications
A simple file specification that begins with a slash is an absolute file specification.
The last component is the file name; the preceding components specify its
context. In some file specifications, the file name may be empty; for example,
URL (uniform resource locator) specifications can specify directories instead of
files. A file specification that does not begin with a slash is a relative file
specification giving the location of the file relative to that of the PDF file
containing it.
In the case of a URL-based file system, the rules of Internet RFC 1808, Relative
Uniform Resource Locators (see the Bibliography), are used to compute an
absolute URL from a relative file specification and the specification of the PDF
file. Prior to this process, the relative file specification is converted to a relative
URL by using the escape mechanism of RFC 1738, Uniform Resource Locators, to
represent any bytes that would be either unsafe according to RFC 1738 or not
representable in 7-bit U.S. ASCII. In addition, such URL-based relative file
specifications are limited to paths as defined in RFC 1808. The scheme, network
180
CHAPTER 3
Syntax
location/login, fragment identifier, query information, and parameter sections
are not allowed.
In the case of other file systems, a relative file specification is converted to an
absolute file specification by removing the file name component from the
specification of the containing PDF file and appending the relative file
specification in its place. For example, the relative file specification
ArtFiles / Figure1 . pdf
appearing in a PDF file whose specification is
/ HardDisk / PDFDocuments / AnnualReport / Summary. pdf
yields the absolute specification
/ HardDisk / PDFDocuments / AnnualReport / ArtFiles / Figure1 . pdf
The special component . . (two periods) can be used in a relative file specification
to move up a level in the file system hierarchy. When the component immediately
preceding . . is not another . . , the two cancel each other; both are eliminated from
the file specification and the process is repeated. Thus, in the example above, the
relative file specification
. . /. . / ArtFiles / Figure1 . pdf
would yield the absolute specification
/ HardDisk / ArtFiles / Figure1 . pdf
Conversion to Platform-Dependent File Names
The conversion of a file specification to a platform-dependent file name depends
on the specific file naming conventions of each platform:
• For DOS, the initial component is either a physical or logical drive identifier or
a network resource name as returned by the Microsoft Windows function
WNetGetConnection, and is followed by a colon ( : ). A network resource name is
constructed from the first two components; the first component is the server
name and the second is the share name (volume name). All components are
then separated by backslashes. It is possible to specify an absolute DOS path
181
SECTION 3.10
File Specifications
without a drive by making the first component empty. (Empty components are
ignored by other platforms.)
• For Mac OS, all components are separated by colons ( : ).
• For UNIX, all components are separated by slashes ( / ). An initial slash, if
present, is preserved.
Strings used to specify a file name are interpreted in the standard encoding for
the platform on which the document is being viewed. Table 3.40 shows examples
of file specifications on the most common platforms.
TABLE 3.40 Examples of file specifications
SYSTEM
SYSTEM-DEPENDENT PATHS
WRITTEN FORM
DOS
\ pdfdocs \ spec . pdf ( no drive )
( / / pdfdocs / spec . pdf )
r : \ pdfdocs \ spec . pdf
( / r / pdfdocs / spec . pdf )
( / pclib / eng / pdfdocs / spec . pdf )
pclib / eng : \ pdfdocs \ spec . pdf
Mac OS
Mac HD : PDFDocs : spec . pdf
( /Mac HD/ PDFDocs/ spec . pdf )
UNIX
/ user / fred / pdfdocs / spec . pdf
( / user / fred / pdfdocs / spec . pdf )
pdfdocs / spec . pdf ( relative )
( pdfdocs / spec . pdf )
When creating documents that are to be viewed on multiple platforms, care must
be taken to ensure file name compatibility. Only a subset of the U.S. ASCII
character set should be used in file specifications: the uppercase alphabetic
characters (A-Z), the numeric characters (0-9), and the underscore ( _ ). The
period ( . ) has special meaning in DOS and Windows file names, and as the first
character in a Mac OS pathname. In file specifications, the period should be used
only to separate a base file name from a file extension.
Some file systems are case-insensitive, and names within a directory should
remain distinguishable if lowercase letters are changed to uppercase or vice
versa. On DOS and Windows 3.1 systems and on some CD-ROM file systems,
file names are limited to 8 characters plus a 3-character extension. File system
software typically converts long names to short names by retaining the first 6 or
7 characters of the file name and the first 3 characters after the last period, if any.
Since characters beyond the sixth or seventh are often converted to other values
unrelated to the original value, file names must be distinguishable from the first
6 characters.
182
CHAPTER 3
Syntax
Multiple-Byte Strings in File Specifications
In PDF 1.2 or higher, a file specification may contain multiple-byte character
codes, represented in hexadecimal form between angle brackets (< and >). Since
the slash character < 2F > is used as a component delimiter and the backslash
< 5C > is used as an escape character, any occurrence of either of these bytes in a
multiple-byte character must be preceded by the ASCII code for the backslash
character. For example, a file name containing the
2-byte character code
< 89 5C > must write it as < 89 5C 5C >. When the application encounters this
sequence of bytes in a file name, it replaces the sequence with the original 2-byte
code.
3.10.2
File Specification Dictionaries
The dictionary form of file specification provides more flexibility than the string
form, allowing different files to be specified for different file systems or
platforms, or for file systems other than the standard ones (DOS/Windows, Mac
OS, and UNIX). Table 3.41 shows the entries in a file specification dictionary.
Regardless of the platform, consumer applications should use the F and
(beginning with PDF 1.7) UF entries to specify files. The UF entry is optional, but
it is also recommended because it enables cross-platform and cross-language
compatibility.
TABLE 3.41 Entries in a file specification dictionary
KEY
TYPE
VALUE
Type
name
(Required if an EF or RF entry is present; recommended always) The type of PDF object
that this dictionary describes; must be Filespec for a file specification dictionary (see
implementation note 45 in Appendix H).
FS
name
(Optional) The name of the file system to be used to interpret this file specification. If
this entry is present, all other entries in the dictionary are interpreted by the desig-
nated file system. PDF defines only one standard file system name, URL (see Section
3.10.4, “URL Specifications”); an application or plug-in extension can register other
names (see Appendix E). This entry is independent of the F, UF, DOS, Mac, and Unix
entries.
183
SECTION 3.10
File Specifications
KEY
TYPE
VALUE
F
string
(Required if the DOS, Mac, and Unix entries are all absent; amended with the UF entry
for PDF 1.7) A file specification string of the form described in Section 3.10.1, “File
Specification Strings,” or (if the file system is URL) a uniform resource locator, as de-
scribed in Section 3.10.4, “URL Specifications.”
Note: It is recommended that the UF entry be used in addition to the F entry. The UF en-
try provides cross-platform and cross-language compatibility and the F entry provides
backwards compatibility.
UF
text string
(Optional, but recommended if the F entry exists in the dictionary; PDF 1.7) A Unicode
text string that provides file specification of the form described in Section 3.10.1, “File
Specification Strings.” Note that this is a Unicode text string encoded using PDFDocEn-
coding or UTF-16BE with a leading byte-order marker (as defined in Section , “Text
String Type”). The F entry should always be included along with this entry for back-
wards compatibility reasons.
DOS
byte string
(Optional) A file specification string (see Section 3.10.1, “File Specification Strings”)
representing a DOS file name.
Note: Beginning with PDF 1.7, use of the F entry and optionally the UF entry is recom-
mended in place of the DOS, Mac or Unix entries.
Mac
byte string
(Optional) A file specification string (see Section 3.10.1, “File Specification Strings”)
representing a Mac OS file name.
Note: Beginning with PDF 1.7, use of the F entry and optionally the UF entry is recom-
mended in place of the DOS, Mac or Unix entries.
Unix
byte string
(Optional) A file specification string (see Section 3.10.1, “File Specification Strings”)
representing a UNIX file name.
Note: Beginning with PDF 1.7, use of the F entry and optionally the UF entry is recom-
mended in place of the DOS, Mac or Unix entries.
ID
array
(Optional) An array of two byte strings constituting a file identifier (see Section 10.3,
“File Identifiers”) that is also included in the referenced file. The use of this entry im-
proves an application’s chances of finding the intended file and allows it to warn the
user if the file has changed since the link was made.
V
boolean
(Optional; PDF 1.2) A flag indicating whether the file referenced by the file specifica-
tion is volatile (changes frequently with time). If the value is true, applications should
never cache a copy of the file. For example, a movie annotation referencing a URL to
a live video camera could set this flag to true to notify the application that it should
reacquire the movie each time it is played. Default value: false.
184
CHAPTER 3
Syntax
KEY
TYPE
VALUE
EF
dictionary
(Required if RF is present; PDF 1.3; amended to include the UF key in PDF 1.7) A dictio-
nary containing a subset of the keys F, UF, DOS, Mac, and Unix, corresponding to the
entries by those names in the file specification dictionary. The value of each such key
is an embedded file stream (see Section 3.10.3, “Embedded File Streams”) containing
the corresponding file. If this entry is present, the Type entry is required and the file
specification dictionary must be indirectly referenced. (See implementation note 46
in Appendix H.)
Note: It is recommended that the F and UF entries be used in place of the DOS, Mac, or
Unix entries.
RF
dictionary
(Optional; PDF 1.3) A dictionary with the same structure as the EF dictionary, which
must also be present. Each key in the RF dictionary must also be present in the EF dic-
tionary. Each value is a related files array (see “Related Files Arrays” on page 186)
identifying files that are related to the corresponding file in the EF dictionary. If this
entry is present, the Type entry is required and the file specification dictionary must
be indirectly referenced.
Desc
text string
(Optional; PDF 1.6) Descriptive text associated with the file specification. It is used
for files in the EmbeddedFiles name tree (see Section 3.6.3, “Name Dictionary”).
CI
dictionary
(Optional; must be indirect reference; PDF 1.7) A collection item dictionary, which is
used to create the user interface for portable collections (see Section 3.10.5, “Collec-
tion Items).
3.10.3
Embedded File Streams
File specifications ordinarily refer to files external to the PDF file in which they
occur. When a PDF file is archived or transmitted, all external files it refers to
must accompany it to preserve the file’s integrity. Embedded file streams (PDF 1.3)
address this problem by allowing the contents of referenced files to be embedded
directly within the body of the PDF file. For example, if the file contains OPI
(Open Prepress Interface) dictionaries that refer to externally stored high-
resolution images (see Section 10.10.6, “Open Prepress Interface (OPI)”), the
image data can be incorporated into the PDF file with embedded file streams.
This makes the PDF file a self-contained unit that can be stored or transmitted as
a single entity. (The embedded files are included purely for convenience and need
not be directly processed by any PDF consumer application.)
185
SECTION 3.10
File Specifications
An embedded file stream can be included in a PDF document in the following
ways:
• Any file specification dictionary in the document may have an EF entry that
specifies an embedded file stream. The stream data must still be associated with
a location in the file system. In particular, this method is used for file attach-
ment annotations (see “File Attachment Annotations” on page 637), which as-
sociate the embedded file with a location on a page in the document.
• Embedded file streams can be associated with the document as a whole
through the EmbeddedFiles entry (PDF 1.4) in the PDF document’s name dic-
tionary (see Section 3.6.3, “Name Dictionary”). The associated name tree maps
name strings to file specifications that refer to embedded file streams through
their EF entries. (See implementation note 45 in Appendix H.)
Note: Beginning with PDF 1.6, the Desc entry of the file specification dictionary
(see Table 3.41) can be used to provide a textual description of the embedded file,
which can be displayed in the user interface of a viewer application. Previously, it
was necessary to identify document-level embedded files by the name string pro-
vided in the name dictionary associated with an embedded file stream in much
the same way that the JavaScript name tree associates name strings with docu-
ment-level JavaScript actions (see “JavaScript Actions” on page 709).
The stream dictionary describing an embedded file contains the standard entries
for any stream, such as Length and Filter (see Table 3.4 on page 62), as well as the
additional entries shown in Table 3.42.
TABLE 3.42 Additional entries in an embedded file stream dictionary
KEY
TYPE
VALUE
Type
name
(Optional) The type of PDF object that this dictionary describes; if present,
must be EmbeddedFile for an embedded file stream.
Subtype
name
(Optional) The subtype of the embedded file. The value of this entry must be
a first-class name, as defined in Appendix E. Names without a registered pre-
fix must conform to the MIME media type names defined in Internet RFC
2046, Multipurpose Internet Mail Extensions (MIME), Part Two: Media Types
(see the Bibliography), with the provision that characters not allowed in
names must use the 2-character hexadecimal code format described in Sec-
tion 3.2.4, “Name Objects.”
Params
dictionary
(Optional) An embedded file parameter dictionary containing additional, file-
specific information (see Table 3.43).
186
CHAPTER 3
Syntax
TABLE 3.43 Entries in an embedded file parameter dictionary
KEY
TYPE
VALUE
Size
integer
(Optional) The size of the embedded file, in bytes.
CreationDate
date
(Optional) The date and time when the embedded file was created.
ModDate
date
(Optional) The date and time when the embedded file was last modified.
Mac
dictionary
(Optional) A subdictionary containing additional information specific to
Mac OS files (see Table 3.44).
CheckSum
string
(Optional) A 16-byte string that is the checksum of the bytes of the uncom-
pressed embedded file. The checksum is calculated by applying the standard
MD5 message-digest algorithm (described in Internet RFC 1321, The MD5
Message-Digest Algorithm; see the Bibliography) to the bytes of the embedded
file stream.
For Mac OS files, the Mac entry in the embedded file parameter dictionary holds
a further subdictionary containing Mac OS-specific file information. Table 3.44
shows the contents of this subdictionary.
TABLE 3.44 Entries in a Mac OS file information dictionary
KEY
TYPE
VALUE
Subtype
integer
(Optional) The embedded file’s file type. It is encoded as an integer according to Mac
OS conventions: a 4-character ASCII text literal, converted to a 32-bit integer, with the
high-order byte first. For example, the file type 'CARO' is represented as the hexadeci-
mal integer 4341524F, which is expressed in decimal as 1128354383.
Creator
integer
(Optional) The embedded file’s creator signature, encoded in the same way as Subtype.
ResFork
stream
(Optional) The binary contents of the embedded file’s resource fork.
Related Files Arrays
In some circumstances, a PDF file can refer to a group of related files, such as the
set of five files that make up a DCS
1.0 color-separated image. The file
specification explicitly names only one of the files; the rest are identified by some
systematic variation of that file name (such as by altering the extension). When
such a file is to be embedded in a PDF file, the related files must be embedded as
187
SECTION 3.10
File Specifications
well. This is accomplished by including a related files array (PDF 1.3) as the value
of the RF entry in the file specification dictionary. The array has 2 × n elements,
which are paired in the form
[ string1 stream1
string2 stream2
…
stringn streamn
]
The first element of each pair is a string giving the name of one of the related files;
the second element is an embedded file stream holding the file’s contents.
In Example 3.21, objects 21, 31, and 41 are embedded file streams containing the
DOS file SUNSET. EPS, the Mac OS file Sunset . eps, and the UNIX file Sunset . eps,
respectively. The file specification dictionary’s RF entry specifies an array, object
30, identifying a set of embedded files related to the Mac OS file, forming a
DCS 1.0 set. The example shows only the first two embedded file streams in the
set; an actual PDF file would, of course, include all of them.
Example 3.21
10 0 obj
% File specification dictionary
<< /Type /Filespec
/DOS ( SUNSET. EPS)
/Mac ( Sunset . eps )
% Name of Mac OS file
/Unix ( Sunset . eps )
/EF << /DOS
21 0 R
/Mac 31 0 R
% Embedded Mac OS file
/Unix 41 0 R
>>
/RF << /Mac 30 0 R >>
% Related files array for Mac OS file
>>
endobj
30 0 obj
% Related files array for Mac OS file
[
( Sunset . eps )
31 0 R
% Includes file Sunset . eps itself
( Sunset . C )
32 0 R
( Sunset . M ) 33 0 R
( Sunset . Y )
34 0 R
( Sunset . K )
35 0 R
]
endobj
188
CHAPTER 3
Syntax
31 0 obj
% Embedded file stream for Mac OS file
<< /Type /EmbeddedFile
% Sunset . eps
/Length …
/Filter
…
>>
stream
… Data for Sunset . eps…
endstream
endobj
32 0 obj
% Embedded file stream for related file
<< /Type /EmbeddedFile
% Sunset . C
/Length …
/Filter
…
>>
stream
… Data for Sunset . C…
endstream
endobj
3.10.4
URL Specifications
When the FS entry in a file specification dictionary has the value URL, the value of
the F entry in that dictionary is not a file specification string, but a uniform
resource locator (URL) of the form defined in Internet RFC 1738, Uniform
Resource Locators
(see the Bibliography). Example
3.22 shows a URL
specification.
Example 3.22
<< /FS /URL
/F
( ftp : / / www . beatles . com / Movies / AbbeyRoad . mov )
>>
The URL must adhere to the character-encoding requirements specified in RFC
1738. Because 7-bit U.S. ASCII is a strict subset of PDFDocEncoding, this value
may also be considered to be in that encoding.
189
SECTION 3.10
File Specifications
3.10.5
Collection Items
Beginning with PDF 1.7, a collection item dictionary contains the data described
by the collection schema dictionary for a particular file in a collection (see
Section 8.2.4, “Collections). Table 3.45 describes the entries in a collection item
dictionary.
TABLE 3.45 Entries in a collection item dictionary
KEY
TYPE
VALUE
Type
name
(Optional) The type of PDF object that this dictionary describes; if present, must be
CollectionItem for a collection item dictionary.
Other
text string,
(Optional) Provides the data corresponding to the related fields in the collection dic-
keys
date,
tionary. If the entry is a dictionary, then it is a collection subitem dictionary (see
chosen by
number or
Table 3.46).
producer dictionary
The type of each entry must match the type of data identified by the collection field
dictionary (see Table 8.8 on page 591). For example, if the corresponding collection
field has a Subtype entry of S, then the entry is a text string.
A single collection item dictionary may contain multiple entries, with one entry rep-
resenting each key (see Example 8.3 on page 593).
A collection subitem dictionary provides the data corresponding to the related
fields in the collection dictionary, and it provides a means of associating a prefix
string with that data value. The prefix is ignored by the sorting algorithm.
Table 3.46 describes the entries in a collection subitem dictionary.
TABLE 3.46 Entries in a collection subitem dictionary
KEY
TYPE
VALUE
Type
name
(Optional) The type of PDF object that this dictionary describes; if present, must be
CollectionSubitem for a collection item dictionary.
D
text string,
(Optional) The data corresponding to the related entry in the collection field dictio-
date, or
nary (see Table 8.8 on page 591). The type of data must match the data type identified
number
by the collection field dictionary. Default: none.
P
text string
(Optional) A prefix string that is concatenated with the text string presented to the
user. This entry is ignored when a PDF viewer application sorts the items in the col-
lection. Default: none.
190
CHAPTER 3
Syntax
3.10.6
Maintenance of File Specifications
The techniques described in this section can be used to maintain the integrity of
the file specifications within a PDF file during the following types of operations:
• Updating the relevant file specification when a referenced file is renamed
• Determining the complete collection of files that must be copied to a mirror
site
• When creating new links to external files, discovering existing file specifica-
tions that refer to the same files and sharing them
• Finding the file specifications associated with embedded files to be packed or
unpacked
It is not possible, in general, to find all file specification strings in a PDF file
because there is no way to determine whether a given string is a file specification
string. It is possible, however, to find all file specification dictionaries, provided
that they meet the following conditions:
• They are indirect objects.
• They contain a Type entry whose value is the name Filespec.
An application can locate all of the file specification dictionaries by traversing the
PDF file’s cross-reference table (see Section 3.4.3, “Cross-Reference Table”) and
finding all dictionaries with Type keys whose value is Filespec. For this reason, it
is highly recommended that all file specifications be expressed in dictionary form
and meet the conditions stated above. Note that any file specification dictionary
specifying embedded files (that is, one that contains an EF entry) must satisfy
these conditions (see Table 3.41 on page 182).
Note: It may not be possible to locate file specification dictionaries that are direct
objects, since they are neither self-typed nor necessarily reachable by any standard
path of object references.
Files may be embedded in a PDF file either directly, using the EF entry in a file
specification dictionary, or indirectly, using related files arrays specified in the RF
entry. If a file is embedded indirectly, its name is given by the string that precedes
the embedded file stream in the related files array. If it is embedded directly, its
name is obtained from the value of the corresponding entry in the file
191
SECTION 3.10
File Specifications
specification dictionary. In Example 3.21 on page 187, for instance, the EF
dictionary has a DOS entry identifying object number 21 as an embedded file
stream. The name of the embedded DOS file, SUNSET. EPS, is given by the DOS
entry in the file specification dictionary.
A given external file may be referenced from more than one file specification.
Therefore, when embedding a file with a given name, it is necessary to check for
other occurrences of the same name as the value associated with the
corresponding key in other file specification dictionaries. This requires finding
all embeddable file specifications and, for each matching key, checking for both
of the following conditions:
• The string value associated with the key matches the name of the file being em-
bedded.
• A value has not already been embedded for the file specification. (If there is
already a corresponding key in the EF dictionary, a file has already been em-
bedded for that use of the file name.)
Note that there is no requirement that the files associated with a given file name
be unique. The same file name, such as readme . txt, may be associated with
different embedded files in distinct file specifications.
192
CHAPTER 3
Syntax
CHAPTER 4
Graphics
4
The graphics operators used in PDF content streams describe the appearance of
pages that are to be reproduced on a raster output device. The facilities described
in this chapter are intended for both printer and display applications.
The graphics operators form six main groups:
• Graphics state operators manipulate the data structure called the graphics state,
the global framework within which the other graphics operators execute. The
graphics state includes the current transformation matrix (CTM), which maps
user space coordinates used within a PDF content stream into output device
coordinates. It also includes the current color, the current clipping path, and
many other parameters that are implicit operands of the painting operators.
• Path construction operators specify paths, which define shapes, line trajectories,
and regions of various sorts. They include operators for beginning a new path,
adding line segments and curves to it, and closing it.
• Path-painting operators fill a path with a color, paint a stroke along it, or use it
as a clipping boundary.
• Other painting operators paint certain self-describing graphics objects. These
include sampled images, geometrically defined shadings, and entire content
streams that in turn contain sequences of graphics operators.
• Text operators select and show character glyphs from fonts (descriptions of type-
faces for representing text characters). Because PDF treats glyphs as general
graphical shapes, many of the text operators could be grouped with the graph-
ics state or painting operators. However, the data structures and mechanisms
for dealing with glyph and font descriptions are sufficiently specialized that
Chapter 5 focuses on them.
193
194
CHAPTER 4
Graphics
• Marked-content operators associate higher-level logical information with ob-
jects in the content stream. This information does not affect the rendered ap-
pearance of the content (although it may determine if the content should be
presented at all; see Section 4.10, “Optional Content”); it is useful to applica-
tions that use PDF for document interchange. Marked content is described in
Section 10.5, “Marked Content.”
This chapter presents general information about device-independent graphics in
PDF: how a PDF content stream describes the abstract appearance of a page.
Rendering—the device-dependent part of graphics—is covered in Chapter 6. The
Bibliography lists a number of books that give details of these computer graphics
concepts and their implementation.
4.1
Graphics Objects
As discussed in Section 3.7.1, “Content Streams,” the data in a content stream is
interpreted as a sequence of operators and their operands, expressed as basic data
objects according to standard PDF syntax. A content stream can describe the
appearance of a page, or it can be treated as a graphical element in certain other
contexts.
The operands and operators are written sequentially using postfix notation.
Although this notation resembles the sequential execution model of the Post-
Script language, a PDF content stream is not a program to be interpreted; rather,
it is a static description of a sequence of graphics objects. There are specific rules,
described below, for writing the operands and operators that describe a graphics
object.
PDF provides five types of graphics objects:
• A path object is an arbitrary shape made up of straight lines, rectangles, and
cubic Bézier curves. A path may intersect itself and may have disconnected
sections and holes. A path object ends with one or more painting operators that
specify whether the path is stroked, filled, used as a clipping boundary, or some
combination of these operations.
• A text object consists of one or more character strings that identify sequences of
glyphs to be painted. Like a path, text can be stroked, filled, or used as a clip-
ping boundary.
195
SECTION 4.1
Graphics Objects
• An external object (XObject) is an object defined outside the content stream
and referenced as a named resource (see Section 3.7.2, “Resource Diction-
aries”). The interpretation of an XObject depends on its type. An image XOb-
ject defines a rectangular array of color samples to be painted; a form XObject is
an entire content stream to be treated as a single graphics object. Specialized
types of form XObjects are used to import content from one PDF file into an-
other (reference XObjects) and to group graphical elements together as a unit
for various purposes (group XObjects). In particular, the latter are used to de-
fine transparency groups for use in the transparent imaging model (transparen-
cy group XObjects, discussed in detail in Chapter 7). There is also a PostScript
XObject, whose use is discouraged.
• An inline image object uses a special syntax to express the data for a small image
directly within the content stream.
• A shading object describes a geometric shape whose color is an arbitrary func-
tion of position within the shape. (A shading can also be treated as a color
when painting other graphics objects; it is not considered to be a separate
graphics object in that case.)
PDF 1.3 and earlier versions use an opaque imaging model in which each graphics
object is painted in sequence, completely obscuring any previous marks it may
overlay on the page. PDF 1.4 introduces a transparent imaging model in which ob-
jects can be less than fully opaque, allowing previously painted marks to show
through. Each object is painted on the page with a specified opacity, which may
be constant at every point within the object’s shape or may vary from point to
point. The previously existing contents of the page form a backdrop with which
the new object is composited, producing results that combine the colors of the
object and backdrop according to their respective opacity characteristics. The ob-
jects at any given point on the page can be thought of as forming a transparency
stack, where the stacking order is defined to be the order in which the objects are
specified, bottommost object first. All objects in the stack can potentially contrib-
ute to the result, depending on their colors, shapes, and opacities.
PDF’s graphics parameters are so arranged that objects are painted by default
with full opacity, reducing the behavior of the transparent imaging model to that
of the opaque model. Accordingly, the material in this chapter applies to both the
opaque and transparent models except where explicitly stated otherwise; the
transparent model is described in its full generality in Chapter 7.
196
CHAPTER 4
Graphics
Although the painting behavior described above is often attributed to individual
operators making up an object, it is always the object as a whole that is painted.
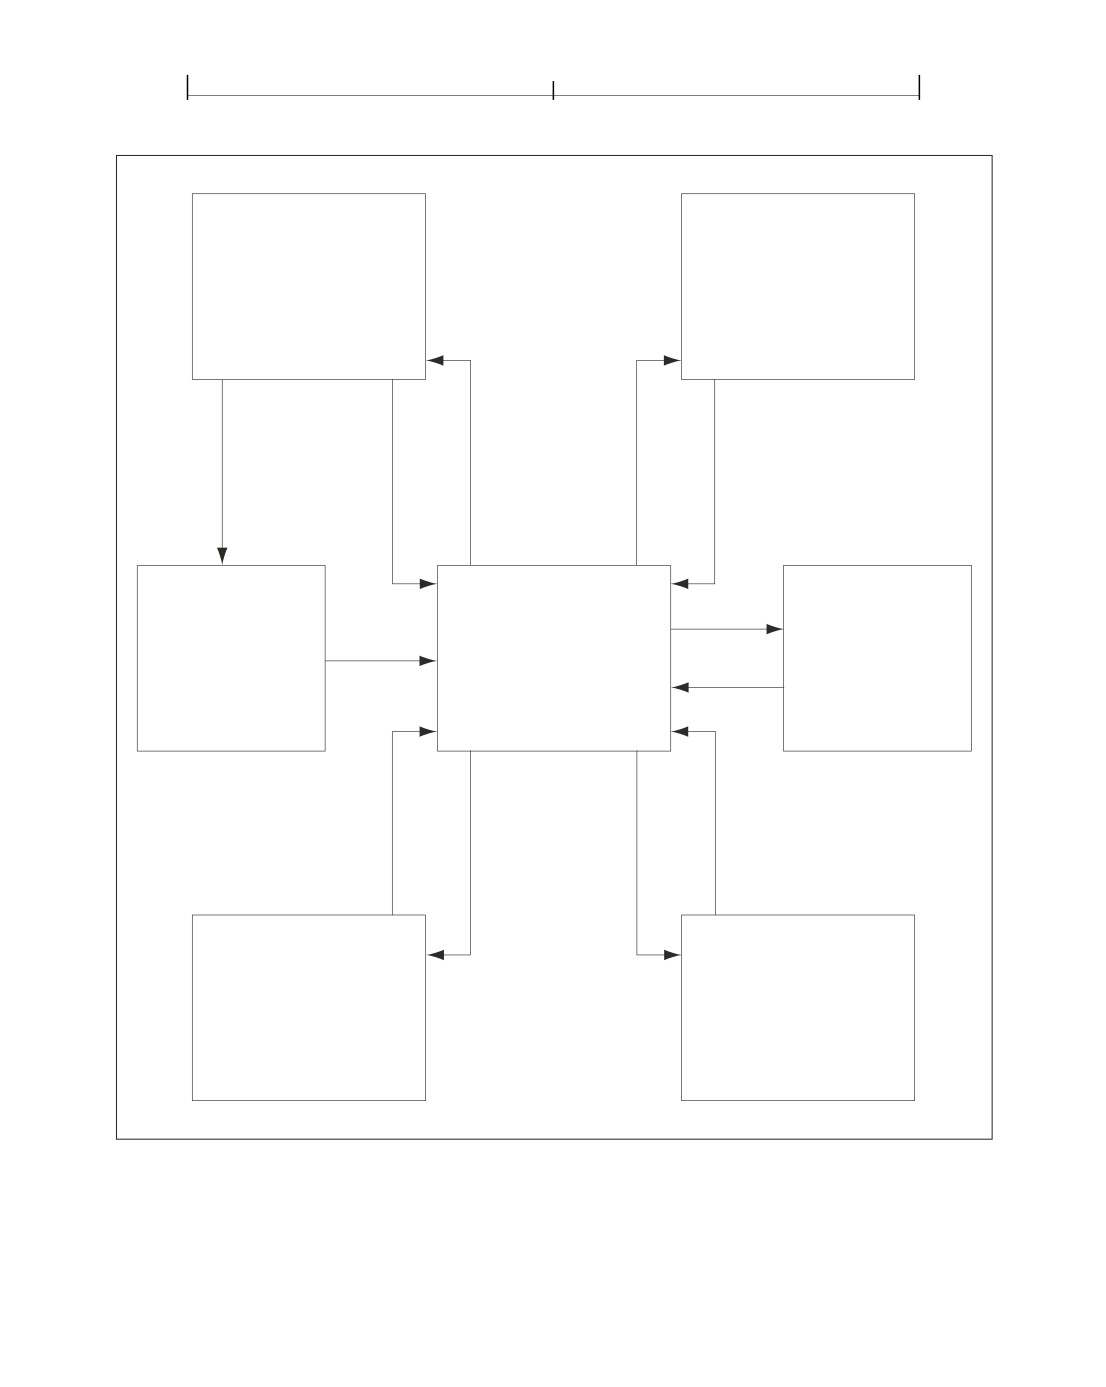
Figure 4.1 shows the ordering rules for the operations that define graphics
objects. Some operations are permitted only in certain types of graphics objects
or in the intervals between graphics objects (called the page description level in
the figure). Every content stream begins at the page description level, where
changes can be made to the graphics state, such as colors and text attributes, as
discussed in the following sections.
In the figure, arrows indicate the operators that mark the beginning or end of
each type of graphics object. Some operators are identified individually, others by
general category. Table 4.1 summarizes these categories for all PDF operators.
TABLE 4.1 Operator categories
CATEGORY
OPERATORS
TABLE
PAGE
General graphics state
w, J, j, M, d, ri, i, gs
4.7
219
Special graphics state
q, Q, cm
4.7
219
Path construction
m, l, c, v, y, h, re
4.9
226
Path painting
S, s, f, F, f*, B, B*, b, b*, n
4.10
230
Clipping paths
W, W*
4.11
235
Text objects
BT, ET
5.4
405
Text state
Tc, Tw, Tz, TL, Tf, Tr, Ts
5.2
398
Text positioning
Td, TD, Tm, T*
5.5
406
Text showing
Tj, TJ, ', "
5.6
407
Type 3 fonts
d0, d1
5.10
423
Color
CS, cs, SC, SCN, sc, scn, G, g, RG, rg, K, k
4.24
287
Shading patterns
sh
4.27
303
Inline images
BI, ID, EI
4.42
352
XObjects
Do
4.37
332
Marked content
MP, DP, BMC, BDC, EMC
10.7
851
Compatibility
BX, EX
3.29
152
197
SECTION 4.1
Graphics Objects
Path object
Text object
Allowed operators:
Allowed operators:
• Path construction
• General graphics state
• Color
• Text state
• Text-showing
• Text-positioning
• Marked-content
W,W* Path-painting
m, re
BT
ET
operators
Clipping path object
Page description level
Shading object
Allowed operators:
Allowed operators:
sh
Allowed operators:
• None
Path-painting
• General graphics state
• None
operators
• Special graphics state
• Color
(immediate)
• Text state
• Marked-content
EI
BI
Do
(immediate)
In-line image object
External object
Allowed operators:
Allowed operators:
• ID
• None
FIGURE 4.1 Graphics objects
198
CHAPTER 4
Graphics
For example, the path construction operators m and re signal the beginning of a
path object. Inside the path object, additional path construction operators are
permitted, as are the clipping path operators W and W*, but not general graphics
state operators such as w or J. A path-painting operator, such as S or f, ends the
path object and returns to the page description level.
Note: A content stream whose operations violate these rules for describing graphics
objects can produce unpredictable behavior, even though it may display and print
correctly. Applications that attempt to extract graphics objects for editing or other
purposes depend on the objects’ being well formed. The rules for graphics objects are
also important for the proper interpretation of marked content (see Section 10.5,
“Marked Content”).
A graphics object also implicitly includes all graphics state parameters that affect
its behavior. For instance, a path object depends on the value of the current color
parameter at the moment the path object is defined. The effect is as if this param-
eter were specified as part of the definition of the path object. However, the oper-
ators that are invoked at the page description level to set graphics state
parameters are not considered to belong to any particular graphics object. Graph-
ics state parameters need to be specified only when they change. A graphics
object may depend on parameters that were defined much earlier.
Similarly, the individual character strings within a text object implicitly include
the graphics state parameters on which they depend. Most of these parameters
may be set inside or outside the text object. The effect is as if they were separately
specified for each text string.
The important point is that there is no semantic significance to the exact arrange-
ment of graphics state operators. An application that reads and writes a PDF con-
tent stream is not required to preserve this arrangement, but is free to change it to
any other arrangement that achieves the same values of the relevant graphics state
parameters for each graphics object. An application should not infer any higher-
level logical semantics from the arrangement of tokens constituting a graphics
object. A separate mechanism, marked content (see Section 10.5, “Marked Con-
tent”), allows such higher-level information to be explicitly associated with the
graphics objects.
199
SECTION 4.2
Coordinate Systems
4.2
Coordinate Systems
Coordinate systems define the canvas on which all painting occurs. They deter-
mine the position, orientation, and size of the text, graphics, and images that
appear on a page. This section describes each of the coordinate systems used in
PDF, how they are related, and how transformations among them are specified.
Note: The coordinate systems discussed in this section apply to two-dimensional
graphics. PDF 1.6 introduces the ability to display 3D artwork, in which objects are
described in a three-dimensional coordinate system, as described in Section 9.5.4,
“Coordinate Systems for 3D.”
4.2.1
Coordinate Spaces
Paths and positions are defined in terms of pairs of coordinates on the Cartesian
plane. A coordinate pair is a pair of real numbers x and y that locate a point hori-
zontally and vertically within a two-dimensional coordinate space. A coordinate
space is determined by the following properties with respect to the current page:
• The location of the origin
• The orientation of the x and y axes
• The lengths of the units along each axis
PDF defines several coordinate spaces in which the coordinates specifying graph-
ics objects are interpreted. The following sections describe these spaces and the
relationships among them.
Transformations among coordinate spaces are defined by transformation matri-
ces, which can specify any linear mapping of two-dimensional coordinates, in-
cluding translation, scaling, rotation, reflection, and skewing. Transformation
matrices are discussed in Sections 4.2.2, “Common Transformations,” and 4.2.3,
“Transformation Matrices.”
Device Space
The contents of a page ultimately appear on a raster output device such as a dis-
play or a printer. Such devices vary greatly in the built-in coordinate systems they
use to address pixels within their imageable areas. A particular device’s coordi-
200
CHAPTER 4
Graphics
nate system is called its device space. The origin of the device space on different
devices can fall in different places on the output page; on displays, the origin can
vary depending on the window system. Because the paper or other output me-
dium moves through different printers and imagesetters in different directions,
the axes of their device spaces may be oriented differently. For instance, vertical
(y) coordinates may increase from the top of the page to the bottom on some
devices and from bottom to top on others. Finally, different devices have different
resolutions; some even have resolutions that differ in the horizontal and vertical
directions.
If coordinates in a PDF file were specified in device space, the file would be
device-dependent and would appear differently on different devices. For exam-
ple, images specified in the typical device spaces of a 72-pixel-per-inch display
and a 600-dot-per-inch printer would differ in size by more than a factor of 8; an
8-inch line segment on the display would appear less than 1 inch long on the
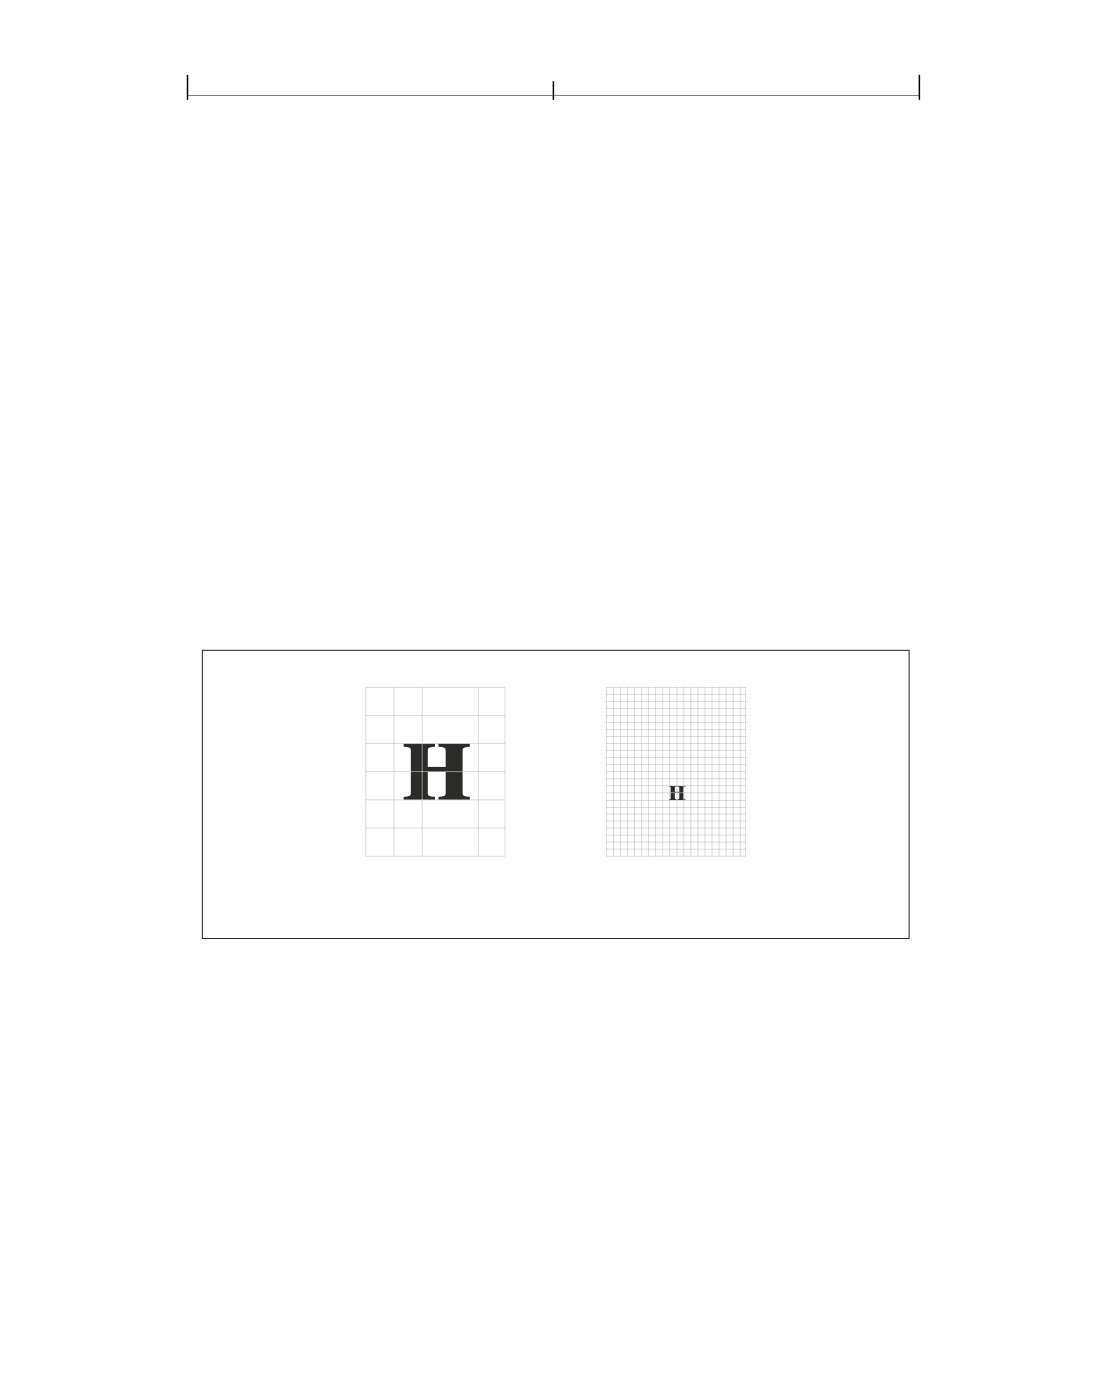
printer. Figure 4.2 shows how the same graphics object, specified in device space,
can appear drastically different when rendered on different output devices.
Device space for
Device space for
72-dpi screen
300-dpi printer
FIGURE 4.2 Device space
User Space
To avoid the device-dependent effects of specifying objects in device space, PDF
defines a device-independent coordinate system that always bears the same rela-
tionship to the current page, regardless of the output device on which printing or
displaying occurs. This device-independent coordinate system is called user
space.
201
SECTION 4.2
Coordinate Systems
The user space coordinate system is initialized to a default state for each page of a
document. The CropBox entry in the page dictionary specifies the rectangle of
user space corresponding to the visible area of the intended output medium (dis-
play window or printed page). The positive x axis extends horizontally to the
right and the positive y axis vertically upward, as in standard mathematical prac-
tice (subject to alteration by the Rotate entry in the page dictionary). The length
of a unit along both the x and y axes is set by the UserUnit entry (PDF 1.6) in the
page dictionary (see Table 3.27). If that entry is not present or supported, the de-
fault value of 1⁄ 72 inch is used. This coordinate system is called default user space.
Note: In PostScript, the origin of default user space always corresponds to the lower-
left corner of the output medium. While this convention is common in PDF docu-
ments as well, it is not required; the page dictionary’s CropBox entry can specify any
rectangle of default user space to be made visible on the medium.
Note: The default for the size of the unit in default user space (1⁄ 72 inch) is approx-
imately the same as a point, a unit widely used in the printing industry. It is not ex-
actly the same, however; there is no universal definition of a point.
Conceptually, user space is an infinite plane. Only a small portion of this plane
corresponds to the imageable area of the output device: a rectangular region de-
fined by the CropBox entry in the page dictionary. The region of default user
space that is viewed or printed can be different for each page and is described in
Section 10.10.1, “Page Boundaries.”
Note: Because coordinates in user space (as in any other coordinate space) may be
specified as either integers or real numbers, the unit size in default user space does
not constrain positions to any arbitrary grid. The resolution of coordinates in user
space is not related in any way to the resolution of pixels in device space.
The transformation from user space to device space is defined by the current
transformation matrix (CTM), an element of the PDF graphics state (see Section
4.3, “Graphics State”). A PDF consumer application can adjust the CTM for the
native resolution of a particular output device, maintaining the device-
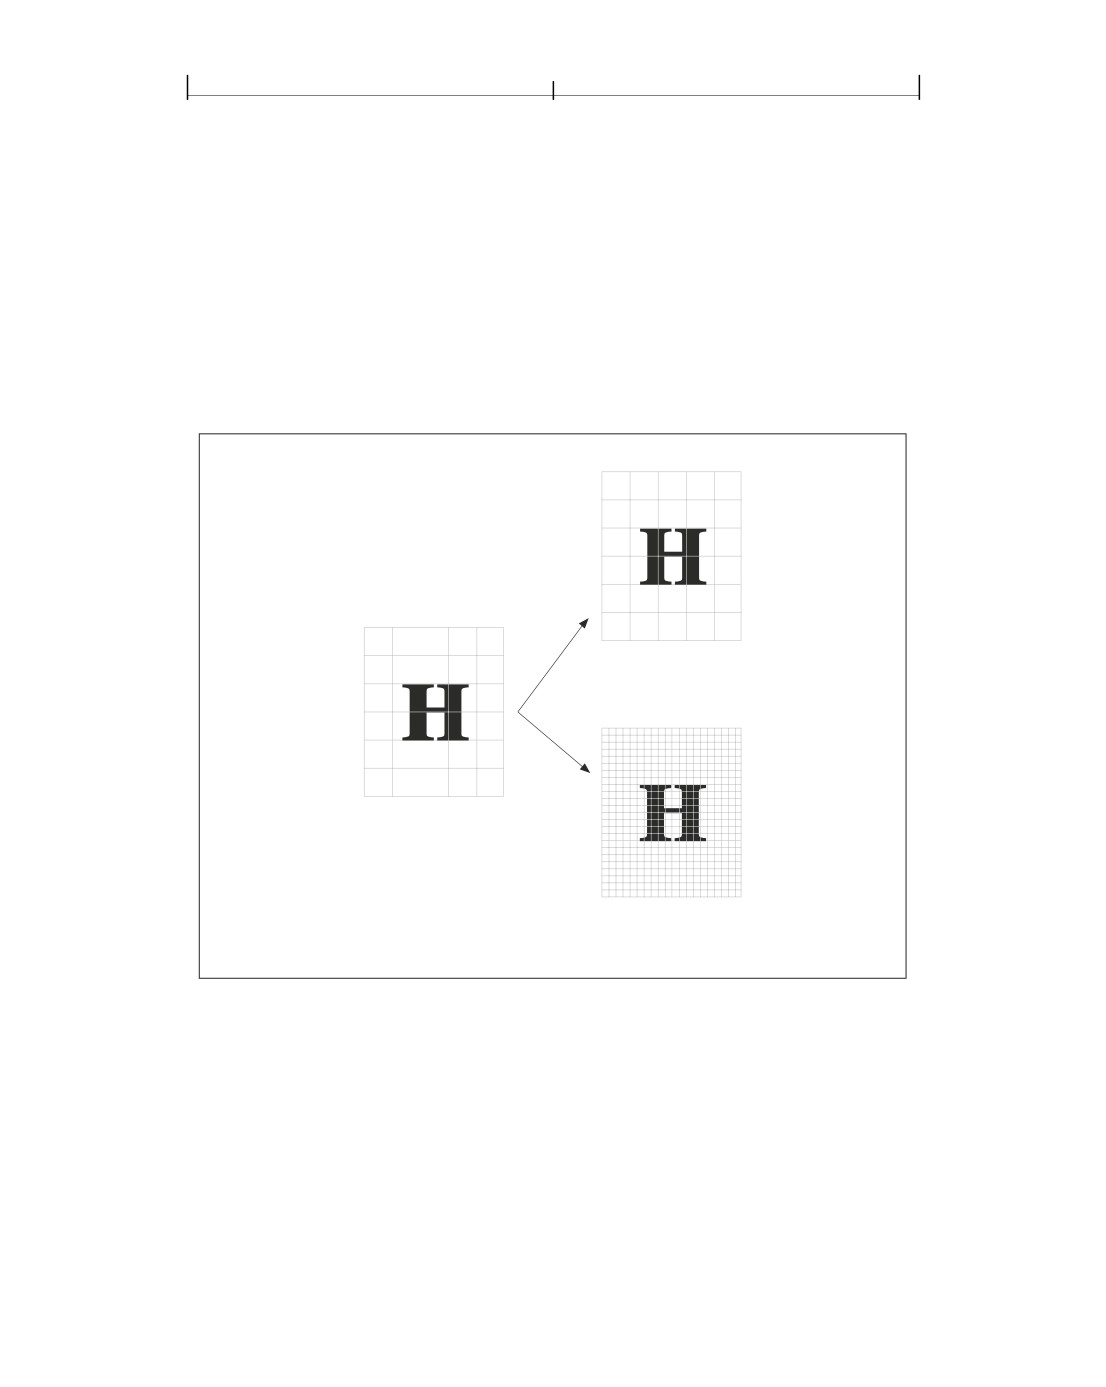
independence of the PDF page description. Figure 4.3 shows how this allows an
object specified in user space to appear the same regardless of the device on
which it is rendered.
The default user space provides a consistent, dependable starting place for PDF
page descriptions regardless of the output device used. If necessary, a PDF con-
202
CHAPTER 4
Graphics
tent stream may modify user space to be more suitable to its needs by applying
the coordinate transformation operator, cm (see Section 4.3.3, “Graphics State Op-
erators”). Thus, what may appear to be absolute coordinates in a content stream
are not absolute with respect to the current page because they are expressed in a
coordinate system that may slide around and shrink or expand. Coordinate sys-
tem transformation not only enhances device-independence but is a useful tool
in its own right. For example, a content stream originally composed to occupy an
entire page can be incorporated without change as an element of another page by
shrinking the coordinate system in which it is drawn.
Device space for
72-dpi screen
CTM
User space
Device space for
300-dpi printer
FIGURE 4.3 User space
203
SECTION 4.2
Coordinate Systems
Other Coordinate Spaces
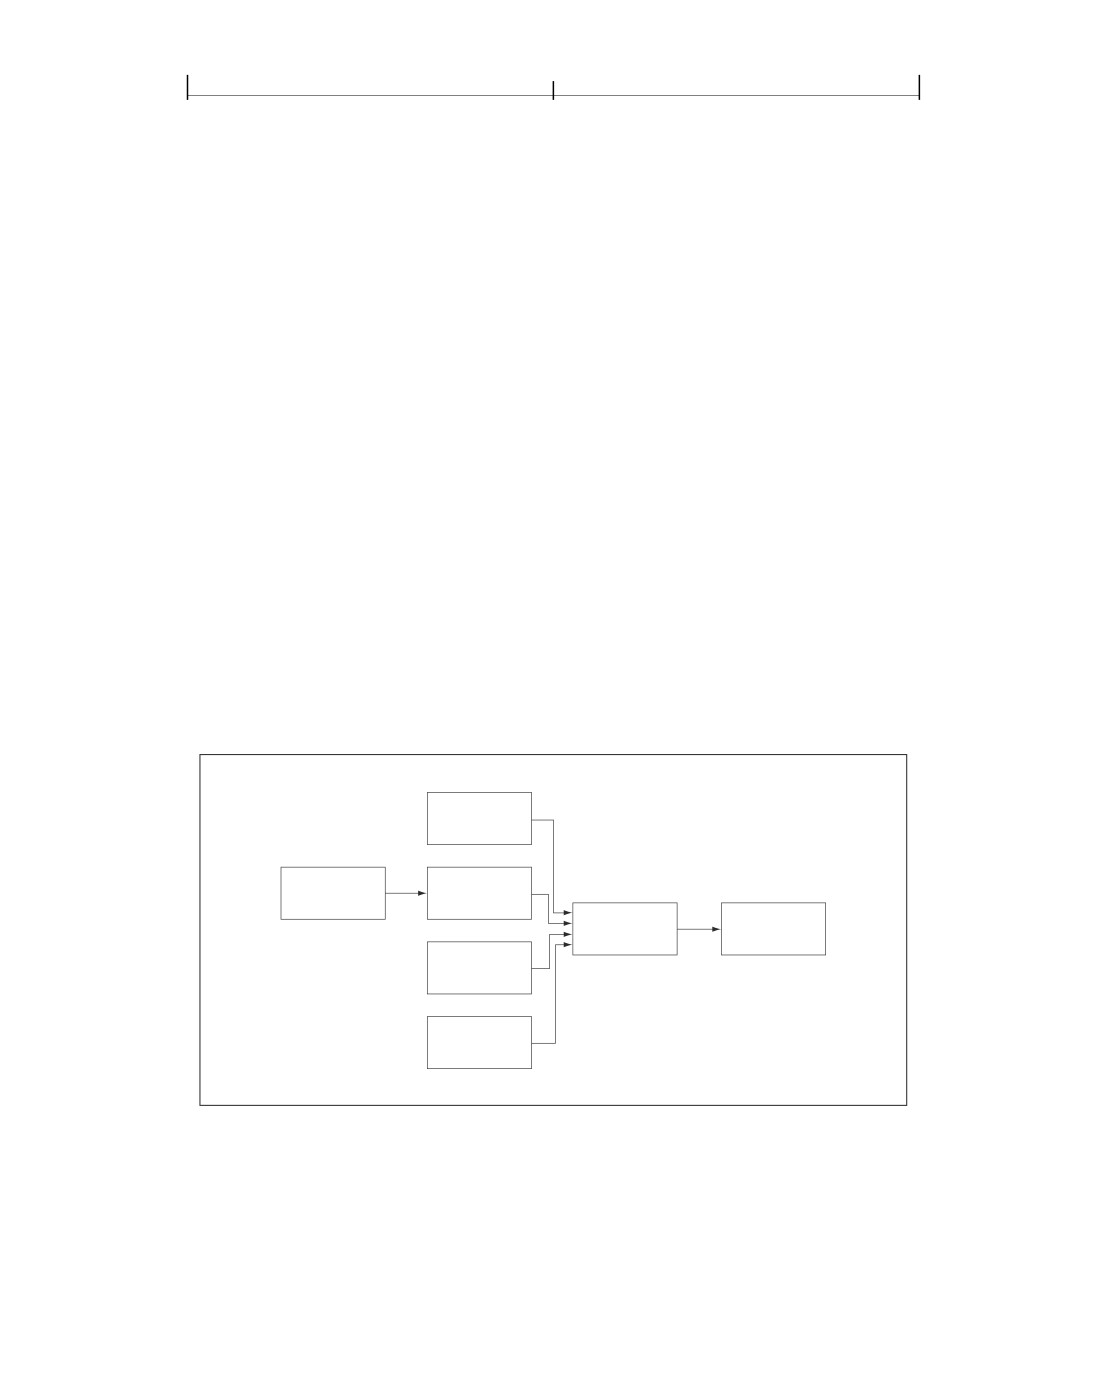
In addition to device space and user space, PDF uses a variety of other coordinate
spaces for specialized purposes:
• The coordinates of text are specified in text space. The transformation from text
space to user space is defined by a text matrix in combination with several text-
related parameters in the graphics state (see Section 5.3.1, “Text-Positioning
Operators”).
• Character glyphs in a font are defined in glyph space (see Section 5.1.3, “Glyph
Positioning and Metrics”). The transformation from glyph space to text space
is defined by the font matrix. For most types of fonts, this matrix is predefined
to map 1000 units of glyph space to 1 unit of text space; for Type 3 fonts, the
font matrix is given explicitly in the font dictionary (see Section 5.5.4, “Type 3
Fonts”).
• All sampled images are defined in image space. The transformation from image
space to user space is predefined and cannot be changed. All images are 1 unit
wide by 1 unit high in user space, regardless of the number of samples in the
image. To be painted, an image is mapped to a region of the page by temporari-
ly altering the CTM.
Note: In PostScript, unlike PDF, the relationship between image space and user
space can be specified explicitly. The fixed transformation prescribed in PDF cor-
responds to the convention that is recommended for use in PostScript.
• A form XObject (discussed in Section 4.9, “Form XObjects”) is a self-contained
content stream that can be treated as a graphical element within another con-
tent stream. The space in which it is defined is called form space. The transfor-
mation from form space to user space is specified by a form matrix contained
in the form XObject.
• PDF 1.2 defines a type of color known as a pattern, discussed in Section 4.6,
“Patterns.” A pattern is defined either by a content stream that is invoked
repeatedly to tile an area or by a shading whose color is a function of position.
The space in which a pattern is defined is called pattern space. The transforma-
tion from pattern space to user space is specified by a pattern matrix contained
in the pattern.
• PDF 1.6 introduces embedded 3D artwork, which is described in three-dimen-
sional coordinates (see Section 9.5.4, “Coordinate Systems for 3D”) that are
204
CHAPTER 4
Graphics
projected into an annotation’s target coordinate system (see Section 9.5.1, “3D
Annotations”).
Relationships among Coordinate Spaces
Figure 4.4 shows the relationships among the coordinate spaces described above.
Each arrow in the figure represents a transformation from one coordinate space
to another. PDF allows modifications to many of these transformations.
Because PDF coordinate spaces are defined relative to one another, changes made
to one transformation can affect the appearance of objects defined in several
coordinate spaces. For example, a change in the CTM, which defines the trans-
formation from user space to device space, affects forms, text, images, and pat-
terns, since they are all upstream from user space.
4.2.2
Common Transformations
A transformation matrix specifies the relationship between two coordinate spac-
es. By modifying a transformation matrix, objects can be scaled, rotated, translat-
ed, or transformed in other ways.
Form
space
Glyph
Text
space
space
User
Device
space
space
Image
space
Pattern
space
FIGURE 4.4 Relationships among coordinate systems
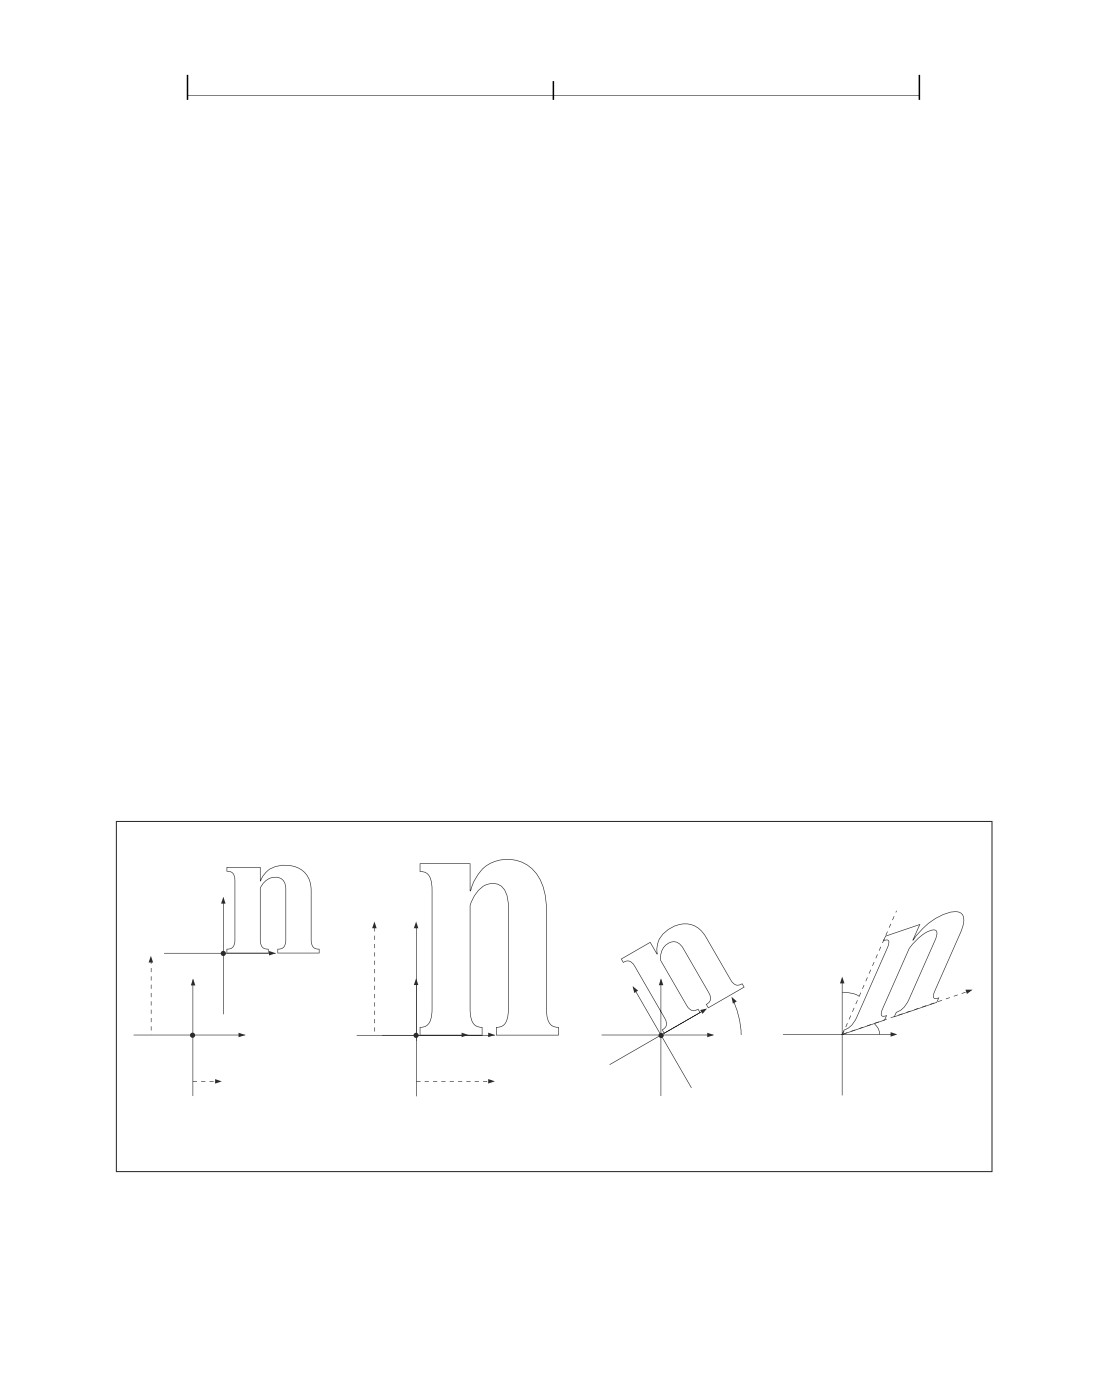
205
SECTION 4.2
Coordinate Systems
A transformation matrix in PDF is specified by six numbers, usually in the form
of an array containing six elements. In its most general form, this array is denoted
[ a b c d e f ]; it can represent any linear transformation from one coordinate
system to another. This section lists the arrays that specify the most common
transformations; Section 4.2.3, “Transformation Matrices,” discusses more math-
ematical details of transformations, including information on specifying transfor-
mations that are combinations of those listed here:
• Translations are specified as [ 1 0 0 1 tx ty ], where tx and ty are the distances
to translate the origin of the coordinate system in the horizontal and vertical
dimensions, respectively.
• Scaling is obtained by [ sx 0 0 sy 0 0 ]. This scales the coordinates so that 1
unit in the horizontal and vertical dimensions of the new coordinate system is
the same size as sx and sy units, respectively, in the previous coordinate system.
• Rotations are produced by [ cos θ sin θ −sin θ cos θ 0 0 ], which has the effect
of rotating the coordinate system axes by an angle θ counterclockwise.
• Skew is specified by [ 1 tan α tan β 1 0 0 ], which skews the x axis by an angle
α and the y axis by an angle β.
Figure 4.5 shows examples of each transformation. The directions of translation,
rotation, and skew shown in the figure correspond to positive values of the array
elements.
sy
b
ty
q
a
tx
sx
Translation
Scaling
Rotation
Skewing
FIGURE 4.5 Effects of coordinate transformations
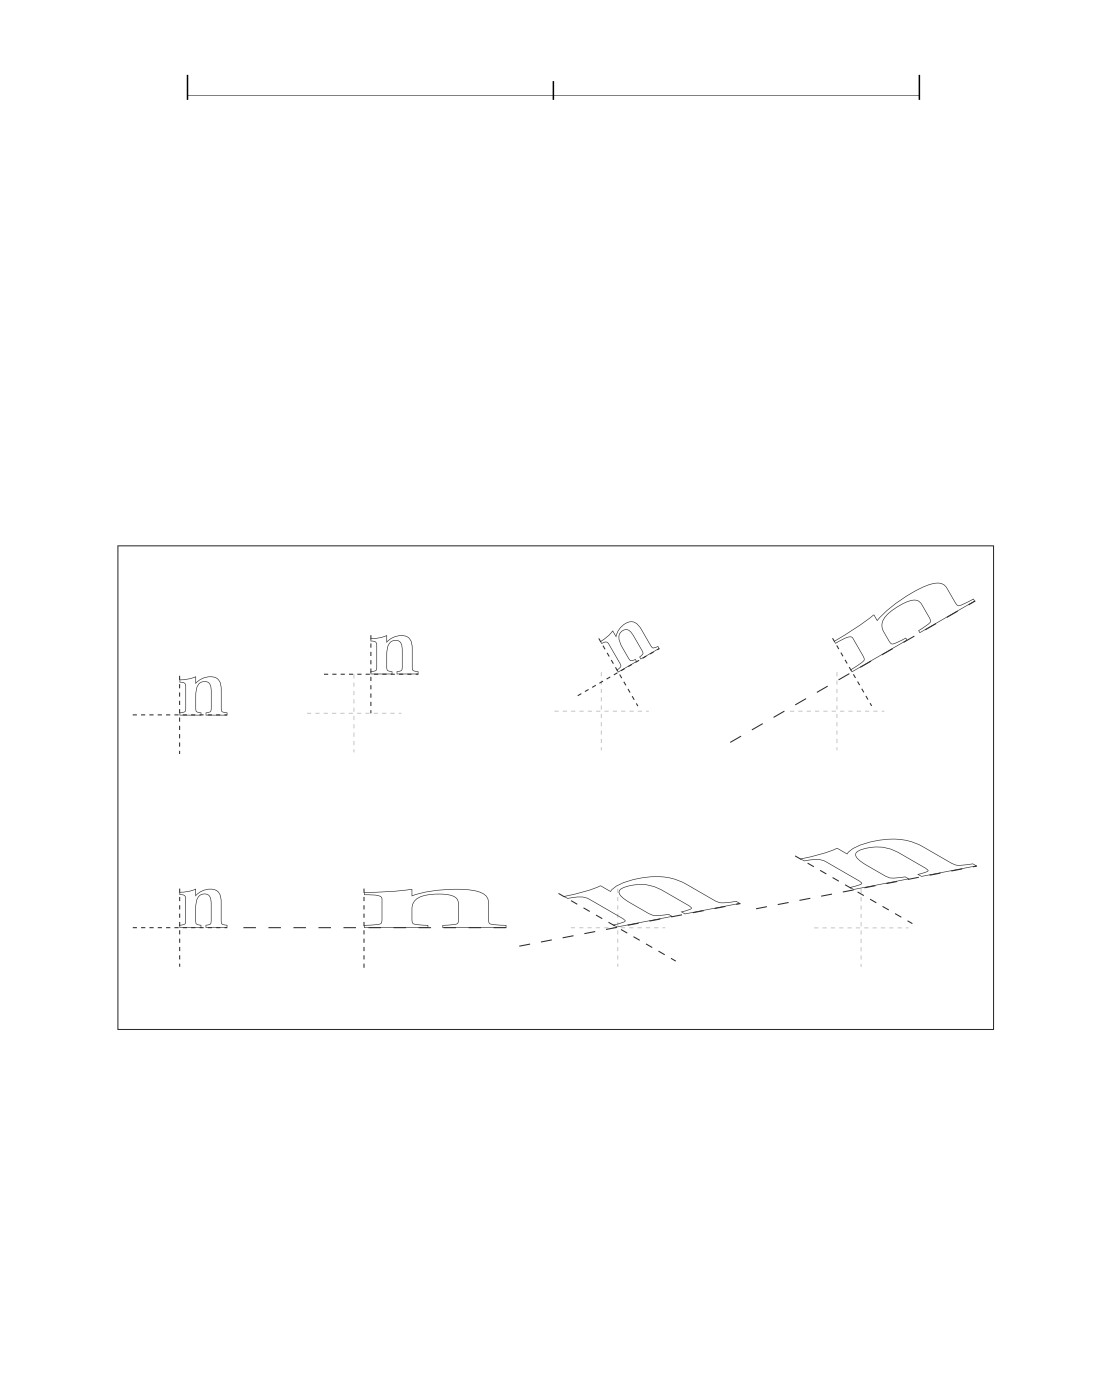
206
CHAPTER 4
Graphics
If several transformations are combined, the order in which they are applied is
significant. For example, first scaling and then translating the x axis is not the
same as first translating and then scaling it. In general, to obtain the expected
results, transformations should be done in the following order:
1. Translate
2. Rotate
3. Scale or skew
Figure 4.6 shows the effect of the order in which transformations are applied. The
figure shows two sequences of transformations applied to a coordinate system.
After each successive transformation, an outline of the letter n is drawn.
Original
Step 1: Translation
Step 2: Rotation
Step 3: Scaling
Original
Step 1: Scaling
Step 2: Rotation
Step 3: Translation
FIGURE 4.6 Effect of transformation order
207
SECTION 4.2
Coordinate Systems
The following transformations are shown in the figure:
• A translation of 10 units in the x direction and 20 units in the y direction
• A rotation of 30 degrees
• A scaling by a factor of 3 in the x direction
In the figure, the axes are shown with a dash pattern having a 2-unit dash and a
2-unit gap. In addition, the original (untransformed) axes are shown in a lighter
color for reference. Notice that the scale-rotate-translate ordering results in a
distortion of the coordinate system, leaving the x and y axes no longer perpendic-
ular; the recommended translate-rotate-scale ordering results in no distortion.
4.2.3
Transformation Matrices
This section discusses the mathematics of transformation matrices. It is not
necessary to read this section to use the transformations described previously;
the information is presented for the benefit of readers who want to gain a deeper
understanding of the theoretical basis of coordinate transformations.
To understand the mathematics of coordinate transformations in PDF, it is vital
to remember two points:
• Transformations alter coordinate systems, not graphics objects. All objects paint-
ed before a transformation is applied are unaffected by the transformation. Ob-
jects painted after the transformation is applied are interpreted in the
transformed coordinate system.
• Transformation matrices specify the transformation from the new (transformed)
coordinate system to the original (untransformed) coordinate system. All coor-
dinates used after the transformation are expressed in the transformed coordi-
nate system. PDF applies the transformation matrix to find the equivalent
coordinates in the untransformed coordinate system.
Note: Many computer graphics textbooks consider transformations of graphics ob-
jects rather than of coordinate systems. Although either approach is correct and self-
consistent, some details of the calculations differ depending on which point of view
is taken.
Большое спасибо!
Ваше мнение очень важно для нас.
Нет комментариевНе стесняйтесь поделиться с нами вашим ценным мнением.
Текст