PDF Reference sixth edition, Adobe Portable Document Format Version 1.7 (book 1) — page 4
126
CHAPTER 3
Syntax
Password Algorithms
In addition to the encryption key, the standard security handler must provide the
contents of the encryption dictionary (Table 3.18 on page 116 and Table 3.19 on
page 122). The values of the Filter, V, Length, R, and P entries are straightforward,
but the computation of the O (owner password) and U (user password) entries
requires further explanation. Algorithms 3.3 through 3.5 show how the values of
the owner password and user password entries are computed (with separate
versions of the latter depending on the revision of the security handler).
Algorithm 3.3 Computing the encryption dictionary’s O (owner password) value
1.
Pad or truncate the owner password string as described in step 1 of Algorithm 3.2.
If there is no owner password, use the user password instead. (See implementation
note 27 in Appendix H.)
2.
Initialize the MD5 hash function and pass the result of step 1 as input to this function.
3.
(Revision 3 or greater) Do the following 50 times: Take the output from the previ-
ous MD5 hash and pass it as input into a new MD5 hash.
4.
Create an RC4 encryption key using the first n bytes of the output from the final
MD5 hash, where n is always 5 for revision 2 but, for revision 3 or greater, depends
on the value of the encryption dictionary’s Length entry.
5.
Pad or truncate the user password string as described in step 1 of Algorithm 3.2.
6.
Encrypt the result of step 5, using an RC4 encryption function with the encryp-
tion key obtained in step 4.
7.
(Revision 3 or greater) Do the following 19 times: Take the output from the previ-
ous invocation of the RC4 function and pass it as input to a new invocation of the
function; use an encryption key generated by taking each byte of the encryption
key obtained in step 4 and performing an XOR (exclusive or) operation between
that byte and the single-byte value of the iteration counter (from 1 to 19).
8.
Store the output from the final invocation of the RC4 function as the value of the
O entry in the encryption dictionary.
Algorithm 3.4 Computing the encryption dictionary’s U (user password) value (Revision 2)
1.
Create an encryption key based on the user password string, as described in Algo-
rithm 3.2.
2.
Encrypt the 32-byte padding string shown in step 1 of Algorithm 3.2, using an
RC4 encryption function with the encryption key from the preceding step.
3.
Store the result of step 2 as the value of the U entry in the encryption dictionary.
127
SECTION 3.5
Encryption
Algorithm 3.5 Computing the encryption dictionary’s U (user password) value (Revision 3
or greater)
1.
Create an encryption key based on the user password string, as described in Algo-
rithm 3.2.
2.
Initialize the MD5 hash function and pass the 32-byte padding string shown in
step 1 of Algorithm 3.2 as input to this function.
3.
Pass the first element of the file’s file identifier array (the value of the ID entry in
the document’s trailer dictionary; see Table 3.13 on page 97) to the hash function
and finish the hash. (See implementation note 26 in Appendix H.)
4.
Encrypt the 16-byte result of the hash, using an RC4 encryption function with the
encryption key from step 1.
5.
Do the following 19 times: Take the output from the previous invocation of the
RC4 function and pass it as input to a new invocation of the function; use an en-
cryption key generated by taking each byte of the original encryption key (ob-
tained in step 1) and performing an XOR (exclusive or) operation between that
byte and the single-byte value of the iteration counter (from 1 to 19).
6.
Append 16 bytes of arbitrary padding to the output from the final invocation of
the RC4 function and store the 32-byte result as the value of the U entry in the en-
cryption dictionary.
The standard security handler uses Algorithms 3.6 and 3.7 to determine whether
a supplied password string is the correct user or owner password. Note too that
Algorithm 3.6 can be used to determine whether a document’s user password is
the empty string, and therefore whether to suppress prompting for a password
when the document is opened.
Algorithm 3.6 Authenticating the user password
1.
Perform all but the last step of Algorithm 3.4 (Revision 2) or Algorithm 3.5 (Revi-
sion 3 or greater) using the supplied password string.
2.
If the result of step 1 is equal to the value of the encryption dictionary’s U entry
(comparing on the first 16 bytes in the case of Revision 3 or greater), the password
supplied is the correct user password. The key obtained in step 1 (that is, in the
first step of Algorithm 3.4 or 3.5) can be used to decrypt the document using Al-
gorithm 3.1 on page 119.
128
CHAPTER 3
Syntax
Algorithm 3.7 Authenticating the owner password
1.
Compute an encryption key from the supplied password string, as described in
steps 1 to 4 of Algorithm 3.3.
2.
(Revision 2 only) Decrypt the value of the encryption dictionary’s O entry, using
an RC4 encryption function with the encryption key computed in step 1.
(Revision 3 or greater) Do the following 20 times: Decrypt the value of the encryp-
tion dictionary’s O entry (first iteration) or the output from the previous iteration
(all subsequent iterations), using an RC4 encryption function with a different en-
cryption key at each iteration. The key is generated by taking the original key (ob-
tained in step 1) and performing an XOR (exclusive or) operation between each
byte of the key and the single-byte value of the iteration counter (from 19 to 0).
3.
The result of step 2 purports to be the user password. Authenticate this user pass-
word using Algorithm 3.6. If it is correct, the password supplied is the correct
owner password.
3.5.3
Public-Key Security Handlers
Security handlers may use public-key encryption technology to encrypt a
document (or strings and streams within a document). When doing so, it is
possible to specify one or more lists of recipients, where each list has its own
unique access permissions. Only specified recipients can open the encrypted
document or content, unlike the standard security handler, where a password
determines access. The permissions defined for public-key security handlers are
identical to those defined for the standard security handler (see Section 3.5.2,
“Standard Security Handler”).
Public-key security handlers use the industry standard Public Key Cryptographic
Standard Number 7 (PKCS#7) binary encoding syntax to encode recipient list,
decryption key, and access permission information. The PKCS#7 specification is
in Internet RFC 2315, PKCS #7: Cryptographic Message Syntax, Version 1.5 (see
the Bibliography).
When encrypting the data, each recipient’s X.509 public key certificate (as
described in ITU-T Recommendation X.509; see the Bibliography) must be
available. When decrypting the data, the application scans the recipient list for
which the content is encrypted and attempts to find a match with a certificate that
belongs to the user. If a match is found, the user requires access to the
corresponding private key, which may require authentication, possibly using a
password. Once access is obtained, the private key is used to decrypt the
encrypted data.
129
SECTION 3.5
Encryption
Public-Key Encryption Dictionary
Encryption dictionaries for public-key security handlers contain the common
entries shown in Table 3.18, whose values are described below. In addition, they
may contain the entry shown in Table 3.21.
The Filter entry is the name of a public-key security handler. Examples of existing
security handlers that support public-key encryption are Entrust.PPKEF,
Adobe.PPKLite, and Adobe.PubSec. This handler will be the preferred handler
when encrypting the document.
Permitted values of the SubFilter entry for use with conforming public-key
security handlers are adbe.pkcs7.s3, adbe.pkcs7.s4, which are used when not
using crypt filters (see Section 3.5.4, “Crypt Filters”) and adbe.pkcs7.s5, which is
used when using crypt filters.
The CF, StmF, and StrF entries may be present when SubFilter is adbe.pkcs7.s5.
TABLE 3.21 Additional encryption dictionary entries for public-key security handlers
KEY
TYPE
VALUE
Recipients
array
(Required when SubFilter is adbe.pkcs7.s3 or adbe.pkcs7.s4; PDF 1.3) An array of
byte-strings, where each string is a PKCS#7 object listing recipients who have been
granted equal access rights to the document. The data contained in the PKCS#7 ob-
ject includes both a cryptographic key that is used to decrypt the encrypted data
and the access permissions (see Table 3.20) that apply to the recipient list. There
should be only one PKCS#7 object per unique set of access permissions; if a recipi-
ent appears in more than one list, the permissions used are those in the first match-
ing list.
Note: When SubFilter is adbe.pkcs7.s5, recipient lists are specified in the crypt filter
dictionary; see Table 3.24.
130
CHAPTER 3
Syntax
Public-Key Encryption Algorithms
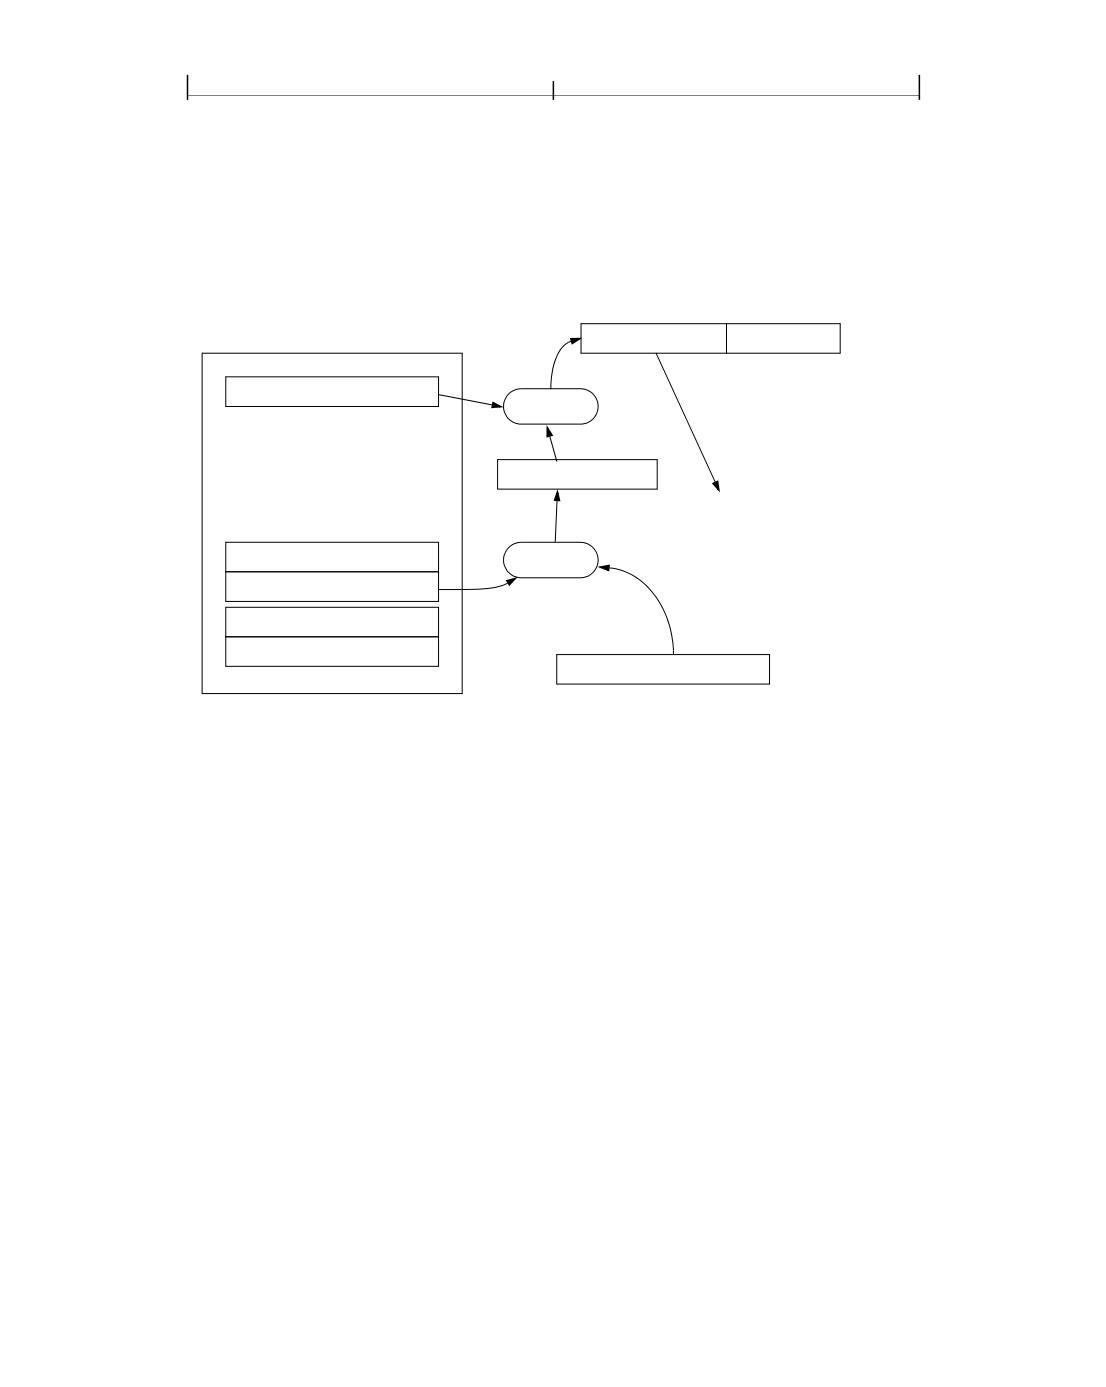
Figure 3.4 illustrates how PKCS#7 objects are used when encrypting PDF files. A
PKCS#7 object is designed to encapsulate and encrypt what is referred to as the
enveloped data.
Plaintext byte array
PKCS#7 Object
20-byte seed
Permissions*
* Permissions not present
when PKCS#7 object is ref-
Enveloped data
erenced from Crypt filter
Decrypt
decode parameter dictio-
nary
Plaintext key
Used to generate
encryption key as
described on page
John Doe
Decrypt
131
Encrypted key
Jeff Smith
Encrypted key
John Doe’s private key
FIGURE 3.4 Public-key encryption algorithm
The enveloped data in the PKCS#7 object contains keying material that must be
used to decrypt the document (or individual strings or streams in the document,
when crypt filters are used; see Section 3.5.4, “Crypt Filters”). A key is used to
encrypt (and decrypt) the enveloped data. This key (the plaintext key in Figure
3.4) is encrypted for each recipient, using that recipient’s public key, and is stored
in the PKCS#7 object (as the encrypted key for each recipient). To decrypt the
document, that key is decrypted using the recipient’s private key, which yields a
decrypted (plaintext) key. That key, in turn, is used to decrypt the enveloped data
in the PKCS#7 object, resulting in a byte array that includes the following
information:
• A 20-byte seed that is used to create the encryption key that is used by Algo-
rithm 3.1. The seed should be a unique random number generated by the secu-
rity handler that encrypted the document.
• A 4-byte value defining the permissions, least significant byte first. See
Table 3.20 for the possible permission values.
131
SECTION 3.5
Encryption
• When SubFilter is adbe.pkcs7.s3, the relevant permissions are restricted to
those specified for revision 2 of the standard security handler.
• For adbe.pkcs7.s4, revision 3 permissions apply.
• For adbe.pkcs7.s5, which supports the use of crypt filters, the permissions
are the same as adbe.pkcs7.s4 when the crypt filter is referenced from the
StmF or StrF entries of the encryption dictionary. When referenced from the
Crypt filter decode parameter dictionary of a stream object (see Table 3.12),
the 4 bytes of permissions are absent from the enveloped data.
The algorithms that may be used to encrypt the enveloped data in the PKCS#7
object are: RC4 with key lengths up to 256-bits, DES, Triple DES, RC2 with key
lengths up to 128 bits, 128-bit AES in Cipher Block Chaining (CBC) mode, 192-
bit AES in CBC mode, 256-bit AES in CBC mode. Acrobat products have used
Triple DES to encrypt the enveloped data, and support all of these listed
algorithms when decrypting the enveloped data. The PKCS#7 specification is in
Internet RFC 2315, PKCS #7: Cryptographic Message Syntax, Version 1.5 (see the
Bibliography).
The encryption key that is used by Algorithm 3.1 is calculated by means of an
SHA-1 message digest operation that digests the following data, in order:
1. The 20 bytes of seed
2. The bytes of each item in the Recipients array of PKCS#7 objects in the order
in which they appear in the array
3. 4 bytes with the value 0xFF if the key being generated is intended for use in
document-level encryption and the document metadata is being left as plain-
text
The first n/8 bytes of the resulting digest is used as the encryption key, where n is
the bit length of the RC4 key.
3.5.4
Crypt Filters
PDF 1.5 introduces crypt filters, which provide finer granularity control of
encryption within a PDF file. The use of crypt filters involves the following
structures:
• The encryption dictionary (see Table 3.18) contains entries that enumerate the
crypt filters in the document (CF) and specify which ones are used by default to
132
CHAPTER 3
Syntax
decrypt all the streams (StmF) and strings (StrF) in the document. In addition,
the value of the V entry must be 4 to use crypt filters.
• Each crypt filter specified in the CF entry of the encryption dictionary is repre-
sented by a crypt filter dictionary, whose entries are shown in Table 3.22.
• A stream filter type, the Crypt filter (see Section 3.3.9, “Crypt Filter”) can be
specified for any stream in the document to override the default filter for
streams. A standard Identity filter is provided (see Table 3.23) to allow specific
streams, such as document metadata, to be unencrypted in an otherwise en-
crypted document. The stream’s DecodeParms entry must contain a Crypt filter
decode parameters dictionary (see Table 3.12) whose Name entry specifies the
particular crypt filter to be used (if missing, Identity is used). Different streams
may specify different crypt filters; however, see implementation notes 28 and
29 in Appendix H.
Authorization to decrypt a stream must always be obtained before the stream can
be accessed. This typically occurs when the document is opened, as specified by a
value of DocOpen for the AuthEvent entry in the crypt filter dictionary. PDF
consumer applications and security handlers should treat any attempt to access a
stream for which authorization has failed as an error. AuthEvent may also be
EFOpen, which indicates the presence of an embedded file that is encrypted with
a crypt filter that may be different from the crypt filters used by default to encrypt
strings and streams in the document; see implementation note 31 in Appendix H.
By specifying a value of None for the CFM entry in the crypt filter dictionary, the
security handler can do its own decryption. This allows the handler to tightly
control key management and use any preferred symmetric-key cryptographic
algorithm.
TABLE 3.22 Entries common to all crypt filter dictionaries
KEY
TYPE
VALUE
Type
name
(Optional) If present, must be CryptFilter for a crypt filter dictionary.
133
SECTION 3.5
Encryption
KEY
TYPE
VALUE
CFM
name
(Optional) The method used, if any, by the consumer application to decrypt
data. The following values are supported:
None The application does not decrypt data but directs the input stream
to the security handler for decryption. (See implementation note
30 in Appendix H.)
V2
The application asks the security handler for the encryption key
and implicitly decrypts data with Algorithm 3.1, using the RC4 al-
gorithm.
AESV2
(PDF 1.6) The application asks the security handler for the en-
cryption key and implicitly decrypts data with Algorithm 3.1, us-
ing the AES algorithm in Cipher Block Chaining (CBC) mode
with a 16-byte block size and an initialization vector that is ran-
domly generated and placed as the first 16 bytes in the stream or
string.
When the value is V2 or AESV2, the application may ask once for this encryp-
tion key and cache the key for subsequent use for streams that use the same
crypt filter. Therefore, there must be a one-to-one relationship between a
crypt filter name and the corresponding encryption key.
Only the values listed here are supported. Applications that encounter other
values should report that the file is encrypted with an unsupported algo-
rithm.
Default value: None.
AuthEvent
name
(Optional) The event to be used to trigger the authorization that is required
to access encryption keys used by this filter. If authorization fails, the event
should fail. Valid values are:
• DocOpen: Authorization is required when a document is opened.
• EFOpen: Authorization is required when accessing embedded files.
Default value: DocOpen.
If this filter is used as the value of StrF or StmF in the encryption dictionary
(see Table 3.18), the application should ignore this key and behave as if the
value is DocOpen.
134
CHAPTER 3
Syntax
KEY
TYPE
VALUE
Length
integer
(Optional) The bit length of the encryption key. It must be a multiple of 8 in
the range of 40 to 128.
Note: Security handlers can define their own use of the Length entry but are en-
couraged to use it to define the bit length of the encryption key.
Security handlers can add their own private data to crypt filter dictionaries.
Names for private data entries must conform to the PDF name registry (see
Appendix E, “PDF Name Registry”).
TABLE 3.23 Standard crypt filter names
NAME
DESCRIPTION
Identity
Input data is passed through without any processing.
Table 3.24 lists the additional crypt filter dictionary entries used by public-key
security handlers (see Section 3.5.3, “Public-Key Security Handlers”). When
these entries are present, the value of CFM must be V2 or AESV2.
TABLE 3.24 Additional crypt filter dictionary entries for public-key security handlers
KEY
TYPE
VALUE
Recipients
array or
(Required) If the crypt filter is referenced from StmF or StrF in the encryption
string
dictionary, this entry is an array of byte strings, where each string is a binary-
encoded PKCS#7 object listing recipients that have been granted equal access
rights to the document. The enveloped data contained in the PKCS#7 object
includes both a 20-byte seed value used to compute the encryption key (see
“Public-Key Encryption Algorithms” on page 130) followed by 4 bytes of per-
missions settings (see Table 3.20) that apply to the recipient list. There should
be only one object per unique set of access permissions. If a recipient appears
in more than one list, the permissions used are those in the first matching list.
If the crypt filter is referenced from a Crypt filter decode parameter dictio-
nary (see Table 3.12), this entry is a string that is a binary-encoded PKCS#7
object containing a list of all recipients who are permitted to access the corre-
sponding encrypted stream. The enveloped data contained in the PKCS#7
object is a 20-byte seed value used to create the encryption key that is used by
Algorithm 3.1.
135
SECTION 3.5
Encryption
KEY
TYPE
VALUE
EncryptMetadata
boolean
(Optional; used only by crypt filters that are referenced from StmF in an encryp-
tion dictionary) Indicates whether the document-level metadata stream (see
Section 10.2.2, “Metadata Streams”) is to be encrypted. PDF consumer appli-
cations should respect this value when determining whether metadata should
be encrypted; see implementation note 32 in Appendix H.
Default value: true.
Example 3.12 shows the use of crypt filters in an encrypted document containing
a plaintext document-level metadata stream. The metadata stream is left as is by
applying the Identity crypt filter. The remaining
streams
and
strings
are
decrypted using the default filters.
Example 3.12
%PDF1.5
1 0 obj
% Document catalog
<< /Type /Catalog
/Pages 2 0 R
/Metadata 6 0 R
>>
endobj
2 0 obj
% Page tree
<< /Type /Pages
/Kids [3 0 R]
/Count 1
>>
endobj
3 0 obj
% 1s t page
<< /Type /Page
/Parent 2 0 R
/MediaBox [0 0 612 792]
/Contents 4 0 R
>>
endobj
4 0 obj
% Page contents
<< /Length 35 >>
stream
*** Encrypted Page-marking operators ***
endstream
endobj
136
CHAPTER 3
Syntax
5 0 obj
<< /Title ($#*#%*$#^&##) >> % Info dictionary: encrypted text string
endobj
6 0 obj
<< /Type /Metadata
/Subtype /XML
/Length 15
/Filter [/Crypt]
% Uses a crypt filter
/DecodeParms
% with these parameters
<< /Type /CryptFilterDecodeParms
/Name /Identity
% Indicates no encryption
>>
>>
stream
XML metadata
% Unencrypted metadata
endstream
endobj
8 0 obj
% Encryption dictionary
<< /Filter /MySecurityHandlerName
/V 4
% Version 4: allow crypt filters
/CF
% List of crypt filters
<< /MyFilter0
<< /Type /CryptFilter
/CFM V2 >>
% Uses the standard algorithm
>>
/StrF /MyFilter0
% Strings are decrypted using /MyFilter0
/StmF /MyFilter0
% Streams are decrypted using /MyFilter0
% Private data for /MySecurityHandlerName
/MyUnsecureKey (12345678)
/EncryptMetadata false
>>
endobj
xref
trailer
<< /Size 8
/Root 1 0 R
/Info 5 0 R
/Encrypt 8 0 R
>>
startxref
495
%%EOF
137
SECTION 3.6
Document Structure
3.6
Document Structure
A PDF document can be regarded as a hierarchy of objects contained in the
body section of a PDF file. At the root of the hierarchy is the document’s catalog
dictionary (see Section 3.6.1, “Document Catalog”). Most of the objects in the
hierarchy are dictionaries. For example, each page of the document is
represented by a page object—a dictionary that includes references to the page’s
contents and other attributes, such as its thumbnail image
(Section
8.2.3,
“Thumbnail Images”) and any annotations
(Section
8.4,
“Annotations”)
associated with it. The individual page objects are tied together in a structure
called the page tree (described in Section 3.6.2, “Page Tree”), which in turn is
specified by an indirect reference in the document catalog. Parent, child, and
sibling relationships within the hierarchy are defined by dictionary entries whose
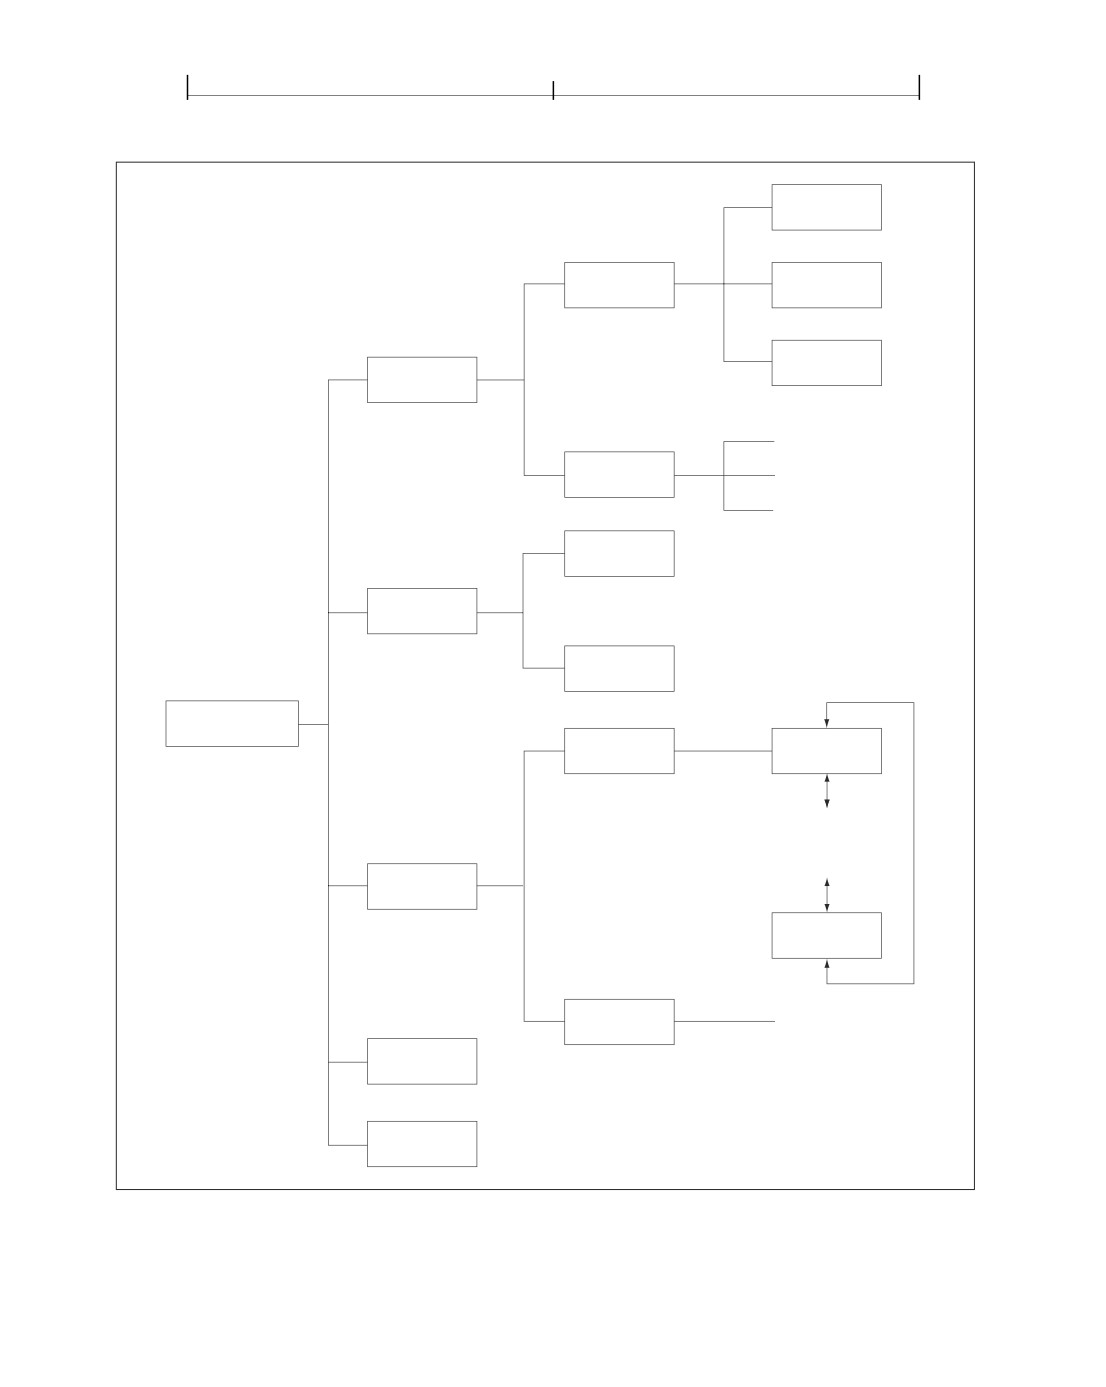
values are indirect references to other dictionaries. Figure 3.5 illustrates the
structure of the object hierarchy.
Note: The data structures described in this section, particularly the catalog and page
dictionaries, combine entries describing document structure with ones dealing with
the detailed semantics of documents and pages. All entries are listed here, but many
of their descriptions are deferred to subsequent chapters.
3.6.1
Document Catalog
The root of a document’s object hierarchy is the catalog dictionary, located by
means of the Root entry in the trailer of the PDF file (see Section 3.4.4, “File
Trailer”). The catalog contains references to other objects defining the
document’s contents, outline, article threads (PDF 1.1), named destinations, and
other attributes. In addition, it contains information about how the document
should be displayed on the screen, such as whether its outline and thumbnail
page images should be displayed automatically and whether some location other
than the first page should be shown when the document is opened. Table 3.25
shows the entries in the catalog dictionary.
138
CHAPTER 3
Syntax
Content
stream
Thumbnail
Page
image
•
Annotations
Page
tree
•
•
•
•
•
Page
•
•
•
•
•
•
Outline
entry
•
Outline
hierarchy
•
•
Outline
entry
Document catalog
Thread
Bead
•
•
•
•
Article
threads
•
•
Bead
Thread
•
•
•
Named
destinations
Interactive
form
FIGURE 3.5 Structure of a PDF document
139
SECTION 3.6
Document Structure
TABLE 3.25 Entries in the catalog dictionary
KEY
TYPE
VALUE
Type
name
(Required) The type of PDF object that this dictionary describes; must
be Catalog for the catalog dictionary.
Version
name
(Optional; PDF 1.4) The version of the PDF specification to which the
document conforms (for example, 1.4) if later than the version specified
in the file’s header (see Section 3.4.1, “File Header”). If the header speci-
fies a later version, or if this entry is absent, the document conforms to
the version specified in the header. This entry enables a PDF producer
application to update the version using an incremental update; see Sec-
tion 3.4.5, “Incremental Updates.” (See implementation note 33 in Ap-
pendix H.)
Note: The value of this entry is a name object, not a number, and therefore
must be preceded by a slash character (/) when written in the PDF file (for
example, /1.4).
Pages
dictionary
(Required; must be an indirect reference) The page tree node that is the
root of the document’s page tree (see Section 3.6.2, “Page Tree”).
PageLabels
number tree
(Optional; PDF 1.3) A number tree (see Section 3.8.6, “Number Trees”)
defining the page labeling for the document. The keys in this tree are
page indices; the corresponding values are page label dictionaries (see
Section 8.3.1, “Page Labels”). Each page index denotes the first page in a
labeling range to which the specified page label dictionary applies. The
tree must include a value for page index 0.
Names
dictionary
(Optional; PDF 1.2) The document’s name dictionary (see Section 3.6.3,
“Name Dictionary”).
Dests
dictionary
(Optional; PDF 1.1; must be an indirect reference) A dictionary of names
and corresponding destinations (see “Named Destinations” on page
583).
ViewerPreferences
dictionary
(Optional; PDF 1.2) A viewer preferences dictionary (see Section 8.1,
“Viewer Preferences”) specifying the way the document is to be dis-
played on the screen. If this entry is absent, applications should use their
own current user preference settings.
140
CHAPTER 3
Syntax
KEY
TYPE
VALUE
PageLayout
name
(Optional) A name object specifying the page layout to be used when the
document is opened:
SinglePage
Display one page at a time
OneColumn
Display the pages in one column
TwoColumnLeft
Display the pages in two columns, with odd-
numbered pages on the left
TwoColumnRight Display the pages in two columns, with odd-
numbered pages on the right
TwoPageLeft
(PDF 1.5) Display the pages two at a time, with
odd-numbered pages on the left
TwoPageRight
(PDF 1.5) Display the pages two at a time, with
odd-numbered pages on the right
Default value: SinglePage.
PageMode
name
(Optional) A name object specifying how the document should be dis-
played when opened:
UseNone
Neither document outline nor thumbnail im-
ages visible
UseOutlines
Document outline visible
UseThumbs
Thumbnail images visible
FullScreen
Full-screen mode, with no menu bar, window
controls, or any other window visible
UseOC
(PDF 1.5) Optional content group panel visible
UseAttachments
(PDF 1.6) Attachments panel visible
Default value: UseNone.
Outlines
dictionary
(Optional; must be an indirect reference) The outline dictionary that is
the root of the document’s outline hierarchy (see Section 8.2.2, “Docu-
ment Outline”).
Threads
array
(Optional; PDF 1.1; must be an indirect reference) An array of thread
dictionaries representing the document’s article threads (see Section
8.3.2, “Articles”).
OpenAction
array or
(Optional; PDF 1.1) A value specifying a destination to be displayed or
dictionary
an action to be performed when the document is opened. The value is
either an array defining a destination (see Section 8.2.1, “Destinations”)
or an action dictionary representing an action (Section 8.5, “Actions”). If
this entry is absent, the document should be opened to the top of the
first page at the default magnification factor.
141
SECTION 3.6
Document Structure
KEY
TYPE
VALUE
AA
dictionary
(Optional; PDF 1.4) An additional-actions dictionary defining the ac-
tions to be taken in response to various trigger events affecting the docu-
ment as a whole
(see
“Trigger Events” on page
648).
(See also
implementation note 34 in Appendix H.)
URI
dictionary
(Optional; PDF 1.1) A URI dictionary containing document-level infor-
mation for URI (uniform resource identifier) actions (see “URI Actions”
on page 662).
AcroForm
dictionary
(Optional; PDF 1.2) The document’s interactive form (AcroForm) dictio-
nary (see Section 8.6.1, “Interactive Form Dictionary”).
Metadata
stream
(Optional; PDF 1.4; must be an indirect reference) A metadata stream
containing metadata for the document (see Section 10.2.2, “Metadata
Streams”).
StructTreeRoot
dictionary
(Optional; PDF 1.3) The document’s structure tree root dictionary (see
Section 10.6.1, “Structure Hierarchy”).
MarkInfo
dictionary
(Optional; PDF 1.4) A mark information dictionary containing informa-
tion about the document’s usage of Tagged PDF conventions (see Sec-
tion 10.6, “Logical Structure”).
Lang
text string
(Optional; PDF 1.4) A language identifier specifying the natural language
for all text in the document except where overridden by language speci-
fications for structure elements or marked content (see Section 10.8.1,
“Natural Language Specification”). If this entry is absent, the language is
considered unknown.
SpiderInfo
dictionary
(Optional; PDF 1.3) A Web Capture information dictionary containing
state information used by the Acrobat Web Capture (AcroSpider) plug-
in extension (see Section 10.9.1, “Web Capture Information Dictio-
nary”).
OutputIntents
array
(Optional; PDF 1.4) An array of output intent dictionaries describing the
color characteristics of output devices on which the document might be
rendered (see “Output Intents” on page 970).
PieceInfo
dictionary
(Optional; PDF 1.4) A page-piece dictionary associated with the docu-
ment (see Section 10.4, “Page-Piece Dictionaries”).
OCProperties
dictionary
(Optional; PDF 1.5; required if a document contains optional content) The
document’s optional content properties dictionary (see Section 4.10.3,
“Configuring Optional Content”).
142
CHAPTER 3
Syntax
KEY
TYPE
VALUE
Perms
dictionary
(Optional; PDF 1.5) A permissions dictionary that specifies user access
permissions for the document. Section 8.7.3, “Permissions,” describes
this dictionary and how it is used.
Legal
dictionary
(Optional; PDF 1.5) A dictionary containing attestations regarding the
content of a PDF document, as it relates to the legality of digital signa-
tures (see Section 8.7.4, “Legal Content Attestations”).
Requirements
array
(Optional; PDF 1.7) An array of requirement dictionaries representing
requirements for the document. Section 8.9, “Document Requirements,”
describes this dictionary and how to use it.
Collection
dictionary
(Optional; PDF 1.7) A collection dictionary that a PDF consumer uses to
enhance the presentation of file attachments stored in the PDF docu-
ment. (see Section 8.2.4, “Collections”).
NeedsRendering
boolean
(Optional; PDF 1.7) A flag used to expedite the display of PDF docu-
ments containing XFA forms. It specifies whether the document must be
regenerated when the document is first opened.
If true, the viewer application treats the document as a shell and regener-
ates the content when the document is opened, regardless of any dynam-
ic forms settings that appear in the XFA stream itself. This setting is used
to expedite the display of documents whose layout varies depending on
the content of the XFA streams.
If false, the viewer application does not regenerate the content when the
document is opened. See the XML Forms Architecture (XFA) Specifica-
tion (Bibliography).
Default value: false.
Example 3.13 shows a sample catalog object.
Example 3.13
1 0 obj
<< /Type /Catalog
/Pages 2 0 R
/PageMode /UseOutlines
/Outlines 3 0 R
>>
endobj
143
SECTION 3.6
Document Structure
3.6.2
Page Tree
The pages of a document are accessed through a structure known as the page tree,
which defines the ordering of pages in the document. The tree structure allows
PDF consumer applications, using only limited memory, to quickly open a
document containing thousands of pages. The tree contains nodes of two types—
intermediate nodes, called page tree nodes, and leaf nodes, called page objects—
whose form is described in the sections below. Applications should be prepared
to handle any form of tree structure built of such nodes. The simplest structure
would consist of a single page tree node that references all of the document’s page
objects directly. However, to optimize application performance, the Acrobat
Distiller program constructs trees of a particular form, known as balanced trees.
Further information on this form of tree can be found in Data Structures and
Algorithms, by Aho, Hopcroft, and Ullman (see the Bibliography).
Page Tree Nodes
Table 3.26 shows the required entries in a page tree node.
TABLE 3.26 Required entries in a page tree node
KEY
TYPE
VALUE
Type
name
(Required) The type of PDF object that this dictionary describes; must be Pages for
a page tree node.
Parent
dictionary
(Required except in root node; must be an indirect reference) The page tree node that
is the immediate parent of this one.
Kids
array
(Required) An array of indirect references to the immediate children of this node.
The children may be page objects or other page tree nodes.
Count
integer
(Required) The number of leaf nodes (page objects) that are descendants of this
node within the page tree.
Note: The structure of the page tree is not necessarily related to the logical structure
of the document; that is, page tree nodes do not represent chapters, sections, and so
forth. (Other data structures are defined for that purpose; see Section 10.6, “Logical
Structure.”) Applications that consume or produce PDF files are not required to pre-
serve the existing structure of the page tree.
144
CHAPTER 3
Syntax
Example 3.14 illustrates the page tree for a document with three pages. See “Page
Objects,” below, for the contents of the individual page objects, and Section G.4,
“Page Tree Example,” for a more extended example showing the page tree for a
longer document.
Example 3.14
2 0 obj
<< /Type /Pages
/Kids
[
4 0 R
10 0 R
24 0 R
]
/Count 3
>>
endobj
4 0 obj
<< /Type /Page
… Additional entries describing the attributes of this page…
>>
endobj
10 0 obj
<< /Type /Page
… Additional entries describing the attributes of this page…
>>
endobj
24 0 obj
<< /Type /Page
… Additional entries describing the attributes of this page…
>>
endobj
In addition to the entries shown in Table 3.26, a page tree node may contain
further entries defining inherited attributes for the page objects that are its
descendants (see “Inheritance of Page Attributes” on page 149).
Page Objects
The leaves of the page tree are page objects, each of which is a dictionary
specifying the attributes of a single page of the document. Table 3.27 shows the
contents of this dictionary (see also implementation note 35 in Appendix H). The
145
SECTION 3.6
Document Structure
table also identifies which attributes a page may inherit from its ancestor nodes in
the page tree, as described under “Inheritance of Page Attributes” on page 149.
Attributes that are not explicitly identified in the table as inheritable cannot be
inherited.
TABLE 3.27 Entries in a page object
KEY
TYPE
VALUE
Type
name
(Required) The type of PDF object that this dictionary describes; must be
Page for a page object.
Parent
dictionary
(Required; must be an indirect reference) The page tree node that is the im-
mediate parent of this page object.
LastModified
date
(Required if PieceInfo is present; optional otherwise; PDF 1.3) The date and
time (see Section 3.8.3, “Dates”) when the page’s contents were most re-
cently modified. If a page-piece dictionary (PieceInfo) is present, the
modification date is used to ascertain which of the application data dictio-
naries that it contains correspond to the current content of the page (see
Section 10.4, “Page-Piece Dictionaries”).
Resources
dictionary
(Required; inheritable) A dictionary containing any resources required by
the page (see Section 3.7.2, “Resource Dictionaries”). If the page requires
no resources, the value of this entry should be an empty dictionary. Omit-
ting the entry entirely indicates that the resources are to be inherited from
an ancestor node in the page tree.
MediaBox
rectangle
(Required; inheritable) A rectangle (see Section 3.8.4, “Rectangles”), ex-
pressed in default user space units, defining the boundaries of the physical
medium on which the page is intended to be displayed or printed (see
Section 10.10.1, “Page Boundaries”).
CropBox
rectangle
(Optional; inheritable) A rectangle, expressed in default user space units,
defining the visible region of default user space. When the page is dis-
played or printed, its contents are to be clipped (cropped) to this rectangle
and then imposed on the output medium in some implementation-
defined manner (see Section 10.10.1, “Page Boundaries”). Default value:
the value of MediaBox.
BleedBox
rectangle
(Optional; PDF 1.3) A rectangle, expressed in default user space units, de-
fining the region to which the contents of the page should be clipped
when output in a production environment (see Section 10.10.1, “Page
Boundaries”). Default value: the value of CropBox.
146
CHAPTER 3
Syntax
KEY
TYPE
VALUE
TrimBox
rectangle
(Optional; PDF 1.3) A rectangle, expressed in default user space units, de-
fining the intended dimensions of the finished page after trimming (see
Section 10.10.1, “Page Boundaries”). Default value: the value of CropBox.
ArtBox
rectangle
(Optional; PDF 1.3) A rectangle, expressed in default user space units, de-
fining the extent of the page’s meaningful content (including potential
white space) as intended by the page’s creator (see Section 10.10.1, “Page
Boundaries”). Default value: the value of CropBox.
BoxColorInfo
dictionary
(Optional; PDF 1.4) A box color information dictionary specifying the col-
ors and other visual characteristics to be used in displaying guidelines on
the screen for the various page boundaries (see “Display of Page Bound-
aries” on page 965). If this entry is absent, the application should use its
own current default settings.
Contents
stream or array
(Optional) A content stream (see Section 3.7.1, “Content Streams”) de-
scribing the contents of this page. If this entry is absent, the page is empty.
The value may be either a single stream or an array of streams. If the value
is an array, the effect is as if all of the streams in the array were concatenat-
ed, in order, to form a single stream. This allows PDF producers to create
image objects and other resources as they occur, even though they inter-
rupt the content stream. The division between streams may occur only at
the boundaries between lexical tokens (see Section 3.1, “Lexical Conven-
tions”) but is unrelated to the page’s logical content or organization. Ap-
plications that consume or produce PDF files are not required to preserve
the existing structure of the Contents array. (See implementation note 36
in Appendix H.)
Rotate
integer
(Optional; inheritable) The number of degrees by which the page should
be rotated clockwise when displayed or printed. The value must be a mul-
tiple of 90. Default value: 0.
Group
dictionary
(Optional; PDF 1.4) A group attributes dictionary specifying the attributes
of the page’s page group for use in the transparent imaging model (see
Sections 7.3.6, “Page Group,” and 7.5.5, “Transparency Group XObjects”).
Thumb
stream
(Optional) A stream object defining the page’s thumbnail image (see Sec-
tion 8.2.3, “Thumbnail Images”).
B
array
(Optional; PDF 1.1; recommended if the page contains article beads) An ar-
ray of indirect references to article beads appearing on the page (see Sec-
tion 8.3.2, “Articles”; see also implementation note 37 in Appendix H).
The beads are listed in the array in natural reading order.
147
SECTION 3.6
Document Structure
KEY
TYPE
VALUE
Dur
number
(Optional; PDF 1.1) The page’s display duration (also called its advance
timing): the maximum length of time, in seconds, that the page is dis-
played during presentations before the viewer application automatically
advances to the next page (see Section 8.3.3, “Presentations”). By default,
the viewer does not advance automatically.
Trans
dictionary
(Optional; PDF 1.1) A transition dictionary describing the transition effect
to be used when displaying the page during presentations (see Section
8.3.3, “Presentations”).
Annots
array
(Optional) An array of annotation dictionaries representing annotations
associated with the page (see Section 8.4, “Annotations”).
AA
dictionary
(Optional; PDF 1.2) An additional-actions dictionary defining actions to
be performed when the page is opened or closed (see Section 8.5.2, “Trig-
ger Events”; see also implementation note 38 in Appendix H).
Metadata
stream
(Optional; PDF 1.4) A metadata stream containing metadata for the page
(see Section 10.2.2, “Metadata Streams”).
PieceInfo
dictionary
(Optional; PDF 1.3) A page-piece dictionary associated with the page (see
Section 10.4, “Page-Piece Dictionaries”).
StructParents
integer
(Required if the page contains structural content items; PDF 1.3) The inte-
ger key of the page’s entry in the structural parent tree (see “Finding Struc-
ture Elements from Content Items” on page 868).
ID
byte string
(Optional; PDF 1.3; indirect reference preferred) The digital identifier of
the page’s parent Web Capture content set (see Section 10.9.5, “Object At-
tributes Related to Web Capture”).
PZ
number
(Optional; PDF 1.3) The page’s preferred zoom (magnification) factor: the
factor by which it should be scaled to achieve the natural display magnifi-
cation (see Section 10.9.5, “Object Attributes Related to Web Capture”).
SeparationInfo
dictionary
(Optional; PDF 1.3) A separation dictionary containing information need-
ed to generate color separations for the page (see Section 10.10.3, “Separa-
tion Dictionaries”).
Tabs
name
(Optional; PDF 1.5) A name specifying the tab order to be used for anno-
tations on the page. The possible values are R (row order), C (column or-
der), and S (structure order). See Section 8.4, “Annotations,” for details.
148
CHAPTER 3
Syntax
KEY
TYPE
VALUE
TemplateInstantiated
(Required if this page was created from a named page object; PDF 1.5) The
name
name of the originating page object (see Section 8.6.5, “Named Pages”).
PresSteps
dictionary
(Optional; PDF 1.5) A navigation node dictionary representing the first
node on the page (see “Sub-page Navigation” on page 601).
UserUnit
number
(Optional; PDF 1.6) A positive number giving the size of default user
space units, in multiples of 1⁄ 72 inch. The range of supported values is im-
plementation-dependent; see implementation note 177 in Appendix H.
Default value: 1.0 (user unit is 1⁄ 72 inch).
VP
dictionary
(Optional; PDF 1.6) An array of viewport dictionaries (see Table 8.109)
specifying rectangular regions of the page.
Example 3.15 shows the definition of a page object with a thumbnail image and
two annotations. The media box specifies that the page is to be printed on letter-
size paper. In addition, the resource dictionary is specified as a direct object and
shows that the page makes use of three fonts named F3, F5, and F7.
Example 3.15
3 0 obj
<< /Type /Page
/Parent 4 0 R
/MediaBox [ 0 0 612 792 ]
/Resources << /Font << /F3 7 0 R
/F5 9 0 R
/F7 11 0 R
>>
/ProcSet [ /PDF ]
>>
/Contents 12 0 R
/Thumb 14 0 R
/Annots [ 23 0 R
24 0 R
]
>>
endobj
149
SECTION 3.6
Document Structure
Inheritance of Page Attributes
Some of the page attributes shown in Table 3.27 are designated as inheritable. If
such an attribute is omitted from a page object, its value is inherited from an
ancestor node in the page tree. If the attribute is a required one, a value must be
supplied in an ancestor node. If the attribute is optional and no inherited value is
specified, the default value is used.
An attribute can thus be defined once for a whole set of pages by specifying it in
an intermediate page tree node and arranging the pages that share the attribute as
descendants of that node. For example, a document might specify the same
media box for all of its pages by including a MediaBox entry in the root node of
the page tree. If necessary, an individual page object could override this inherited
value with a MediaBox entry of its own.
Note: In a document conforming to the Linearized PDF organization (see Appen-
dix F), all page attributes must be specified explicitly as entries in the page dictio-
naries to which they apply; they may not be inherited from an ancestor node.
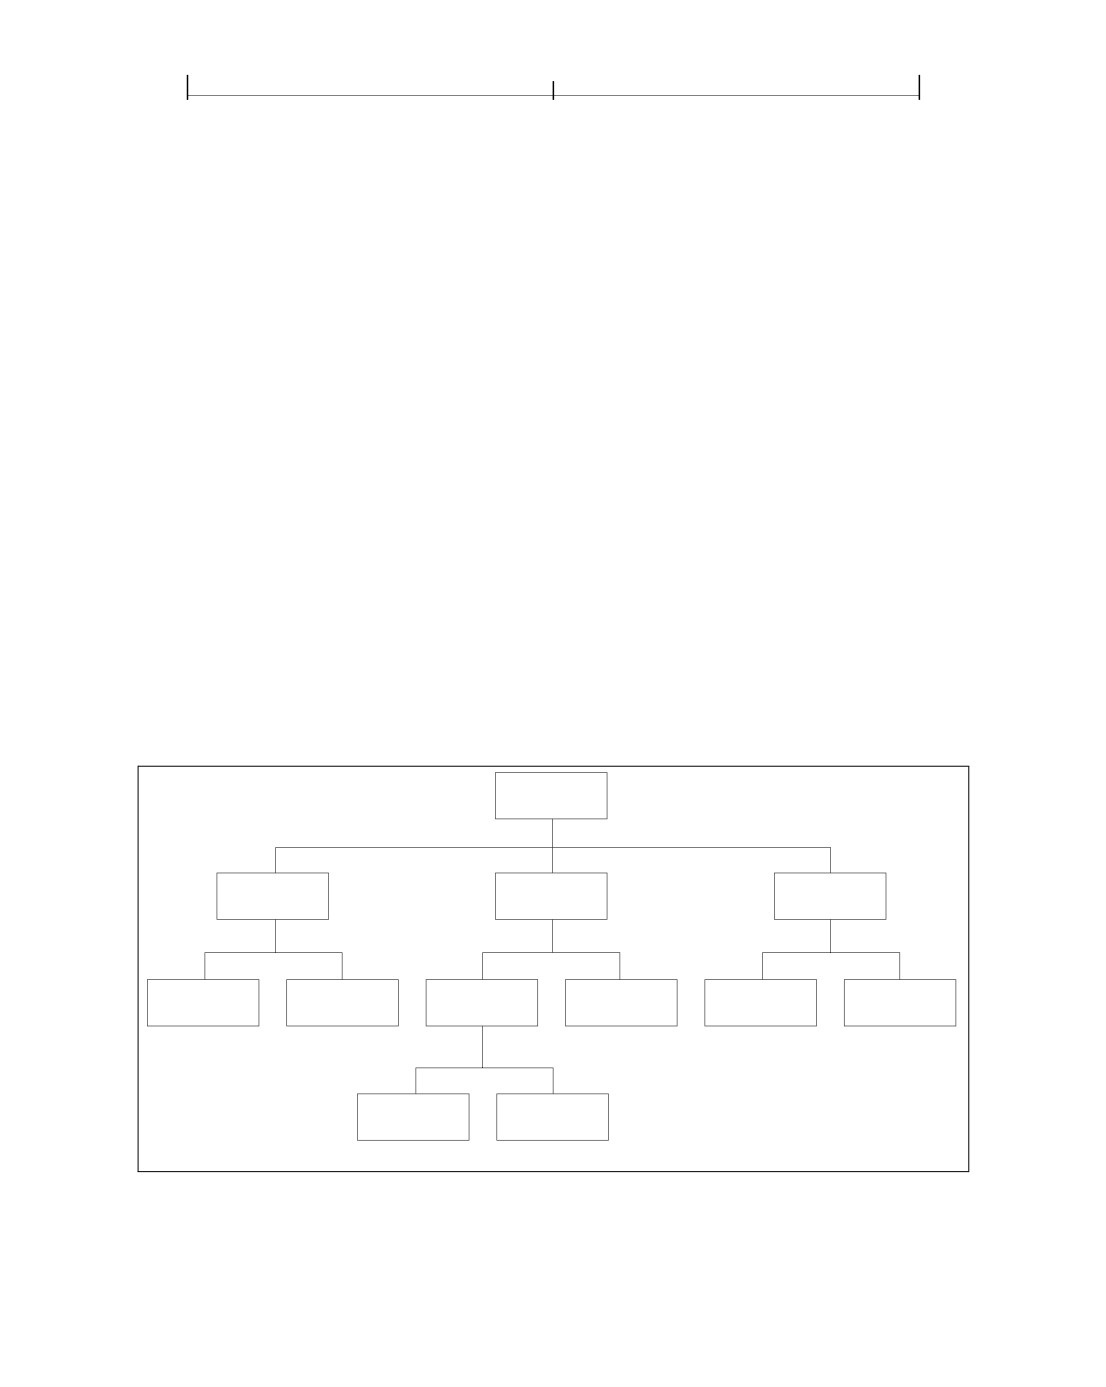
Figure 3.6 illustrates the inheritance of attributes. In the page tree shown, pages 1,
2, and 4 are rotated clockwise by 90 degrees, page 3 by 270 degrees, page 6 by 180
degrees, and pages 5 and 7 not at all (0 degrees).
Pages
Pages
Pages
Pages
/Rotate 90
/Rotate 180
Page
Page
Pages
Page
Page
Page
/Rotate 0
Page 1
Page 2
Page 5
Page 6
Page 7
Page
Page
/Rotate 270
/Rotate 90
Page 3
Page 4
FIGURE 3.6 Inheritance of attributes
150
CHAPTER 3
Syntax
3.6.3
Name Dictionary
Some categories of objects in a PDF file can be referred to by name rather than by
object reference. The correspondence between names and objects is established
by the document’s name dictionary (PDF 1.2), located by means of the Names
entry in the document’s catalog (see Section 3.6.1, “Document Catalog”). Each
entry in this dictionary designates the root of a name tree (Section 3.8.5, “Name
Trees”) defining names for a particular category of objects. Table 3.28 shows the
contents of the name dictionary.
TABLE 3.28 Entries in the name dictionary
KEY
TYPE
VALUE
Dests
name tree
(Optional; PDF 1.2) A name tree mapping name strings to destinations
(see “Named Destinations” on page 583).
AP
name tree
(Optional; PDF 1.3) A name tree mapping name strings to annotation
appearance streams (see Section 8.4.4, “Appearance Streams”).
JavaScript
name tree
(Optional; PDF 1.3) A name tree mapping name strings to document-level
JavaScript actions (see “JavaScript Actions” on page 709).
Pages
name tree
(Optional; PDF 1.3) A name tree mapping name strings to visible pages for
use in interactive forms (see Section 8.6.5, “Named Pages”).
Templates
name tree
(Optional; PDF 1.3) A name tree mapping name strings to invisible (tem-
plate) pages for use in interactive forms (see Section 8.6.5, “Named Pag-
es”).
IDS
name tree
(Optional; PDF 1.3) A name tree mapping digital identifiers to Web Cap-
ture content sets (see Section 10.9.3, “Content Sets”).
URLS
name tree
(Optional; PDF 1.3) A name tree mapping uniform resource locators
(URLs) to Web Capture content sets (see Section 10.9.3, “Content Sets”).
EmbeddedFiles
name tree
(Optional; PDF 1.4) A name tree mapping name strings to file specifica-
tions for embedded file streams (see Section 3.10.3, “Embedded File
Streams”).
AlternatePresentations
name tree
(Optional; PDF 1.4) A name tree mapping name strings to alternate pre-
sentations (see Section 9.4, “Alternate Presentations”).
Renditions
name tree
(Optional; PDF 1.5) A name tree mapping name strings (which must have
Unicode encoding) to rendition objects (see Section 9.1.2, “Renditions”).
151
SECTION 3.7
Content Streams and Resources
3.7
Content Streams and Resources
Content streams are the primary means for describing the appearance of pages
and other graphical elements. A content stream depends on information
contained in an associated resource dictionary; in combination, these two objects
form a self-contained entity. This section describes these objects.
3.7.1
Content Streams
A content stream is a PDF stream object whose data consists of a sequence of
instructions describing the graphical elements to be painted on a page. The
instructions are represented in the form of PDF objects, using the same object
syntax as in the rest of the PDF document. However, whereas the document as a
whole is a static, random-access data structure, the objects in the content stream
are intended to be interpreted and acted upon sequentially.
Each page of a document is represented by one or more content streams. Content
streams are also used to package sequences of instructions as self-contained
graphical elements, such as forms (see Section 4.9, “Form XObjects”), patterns
(Section
4.6,
“Patterns”), certain fonts
(Section 5.5.4,
“Type 3 Fonts”), and
annotation appearances (Section 8.4.4, “Appearance Streams”).
A content stream, after decoding with any specified filters, is interpreted
according to the PDF syntax rules described in Section
3.1,
“Lexical
Conventions.” It consists of PDF objects denoting operands and operators. The
operands needed by an operator precede it in the stream. See Example 3.3 on
page 68 for an example of a content stream.
An operand is a direct object belonging to any of the basic PDF data types except
a stream. Dictionaries are permitted as operands only by certain specific
operators. Indirect objects and object references are not permitted at all.
An operator is a PDF keyword that specifies some action to be performed, such as
painting a graphical shape on the page. An operator keyword is distinguished
from a name object by the absence of an initial slash character (/ ). Operators are
meaningful only inside a content stream.
Note: This postfix notation, in which an operator is preceded by its operands, is
superficially the same as in the PostScript language. However, PDF has no concept
of an operand stack as PostScript has. In PDF, all of the operands needed by an op-
152
CHAPTER 3
Syntax
erator must immediately precede that operator. Operators do not return results, and
operands cannot be left over when an operator finishes execution.
Most operators have to do with painting graphical elements on the page or with
specifying parameters that affect subsequent painting operations. The individual
operators are described in the chapters devoted to their functions:
• Chapter 4 describes operators that paint general graphics, such as filled areas,
strokes, and sampled images, and that specify device-independent graphical
parameters, such as color.
• Chapter 5 describes operators that paint text using character glyphs defined in
fonts.
• Chapter 6 describes operators that specify device-dependent rendering param-
eters.
• Chapter 10 describes the marked-content operators that associate higher-level
logical information with objects in the content stream. These operators do not
affect the rendered appearance of the content; they specify information useful
to applications that use PDF for document interchange.
Ordinarily, when an application encounters an operator in a content stream that
it does not recognize, an error occurs. (See implementation note 39 in Appendix
H.) A pair of compatibility operators, BX and EX (PDF 1.1), modify this behavior
(see Table 3.29). These operators must occur in pairs and may be nested. They
bracket a compatibility section, a portion of a content stream within which
unrecognized operators are to be ignored without error. This mechanism enables
a PDF document to use operators defined in later versions of PDF without
sacrificing compatibility with older applications. It should be used only in cases
where ignoring such newer operators is the appropriate thing to do. The BX and
EX operators are not themselves part of any graphics object (see Section 4.1,
“Graphics Objects”) or of the graphics state (Section 4.3, “Graphics State”).
TABLE 3.29 Compatibility operators
OPERANDS OPERATOR DESCRIPTION
—
BX
(PDF 1.1) Begin a compatibility section. Unrecognized operators (along with their
operands) are ignored without error until the balancing EX operator is encountered.
—
EX
(PDF 1.1) End a compatibility section begun by a balancing BX operator.
153
SECTION 3.7
Content Streams and Resources
3.7.2
Resource Dictionaries
As stated above, the operands supplied to operators in a content stream may only
be direct objects; indirect objects and object references are not permitted. In
some cases, an operator needs to refer to a PDF object that is defined outside the
content stream, such as a font dictionary or a stream containing image data. This
can be accomplished by defining such objects as named resources and referring to
them by name from within the content stream.
Note: Named resources are meaningful only in the context of a content stream. The
scope of a resource name is local to a particular content stream and is unrelated to
externally known identifiers for objects such as fonts. References from one object to
another outside of content streams should be made by means of indirect object refer-
ences rather than named resources.
A content stream’s named resources are defined by a resource dictionary, which
enumerates the named resources needed by the operators in the content stream
and the names by which they can be referred to. For example, if a text operator
appearing within the content stream needs a certain font, the content stream’s
resource dictionary can associate the name F42 with the corresponding font
dictionary. The text operator can use this name to refer to the font.
A resource dictionary is associated with a content stream in one of the following
ways:
• For a content stream that is the value of a page’s Contents entry (or is an
element of an array that is the value of that entry), the resource dictionary is
designated by the page dictionary’s Resources entry. (Since a page’s Resources
attribute is inheritable, as described under “Inheritance of Page Attributes” on
page 149, it may actually reside in some ancestor node of the page object.)
• For other content streams, the stream dictionary’s Resources entry specifies the
resource dictionary. This applies to content streams that define form XObjects,
patterns, Type 3 fonts, and annotation appearances.
• A form XObject or a Type 3 font’s glyph description may omit the Resources
entry, in which case resources are looked up in the Resources entry of the page
on which the form or font is used. This practice is not recommended.
154
CHAPTER 3
Syntax
In the context of a given content stream, the term current resource dictionary
refers to the resource dictionary associated with the stream in one of the ways
described above.
Each key in a resource dictionary is the name of a resource type, as shown in
Table 3.30. The corresponding values are as follows:
• For resource type ProcSet, the value is an array of procedure set names
• For all other resource types, the value is a subdictionary. Each key in the sub-
dictionary is the name of a specific resource, and the corresponding value is a
PDF object associated with the name.
TABLE 3.30 Entries in a resource dictionary
KEY
TYPE
VALUE
ExtGState
dictionary
(Optional) A dictionary that maps resource names to graphics state parame-
ter dictionaries (see Section 4.3.4, “Graphics State Parameter Dictionaries”).
ColorSpace
dictionary
(Optional) A dictionary that maps each resource name to either the name of a
device-dependent color space or an array describing a color space (see Sec-
tion 4.5, “Color Spaces”).
Pattern
dictionary
(Optional) A dictionary that maps resource names to pattern objects (see Sec-
tion 4.6, “Patterns”).
Shading
dictionary
(Optional; PDF 1.3) A dictionary that maps resource names to shading dic-
tionaries (see “Shading Dictionaries” on page 304).
XObject
dictionary
(Optional) A dictionary that maps resource names to external objects (see
Section 4.7, “External Objects”).
Font
dictionary
(Optional) A dictionary that maps resource names to font dictionaries (see
Chapter 5).
ProcSet
array
(Optional) An array of predefined procedure set names (see Section 10.1,
“Procedure Sets”).
Properties
dictionary
(Optional; PDF 1.2) A dictionary that maps resource names to property list
dictionaries for marked content (see Section 10.5.1, “Property Lists”).
Example 3.16 shows a resource dictionary containing procedure sets, fonts, and
external objects. The procedure sets are specified by an array, as described in
Section 10.1, “Procedure Sets.” The fonts are specified with a subdictionary
155
SECTION 3.8
Common Data Structures
associating the names F5, F6, F7, and F8 with objects 6, 8, 10, and 12, respectively.
Likewise, the XObject subdictionary associates the names Im1 and Im2 with
objects 13 and 15, respectively.
Example 3.16
<< /ProcSet [ /PDF /ImageB ]
/Font << /F5 6 0 R
/F6 8 0 R
/F7 10 0 R
/F8 12 0 R
>>
/XObject << /Im1 13 0 R
/Im2 15 0 R
>>
>>
3.8
Common Data Structures
As mentioned at the beginning of this chapter, there are some general-purpose
data structures that are built from the basic object types described in Section 3.2,
“Objects,” and are used in many places throughout PDF. This section describes
data structures for text strings, dates, rectangles, name trees, and number trees.
The subsequent two sections describe more complex data structures for functions
and file specifications.
All of these data structures are meaningful only as part of the document hier-
archy; they cannot appear within content streams. In particular, the special
conventions for interpreting the values of string objects apply only to strings
outside content streams. An entirely different convention is used within content
streams for using strings to select sequences of glyphs to be painted on the page
(see Chapter 5). Table 3.31 summarizes the basic and higher-level data types that
are used throughout this book to describe the values of dictionary entries and
other PDF data values.
TABLE 3.31 PDF data types
TYPE
DESCRIPTION
SECTION
PAGE
ASCII string
Bytes containing ASCII characters
3.8.1
157
array
Array object
3.2.5
58
156
CHAPTER 3
Syntax
TYPE
DESCRIPTION
SECTION
PAGE
boolean
Boolean value
3.2.1
52
byte string
A series of 8-bit bytes that represent
3.8.1
157
characters or other binary data. If such a
type represents characters, the encoding
is not identified.
date
Date (ASCII string)
3.8.3
160
dictionary
Dictionary object
3.2.6
59
file specification
File specification (string or dictionary)
3.10
178
function
Function (dictionary or stream)
3.9
166
integer
Integer number
3.2.2
52
name
Name object
3.2.4
56
name tree
Name tree (dictionary)
3.8.5
161
null
Null object
3.2.8
63
number
Number (integer or real)
3.2.2
52
number tree
Number tree (dictionary)
3.8.6
166
PDFDocEncoded string
Bytes containing a string that has been
3.8.1
encoded using PDFDocEncoding
rectangle
Rectangle (array)
3.8.4
161
stream
Stream object
3.2.7
60
string
Any string that is not a text string.
3.8.1
53
Beginning with PDF 1.7, this type is
further qualified as the types:
PDFDocEncoded string, ASCII string,
and byte string.
text string
Bytes that represent characters encoded
3.8.1
158
using either PDFDocEncoding or UTF-
16BE with a leading byte-order marker (as
defined in “Text String Type” on page 158.)
text stream
Text stream
3.8.2
160
157
SECTION 3.8
Common Data Structures
3.8.1
String Types
PDF supports the string and text string types. Beginning with PDF 1.7, the string
type is further qualified as PDFDocEncoded string, ASCII string, or byte string.
The further qualification reflects the encoding used to represent the characters or
glyphs described by the string.
Table 3.32 summarizes the string types. These types are not true types. Rather,
they are versions of the string type that represent data encoded using specific
conventions.
TABLE 3.32 String Types
TYPE
DESCRIPTION
string
For PDF 1.6 and earlier, this type is used for any string that can-
not be represented as a text string. Beginning with PDF 1.7, this
type is further qualified as ASCII string, PDFDocEncoded
string, and byte string.
text string
Used for human-readable characters, such as text annotations,
bookmark names, article names, and document information.
These strings are encoded using either PDFDocEncoding or
UTF-16BE with a leading byte-order marker.
This type is described in “Text String Type” on page 158.
PDFDocEncoded string
(PDF 1.7) Used for characters and glyphs that are represented in
a single byte, using PDFDocEncoding. This type, which reflects
a more specific encoding than the text string type, is described
in “PDFDocEncoded String Type” on page 159.
ASCII string
(PDF 1.7) Used for characters that are represented in a single
byte using ASCII encoding.
byte string
(PDF 1.7) Used for binary data represented as a series of 8-bit
bytes, where each byte can be any value representable in 8 bits.
The string may represent characters or glyphs but the encoding
is not known. The bytes of the string may not represent charac-
ters. This type is used for data such as MD5 hash values, signa-
ture certificates, and Web Capture identification values.
This type is described in “Byte String Type” on page 159.
158
CHAPTER 3
Syntax
The string types described in Table 3.32 specify increasingly specific encoding
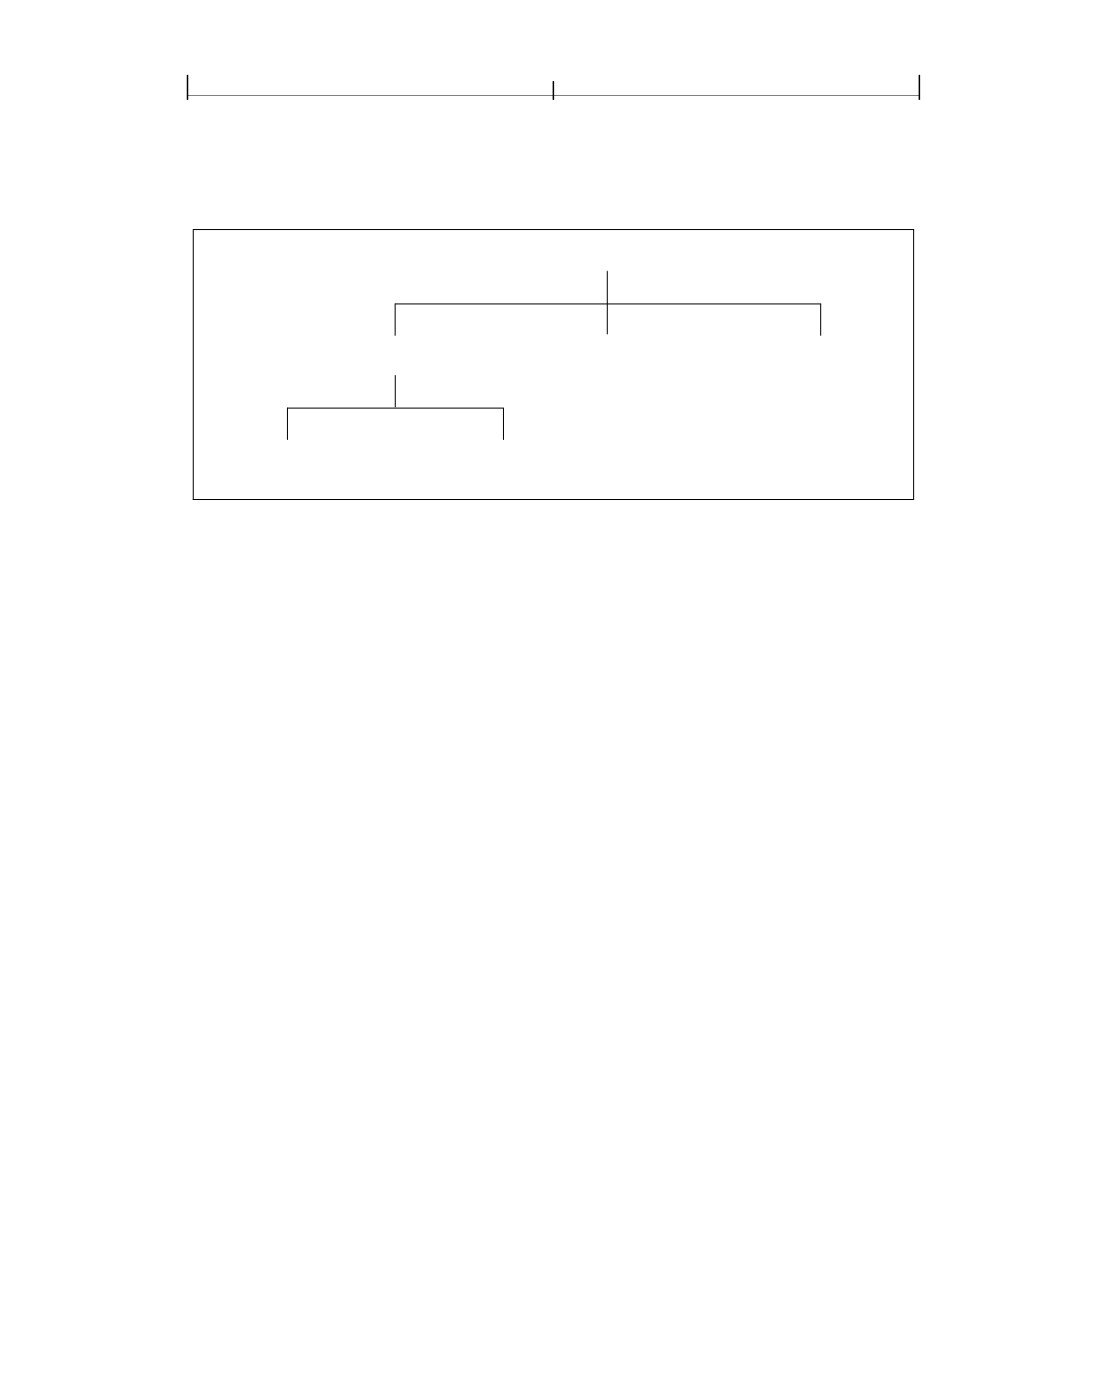
schemes, as shown in Figure 3.7.
string type
text string type
ASCII string type
byte string type
PDFDocEncoded
UTF-16BE encoded string with
string type
a leading byte order marker
FIGURE 3.7 Relationship between string types
Text String Type
The text string type is used for character strings that contain information
intended to be human-readable, such as text annotations, bookmark names,
article names, document information, and so forth. The term character strings is
used to describe such strings independent of the encoding with which they are
represented in a PDF document.
Note: This type is not a true type. Rather, it is a string type that represents data en-
coded using specific conventions.
The text string type is used for character strings that are encoded in either PDF-
DocEncoding or the UTF-16BE Unicode character encoding scheme. PDFDocEn-
coding can encode all of the ISO Latin 1 character set and is documented in
Appendix D. UTF-16BE can encode all Unicode characters. UTF-16BE and
Unicode character encoding are described in the Unicode Standard by the
Unicode Consortium (see the Bibliography). Note that PDFDocEncoding does
not support all Unicode characters whereas UTF-16BE does.
For text strings encoded in Unicode, the first two bytes must be 254 followed by
255. These two bytes represent the Unicode byte order marker, U+FEFF, indicating
that the string is encoded in the UTF-16BE (big-endian) encoding scheme
specified in the Unicode standard. (This mechanism precludes beginning a string
159
SECTION 3.8
Common Data Structures
using PDFDocEncoding with the two characters thorn ydieresis, which is unlikely
to be a meaningful beginning of a word or phrase).
Note: Applications that process PDF files containing Unicode text strings should be
prepared to handle supplementary characters; that is, characters requiring more
than two bytes to represent.
An escape sequence may appear anywhere in a Unicode text string to indicate the
language in which subsequent text is written, which is useful when the language
cannot be determined from the character codes used in the text. The escape
sequence consists of the following elements, in order:
1. The Unicode value U+001B (that is, the byte sequence 0 followed by 27).
2. A 2-character ISO 639 language code—for example, en for English or ja for
Japanese. Character in this context means byte (as in ASCII character), not
Unicode character.
3. (Optional) A 2-character ISO 3166 country code—for example, US for the
United States or JP for Japan.
4. The Unicode value U+001B.
The complete list of codes defined by ISO 639 and ISO 3166 can be obtained
from the International Organization for Standardization (see the Bibliography).
PDFDocEncoded String Type
A PDFDocEncoded string is similar to a string object, but it is a character string
where characters are represented in a single byte using PDFDocEncoding. Note
that PDFDocEncoding does not support all Unicode characters whereas UTF-
16BE does.
Note: This type is not a true type. Rather, it is a string type that represents data en-
coded using a specific convention.
Byte String Type
The byte string type is used for binary data represented as a series of 8-bit bytes,
where each byte can be any value representable in 8 bits. The string may
160
CHAPTER 3
Syntax
represent characters but the encoding is not known. The bytes of the string may
not represent characters.
Note: This type is not a true type. Rather, it is a string type that represents data
whose encoding is unknown.
3.8.2
Text Streams
A text stream (PDF 1.5) is a PDF stream object (Section 3.2.7) whose unencoded
bytes meet the same requirements as a text string (“Text String Type” on page
158) with respect to encoding, byte order, and lead bytes.
3.8.3
Dates
PDF defines a standard date format, which closely follows that of the
international standard ASN.1 (Abstract Syntax Notation One), defined in ISO/
IEC 8824 (see the Bibliography). A date is an ASCII string of the form
( D : YYYYMMDDHHmmSSOHH ' mm ' )
where
YYYY is the year
MM is the month
DD is the day (01-31)
HH is the hour (00-23)
mm is the minute (00-59)
SS is the second (00-59)
O is the relationship of local time to Universal Time (UT), denoted by one of
the characters +, −, or Z (see below)
HH followed by ' is the absolute value of the offset from UT in hours (00-23)
mm followed by ' is the absolute value of the offset from UT in minutes (00-59)
The apostrophe character (' ) after HH and mm is part of the syntax. All fields after
the year are optional.
(The prefix D : , although also optional, is strongly
recommended.) The default values for MM and DD are both 01; all other
161
SECTION 3.8
Common Data Structures
numerical fields default to zero values. A plus sign (+) as the value of the O field
signifies that local time is later than UT, a minus sign (−) signifies that local time
is earlier than UT, and the letter Z signifies that local time is equal to UT. If no UT
information is specified, the relationship of the specified time to UT is considered
to be unknown. Regardless of whether the time zone is known, the rest of the date
should be specified in local time.
For example, December 23, 1998, at 7:52 PM, U.S. Pacific Standard Time, is
represented by the string
D : 199812231952 − 08 ' 00 '
3.8.4
Rectangles
Rectangles are used to describe locations on a page and bounding boxes for a
variety of objects, such as fonts. A rectangle is written as an array of four numbers
giving the coordinates of a pair of diagonally opposite corners. Typically, the
array takes the form
[ llx lly urx ury ]
specifying the lower-left x, lower-left y, upper-right x, and upper-right y
coordinates of the rectangle, in that order. The other two corners of the rectangle
are then assumed to have coordinates (llx, ury) and (urx, lly).
Note: Although rectangles are conventionally specified by their lower-left and upper-
right corners, it is acceptable to specify any two diagonally opposite corners. Appli-
cations that process PDF should be prepared to normalize such rectangles in situa-
tions where specific corners are required.
3.8.5
Name Trees
A name tree serves a similar purpose to a dictionary—associating keys and
values—but by different means. A name tree differs from a dictionary in the
following important ways:
• Unlike the keys in a dictionary, which are name objects, those in a name tree
are strings.
• The keys are ordered.
162
CHAPTER 3
Syntax
• The values associated with the keys may be objects of any type. Stream objects
are required to be specified by indirect object references. It is recommended,
though not required, that dictionary, array, and string objects be specified by
indirect object references, and other PDF objects (nulls, numbers, booleans,
and names) be specified as direct objects.
• The data structure can represent an arbitrarily large collection of key-value
pairs, which can be looked up efficiently without requiring the entire data
structure to be read from the PDF file. (In contrast, a dictionary is subject to an
implementation limit on the number of entries it can contain.)
A name tree is constructed of nodes, each of which is a dictionary object.
Table 3.33 shows the entries in a node dictionary. The nodes are of three kinds,
depending on the specific entries they contain. The tree always has exactly one
root node, which contains a single entry: either Kids or Names but not both. If the
root node has a Names entry, it is the only node in the tree. If it has a Kids entry,
each of the remaining nodes is either an intermediate node, containing a Limits
entry and a Kids entry, or a leaf node, containing a Limits entry and a Names
entry.
TABLE 3.33 Entries in a name tree node dictionary
KEY
TYPE
VALUE
Kids
array
(Root and intermediate nodes only; required in intermediate nodes; present in the root
node if and only if Names is not present) An array of indirect references to the immediate
children of this node. The children may be intermediate or leaf nodes.
Names
array
(Root and leaf nodes only; required in leaf nodes; present in the root node if and only if Kids
is not present) An array of the form
[ key1 value1 key2 value2 … keyn valuen ]
where each keyi is a string and the corresponding valuei is the object associated with that
key. The keys are sorted in lexical order, as described below.
Limits
array
(Intermediate and leaf nodes only; required) An array of two strings, specifying the (lexi-
cally) least and greatest keys included in the Names array of a leaf node or in the Names
arrays of any leaf nodes that are descendants of an intermediate node.
The Kids entries in the root and intermediate nodes define the tree’s structure by
identifying the immediate children of each node. The Names entries in the leaf
(or root) nodes contain the tree’s keys and their associated values, arranged in
key-value pairs and sorted lexically in ascending order by key. Shorter keys
163
SECTION 3.8
Common Data Structures
appear before longer ones beginning with the same byte sequence. The encoding
of the keys is immaterial as long as it is self-consistent; keys are compared for
equality on a simple byte-by-byte basis.
The keys contained within the various nodes’ Names entries do not overlap; each
Names entry contains a single contiguous range of all the keys in the tree. In a leaf
node, the Limits entry specifies the least and greatest keys contained within the
node’s Names entry. In an intermediate node, it specifies the least and greatest
keys contained within the Names entries of any of that node’s descendants. The
value associated with a given key can thus be found by walking the tree in order,
searching for the leaf node whose Names entry contains that key.
Example 3.17 is an abbreviated outline, showing object numbers and nodes, of a
name tree that maps the names of all the chemical elements, from actinium to
zirconium, to their atomic numbers. Example 3.18 shows the representation of
this tree in a PDF file.
Example 3.17
Example of a name tree
1:
Root node
2:
Intermediate node: Actinium to Gold
5: Leaf node: Actinium = 25, … , Astatine = 31
25: Integer: 89
…
31: Integer: 85
…
11:Leaf node: Gadolinium = 56, … , Gold = 59
56: Integer: 64
…
59: Integer: 79
3:
Intermediate node: Hafnium to Protactinium
12: Leaf node: Hafnium = 60, … , Hydrogen = 65
60: Integer: 72
…
65: Integer: 1
…
19: Leaf node: Palladium = 92, … , Protactinium = 100
92: Integer: 46
…
100:Integer: 91
4:
Intermediate node: Radium to Zirconium
20: Leaf node: Radium = 101, … , Ruthenium = 107
101:Integer: 89
164
CHAPTER 3
Syntax
…
107:Integer: 85
…
24: Leaf node: Xenon = 129, … , Zirconium = 133
129:Integer: 54
…
133:Integer: 40
Example 3.18
1 0 obj
<< /Kids
[
2 0 R
% Root node
3 0 R
4 0 R
]
>>
endobj
2 0 obj
<< /Limits [ ( Actinium ) ( Gold ) ]
% Intermediate node
/Kids
[
5 0 R
6 0 R
7 0 R
8 0 R
9 0 R
10 0 R
11 0 R
]
>>
endobj
3 0 obj
<< /Limits [ ( Hafnium ) ( Protactinium ) ]
% Intermediate node
/Kids
[
12 0 R
13 0 R
14 0 R
15 0 R
16 0 R
17 0 R
18 0 R
19 0 R
]
>>
endobj
165
SECTION 3.8
Common Data Structures
4 0 obj
<< /Limits [ ( Radium ) ( Zirconium ) ]
% Intermediate node
/Kids
[
20 0 R
21 0 R
22 0 R
23 0 R
24 0 R
]
>>
endobj
5 0 obj
<< /Limits [ ( Actinium ) ( Astatine ) ]
% Leaf node
/Names [ ( Actinium ) 25 0 R
( Aluminum ) 26 0 R
( Americium ) 27 0 R
( Antimony ) 28 0 R
( Argon ) 29 0 R
( Arsenic )
30 0 R
( Astatine )
31 0 R
]
>>
endobj
…
24 0 obj
<< /Limits [ ( Xenon ) ( Zirconium ) ]
% Leaf node
/Names [ ( Xenon ) 129 0 R
( Ytterbium ) 130 0 R
( Yttrium )
131 0 R
( Zinc )
132 0 R
( Zirconium ) 133 0 R
]
>>
endobj
25 0 obj
89
% Atomic number (Actinium)
endobj
…
133 0 obj
40
% Atomic number (Zirconium)
endobj
166
CHAPTER 3
Syntax
3.8.6
Number Trees
A number tree is similar to a name tree (see Section 3.8.5, “Name Trees”), except
that its keys are integers instead of strings and are sorted in ascending numerical
order. The entries in the leaf (or root) nodes containing the key-value pairs are
named Nums instead of Names as in a name tree. Table 3.34 shows the entries in a
number tree’s node dictionaries.
TABLE 3.34 Entries in a number tree node dictionary
KEY
TYPE
VALUE
Kids
array
(Root and intermediate nodes only; required in intermediate nodes; present in the root
node if and only if Nums is not present) An array of indirect references to the immediate
children of this node. The children may be intermediate or leaf nodes.
Nums
array
(Root and leaf nodes only; required in leaf nodes; present in the root node if and only if Kids
is not present) An array of the form
[ key1 value1 key2 value2 … keyn valuen ]
where each keyi is an integer and the corresponding valuei is the object associated with
that key. The keys are sorted in numerical order, analogously to the arrangement of keys
in a name tree as described in Section 3.8.5, “Name Trees.”
Limits
array
(Intermediate and leaf nodes only; required) An array of two integers, specifying the
(numerically) least and greatest keys included in the Nums array of a leaf node or in the
Nums arrays of any leaf nodes that are descendants of an intermediate node.
3.9
Functions
PDF is not a programming language, and a PDF file is not a program. However,
PDF does provide several types of function objects (PDF 1.2) that represent
parameterized classes of functions, including mathematical formulas and
sampled representations with arbitrary resolution. Functions are used in various
ways in PDF, including device-dependent rasterization information for high-
quality printing (halftone spot functions and transfer functions), color transform
functions for certain color spaces, and specification of colors as a function of
position for smooth shadings.
Большое спасибо!
Ваше мнение очень важно для нас.
Нет комментариевНе стесняйтесь поделиться с нами вашим ценным мнением.
Текст