PDF Reference sixth edition, Adobe Portable Document Format Version 1.7 (book 1) — page 3
85
SECTION 3.3
Filters
TABLE 3.11 Optional parameter for the DCTDecode filter
KEY
TYPE
VALUE
ColorTransform
integer
A code specifying the transformation to be performed on the sample values:
0
No transformation.
1
If the image has three color components, transform RGB values to
YUV before encoding and from YUV to RGB after decoding. If the
image has four components, transform CMYK values to YUVK be-
fore encoding and from YUVK to CMYK after decoding. This option
is ignored if the image has one or two color components.
Note: The RGB and YUV used here have nothing to do with the color spaces
defined as part of the Adobe imaging model. The purpose of converting from
RGB to YUV is to separate luminance and chrominance information (see be-
low).
The default value of ColorTransform is 1 if the image has three components
and 0 otherwise. In other words, conversion between RGB and YUV is per-
formed for all three-component images unless explicitly disabled by setting
ColorTransform to 0. Additionally, the encoding algorithm inserts an Adobe-
defined marker code in the encoded data, indicating the ColorTransform val-
ue used. If present, this marker code overrides the ColorTransform value giv-
en to DCTDecode. Thus it is necessary to specify ColorTransform only when
decoding data that does not contain the Adobe-defined marker code.
The encoding algorithm can reduce the information loss by making the step size
in the quantization smaller at the expense of reducing the amount of compression
achieved by the algorithm. The compression achieved by the JPEG algorithm
depends on the image being compressed and the amount of loss that is
acceptable. In general, a compression of 15 : 1 can be achieved without perceptible
loss of information, and 30 : 1 compression causes little impairment of the image.
Better compression is often possible for color spaces that treat luminance and
chrominance separately than for those that do not. The RGB-to-YUV conversion
provided by the filters is one attempt to separate luminance and chrominance; it
conforms to CCIR recommendation 601-1. Other color spaces, such as the CIE
1976 L*a*b* space, may also achieve this objective. The chrominance
components can then be compressed more than the luminance by using coarser
sampling or quantization, with no degradation in quality.
86
CHAPTER 3
Syntax
The JPEG filter implementation in Acrobat products does not support features of
the JPEG standard that are irrelevant to images. In addition, certain choices have
been made regarding reserved marker codes and other optional features of the
standard. For details, see Adobe Technical Note #5116, Supporting the DCT
Filters in PostScript Level 2.
In addition to the baseline JPEG format, beginning with PDF 1.3, the DCTDecode
filter supports the progressive JPEG extension. This extension does not add any
entries to the DCTDecode parameter dictionary; the distinction between baseline
and progressive JPEG is represented in the encoded data.
Note: There is no benefit to using progressive JPEG for stream data that is embed-
ded in a PDF file. Decoding progressive JPEG is slower and consumes more memory
than baseline JPEG. The purpose of this feature is to enable a stream to refer to an
external file whose data happens to be already encoded in progressive JPEG. (See
also implementation note 11 in Appendix H.)
3.3.8
JPXDecode Filter
The JPXDecode filter (PDF 1.5) decodes data that has been encoded using the
JPEG2000 compression method, an international standard for the compression
and packaging of image data. JPEG2000 defines a wavelet-based method for
image compression that gives somewhat better size reduction than other methods
such as regular JPEG or CCITT. Although the filter can reproduce samples that
are losslessly compressed, it is recommended only for use with images and not for
general data compression.
In PDF, this filter can be applied only to image XObjects, and not to inline images
(see Section 4.8, “Images”). It is suitable both for images that have a single color
component and for those that have multiple color components. The color
components in an image may have different numbers of bits per sample. Any
value from 1 to 38 is allowed.
From a single JPEG2000 data stream, multiple versions of an image may be
decoded. These different versions form progressions along four degrees of
freedom: sampling resolution, color depth, band, and location. For example, with
a resolution progression, a thumbnail version of the image may be decoded from
the data, followed by a sequence of other versions of the image, each with
approximately four times as many samples (twice the width times twice the
height) as the previous one. The last version is the full-resolution image.
87
SECTION 3.3
Filters
Viewing and printing applications may gain performance benefits by using the
resolution progression. If the full-resolution image is densely sampled, the
application may be able to select and decode only the data making up a lower-
resolution version, thereby spending less time decoding. Fewer bytes need be
processed, a particular benefit when viewing files over the Web. The tiling
structure of the image may also provide benefits if only certain areas of an image
need to be displayed or printed.
Note: Information on these progressions is encoded in the data; no decode parame-
ters are needed to describe them. The decoder deals with any progressions it encoun-
ters to deliver the correct image data. Progressions that are of no interest may simply
have performance consequences.
The JPEG2000 specifications define two widely used formats, JP2 and JPX, for
packaging the compressed image data. JP2 is a subset of JPX. These packagings
contain all the information needed to properly interpret the image data,
including the color space, bits per component, and image dimensions. In other
words, they are complete descriptions of images (as opposed to image data that
require outside parameters for correct interpretation). The JPXDecode filter
expects to read a full JPX file structure—either internal to the PDF file or as an
external file.
To promote interoperability, the specifications define a subset of JPX called JPX
baseline (of which JP2 is also a subset). The complete details of the baseline set of
JPX features are contained in ISO/IEC 15444-2, Information Technology—JPEG
2000 Image Coding System: Extensions (see the Bibliography). See also
Data used in PDF image XObjects should be limited to the JPX baseline set of
features, except for enumerated color space 19 (CIEJab). In addition, enumerated
color space 12 (CMYK), which is part of JPX but not JPX baseline, is supported in
PDF.
A JPX file describes a collection of channels that are present in the image data. A
channel may have one of three types:
• An ordinary channel contains values that, when decoded, become samples for a
specified color component.
• An opacity channel provides samples that are to be interpreted as raw opacity
information.
88
CHAPTER 3
Syntax
• A premultiplied opacity channel provides samples that have been multiplied
into the color samples of those channels with which it is associated.
Opacity and premultiplied opacity channels are associated with specific color
channels. There is never more than one opacity channel
(of either type)
associated with a given color channel. For example, it is possible for one opacity
channel to apply to the red samples and another to apply to the green and blue
color channels of an RGB image.
Note: The method by which the opacity information is to be used is explicitly not
specified, although one possible method shows a normal blending mode.
In addition to using opacity channels for describing transparency, JPX files also
have the ability to specify chroma-key transparency. A single color is specified by
giving an array of values, one value for each color channel. Any image location
that matches this color is considered to be completely transparent.
Images in JPX files can have one of the following color spaces:
• A predefined color space, chosen from a list of enumerated color spaces. (Two of
these are actually families of spaces and parameters are included.)
• A “restricted ICC profile.” (These are the only sorts of ICC profiles that are al-
lowed in JP2 files.)
• An input ICC profile of any sort defined by ICC-1.
• A vendor-defined color space.
More than one color space may be specified for an image, with each space being
tagged with a precedence and an approximation value that indicates how well it
represents the preferred color space. In addition, the image’s color space may
serve as the foundation for a palette of colors that are selected using samples
coming from the image’s data channels: the equivalent of an Indexed color space
in PDF.
There are other features in the JPX format beyond describing a simple image.
These include provisions for describing layering and giving instructions on
composition, specifying simple animation, and including generic XML metadata
(along with JPEG2000-specific schemas for such data). It is recommended, but
not required, that relevant metadata be replicated in the image dictionary’s
Metadata stream in XMP format (see Section 10.2.2, “Metadata Streams).
89
SECTION 3.3
Filters
When using the JPXDecode filter with image XObjects, there are changes to and
constraints on some entries in the image dictionary (see Section 4.8.4, “Image
Dictionaries” for details on these entries):
• Width and Height must match the corresponding width and height values in
the JPEG2000 data.
• ColorSpace is optional since JPEG2000 data contain color space specifications.
If present, it determines how the image samples are interpreted, and the color
space specifications in the JPEG2000 data are ignored. The number of color
channels in the JPEG2000 data must match the number of components in the
color space; the PDF producer must ensure that the samples are consistent with
the color space used.
Any color space other than Pattern may be specified. If an Indexed color space
is used, it is subject to the PDF limit of 256 colors. (The analogous concept in
the JPEG2000 color specifications is a palette color space, which has a limit of
1024 colors.) If the color space does not match one of JPX’s enumerated color
spaces (for example, if it has two color components or more than four), it can
be specified as a vendor color space in the JPX data.
If ColorSpace is not present in the image dictionary, the color space informa-
tion in the JPEG2000 data is used. Consumer applications must support the
JPX baseline set of enumerated color spaces; they are also responsible for deal-
ing with the interaction between the color spaces and the bit depth of samples.
If multiple color space specifications are given in the JPEG2000 data, a render-
ing application should attempt to use the one with the highest precedence and
best approximation value. If the color space is given by an unsupported ICC
profile, the next lower color space, in terms of precedence and approximation
value, is used. If no supported color space is found, the color space used should
be DeviceGray, DeviceRGB, or DeviceCMYK, depending on the number of color
channels in the JPEG2000 data.
• SMaskInData specifies whether soft-mask information packaged with the im-
age samples should be used (see “Soft-Mask Images” on page 553); if it is, the
SMask entry is not needed. If SMaskInData is nonzero, there must be only one
opacity channel in the JPEG2000 data and it must apply to all color channels.
• Decode is ignored, except in the case where the image is treated as a mask; that
is, when ImageMask is true. In this case, the JPEG2000 data must provide a sin-
gle color channel with 1-bit samples.
90
CHAPTER 3
Syntax
3.3.9
Crypt Filter
The Crypt filter (PDF 1.5) allows the document-level security handler (see
Section 3.5, “Encryption”) to determine which algorithms should be used to
decrypt the input data. The Name parameter in the decode parameters dictionary
for this filter (see Table 3.12) specifies which of the named crypt filters in the
document (see Section 3.5.4, “Crypt Filters”) should be used.
TABLE 3.12 Optional parameters for Crypt filters
KEY
TYPE
VALUE
Type
name
(Optional) If present, must be CryptFilterDecodeParms for a Crypt filter de-
code parameter dictionary.
Name
name
(Optional) The name of the crypt filter that is to be used to decrypt this
stream. The name must correspond to an entry in the CF entry of the encryp-
tion dictionary (see Table 3.18) or one of the standard crypt filters (see
Table 3.23).
Default value: Identity.
In addition, the decode parameters dictionary may include entries that are
private to the security handler. Security handlers may use information from both
the crypt filter decode parameters dictionary and the crypt filter dictionaries (see
Table 3.22) when decrypting data or providing a key to decrypt data.
Note: When adding private data to the decode parameters dictionary, security han-
dlers should name these entries in conformance with the PDF name registry (see
Appendix E, “PDF Name Registry”).
3.4
File Structure
The preceding sections describe the syntax of individual objects. This section
describes how objects are organized in a PDF file for efficient random access and
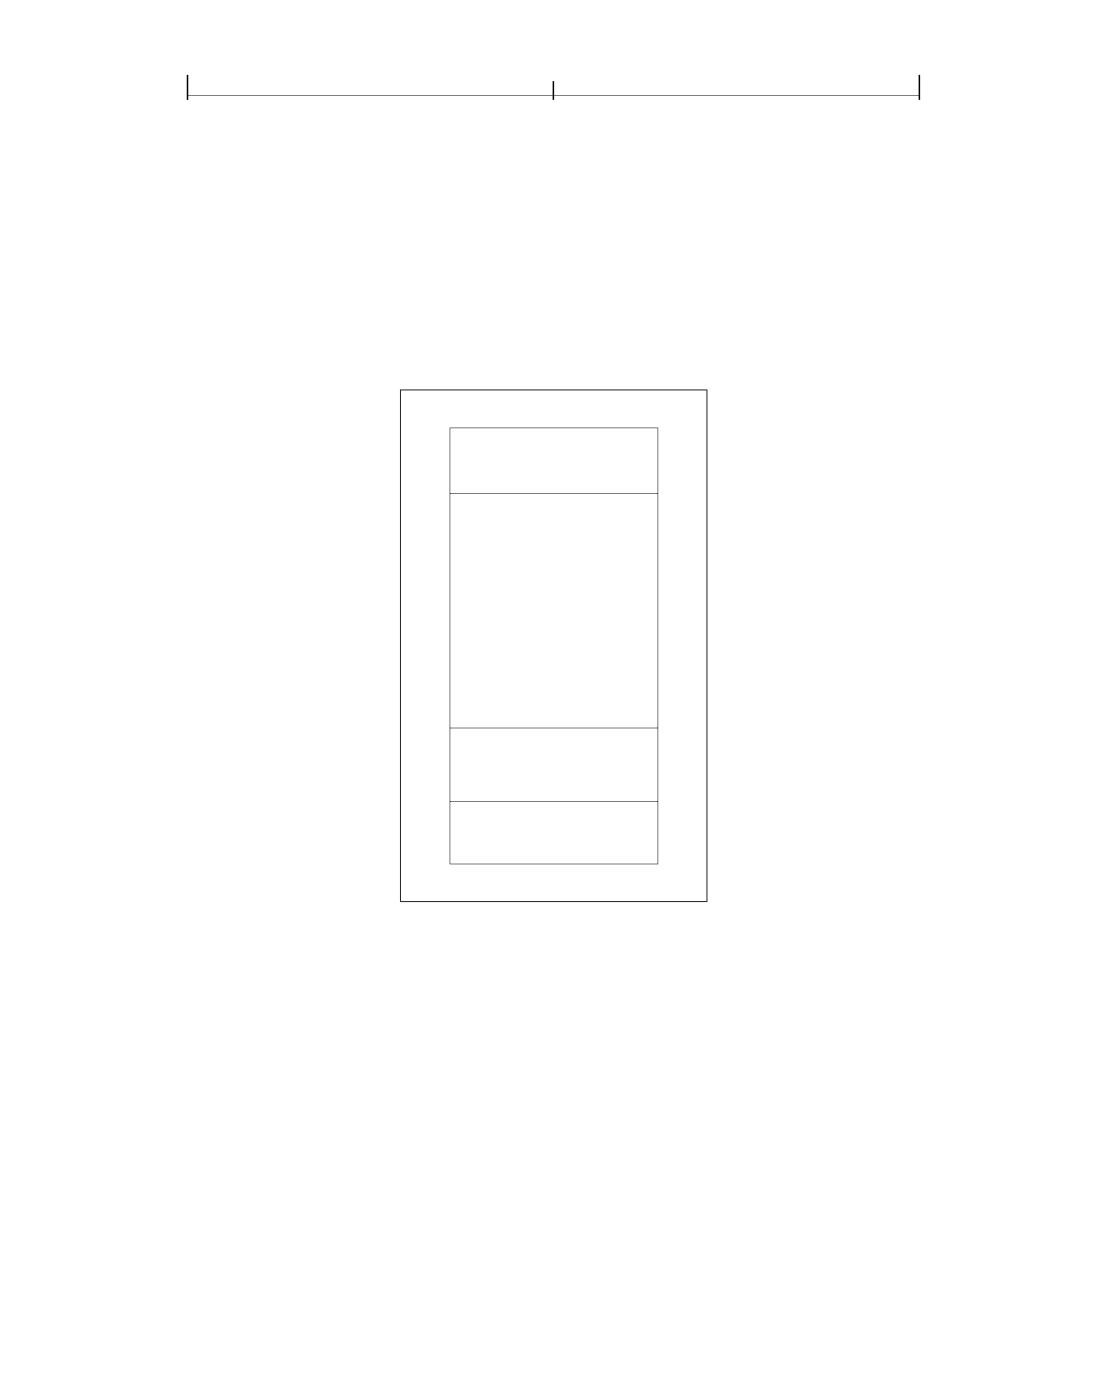
incremental update. A canonical PDF file initially consists of four elements (see
Figure 3.2):
• A one-line header identifying the version of the PDF specification to which the
file conforms
• A body containing the objects that make up the document contained in the file
91
SECTION 3.4
File Structure
• A cross-reference table containing information about the indirect objects in the
file
• A trailer giving the location of the cross-reference table and of certain special
objects within the body of the file
This initial structure may be modified by later updates, which append additional
elements to the end of the file; see Section 3.4.5, “Incremental Updates,” for
details.
Header
Body
Cross-reference
table
Trailer
FIGURE 3.2 Initial structure of a PDF file
As a matter of convention, the tokens in a PDF file are arranged into lines; see
Section 3.1, “Lexical Conventions.” Each line is terminated by an end-of-line
(EOL) marker, which may be a carriage return (character code 13), a line feed
(character code 10), or both. PDF files with binary data may have arbitrarily long
lines. However, to increase compatibility with other applications that process
PDF files, lines that are not part of stream object data are limited to no more than
255 characters, with one exception. Beginning with PDF 1.3, the Contents string
of a signature dictionary (see Section 8.7, “Digital Signatures”) is not subject to
the restriction on line length. See also implementation note 12 in Appendix H.
92
CHAPTER 3
Syntax
The rules described here are sufficient to produce a well-formed PDF file.
However, additional rules apply to organizing a PDF file to enable efficient
incremental access to a document’s components in a network environment. This
form of organization, called Linearized PDF, is described in Appendix F.
3.4.1
File Header
The first line of a PDF file is a header identifying the version of the PDF
specification to which the file conforms. For a file conforming to PDF 1.7, the
header should be
%PDF−1. 7
However, since any file conforming to an earlier version of PDF also conforms to
version 1.7, an application that processes PDF 1.7 can also accept files with any of
the following headers:
%PDF−1. 0
%PDF−1. 1
%PDF−1. 2
%PDF−1. 3
%PDF−1. 4
%PDF−1. 5
%PDF−1. 6
(See also implementation notes 13 and 14 in Appendix H.)
Beginning with PDF 1.4, the version in the file header can be overridden by the
Version entry in the document’s catalog dictionary (located by means of the Root
entry in the file’s trailer, as described in Section 3.4.4, “File Trailer”). This enables
a PDF producer application to update the version using an incremental update
(see Section 3.4.5, “Incremental Updates”).
Under some conditions, a consumer application may be able to process PDF files
conforming to a later version than it was designed to accept. New PDF features
are often introduced in such a way that they can safely be ignored by a consumer
that does not understand them (see Section H.1, “PDF Version Numbers”).
Note: If a PDF file contains binary data, as most do (see Section 3.1, “Lexical Con-
ventions”), it is recommended that the header line be immediately followed by a
comment line containing at least four binary characters—that is, characters whose
93
SECTION 3.4
File Structure
codes are 128 or greater. This ensures proper behavior of file transfer applications
that inspect data near the beginning of a file to determine whether to treat the file’s
contents as text or as binary.
3.4.2
File Body
The body of a PDF file consists of a sequence of indirect objects representing the
contents of a document. The objects, which are of the basic types described in
Section 3.2, “Objects,” represent components of the document such as fonts,
pages, and sampled images. Beginning with PDF 1.5, the body can also contain
object streams, each of which contains a sequence of indirect objects; see Section
3.4.6, “Object Streams.”
3.4.3
Cross-Reference Table
The cross-reference table contains information that permits random access to
indirect objects within the file so that the entire file need not be read to locate any
particular object. The table contains a one-line entry for each indirect object,
specifying the location of that object within the body of the file. (Beginning with
PDF 1.5, some or all of the cross-reference information may alternatively be
contained in cross-reference streams; see Section
3.4.7,
“Cross-Reference
Streams”.)
The cross-reference table is the only part of a PDF file with a fixed format, which
permits entries in the table to be accessed randomly. The table comprises one or
more cross-reference sections. Initially, the entire table consists of a single section
(or two sections if the file is linearized; see Appendix F). One additional section is
added each time the file is updated (see Section 3.4.5, “Incremental Updates”).
Each cross-reference section begins with a line containing the keyword xref.
Following this line are one or more cross-reference subsections, which may appear
in any order. The subsection structure is useful for incremental updates, since it
allows a new cross-reference section to be added to the PDF file, containing
entries only for objects that have been added or deleted. For a file that has never
been updated, the cross-reference section contains only one subsection, whose
object numbering begins at 0.
94
CHAPTER 3
Syntax
Each cross-reference subsection contains entries for a contiguous range of object
numbers. The subsection begins with a line containing two numbers separated by
a space: the object number of the first object in this subsection and the number of
entries in the subsection. For example, the line
28 5
introduces a subsection containing five objects numbered consecutively from 28
to 32.
Note: A given object number must not have an entry in more than one subsection
within a single section. However, see implementation note 15 in Appendix H.
Following this line are the cross-reference entries themselves, one per line. Each
entry is exactly 20 bytes long, including the end-of-line marker. There are two
kinds of cross-reference entries: one for objects that are in use and another for
objects that have been deleted and therefore are free. Both types of entries have
similar basic formats, distinguished by the keyword n (for an in-use entry) or f
(for a free entry). The format of an in-use entry is
nnnnnnnnnn ggggg n eol
where
nnnnnnnnnn is a 10-digit byte offset
ggggg is a 5-digit generation number
n is a literal keyword identifying this as an in-use entry
eol is a 2-character end-of-line sequence
The byte offset is a 10-digit number, padded with leading zeros if necessary,
giving the number of bytes from the beginning of the file to the beginning of the
object. It is separated from the generation number by a single space. The
generation number is a 5-digit number, also padded with leading zeros if
necessary. Following the generation number is a single space, the keyword n, and
a 2-character end-of-line sequence. If the file’s end-of-line marker is a single
character (either a carriage return or a line feed), it is preceded by a single space;
if the marker is 2 characters (both a carriage return and a line feed), it is not
preceded by a space. Thus, the overall length of the entry is always exactly 20
bytes.
95
SECTION 3.4
File Structure
The cross-reference entry for a free object has essentially the same format, except
that the keyword is f instead of n and the interpretation of the first item is
different:
nnnnnnnnnn ggggg f eol
where
nnnnnnnnnn is the 10-digit object number of the next free object
ggggg is a 5-digit generation number
f is a literal keyword identifying this as a free entry
eol is a 2-character end-of-line sequence
The free entries in the cross-reference table form a linked list, with each free
entry containing the object number of the next. The first entry in the table (object
number 0) is always free and has a generation number of 65,535; it is the head of
the linked list of free objects. The last free entry (the tail of the linked list) links
back to object number 0. (In addition, the table may contain other free entries
that link back to object number 0 and have a generation number of 65,535, even
though these entries are not in the linked list itself.) See implementation note 16
in Appendix H.
Except for object number 0, all objects in the cross-reference table initially have
generation numbers of 0. When an indirect object is deleted, its cross-reference
entry is marked free and it is added to the linked list of free entries. The entry’s
generation number is incremented by 1 to indicate the generation number to be
used the next time an object with that object number is created. Thus, each time
the entry is reused, it is given a new generation number. The maximum
generation number is 65,535; when a cross-reference entry reaches this value, it is
never reused.
The cross-reference table (comprising the original cross-reference section and all
update sections) must contain one entry for each object number from 0 to the
maximum object number used in the file, even if one or more of the object
numbers in this range do not actually occur in the file. See implementation note
17 in Appendix H.
Example 3.5 shows a cross-reference section consisting of a single subsection
with six entries: four that are in use (objects number 1, 2, 4, and 5) and two that
96
CHAPTER 3
Syntax
are free (objects number 0 and 3). Object number 3 has been deleted, and the
next object created with that object number is given a generation number of 7.
Example 3.5
xref
0 6
0000000003 65535 f
0000000017 00000 n
0000000081 00000 n
0000000000 00007 f
0000000331 00000 n
0000000409 00000 n
Example 3.6 shows a cross-reference section with four subsections, containing a
total of five entries. The first subsection contains one entry, for object number 0,
which is free. The second subsection contains one entry, for object number 3,
which is in use. The third subsection contains two entries, for objects number 23
and 24, both of which are in use. Object number 23 has been reused, as can be
seen from the fact that it has a generation number of 2. The fourth subsection
contains one entry, for object number 30, which is in use.
Example 3.6
xref
0 1
0000000000 65535 f
3 1
0000025325 00000 n
23 2
0000025518 00002 n
0000025635 00000 n
30 1
0000025777 00000 n
See Section G.6, “Updating Example,” for a more extensive example of the
structure of a PDF file that has been updated several times.
3.4.4
File Trailer
The trailer of a PDF file enables an application reading the file to quickly find the
cross-reference table and certain special objects. Applications should read a PDF
97
SECTION 3.4
File Structure
file from its end. The last line of the file contains only the end-of-file marker,
%%EOF. (See implementation note 18 in Appendix H.) The two preceding lines
contain the keyword startxref and the byte offset from the beginning of the file to
the beginning of the xref keyword in the last cross-reference section. The
startxref line is preceded by the trailer dictionary, consisting of the keyword
trailer followed by a series of key-value pairs enclosed in double angle brackets
(<<… >>). Thus, the trailer has the following overall structure:
trailer
<< key1 value1
key2 value2
…
keyn valuen
>>
startxref
Byte_offset_of_last_cross-reference_section
%%EOF
Table 3.13 lists the contents of the trailer dictionary.
TABLE 3.13 Entries in the file trailer dictionary
KEY
TYPE
VALUE
Size
integer
(Required; must not be an indirect reference) The total number of entries in the file’s
cross-reference table, as defined by the combination of the original section and all
update sections. Equivalently, this value is 1 greater than the highest object number
used in the file.
Note: Any object in a cross-reference section whose number is greater than this value is
ignored and considered missing.
Prev
integer
(Present only if the file has more than one cross-reference section; must not be an indi-
rect reference) The byte offset from the beginning of the file to the beginning of the
previous cross-reference section.
Root
dictionary
(Required; must be an indirect reference) The catalog dictionary for the PDF docu-
ment contained in the file (see Section 3.6.1, “Document Catalog”).
Encrypt
dictionary
(Required if document is encrypted; PDF 1.1) The document’s encryption dictionary
(see Section 3.5, “Encryption”).
Info
dictionary
(Optional; must be an indirect reference) The document’s information dictionary
(see Section 10.2.1, “Document Information Dictionary”).
98
CHAPTER 3
Syntax
KEY
TYPE
VALUE
ID
array
(Optional, but strongly recommended; PDF 1.1) An array of two byte-strings consti-
tuting a file identifier (see Section 10.3, “File Identifiers”) for the file. The two byte-
strings should be direct objects and should be unencrypted. Although this entry is
optional, its absence might prevent the file from functioning in some workflows
that depend on files being uniquely identified.
Note: Table 3.17 defines an additional entry, XRefStm, that appears only in the trail-
er of hybrid-reference files, described in “Compatibility with Applications That Do
Not Support PDF 1.5” on page 109.
Example 3.7 shows an example trailer for a file that has never been updated (as
indicated by the absence of a Prev entry in the trailer dictionary).
Example 3.7
trailer
<< /Size 22
/Root 2 0 R
/Info
1 0 R
/ID
[
< 81b14aafa313db63dbd6f981e49f94f4 >
< 81b14aafa313db63dbd6f981e49f94f4 >
]
>>
startxref
18799
%%EOF
3.4.5
Incremental Updates
The contents of a PDF file can be updated incrementally without rewriting the
entire file. Changes are appended to the end of the file, leaving its original
contents intact. The main advantage to updating a file in this way (as discussed in
Section 2.2.7, “Incremental Update”) is that small changes to a large document
can be saved quickly. There are additional advantages:
• In some cases, incremental updating is the only way to save changes to a docu-
ment. An accepted practice for minimizing the risk of data loss when saving a
document is to write it to a new file and rename the new file to replace the old
one. However, in certain contexts, such as when editing a document across an
HTTP connection or using OLE embedding (a Windows-specific technology),
99
SECTION 3.4
File Structure
it is not possible to overwrite the contents of the original file in this manner. In-
cremental updates can be used to save changes to documents in these contexts.
• Once a document has been signed (see Section 2.2.6, “Security”), all changes
made to the document must be saved using incremental updates, since altering
any existing bytes in the file invalidates existing signatures.
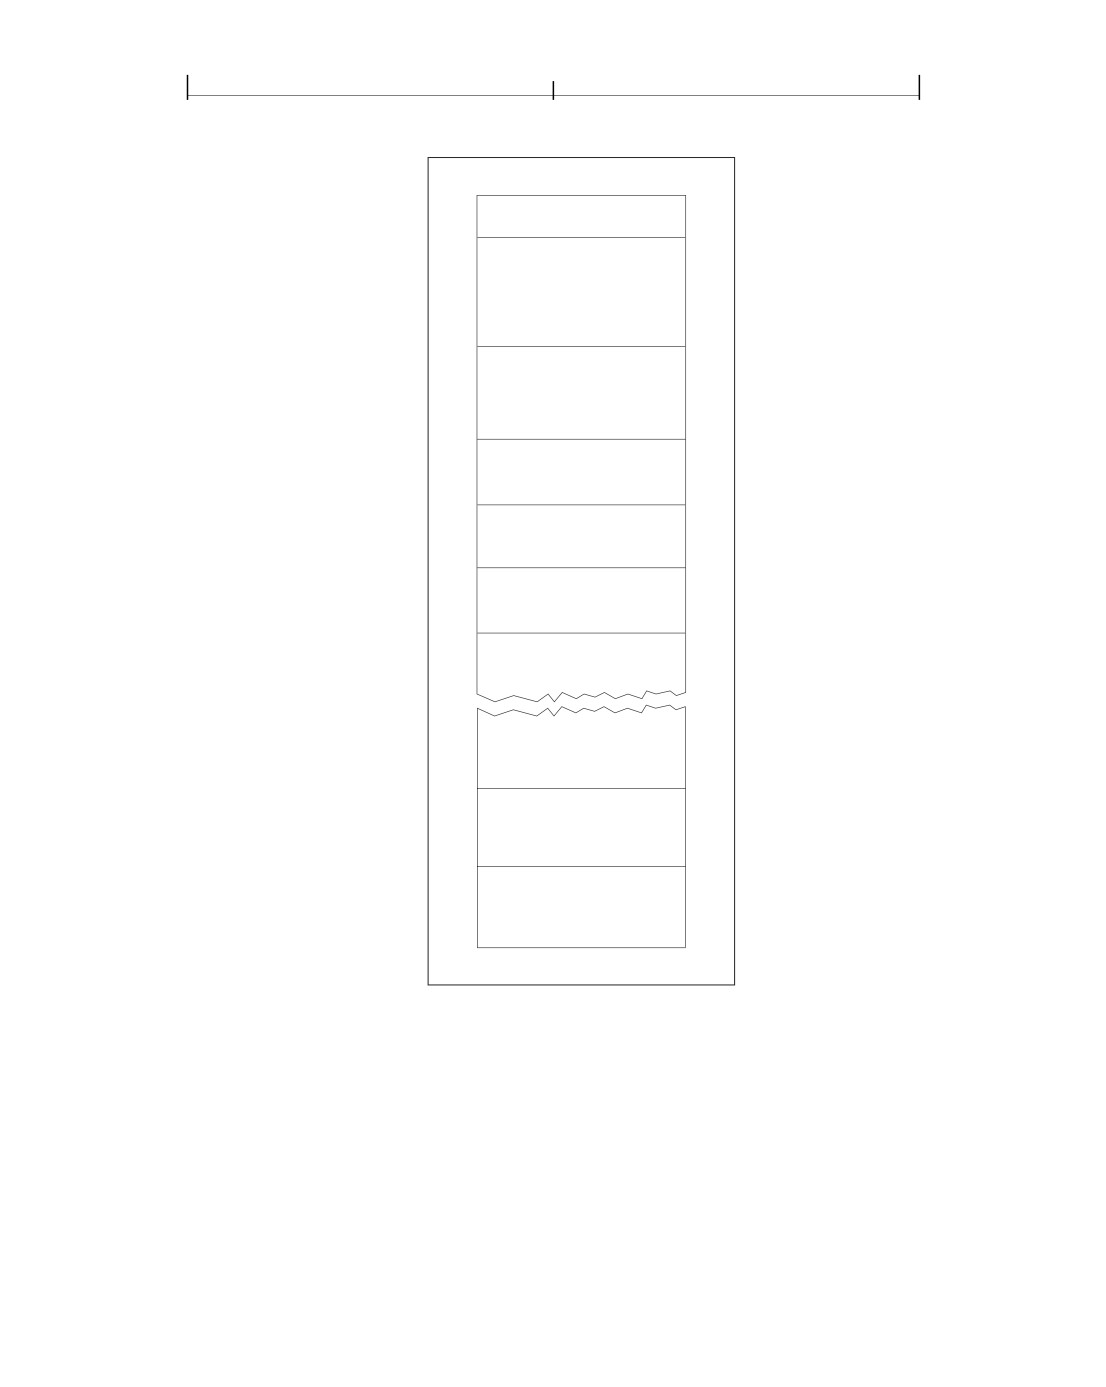
In an incremental update, any new or changed objects are appended to the file, a
cross-reference section is added, and a new trailer is inserted. The resulting file
has the structure shown in Figure 3.3. A complete example of an updated file is
shown in Section G.6, “Updating Example.”
The cross-reference section added when a file is updated contains entries only for
objects that have been changed, replaced, or deleted. Deleted objects are left
unchanged in the file, but are marked as deleted by means of their cross-reference
entries. The added trailer contains all the entries (perhaps modified) from the
previous trailer, as well as a Prev entry giving the location of the previous cross-
reference section (see Table 3.13 on page 97). As shown in Figure 3.3, a file that
has been updated several times contains several trailers; each trailer is terminated
by its own end-of-file (%%EOF) marker.
Because updates are appended to PDF files, a file can have several copies of an
object with the same object identifier (object number and generation number).
This can occur, for example, if a text annotation (see Section 8.4, “Annotations”)
is changed several times and the file is saved between changes. Because the text
annotation object is not deleted, it retains the same object number and generation
number as before. An updated copy of the object is included in the new update
section added to the file. The update’s cross-reference section includes a byte
offset to this new copy of the object, overriding the old byte offset contained in
the original cross-reference section. When a consumer application reads the file,
it must build its cross-reference information in such a way that the most recent
copy of each object is the one accessed in the file.
In versions of PDF earlier than 1.4, it was not possible to use an incremental
update to alter the version of PDF to which the document conforms, since the
version was specified only in the header at the beginning of the file (see Section
3.4.1,
“File Header”). In PDF 1.4, it is possible for a Version entry in the
document’s catalog dictionary
(see Section
3.6.1,
“Document Catalog”) to
override the version specified in the header, which enables the version to be
altered using an incremental update.
100
CHAPTER 3
Syntax
Header
Original
body
Original
cross-reference
section
Original trailer
Body update 1
Cross-reference
section 1
Updated trailer 1
Body update n
Cross-reference
section n
Updated trailer n
FIGURE 3.3 Structure of an updated PDF file
3.4.6
Object Streams
PDF 1.5 introduces a new kind of stream, an object stream, which contains a
sequence of PDF objects. The purpose of object streams is to allow a greater
number of PDF objects to be compressed, thereby substantially reducing the size
of PDF files. The objects in the stream are referred to as compressed objects. (This
101
SECTION 3.4
File Structure
term is used regardless of whether the stream is actually encoded with a
compression filter.)
Any PDF object can appear in an object stream, with the following exceptions:
• Stream objects
• Objects with a generation number other than zero
• A document’s encryption dictionary (see Section 3.5, “Encryption”)
• An object representing the value of the Length entry in an object stream dictio-
nary
Note: In addition, in linearized files (see Appendix F, “Linearized PDF”), the docu-
ment catalog, the linearization dictionary, and page objects may not appear in an
object stream.
Indirect references to objects inside object streams use the normal syntax: for
example, 14 0 R. Access to these objects requires a different way of storing cross-
reference information; see Section 3.4.7, “Cross-Reference Streams.” Although an
application must support PDF 1.5 to use compressed objects, the objects can be
stored in a manner that is compatible with PDF 1.4. Applications that do not
support PDF 1.5 can ignore the objects; see “Compatibility with Applications That
Do Not Support PDF 1.5” on page 109.
In addition to the standard keys for streams shown in Table 3.4, the stream
dictionary describing an object stream contains the following entries:
TABLE 3.14 Additional entries specific to an object stream dictionary
KEY
TYPE
DESCRIPTION
Type
name
(Required) The type of PDF object that this dictionary describes; must be ObjStm
for an object stream.
N
integer
(Required) The number of compressed objects in the stream.
First
integer
(Required) The byte offset (in the decoded stream) of the first compressed object.
Extends
stream
(Optional) A reference to an object stream, of which the current object stream is
considered an extension. Both streams are considered part of a collection of object
streams (see below). A given collection consists of a set of streams whose Extends
links form a directed acyclic graph.
102
CHAPTER 3
Syntax
The creator of a PDF file has flexibility in determining which objects, if any, to
store in object streams. For example, it can be useful to store objects having
common characteristics together, such as “fonts on page 1,” or “Comments for
draft #3.” These objects are known as a collection.
To avoid a degradation of performance, such as would occur when downloading
and decompressing a large object stream to access a single compressed object, the
number of objects in an individual object stream should be limited.
(See
implementation note 19 in Appendix H.) This may require a group of object
streams to be linked as a collection, which can be done by means of the Extends
entry in the object stream dictionary.
Extends can also be used when a collection is being updated to include new
objects. Rather than redefine the original object stream, which would require
duplicating the stream data, the new objects can be stored in a new object stream.
This is particularly important when adding an update section to a document.
The stream data in an object stream consists of the following items:
• N pairs of integers, where the first integer in each pair represents the object
number of a compressed object and the second integer represents the byte off-
set of that object, relative to the first one. The offsets must be in increasing or-
der, but there is no restriction on the order of object numbers.
Note: The byte offset in the decoded stream of the first object is the value of the
First entry.
• The N objects stored consecutively. Only the object values are stored in the
stream; the obj and endobj keywords are not used. A compressed dictionary or
array may contain indirect references.
Note: It is illegal for a compressed object to consist of only an indirect reference;
for example, 3 0 R.
By contrast, dictionaries and arrays in content streams (Section 3.7.1) may not
contain indirect references. In an encrypted file, strings occurring anywhere in
an object stream must not be separately encrypted, since the entire object
stream is encrypted.
Note: The data for the first object is not required to immediately follow the last
byte offset. Future extensions may place additional information between those
two points in the stream.
103
SECTION 3.4
File Structure
An object stream itself, like any stream, is an indirect object, and there must be an
entry for it in a cross-reference table or cross-reference stream (see Section 3.4.7,
“Cross-Reference Streams”), although there might not be any references to it (of
the form 243 0 R).
The generation number of an object stream and of any compressed object is
implicitly zero. If either an object stream or a compressed object is deleted and
the object number is freed, that object number can be reused only for an ordinary
(uncompressed) object other than an object stream. When new object streams
and compressed objects are created, they must always be assigned new object
numbers, not old ones taken from the free list.
Example 3.8 shows three objects (two fonts and a font descriptor) as they would
be represented in a PDF 1.4 or earlier file, along with a cross-reference table. In
Example 3.9, the same objects are stored in an object stream in a PDF 1.5 file,
along with a cross-reference stream.
Example 3.8
11 0 obj
<< /Type /Font
/Subtype /TrueType
...other entries...
/FontDescriptor 12 0 R
>>
endobj
12 0 obj
<< /Type /FontDescriptor
/Ascent 891
...other entries...
/FontFile2 22 0 R
>>
endobj
13 0 obj
<< /Type /Font
/Subtype /Type0
...other entries...
/ToUnicode 10 0 R
104
CHAPTER 3
Syntax
>>
endobj
xref
0 32
0000000000 65535 f
0000001434 00000 n
% Cross-reference entry for object 11
0000001735 00000 n
% Cross-reference entry for object 12
0000002155 00000 n
% Cross-reference entry for object 13
trailer
<< /Size 32
/Root ...
>>
In Example 3.9, the cross-reference stream (see Section 3.4.7, “Cross-Reference
Streams”) contains entries for the fonts (objects 11 and 13) and the descriptor
(object 12), which are compressed objects in an object stream. The first field of
these entries is the entry type (2), the second field is the number of the object
stream (15), and the third field is the position within the sequence of objects in
the object stream (0, 1, and 2). The cross-reference stream also contains a type 1
entry for the object stream itself.
Note: For readability, the object stream has been shown unencoded. In a real PDF
1.5 file, Flate encoding would typically be used to gain the benefits of compression.
Example 3.9
15 0 obj
% The object stream
<< /Type /ObjStm
/Length 1856
/N 3
% The number of objects in the stream
/First 24
% The byte offset of the first object
>>
stream
% The object numbers and offsets of the objects, relative to the first
11 0 12 547 13 665
<< /Type /Font
/Subtype /TrueType
...other keys...
105
SECTION 3.4
File Structure
/FontDescriptor 12 0 R
>>
<< /Type /FontDescriptor
/Ascent 891
...other keys...
/FontFile2 22 0 R
>>
<< /Type /Font
/Subtype /Type0
...other keys...
/ToUnicode 10 0 R
>>
endstream
endobj
99 0 obj
% The cross-reference stream
<< /Type /XRef
/Index [0 32]
% This section has one subsection with 32 objects
/W [1 2 2]
% Each entry has 3 fields: 1, 2 and 2 bytes in width,
% respectively
/Filter /ASCIIHexDecode
% For readability in this example
/Size 32
>>
stream
00 0000 FFFF
% “0 65535 f” in a cross-reference table
02 000F 0000
% The entry for object 11, the first font
02 000F 0001
% The entry for object 12, the font descriptor
02 000F 0002
% The entry for object 13, the second font
01 BA5E 0000
% The entry for object 15, the object stream
endstream
endobj
startxref
54321
% The offset of “99 0 obj”
%%EOF
106
CHAPTER 3
Syntax
3.4.7
Cross-Reference Streams
Beginning with PDF 1.5, cross-reference information may be stored in a cross-
reference stream instead of in a cross-reference table. Cross-reference streams
provide the following advantages:
• A more compact representation of cross-reference information
• The ability to access compressed objects that are stored in object streams (see
Section 3.4.6, “Object Streams”) and to allow new cross-reference entry types
to be added in the future
Cross-reference streams are stream objects (see Section 3.2.7, “Stream Objects”),
and contain a dictionary and a data stream. Each cross-reference stream contains
the information equivalent to the cross-reference table (see Section 3.4.3, “Cross-
Reference Table”) and trailer (see Section 3.4.4, “File Trailer”) for one cross-
reference section. The trailer dictionary entries are stored in the stream
dictionary, and the cross-reference table entries are stored as the stream data, as
shown in the following example:
Example 3.10
... objects ...
12 0 obj
% Cross-reference stream
<< /Type /XRef
% Cross-reference stream dictionary
/Size ...
/Root ...
>>
stream
% Stream data containing cross-reference information
endstream
endobj
... more objects ...
startxref
byte_offset_of_cross-reference_stream
% Points to object 12
%%EOF
Note that the value following the startxref keyword is now the offset of the cross-
reference stream rather than the xref keyword. (See implementation note 21 in
Appendix H.) For files that use cross-reference streams entirely (that is, PDF 1.5
107
SECTION 3.4
File Structure
files that are not hybrid-reference files; see “Compatibility with Applications That
Do Not Support PDF 1.5” on page 109), the keywords xref and trailer are no longer
used. Therefore, with the exception of the startxref address %%EOF segment and
comments, a PDF 1.5 file is entirely a sequence of objects.
Note: The use of object streams and cross-reference streams is permitted in linear-
ized PDF, with minor modifications to the specification (see Section F.2, “Linearized
PDF Document Structure”).
Cross-Reference Stream Dictionary
Cross-reference streams contain the entries shown in Table 3.15 in addition to
the entries common to all streams (Table 3.4) and trailer dictionaries (Table 3.13).
Since some of the information in the cross-reference stream is needed by the
consumer application to construct the index that allows indirect references to be
resolved, the entries in cross-reference streams are subject to the following
restrictions:
• The value of all entries shown in Table 3.15 must be direct objects; indirect ref-
erences are not permitted. For arrays (the Index and W entries), all their ele-
ments must be direct objects as well. If the stream is encoded, the Filter and
DecodeParms entries in Table 3.4 must also be direct objects. Also, see imple-
mentation note 20 in Appendix H.
Note: Other cross-reference stream entries not listed in Table 3.15 may be indi-
rect; in fact, some (such as Root in Table 3.13) are required to be indirect.
• The cross-reference stream must not be encrypted, nor may any strings appear-
ing in the cross-reference stream dictionary. It must not have a Filter entry that
specifies a Crypt filter (see 3.3.9, “Crypt Filter”).
TABLE 3.15 Additional entries specific to a cross-reference stream dictionary
KEY
TYPE
DESCRIPTION
Type
name
(Required) The type of PDF object that this dictionary describes; must be XRef for
a cross-reference stream.
Size
integer
(Required) The number one greater than the highest object number used in this
section or in any section for which this is an update. It is equivalent to the Size en-
try in a trailer dictionary.
108
CHAPTER 3
Syntax
KEY
TYPE
DESCRIPTION
Index
array
(Optional) An array containing a pair of integers for each subsection in this sec-
tion. The first integer is the first object number in the subsection; the second inte-
ger is the number of entries in the subsection
The array is sorted in ascending order by object number. Subsections cannot over-
lap; an object number may have at most one entry in a section.
Default value: [0 Size].
Prev
integer
(Present only if the file has more than one cross-reference stream; not meaningful in
hybrid-reference files; see “Compatibility with Applications That Do Not Support
PDF 1.5” on page 109) The byte offset from the beginning of the file to the begin-
ning of the previous cross-reference stream. This entry has the same function as
the Prev entry in the trailer dictionary (Table 3.13). (See also implementation note
21 in Appendix H.)
W
array
(Required) An array of integers representing the size of the fields in a single cross-
reference entry. Table 3.16 describes the types of entries and their fields. For PDF
1.5, W always contains three integers; the value of each integer is the number of
bytes (in the decoded stream) of the corresponding field. For example, [1 2 1]
means that the fields are one byte, two bytes, and one byte, respectively.
A value of zero for an element in the W array indicates that the corresponding field
is not present in the stream, and the default value is used, if there is one. If the first
element is zero, the type field is not present, and it defaults to type 1.
The sum of the items is the total length of each entry; it can be used with the Index
array to determine the starting position of each subsection.
Note: Different cross-reference streams in a PDF file may use different values for W.
Cross-Reference Stream Data
Each entry in a cross-reference stream has one or more fields, the first of which
designates the entry’s type (see Table 3.16). In PDF 1.5, only types 0, 1, and 2 are
allowed. Any other value is interpreted as a reference to the null object, thus
permitting new entry types to be defined in the future.
The fields are written in increasing order of field number; the length of each field
is determined by the corresponding value in the W entry (see Table 3.15). Fields
requiring more than one byte are stored with the high-order byte first.
109
SECTION 3.4
File Structure
TABLE 3.16 Entries in a cross-reference stream
TYPE
FIELD
DESCRIPTION
0
1
The type of this entry, which must be 0. Type 0 entries define the
linked list of free objects (corresponding to f entries in a cross-
reference table).
2
The object number of the next free object.
3
The generation number to use if this object number is used again.
1
1
The type of this entry, which must be 1. Type 1 entries define
objects that are in use but are not compressed (corresponding to n
entries in a cross-reference table).
2
The byte offset of the object, starting from the beginning of the
file.
3
The generation number of the object. Default value: 0.
2
1
The type of this entry, which must be 2. Type 2 entries define
compressed objects.
2
The object number of the object stream in which this object is
stored. (The generation number of the object stream is implicitly
0.)
3
The index of this object within the object stream.
Like any stream, a cross-reference stream is an indirect object. Therefore, an
entry for it must exist in either a cross-reference stream (usually itself) or in a
cross-reference table
(in hybrid-reference files; see
“Compatibility with
Applications That Do Not Support PDF 1.5” on page 109).
Compatibility with Applications That Do Not Support PDF 1.5
Applications that do not support PDF
1.5 cannot access objects that are
referenced by cross-reference streams. If a file uses cross-reference streams
exclusively, it cannot be opened by such applications.
However, it is possible to construct a file called a hybrid-reference file that is
readable by a PDF 1.4 consumer. Such a file contains objects referenced by
standard cross-reference tables in addition to objects in object streams that are
referenced by cross-reference streams.
110
CHAPTER 3
Syntax
In these files, the trailer dictionary can contain, in addition to the entry for
trailers shown in Table 3.13, an additional entry, as shown in Table 3.17. This
entry is ignored by PDF 1.4 consumers, which therefore have no access to entries
in the cross-reference stream the entry refers to.
TABLE 3.17 Additional entries in a hybrid-reference file’s trailer dictionary
KEY
TYPE
VALUE
XRefStm
integer
(Optional) The byte offset from the beginning of the file of a cross-reference stream.
The Size entry of the trailer must be large enough to include all objects, including
those defined in the cross-reference stream referenced by the XRefStm entry.
However, to allow random access, a main cross-reference section must contain
entries for all objects numbered 0 through Size - 1 (see Section 3.4.3, “Cross-
Reference Table”). Therefore, the XRefStm entry cannot be used in the trailer
dictionary of the main cross-reference section but only in an update cross-
reference section.
When a PDF 1.5 consumer opens a hybrid-reference file, objects with entries in
cross-reference streams are not hidden. When the application searches for an
object, if an entry is not found in any given standard cross-reference section, the
search proceeds to a cross-reference stream specified by the XRefStm entry before
looking in the previous cross-reference section (the Prev entry in the trailer).
Hidden objects, therefore, have two cross-reference entries. One is in the cross-
reference stream. The other is a free entry in some previous section, typically the
section referenced by the Prev entry. A PDF 1.5 consumer looks in the cross-
reference stream first, finds the object there, and ignores the free entry in the
previous section. A PDF 1.4 consumer ignores the cross-reference stream and
looks in the previous section, where it finds the free entry. The free entry must
have a next-generation number of 65535 so that the object number is never reused.
There are limitations on which objects in a hybrid-reference file can be hidden
without making the file appear invalid to PDF 1.4 and earlier consumers. In
particular, the root of the PDF file, the document catalog (see Section 3.6.1,
“Document Catalog”), must not be hidden, nor any object that is visible from the
root. Such objects can be determined by starting from the root and working
recursively:
• In any dictionary that is visible, direct objects are visible. The value of any re-
quired key-value pair is visible.
111
SECTION 3.4
File Structure
• In any array that is visible, every element is visible.
• Resource dictionaries in content streams are visible. Although a resource dic-
tionary is not required, strictly speaking, the content stream to which it is at-
tached is assumed to contain references to the resources.
In general, the objects that may be hidden are optional objects specified by
indirect references. A PDF
1.5 consumer can resolve those references by
processing the cross-reference streams. In a PDF 1.4 consumer, the objects
appear to be free, and the references are treated as references to the null object.
For example, the Outlines entry in the catalog dictionary is optional. Therefore,
its value may be an indirect reference to a hidden object. A PDF 1.4 consumer
treats it as a reference to the null object, which is equivalent to having omitted the
entry entirely; a PDF 1.5 consumer recognizes it. However, if the value of the
Outlines entry is an indirect reference to a visible object, the entire outline tree
must be visible because nodes in the outline tree contain required pointers to
other nodes.
Following this logic, items that must be visible include the entire page tree, fonts,
font descriptors, and width tables. Objects that may be hidden in a hybrid-
reference file include the structure tree, the outline tree, article threads,
annotations, destinations, Web Capture information, and page labels,.
Example 3.11 shows a hybrid-reference file containing a main cross-reference
section and an update cross-reference section with an XRefStm entry that points
to a cross-reference stream (object 11), which in turn has references to an object
stream (object 2).
In this example, the catalog (object 1) contains an indirect reference (3 0 R) to the
root of the structure tree. The search for the object starts at the update cross-
reference table, which has no objects in it. The search proceeds depending on the
version of the consumer application:
• In a PDF 1.4 consumer, the search continues by following the Prev pointer to
the main cross-reference table. That table defines object 3 as a free object,
which is treated as the null object. Therefore, the entry is considered missing,
and the document has no structure tree.
• In a PDF 1.5 consumer, the search continues by following the XRefStm pointer
to the cross-reference stream (object 11). It defines object 3 as a compressed
object, stored at index 0 in the object stream (2 0 obj). Therefore, the document
has a structure tree.
112
CHAPTER 3
Syntax
Note: To make the format and contents of the cross-reference stream readable in this
example, an ASCIIHexDecode filter is specified. As explained in implementation
note 20 in Appendix H, the example would not be acceptable to Acrobat 6.0 and lat-
er viewers as written.
Example 3.11
1 0 obj
% The document root, at offset 23.
<< /Type /Catalog
/StructTreeRoot 3 0 R
…
>>
endobj
12 0 obj
…
endobj
…
99 0 obj
…
endobj
xref
% The main xref section, at offset 2664
0 100
% This subsection has entries for objects 0 - 99.
0000000002 65535 f
% Entry for object 0
0000000023 00000 n
% Entry for object 1, the root
0000000003 65535 f
% Entry for object 2 (object stream), marked free in this table
0000000004 65535 f
% Entry for object 3, marked free in this table
0000000005 65535 f
% …
0000000006 65535 f
0000000007 65535 f
0000000008 65535 f
0000000009 65535 f
0000000010 65535 f
0000000011 65535 f
0000000000 65535 f
% Entry for object 11 (xref stream), marked free in this table.
0000000045 00000 n
% Entry for object 12, in use.
0000000179 00000 n
% Entry for object 13, in use.
…
0000002201 00000 n
% Entry for object 99, in use.
trailer
<< /Size 100
/Root 1 0 R
113
SECTION 3.4
File Structure
/ID …
>>
startxref
2664
% Offset of the main xref section
%%EOF
2 0 obj
% The object stream, at offset 3722
<< /Length ...
/N 8
% This stream contains 8 objects.
/First 47
% The stream-offset of the first object
>>
stream
3 0 4 50 5 72 …
% The numbers and stream-offsets of the 8 objects
<< /Type /StructTreeRoot
% This is object 3.
/K 4 0 R
/RoleMap 5 0 R
/ClassMap 6 0 R
/ParentTree 7 0 R
/ParentTreeNextKey 8
>>
<< /S /Workbook
% This is object 4 (K value from StructTreeRoot).
/P 8 0 R
/K 9 0 R
>>
<< /Workbook /Div
% This is object 5 (RoleMap).
/Worksheet /Sect
/TextBox /Figure
/Shape /Figure
>>
…
% Objects 6 through 10 are defined here.
endstream
endobj
11 0 obj
% The cross-reference stream, at offset 4899
<< /Type /XRef
/Index [2 10]
% This stream contains entries for objects 2 through 11
/Size 100
/W [1 2 1]
% The byte-widths of each field
/Filter /ASCIIHexDecode
% For readability only (not supported by Acrobat 6)
…
>>
stream
01 0E8A 0
% Entry for object 2 (0x0E8A = 3722)
114
CHAPTER 3
Syntax
02 0002 00
% Entry for object 3 (in object stream 2, index 0)
02 0002 01
% Entry for object 4 (in object stream 2, index 1)
02 0002 02
% …
02 0002 03
02 0002 04
02 0002 05
02 0002 06
02 0002 07
% Entry for object 10 (in object stream 2, index 7)
01 1323 0
% Entry for object 11 (0x1323 = 4899)
endstream
endobj
xref
% The update xref section, at offset 5640
0 0
% There are no entries in this section.
trailer
<< /Size 100
/Prev 2664
% Offset of previous xref section
/XRefStm 4899
/Root 1 0 R
/ID …
>>
startxref
5640
%%EOF
The example illustrates several other points:
• The object stream is unencoded and the cross-reference stream uses an ASCII
hexadecimal encoding for clarity. In practice, both streams would be Flate-en-
coded. Also, the comments shown in the cross-reference table in the above ex-
ample are for illustrative purposes; PDF comments are not legal in a cross-
reference table.
• The hidden objects, 2 through 11, are numbered consecutively. In practice,
there is no such requirement, nor is there a requirement that free items in a
cross-reference table be linked in ascending order until the end.
• The update cross-reference table contains no entries, which is not a require-
ment but is reasonable. A PDF creator that uses the hybrid-reference format
creates the main cross-reference table, the update cross-reference table, and the
cross-reference stream at the same time. Objects 12 and 13, for example, are not
compressed. They might have entries in the update table. Since objects 2 and
11, the object stream and the cross-reference stream, are not compressed, they
115
SECTION 3.5
Encryption
might also be defined in the update table. Since they are part of the hidden sec-
tion, however, it makes sense to define them in the cross-reference stream.
• The update cross-reference section must appear at the end of the file, but other-
wise, there are no ordering restrictions on any of the objects or on the main
cross-reference section. However, a file that uses both the hybrid-reference for-
mat and the linearized format has ordering requirements (see Appendix F,
“Linearized PDF”).
3.5
Encryption
A PDF document can be encrypted (PDF 1.1) to protect its contents from un-
authorized access. Encryption applies to all strings and streams in the document’s
PDF file, but not to other object types such as integers and boolean values, which
are used primarily to convey information about the document’s structure rather
than its content. Leaving these values unencrypted allows random access to the
objects within a document, whereas encrypting the strings and streams protects
the document’s substantive contents.
Note: When a PDF stream object (see Section 3.2.7, “Stream Objects”) refers to an
external file, the stream’s contents are not encrypted, since they are not part of the
PDF file itself. However, if the contents of the stream are embedded within the PDF
file (see Section 3.10.3, “Embedded File Streams”), they are encrypted like any other
stream in the file. Beginning with PDF 1.5, embedded files may be encrypted in an
otherwise unencrypted document (see Section 3.5.4, “Crypt Filters”).
Encryption-related information is stored in a document’s encryption dictionary,
which is the value of the Encrypt entry in the document’s trailer dictionary (see
Table 3.13 on page 97). The absence of this entry from the trailer dictionary
means that the document is not encrypted. The entries shown in Table 3.18 are
common to all encryption dictionaries.
The encryption dictionary’s Filter entry identifies the file’s security handler, a
software module that implements various aspects of the encryption process and
controls access to the contents of the encrypted document. PDF specifies a
standard password-based security handler that all consumer applications are
expected to support, but applications may optionally provide security handlers of
their own.
116
CHAPTER 3
Syntax
The SubFilter entry specifies the syntax of the encryption dictionary contents. It
allows interoperability between handlers; that is, a document may be decrypted
by a handler other than the preferred one (the Filter entry) if they both support
the format specified by SubFilter.
The V entry, in specifying which algorithm to use, determines the length of the
encryption key, on which the encryption (and decryption) of data in a PDF file is
based. For V values 2 and 3, the Length entry specifies the exact length of the
encryption key. In PDF 1.5, a value of 4 for V permits the security handler to use
its own encryption and decryption algorithms and to specify crypt filters to use
on specific streams (see Section 3.5.4, “Crypt Filters”).
The remaining contents of the encryption dictionary are determined by the
security handler and may vary from one handler to another. Entries for the
standard security handler are described in Section 3.5.2, “Standard Security
Handler.” Entries for public-key security handlers are described in Section 3.5.3,
“Public-Key Security Handlers.”
TABLE 3.18 Entries common to all encryption dictionaries
KEY
TYPE
VALUE
Filter
name
(Required) The name of the preferred security handler for this document. Typically, it is
the name of the security handler that was used to encrypt the document. If SubFilter is
not present, only this security handler should be used when opening the document. If it
is present, consumer applications can use any security handler that implements the for-
mat specified by SubFilter.
Standard is the name of the built-in password-based security handler. Names for other
security handlers can be registered by using the procedure described in Appendix E.
Note: The definition of this entry has been clarified since the previous version of this docu-
ment.
SubFilter
name
(Optional; PDF 1.3) A name that completely specifies the format and interpretation of
the contents of the encryption dictionary. It is needed to allow security handlers other
than the one specified by Filter to decrypt the document. If this entry is absent, other se-
curity handlers should not be allowed to decrypt the document.
Note: This entry was introduced in PDF 1.3 to support the use of public-key cryptography
in PDF files (see Section 3.5.3, “Public-Key Security Handlers”); however, it was not incor-
porated into the PDF Reference until the fourth edition (PDF 1.5).
117
SECTION 3.5
Encryption
KEY
TYPE
VALUE
V
number
(Optional but strongly recommended) A code specifying the algorithm to be used in en-
crypting and decrypting the document:
0
An algorithm that is undocumented and no longer supported, and whose use is
strongly discouraged.
1
Algorithm 3.1 on page 119, with an encryption key length of 40 bits; see below.
2
(PDF 1.4) Algorithm 3.1, but permitting encryption key lengths greater than 40
bits.
3
(PDF 1.4) An unpublished algorithm that permits encryption key lengths rang-
ing from 40 to 128 bits; see implementation note 22 in Appendix H.
4
(PDF 1.5) The security handler defines the use of encryption and decryption in
the document, using the rules specified by the CF, StmF, and StrF entries.
The default value if this entry is omitted is 0, but a value of 1 or greater is strongly rec-
ommended. (See implementation note 23 in Appendix H.)
Length
integer
(Optional; PDF 1.4; only if V is 2 or 3) The length of the encryption key, in bits. The value
must be a multiple of 8, in the range 40 to 128. Default value: 40.
CF
dictionary
(Optional; meaningful only when the value of V is 4; PDF 1.5) A dictionary whose keys
are crypt filter names and whose values are the corresponding crypt filter dictionaries
(see Table 3.22). Every crypt filter used in the document must have an entry in this dic-
tionary, except for the standard crypt filter names (see Table 3.23).
Note: An attempt to redefine any of the standard names in Table 3.23 is ignored.
StmF
name
(Optional; meaningful only when the value of V is 4; PDF 1.5) The name of the crypt filter
that is used by default when decrypting streams. The name must be a key in the CF dic-
tionary or a standard crypt filter name specified in Table 3.23. All streams in the docu-
ment, except for cross-reference streams (see Section 3.4.7, “Cross-Reference Streams”)
or streams that have a Crypt entry in their Filter array (see Table 3.5), are decrypted by
the security handler, using this crypt filter.
Default value: Identity.
StrF
name
(Optional; meaningful only when the value of V is 4; PDF 1.5) The name of the crypt filter
that is used when decrypting all strings in the document. The name must be a key in the
CF dictionary or a standard crypt filter name specified in Table 3.23.
Default value: Identity.
118
CHAPTER 3
Syntax
KEY
TYPE
VALUE
EFF
name
(Optional; meaningful only when the value of V is 4; PDF 1.6) The name of the crypt filter
that should be used by default when encrypting embedded file streams; it must corre-
spond to a key in the CF dictionary or a standard crypt filter name specified in
Table 3.23.
This entry is provided by the security handler. (See implementation note 24 in Appendix
H.) Applications should respect this value when encrypting embedded files, except for
embedded file streams that have their own crypt filter specifier. If this entry is not
present, and the embedded file stream does not contain a crypt filter specifier, the
stream should be encrypted using the default stream crypt filter specified by StmF.
Unlike strings within the body of the document, those in the encryption
dictionary must be direct objects. The contents of the encryption dictionary are
not encrypted by the usual methods (the algorithm specified by the V entry).
Security handlers are responsible for encrypting any data in the encryption
dictionary that they need to protect.
Note: Document creators have two choices if the encryption methods and syntax
provided by PDF are not sufficient for their needs: they can provide an alternate se-
curity handler or they can encrypt whole PDF documents themselves, not making
use of PDF security.
3.5.1
General Encryption Algorithm
The following algorithms are used when encrypting data in a PDF file:
• A proprietary encryption algorithm known as RC4. RC4 is a symmetric stream
cipher: the same algorithm is used for both encryption and decryption, and the
algorithm does not change the length of the data.
Note: RC4 is a copyrighted, proprietary algorithm of RSA Security, Inc. Adobe
Systems has licensed this algorithm for use in its Acrobat products. Independent
software vendors may be required to license RC4 to develop software that encrypts
or decrypts PDF documents. For further information, visit the RSA Web site at
< http://www.rsasecurity.com > or send e-mail to < products@rsasecurity.com >.
• The AES (Advanced Encryption Standard) algorithm (beginning with PDF
1.6). AES is a symmetric block cipher: the same algorithm is used for both en-
cryption and decryption, and the length of the data when encrypted is rounded
up to a multiple of the block size, which is fixed in this implementation to al-
119
SECTION 3.5
Encryption
ways be 16 bytes, as specified in FIPS 197, Advanced Encryption Standard
(AES); see the Bibliography).
Strings and streams encrypted with AES use a padding scheme that is de-
scribed in Internet RFC 2898, PKCS #5: Password-Based Cryptography Specifi-
cation Version 2.0; see the Bibliography. For an original message length of M,
the pad consists of 16 - (M mod 16) bytes whose value is also 16 - (M mod 16).
For example, a 9-byte message has a pad of 7 bytes, each with the value 0x07.
The pad can be unambiguously removed to determine the original message
length when decrypting. Note that the pad is present when M is evenly divisible
by 16; it contains 16 bytes of 0x10.
PDF’s standard encryption methods also make use of the MD5 message-digest
algorithm for key generation purposes (described in Internet RFC 1321, The
MD5 Message-Digest Algorithm; see the Bibliography).
The encryption of data in a PDF file is based on the use of an encryption key
computed by the security handler. Different security handlers compute the
encryption key using their own mechanisms. Regardless of how the key is
computed, its use in the encryption of data is always the same (see Algorithm
3.1). Because the RC4 algorithm and AES algorithms are symmetric, this same
sequence of steps can be used both to encrypt and to decrypt data.
Algorithm 3.1 Encryption of data using the RC4 or AES algorithms
1.
Obtain the object number and generation number from the object identifier of the
string or stream to be encrypted (see Section 3.2.9, “Indirect Objects”). If the
string is a direct object, use the identifier of the indirect object containing it.
2.
Treating the object number and generation number as binary integers, extend the
original n-byte encryption key to n + 5 bytes by appending the low-order 3 bytes
of the object number and the low-order 2 bytes of the generation number in that
order, low-order byte first. (n is 5 unless the value of V in the encryption dictio-
nary is greater than 1, in which case n is the value of Length divided by 8.)
If using the AES algorithm, extend the encryption key an additional 4 bytes by
adding the value "sAlT", which corresponds to the hexadecimal values 0x73, 0x41,
0x6C, 0x54. (This addition is done for backward compatibility and is not intended
to provide additional security.)
3.
Initialize the MD5 hash function and pass the result of step 2 as input to this func-
tion.
120
CHAPTER 3
Syntax
4.
Use the first (n + 5) bytes, up to a maximum of 16, of the output from the MD5
hash as the key for the RC4 or AES symmetric key algorithms, along with the
string or stream data to be encrypted.
If using the AES algorithm, the Cipher Block Chaining (CBC) mode, which re-
quires an initialization vector, is used. The block size parameter is set to 16 bytes,
and the initialization vector is a 16-byte random number that is stored as the first
16 bytes of the encrypted stream or string.
The output is the encrypted data to be stored in the PDF file.
Stream data is encrypted after applying all stream encoding filters and is
decrypted before applying any stream decoding filters. The number of bytes to be
encrypted or decrypted is given by the Length entry in the stream dictionary.
Decryption of strings (other than those in the encryption dictionary) is done
after escape-sequence processing and hexadecimal decoding as appropriate to the
string representation described in Section 3.2.3, “String Objects.”
3.5.2
Standard Security Handler
PDF’s standard security handler allows access permissions and up to two
passwords to be specified for a document: an owner password and a user
password. An application’s decision to encrypt a document is based on whether
the user creating the document specifies any passwords or access restrictions (for
example, in a security settings dialog box that the user can invoke before saving
the PDF file). If so, the document is encrypted, and the permissions and
information required to validate the passwords are stored in the encryption
dictionary. (An application may also create an encrypted document without any
user interaction if it has some other source of information about what passwords
and permissions to use.)
If a user attempts to open an encrypted document that has a user password, the
application should prompt for a password. Correctly supplying either password
enables the user to open the document, decrypt it, and display it on the screen. If
the document does not have a user password, no password is requested; the
application can simply open, decrypt, and display the document. Whether
additional operations are allowed on a decrypted document depends on which
password (if any) was supplied when the document was opened and on any
access restrictions that were specified when the document was created:
• Opening the document with the correct owner password (assuming it is not the
same as the user password) allows full (owner) access to the document. This
121
SECTION 3.5
Encryption
unlimited access includes the ability to change the document’s passwords and
access permissions.
• Opening the document with the correct user password (or opening a docu-
ment that does not have a user password) allows additional operations to be
performed according to the user access permissions specified in the docu-
ment’s encryption dictionary.
Access permissions are specified in the form of flags corresponding to the various
operations, and the set of operations to which they correspond depends on the
security handler’s revision number (also stored in the encryption dictionary). If
the revision number is 2 or greater, the operations to which user access can be
controlled are as follows:
• Modifying the document’s contents
• Copying or otherwise extracting text and graphics from the document, includ-
ing extraction for accessibility purposes (that is, to make the contents of the
document accessible through assistive technologies such as screen readers or
Braille output devices; see Section 10.8, “Accessibility Support”)
• Adding or modifying text annotations (see “Text Annotations” on page 621)
and interactive form fields (Section 8.6, “Interactive Forms”)
• Printing the document
If the security handler’s revision number is 3 or greater, user access to the
following operations can be controlled more selectively:
• Filling in forms (that is, filling in existing interactive form fields) and signing
the document (which amounts to filling in existing signature fields, a type of
interactive form field).
• Assembling the document: inserting, rotating, or deleting pages and creating
navigation elements such as bookmarks or thumbnail images (see Section 8.2,
“Document-Level Navigation”).
• Printing to a representation from which a faithful digital copy of the PDF con-
tent could be generated. Disallowing such printing may result in degradation of
output quality (a feature implemented as “Print As Image” in Acrobat).
In addition, revisions 3 and greater enable the extraction of text and graphics (in
support of accessibility to users with disabilities or for other purposes) to be
controlled separately.
122
CHAPTER 3
Syntax
If revision 4 is specified, the standard security handler supports crypt filters (see
Section 3.5.4, “Crypt Filters”). The support is limited to the Identity crypt filter
(see Table 3.23) and crypt filters named StdCF whose dictionaries contain a CFM
value of V2 or AESV2 and an AuthEvent value of DocOpen.
Note: Once the document has been opened and decrypted successfully, the applica-
tion has access to the entire contents of the document. There is nothing inherent in
PDF encryption that enforces the document permissions specified in the encryption
dictionary. It is up to the implementors of PDF consumer applications to respect the
intent of the document creator by restricting user access to an encrypted PDF file ac-
cording to the permissions contained in the file.
Note: PDF 1.5 introduces a set of access permissions that do not require the docu-
ment to be encrypted; see Section 8.7.3, “Permissions.”
Standard Encryption Dictionary
Table 3.19 shows the encryption dictionary entries for the standard security
handler (in addition to those in Table 3.18).
TABLE 3.19 Additional encryption dictionary entries for the standard security handler
KEY
TYPE
VALUE
R
number
(Required) A number specifying which revision of the standard security handler
should be used to interpret this dictionary:
• 2 if the document is encrypted with a V value less than 2 (see Table 3.18) and
does not have any of the access permissions set (by means of the P entry, below)
that are designated “Revision 3 or greater” in Table 3.20
• 3 if the document is encrypted with a V value of 2 or 3, or has any “Revision 3
or greater” access permissions set
• 4 if the document is encrypted with a V value of 4
O
string
(Required) A 32-byte string, based on both the owner and user passwords, that is
used in computing the encryption key and in determining whether a valid owner
password was entered. For more information, see “Encryption Key Algorithm” on
page 124 and “Password Algorithms” on page 126.
123
SECTION 3.5
Encryption
KEY
TYPE
VALUE
U
string
(Required) A 32-byte string, based on the user password, that is used in determin-
ing whether to prompt the user for a password and, if so, whether a valid user or
owner password was entered. For more information, see “Password Algorithms”
on page 126.
P
integer
(Required) A set of flags specifying which operations are permitted when the doc-
ument is opened with user access (see Table 3.20).
EncryptMetadata boolean
(Optional; meaningful only when the value of V is 4; PDF 1.5) Indicates whether
the document-level metadata stream (see Section 10.2.2, “Metadata Streams”) is
to be encrypted. Applications should respect this value.
Default value: true.
The values of the O and U entries in this dictionary are used to determine
whether a password entered when the document is opened is the correct owner
password, user password, or neither.
The value of the P entry is an unsigned 32-bit integer containing a set of flags
specifying which access permissions should be granted when the document is
opened with user access. Table 3.20 shows the meanings of these flags. Bit
positions within the flag word are numbered from 1 (low-order) to 32 (high-
order). A 1 bit in any position enables the corresponding access permission.
Which bits are meaningful, and in some cases how they are interpreted, depends
on the security handler’s revision number
(specified in the encryption
dictionary’s R entry).
Note: PDF integer objects are represented internally in signed twos-complement
form. Since all the reserved high-order flag bits in the encryption dictionary’s P val-
ue are required to be 1, the value must be specified as a negative integer. For exam-
ple, assuming revision 2 of the security handler, the value -44 permits printing and
copying but disallows modifying the contents and annotations.
TABLE 3.20 User access permissions
BIT POSITION
MEANING
1-2
Reserved; must be 0.
3
(Revision 2) Print the document.
(Revision 3 or greater) Print the document (possibly not at the high-
est quality level, depending on whether bit 12 is also set).
124
CHAPTER 3
Syntax
BIT POSITION
MEANING
4
Modify the contents of the document by operations other than
those controlled by bits 6, 9, and 11.
5
(Revision 2) Copy or otherwise extract text and graphics from the
document, including extracting text and graphics (in support of ac-
cessibility to users with disabilities or for other purposes).
(Revision 3 or greater) Copy or otherwise extract text and graphics
from the document by operations other than that controlled by bit
10.
6
Add or modify text annotations, fill in interactive form fields, and,
if bit 4 is also set, create or modify interactive form fields (including
signature fields).
7-8
Reserved; must be 1.
9
(Revision 3 or greater) Fill in existing interactive form fields (includ-
ing signature fields), even if bit 6 is clear.
10
(Revision 3 or greater) Extract text and graphics (in support of ac-
cessibility to users with disabilities or for other purposes).
11
(Revision 3 or greater) Assemble the document (insert, rotate, or de-
lete pages and create bookmarks or thumbnail images), even if bit 4
is clear.
12
(Revision 3 or greater) Print the document to a representation from
which a faithful digital copy of the PDF content could be generated.
When this bit is clear (and bit 3 is set), printing is limited to a low-
level representation of the appearance, possibly of degraded quality.
(See implementation note 25 in Appendix H.)
13-32
(Revision 3 or greater) Reserved; must be 1.
Encryption Key Algorithm
As noted earlier, one function of a security handler is to generate an encryption
key for use in encrypting and decrypting the contents of a document. Given a
password string, the standard security handler computes an encryption key as
shown in Algorithm 3.2.
125
SECTION 3.5
Encryption
Algorithm 3.2 Computing an encryption key
1.
Pad or truncate the password string to exactly 32 bytes. If the password string is
more than 32 bytes long, use only its first 32 bytes; if it is less than 32 bytes long,
pad it by appending the required number of additional bytes from the beginning
of the following padding string:
< 28 BF 4E 5E 4E 75 8A 41 64 00 4E 56 FF FA 01 08
2E 2E 00 B6 D0 68 3E 80 2F 0C A9 FE 64 53 69 7A
>
That is, if the password string is n bytes long, append the first 32 − n bytes of the
padding string to the end of the password string. If the password string is empty
(zero-length), meaning there is no user password, substitute the entire padding
string in its place.
2.
Initialize the MD5 hash function and pass the result of step 1 as input to this func-
tion.
3.
Pass the value of the encryption dictionary’s O entry to the MD5 hash function.
(Algorithm 3.3 shows how the O value is computed.)
4.
Treat the value of the P entry as an unsigned 4-byte integer and pass these bytes to
the MD5 hash function, low-order byte first.
5.
Pass the first element of the file’s file identifier array (the value of the ID entry in
the document’s trailer dictionary; see Table 3.13 on page 97) to the MD5 hash
function. (See implementation note 26 in Appendix H.)
6.
(Revision 4 or greater) If document metadata is not being encrypted, pass 4 bytes
with the value 0xFFFFFFFF to the MD5 hash function.
7.
Finish the hash.
8.
(Revision 3 or greater) Do the following 50 times: Take the output from the previ-
ous MD5 hash and pass the first n bytes of the output as input into a new MD5
hash, where n is the number of bytes of the encryption key as defined by the value
of the encryption dictionary’s Length entry.
9.
Set the encryption key to the first n bytes of the output from the final MD5 hash,
where n is always 5 for revision 2 but, for revision 3 or greater, depends on the val-
ue of the encryption dictionary’s Length entry.
This
algorithm, when applied to the user password string, produces the
encryption key used to encrypt or decrypt string and stream data according to
Algorithm 3.1 on page 119. Parts of this algorithm are also used in the algorithms
described below.
Большое спасибо!
Ваше мнение очень важно для нас.
Нет комментариевНе стесняйтесь поделиться с нами вашим ценным мнением.
Текст