PDF Reference sixth edition, Adobe Portable Document Format Version 1.7 (book 2) — page 9
923
SECTION 10.7
Tagged PDF
KEY
TYPE
VALUE
StartIndent
number
(Optional; inheritable) The distance from the start edge of the reference area
to that of the BLSE, measured in default user space units in the inline-pro-
gression direction. This attribute applies only to structure elements with a
Placement attribute of Block or Start (see “General Layout Attributes” on page
917). The attribute is disregarded for elements with other Placement values.
Default value: 0.
Note: A negative value for this attribute places the start edge of the BLSE out-
side that of the reference area. The results are implementation-dependent and
may not be supported by all Tagged PDF consumer applications or export
formats.
Note: If a structure element with a StartIndent attribute is placed adjacent to a
floating element with a Placement attribute of Start, the actual value used for
the element’s starting indent is its own StartIndent attribute or the inline extent
of the adjacent floating element, whichever is greater. This value may be further
adjusted by the element’s TextIndent attribute, if any.
EndIndent
number
(Optional; inheritable) The distance from the end edge of the BLSE to that of
the reference area, measured in default user space units in the inline-progres-
sion direction. This attribute applies only to structure elements with a
Placement attribute of Block or End (see “General Layout Attributes” on page
917). The attribute is disregarded for elements with other Placement values.
Default value: 0.
Note: A negative value for this attribute places the end edge of the BLSE outside
that of the reference area. The results are implementation-dependent and may
not be supported by all Tagged PDF consumer applications or export formats.
Note: If a structure element with an EndIndent attribute is placed adjacent to a
floating element with a Placement attribute of End, the actual value used for the
element’s ending indent is its own EndIndent attribute or the inline extent of the
adjacent floating element, whichever is greater.
TextIndent
number
(Optional; inheritable; applies only to some BLSEs, as described below) The ad-
ditional distance, measured in default user space units in the inline-progres-
sion direction, from the start edge of the BLSE, as specified by StartIndent
(above), to that of the first line of text. A negative value indicates a hanging
indent. Default value: 0.
This attribute applies only to paragraphlike BLSEs and those of structure
types Lbl (Label), LBody (List body), TH (Table header), and TD (Table data),
provided that they contain content other than nested BLSEs.
924
CHAPTER 10
Document Interchange
KEY
TYPE
VALUE
TextAlign
name
(Optional; inheritable; applies only to BLSEs containing text) The alignment,
in the inline-progression direction, of text and other content within lines of
the BLSE:
Start
Aligned with the start edge.
Center
Centered between the start and end edges.
End
Aligned with the end edge.
Justify
Aligned with both the start and end edges, with internal
spacing within each line expanded, if necessary, to achieve
such alignment. The last (or only) line is aligned with the
start edge only.
Default value: Start.
BBox
rectangle
(Optional for Annot; required for any figure or table appearing in its entirety on
a single page; not inheritable). An array of four numbers in default user space
units giving the coordinates of the left, bottom, right, and top edges, respec-
tively, of the element’s bounding box (the rectangle that completely encloses
its visible content). This attribute applies to any element that lies on a single
page and occupies a single rectangle.
Width
number
(Optional; not inheritable; illustrations, tables, table headers, and table cells
or name
only; strongly recommended for table cells) The width of the element’s content
rectangle (see “Content and Allocation Rectangles” on page 930), measured
in default user space units in the inline-progression direction. This attribute
applies only to elements of structure type Figure, Formula, Form, Table, TH
(Table header), or TD (Table data).
The name Auto in place of a numeric value indicates that no specific width
constraint is to be imposed; the element’s width is determined by the intrinsic
width of its content. Default value: Auto.
Height
number
(Optional; not inheritable; illustrations, tables, table headers, and table cells
or name
only) The height of the element’s content rectangle (see “Content and Alloca-
tion Rectangles” on page 930), measured in default user space units in the
block-progression direction. This attribute applies only to elements of struc-
ture type Figure, Formula, Form, Table, TH (Table header), or TD (Table data).
The name Auto in place of a numeric value indicates that no specific height
constraint is to be imposed; the element’s height is determined by the intrin-
sic height of its content. Default value: Auto.
925
SECTION 10.7
Tagged PDF
KEY
TYPE
VALUE
BlockAlign
name
(Optional; inheritable; table cells only) The alignment, in the block-progres-
sion direction, of content within the table cell:
Before
Before edge of the first child’s allocation rectangle aligned
with that of the table cell’s content rectangle.
Middle
Children centered within the table cell. The distance between
the before edge of the first child’s allocation rectangle and
that of the table cell’s content rectangle is the same as the
distance between the after edge of the last child’s allocation
rectangle and that of the table cell’s content rectangle.
After
After edge of the last child’s allocation rectangle aligned with
that of the table cell’s content rectangle.
Justify
Children aligned with both the before and after edges of the
table cell’s content rectangle. The first child is placed as
described above for Before and the last child as described for
After, with equal spacing between the children. If there is only
one child, it is aligned with the before edge only, as for Before.
This attribute applies only to elements of structure type TH (Table header) or
TD (Table data) and controls the placement of all BLSEs that are children of
the given element. The table cell’s content rectangle (see “Content and Allo-
cation Rectangles” on page 930) becomes the reference area for all of its
descendants. Default value: Before.
InlineAlign
name
(Optional; inheritable; table cells only) The alignment, in the inline-progres-
sion direction, of content within the table cell:
Start
Start edge of each child’s allocation rectangle aligned with
that of the table cell’s content rectangle.
Center
Each child centered within the table cell. The distance
between the start edges of the child’s allocation rectangle and
the table cell’s content rectangle is the same as the distance
between their end edges.
End
End edge of each child’s allocation rectangle aligned with that
of the table cell’s content rectangle.
This attribute applies only to elements of structure type TH (Table header) or
TD (Table data) and controls the placement of all BLSEs that are children of
the given element. The table cell’s content rectangle (see “Content and Allo-
cation Rectangles” on page 930) becomes the reference area for all of its
descendants. Default value: Start.
926
CHAPTER 10
Document Interchange
KEY
TYPE
VALUE
TBorderStyle
name or
(Optional; inheritable; PDF 1.5) The style of the border drawn on each edge of
array
a table cell. Possible values are the same as those specified for BorderStyle
(see Table 10.30). If both TBorderStyle and BorderStyle apply to a given table
cell, BorderStyle supersedes TBorderStyle. Default value: None.
TPadding
integer or
(Optional; inheritable; PDF 1.5) Specifies an offset to account for the separa-
array
tion between the table cell’s content rectangle and the surrounding border
(see “Content and Allocation Rectangles” on page 930). If both TPadding and
Padding apply to a given table cell, Padding supersedes TPadding. A positive
value enlarges the background area; a negative value trims it, possibly allow-
ing the border to overlap the element’s text or graphic. The value is either a
single number representing the width of the padding, in default user space
units, that applies to all four edges of the table cell or a 4-entry array repre-
senting the padding width for the before edge, after edge, start edge, and end
edge, respectively, of the content rectangle. Default value: 0.
Layout Attributes for ILSEs
The attributes described in Table 10.32 apply to inline-level structure elements
(ILSEs). They may also be specified for a block-level element (BLSE) and apply to
any content items that are its immediate children.
TABLE 10.32 Standard layout attributes specific to inline-level structure elements
KEY
TYPE
VALUE
BaselineShift
number
(Optional; not inheritable) The distance, in default user space units, by
which the element’s baseline is shifted relative to that of its parent element.
The shift direction is the opposite of the block-progression direction spec-
ified by the prevailing WritingMode attribute (see “General Layout Attri-
butes” on page 917). Thus, positive values shift the baseline toward the
before edge and negative values toward the after edge of the reference area
(upward and downward, respectively, in Western writing systems). Default
value: 0.
The shifted element might be a superscript, a subscript, or an inline graph-
ic. The shift applies to the element, its content, and all of its descendants.
Any further baseline shift applied to a child of this element is measured
relative to the shifted baseline of this (parent) element.
927
SECTION 10.7
Tagged PDF
KEY
TYPE
VALUE
LineHeight
number
(Optional; inheritable) The element’s preferred height, measured in default
or name
user space units in the block-progression direction. The height of a line is
determined by the largest LineHeight value for any complete or partial
ILSE that it contains.
The name Normal or Auto in place of a numeric value indicates that no
specific height constraint is to be imposed. The element’s height is set to a
reasonable value based on the content’s font size:
Normal
Adjust the line height to include any nonzero value
specified for BaselineShift (see below).
Auto
Do not adjust for the value of BaselineShift.
Default value: Normal.
This attribute applies to all ILSEs (including implicit ones) that are chil-
dren of this element or of its nested ILSEs, if any. It does not apply to nest-
ed BLSEs.
Note: When translating to a specific export format, the values Normal and
Auto, if specified, are used directly if they are available in the target format.
The meaning of the term “reasonable value,” used above, is left to the con-
sumer application to determine. It can be assumed to be approximately 1.2
times the font size, but this value may vary depending on the export format.
In the absence of a numeric value for LineHeight or an explicit value for the
font size, a reasonable method of calculating the line height from the infor-
mation in a Tagged PDF file is to find the difference between the associated
font’s Ascent and Descent values (see Section 5.7, “Font Descriptors”), map it
from glyph space to default user space (see Section 5.3.3, “Text Space De-
tails”), and use the maximum resulting value for any character in the line.
TextDecorationColor
array
(Optional; inheritable; PDF 1.5) The color to be used for drawing text dec-
orations. The value is an array of three numbers in the range 0.0 to 1.0,
representing the red, green, and blue values, respectively, of an RGB color
space. If this attribute is not specified, the border color for this element is
the current fill color in effect at the start of its associated content.
TextDecorationThickness
number
(Optional; inheritable; PDF 1.5) The thickness of each line drawn as part of
the text decoration. The value is a non-negative number in default user
space units representing the thickness (0 is interpreted as the thinnest pos-
sible line). If this attribute is not specified, it is derived from the current
stroke thickness in effect at the start of the element’s associated content,
transformed into default user space units.
928
CHAPTER 10
Document Interchange
KEY
TYPE
VALUE
TextDecorationType
name
(Optional; not inheritable) The text decoration, if any, to be applied to the
element’s text.
None
No text decoration
Underline A line below the text
Overline
A line above the text
LineThrough A line through the middle of the text
Default value: None.
This attribute applies to all text content items that are children of this ele-
ment or of its nested ILSEs, if any. The attribute does not apply to nested
BLSEs or to content items other than text.
Note: The color, position, and thickness of the decoration should be uniform
across all children, regardless of changes in color, font size, or other varia-
tions in the content’s text characteristics.
RubyAlign
name
(Optional; inheritable; PDF 1.5) The justification of the lines within a ruby
assembly:
Start
The content is to be aligned on the start edge in the inline-
progression direction.
Center
The content is to be centered in the inline-progression
direction.
End
The content is to be aligned on the end edge in the inline-
progression direction.
Justify
The content is to be expanded to fill the available width in
the inline-progression direction.
Distribute The content is to be expanded to fill the available width in
the inline-progression direction. However, some space is
also inserted at the start edge and end edge of the text.
Normally, the spacing is distributed using a
1:2:1
(start:infix:end) ratio. It is changed to a 0:1:1 ratio if the
ruby appears at the start of a text line or to a 1:1:0 ratio if
the ruby appears at the end of the text line.
Default value: Distribute.
This attribute may be specified on the RB and RT elements. When a ruby is
formatted, the attribute is applied to the shorter line of these two elements.
(If the RT element has a shorter width than the RB element, the RT element
is aligned as specified in its RubyAlign attribute.)
929
SECTION 10.7
Tagged PDF
KEY
TYPE
VALUE
RubyPosition
name
(Optional; inheritable; PDF 1.5) The placement of the RT structure element
relative to the RB element in a ruby assembly:
Before
The RT content is to be aligned along the before edge of
the element.
After
The RT content is to be aligned along the after edge of the
element.
Warichu
The RT and associated RP elements are to be formatted as a
warichu, following the RB element.
Inline
The RT and associated RP elements are to be formatted as a
parenthesis comment, following the RB element.
Default value: Before.
GlyphOrientationVertical
name
(Optional; inheritable; PDF 1.5) Specifies the orientation of glyphs when
the inline-progression direction is top to bottom or bottom to top.
This attribute may take one of the following values:
angle
A number representing the clockwise rotation in degrees of
the top of the glyphs relative to the top of the reference area.
Must be a multiple of 90 degrees between -180 and +360.
Auto
Specifies a default orientation for text, depending on whether
it is fullwidth (as wide as it is high). Fullwidth Latin and
fullwidth ideographic text
(excluding ideographic
punctuation) is set with an angle of
0. Ideographic
punctuation and other ideographic characters having
alternate horizontal and vertical forms use the vertical form
of the glyph. Non-fullwidth text is set with an angle of 90.
Default value: Auto.
This attribute is used most commonly to differentiate between the pre-
ferred orientation of alphabetic (non-ideographic) text in vertically writ-
ten Japanese documents
(Auto or
90) and the orientation of the
ideographic characters and/or alphabetic (non-ideographic) text in west-
ern signage and advertising (90).
It affects both the alignment and width of the glyphs. If a glyph is perpen-
dicular to the vertical baseline, its horizontal alignment point is aligned
with the alignment baseline for the script to which the glyph belongs. The
width of the glyph area is determined from the horizontal width font char-
acteristic for the glyph.
930
CHAPTER 10
Document Interchange
Content and Allocation Rectangles
As defined in Section 10.7.2, “Basic Layout Model,” an element’s content rectangle
is an enclosing rectangle derived from the shape of the element’s content, which
defines the bounds used for the layout of any included child elements. The
allocation rectangle includes any additional borders or spacing surrounding the
element, affecting how it is positioned with respect to adjacent elements and the
enclosing content rectangle or reference area.
The exact definition of the content rectangle depends on the element’s structure
type:
• For a table cell (structure type TH or TD), the content rectangle is determined
from the bounding box of all graphics objects in the cell’s content, taking into
account any explicit bounding boxes (such as the BBox entry in a form XOb-
ject). This implied size can be explicitly overridden by the cell’s Width and
Height attributes. The cell’s height is further adjusted to equal the maximum
height of any cell in its row; its width is adjusted to the maximum width of any
cell in its column.
• For any other BLSE, the height of the content rectangle is the sum of the heights
of all BLSEs it contains, plus any additional spacing adjustments between these
elements.
• For an ILSE that contains text, the height of the content rectangle is set by the
LineHeight attribute. The width is determined by summing the widths of the
contained characters, adjusted for any indents, letter spacing, word spacing, or
line-end conditions.
• For an ILSE that contains an illustration or table, the content rectangle is deter-
mined from the bounding box of all graphics objects in the content, taking into
account any explicit bounding boxes (such as the BBox entry in a form XOb-
ject). This implied size can be explicitly overridden by the element’s Width and
Height attributes.
• For an ILSE that contains a mixture of elements, the height of the content rect-
angle is determined by aligning the child objects relative to one another based
on their text baseline (for text ILSEs) or end edge (for non-text ILSEs), along
with any applicable BaselineShift attribute (for all ILSEs), and finding the ex-
treme top and bottom for all elements.
Note: Some applications may apply this process to all elements within the block;
others may apply it on a line-by-line basis.
931
SECTION 10.7
Tagged PDF
The allocation rectangle is derived from the content rectangle in a way that also
depends on the structure type:
• For a BLSE, the allocation rectangle is equal to the content rectangle with its
before and after edges adjusted by the element’s SpaceBefore and SpaceAfter
attributes, if any, but with no changes to the start and end edges.
• For an ILSE, the allocation rectangle is the same as the content rectangle.
Note: Future versions of Tagged PDF are likely to include additional attributes that
can adjust all four edges of the allocation rectangle for both BLSEs and ILSEs.
Illustration Attributes
Certain additional restrictions arise in connection with particular uses of illustra-
tion elements (structure types Figure, Formula, or Form):
• When an illustration element has a Placement attribute of Block, it must have a
Height attribute with an explicitly specified numerical value (not Auto). This
value is the sole source of information about the illustration’s extent in the
block-progression direction.
• When an illustration element has a Placement attribute of Inline, it must have a
Width attribute with an explicitly specified numerical value (not Auto). This
value is the sole source of information about the illustration’s extent in the
inline-progression direction.
• When an illustration element has a Placement attribute of Inline, Start, or End,
the value of its BaselineShift attribute is used to determine the position of its af-
ter edge relative to the text baseline; BaselineShift is ignored for all other values
of Placement. (An illustration element with a Placement value of Start can be
used to create a dropped capital; one with a Placement value of Inline can be
used to create a raised capital.)
932
CHAPTER 10
Document Interchange
Column Attributes
The attributes described in Table 10.33 apply only to the grouping elements Art,
Sect, and Div (see “Grouping Elements” on page 899). They are used when the
content in the grouping element is divided into columns.
TABLE 10.33 Standard column attributes
KEY
TYPE
VALUE
ColumnCount integer
(Optional; not inheritable; PDF 1.6) The number of columns in the content of the
grouping element. Default value: 1.
ColumnGap
number or
(Optional; not inheritable; PDF 1.6) The desired space between adjacent col-
array
umns, measured in default user space units in the inline-progression direction.
If the value is a number, it specifies the space between all columns. If the value is
an array, it should contain ColumnCount - 1 numbers, representing the space be-
tween the first and second columns, the second and third columns, and so on,
respectively. If there are fewer than ColumnCount - 1 numbers, the last element
specifies all remaining spaces; excess array elements are ignored.
ColumnWidths number or
(Optional; not inheritable; PDF 1.6) The desired width of the columns, measured
array
in default user space units in the inline-progression direction. If the value is a
number, it specifies the width of all columns. If the value is an array, it should
contain ColumnCount numbers, representing the width of each column, in or-
der. If there are fewer than ColumnCount numbers, the last element specifies all
remaining widths; excess array elements are ignored.
List Attribute
The ListNumbering attribute, described in Table 10.34, is carried by an L (List)
element, but controls the interpretation of the Lbl (Label) elements within the
list’s LI (List item) elements (see “List Elements” on page 902). This attribute is de-
fined in attribute objects whose O (owner) entry has the value List (or is one of
the format-specific owner names listed in Table 10.28 on page 914).
933
SECTION 10.7
Tagged PDF
TABLE 10.34 Standard list attribute
KEY
TYPE
VALUE
ListNumbering
name
(Optional; inheritable) The numbering system used to generate the content of
the Lbl (Label) elements in an autonumbered list, or the symbol used to identify
each item in an unnumbered list:
None
No autonumbering; Lbl elements (if present) contain arbitrary
text not subject to any numbering scheme
Disc
Solid circular bullet
Circle
Open circular bullet
Square
Solid square bullet
Decimal
Decimal arabic numerals (1-9, 10-99, … )
UpperRoman Uppercase roman numerals (I, II, III, IV, … )
LowerRoman Lowercase roman numerals (i, ii, iii, iv, … )
UpperAlpha Uppercase letters (A, B, C, … )
LowerAlpha Lowercase letters (a, b, c, … )
Default value: None.
Note: The alphabet used for UpperAlpha and LowerAlpha is determined by the pre-
vailing Lang entry (see Section 10.8.1, “Natural Language Specification”).
Note: The set of possible values may be expanded as Unicode identifies additional
numbering systems.
Note: This attribute is used to allow a content extraction tool to autonumber a list.
However, the Lbl elements within the table should nevertheless contain the resulting
numbers explicitly, so that the document can be reflowed or printed without the
need for autonumbering.
PrintField Attributes
(PDF 1.7) The attributes described in Table 10.35 identify the role of fields in
non-interactive PDF forms. Such forms may have originally contained interactive
fields such as text fields and radio buttons but were then converted into non-in-
teractive PDF files, or they may have been designed to be printed out and filled in
manually. Since the roles of the fields cannot be determined from interactive ele-
ments, the roles are defined using PrintField attributes.
934
CHAPTER 10
Document Interchange
PrintField attributes enable screen readers to identify page content that represents
form fields (radio buttons, check boxes, push buttons, and text fields). These at-
tributes enable the controls in print form fields to be represented in the logical
structure tree and to be presented to assistive technology as if they were read-only
interactive fields.
TABLE 10.35 PrintField attributes
KEY
TYPE
VALUE
Role
name
(Optional; not inheritable) The type of form field represented by this graphic.
The following values are defined:
rb
Radio button
cb
Check box
pb
Push button
tv
Text-value field
The tv role is used for interactive fields whose values have been converted to text
in the non-interactive document. Examples include text edit fields, numeric
fields, password fields, digital signatures, and combo boxes. The text that is the
value of the field is the content of the Form element (see Table 10.27 on page
912).
Default value: None specified.
checked
name
(Optional; not inheritable) The state of a radio button or check box field. The val-
ue may be on, off (default), or neutral.
Note: Although the case (capitalization) used for this key is unusual, it is still cor-
rect.
Desc
text string
(Optional; not inheritable) The alternate name of the field, similar to the value
supplied in the TU entry of the field dictionary for interactive fields
(see
Table 8.69).
Table Attributes
Table attributes are defined as attribute objects whose O (owner) entry has the
value Table or is one of the format-specific owner names listed in Table 10.28 on
page 914. Table 10.36 lists the standard table attributes.
935
SECTION 10.8
Accessibility Support
TABLE 10.36 Standard table attributes
KEY
TYPE
VALUE
RowSpan
integer
(Optional; not inheritable) The number of rows in the enclosing table that are
spanned by the cell. The cell expands by adding rows in the block-progression
direction specified by the table’s WritingMode attribute. Default value: 1.
This entry applies only to table cells that have structure types TH or TD or that
are role mapped to structure types TH or TD (see “Table Elements” on page 883).
ColSpan
integer
(Optional; not inheritable) The number of columns in the enclosing table that are
spanned by the cell. The cell expands by adding columns in the inline-progres-
sion direction specified by the table’s WritingMode attribute. Default value: 1.
This entry applies only to table cells that have structure types TH or TD or that
are role mapped to structure types TH or TD (see “Table Elements” on page 883).
Headers
array
(Optional; not inheritable; PDF 1.5) An array of byte strings, where each string is
the element identifier (see the ID entry in Table 10.10) for a TH structure element
that is a header associated with this cell.
This attribute may apply to header cells (TH) as well as data cells (TD) (see “Table
Elements” on page 883). Therefore, the headers associated with any cell are those
in its Headers array plus those in the Headers array of any TH cells in that array,
and so on recursively.
Scope
name
(Optional; not inheritable; PDF 1.5) A name with one of the values Row, Column,
or Both. This attribute applies only to TH elements (see “Table Elements” on page
883) and indicates whether the header cell applies to the rest of the cells in the
row that contains it, the column that contains it, or both the row and the column
that contain it.
Summary
text string
(Optional; not inheritable; PDF 1.7) A summary of the table’s purpose and struc-
ture, for use in non-visual rendering such as speech or braille. This entry applies
only to Table structure elements (see “Table Elements” on page 903).
10.8
Accessibility Support
PDF includes several facilities in support of accessibility of documents to users
with disabilities. In particular, many visually computer users with visual impair-
ments use screen readers to read documents aloud. To enable proper vocaliza-
936
CHAPTER 10
Document Interchange
tion, either through a screen reader or by some more direct invocation of a text-
to-speech engine, PDF supports the following features:
• Specifying the natural language used for text in a PDF document—for example,
as English or Spanish, or used to hide or reveal optional content (see Section
10.8.1, “Natural Language Specification”)
• Providing textual descriptions for images or other items that do not translate
naturally into text (Section 10.8.2, “Alternate Descriptions”), or replacement
text for content that does translate into text but is represented in a nonstandard
way (such as with a ligature or illuminated character; see Section 10.8.3,
“Replacement Text”)
• Specifying the expansion of abbreviations or acronyms (Section 10.8.4, “Ex-
pansion of Abbreviations and Acronyms”)
The core of this support lies in the ability to determine the logical order of con-
tent in a PDF document, independently of the content’s appearance or layout,
through logical structure and Tagged PDF, as described under “Page Content
Order” on page 889. An accessibility application can extract the content of a doc-
ument for presentation to users with disabilities by traversing the structure hier-
archy and presenting the contents of each node. For this reason, producers of
PDF files must ensure that all information in a document is reachable by means
of the structure hierarchy, and they are strongly encouraged to use the facilities
described in this section.
Note: Text can be extracted from Tagged PDF documents and examined or reused
for purposes other than accessibility; see Section 10.7, “Tagged PDF.”
Additional guidelines for accessibility support of content published on the Web
can be found in the W3C document Web Content Accessibility Guidelines and the
documents it points to (see the Bibliography).
10.8.1
Natural Language Specification
Natural language can be specified for text in a document or for optional content.
The natural language used for text in a document is determined in a hierarchical
fashion, based on whether an optional Lang entry (PDF 1.4) is present in any of
several possible locations. At the highest level, the document’s default language
(which applies to both text strings and text within content streams) can be speci-
937
SECTION 10.8
Accessibility Support
fied by a Lang entry in the document catalog (see Section 3.6.1, “Document Cat-
alog”). Below this, the language can be specified for the following items:
• Structure elements of any type (see Section 10.6.1, “Structure Hierarchy”),
through a Lang entry in the structure element dictionary.
• Marked-content sequences that are not in the structure hierarchy (see Section
10.5, “Marked Content”), through a Lang entry in a property list attached to the
marked-content sequence with a Span tag. (Although Span is also a standard
structure type, as described under “Inline-Level Structure Elements” on page
905, its use here is entirely independent of logical structure.)
The natural language used for optional content allows content to be hidden or re-
vealed, based on the Lang entry (PDF 1.5) in the Language dictionary of an op-
tional content usage dictionary.
The following sections provide details on the value of the Lang entry and the
hierarchical manner in which the language for text in a document is determined.
Note: Text strings encoded in Unicode may include an escape sequence or language
tag indicating the language of the text and overriding the prevailing Lang entry (see
Section , “Text String Type”).
Language Identifiers
Certain language-related dictionary entries are text strings that specify language
identifiers. Such text strings appear as Lang entries in the following structures or
dictionaries:
• Document catalog, structure element dictionary, or property list
• Optional content usage dictionary’s Language dictionary, although the hierar-
chical issues described in “Language Specification Hierarchy,” below do not ap-
ply to this entry
A language identifier can either be the empty text string, to indicate that the lan-
guage is unknown, or a Language-Tag as defined in RFC 3066, Tags for the Identi-
fication of Languages. This section provides an informal summary of RFC 3066.
This syntax, which is summarized below, is also used to identify languages in
XML, according to the W3C document Extensible Markup Language (XML) 1.1;
see the Bibliography for more information about these documents. An empty
string indicates that the language is unknown.
938
CHAPTER 10
Document Interchange
Language identifiers can be based on codes defined by the International Organi-
zation for Standardization in ISO 639 and ISO 3166 (see the Bibliography) or reg-
istered with the Internet Assigned Numbers Authority (IANA, whose Web site is
located at < http://iana.org/ >), or they can include codes created for private use. A
language identifier consists of a primary code optionally followed by one or more
subcodes (each preceded by a hyphen). The primary code can be any of the fol-
lowing:
• A 2-character ISO 639 language code—for example, en for English or es for
Spanish
• The letter i, designating an IANA-registered identifier
• The letter x, for private use
The first subcode can be a 2-character ISO 3166 country code, as in en-US, or a
3- to 8-character subcode registered with IANA, as in en-cockney or i-cherokee
(except in private identifiers, for which subcodes are not registered). Subcodes
beyond the first can be any that have been registered with IANA.
Although language codes are commonly represented using lowercase letters and
country codes are commonly represented using uppercase letters, all tags must be
treated as case insensitive.
Language Specification Hierarchy
The Lang entry in the document catalog specifies the natural language for all text
in the document except where overridden by language specifications for struc-
ture elements or for marked-content sequences that are not in the structure hier-
archy (for example, within an entirely unstructured document). Examples in this
section illustrate the hierarchical manner in which the language for text in a doc-
ument is determined.
Example 10.19 shows how a language specified for the document as a whole
could be overridden by one specified for a marked-content sequence within a
page’s content stream, independent of any logical structure. In this case, the Lang
entry in the document catalog (not shown) has the value en-US, meaning U.S. En-
glish, and it is overridden by the Lang property attached (with the Span tag) to
the marked-content sequence Hasta la vista. The Lang property identifies the lan-
guage for this marked content sequence with the value es-MX, meaning Mexican
Spanish.
939
SECTION 10.8
Accessibility Support
Example 10.19
2 0 obj
% Page object
<< /Type /Page
/Contents 3 0 R
% Content stream
…
>>
endobj
3 0 obj
% Page's content stream
<< /Length … >>
stream
BT
( See you later, or as Arnold would say, ) Tj
/Span << /Lang ( es-MX ) >>
% Start of marked-content sequence
BDC
( Hasta la vista . ) Tj
EMC
% End of marked-content sequence
ET
endstream
endobj
Where logical structure is described (by a structure hierarchy) within a docu-
ment, the Lang entry in the document catalog sets the default for the document.
Below that, any language specifications within the structure hierarchy apply in
this order:
• A structure element’s language specification
Note: If a structure element does not have a Lang entry, the element inherits its
language from any parent element that has one.
• Within a structure element, a language specification for a nested structure ele-
ment or marked-content sequence
In Example 10.20, the Lang entry in the structure element dictionary (specifying
English) applies to the marked-content sequence having an MCID (marked-
content identifier) value of 0 within the indicated page’s content stream. However,
nested within that marked-content sequence is another one in which the Lang
property attached with the Span tag (specifying Spanish) overrides the structure
element’s language specification.
Note: This example and the next one below omit required StructParents entries in
the objects used as content items (see “Finding Structure Elements from Content
Items” on page 868).
940
CHAPTER 10
Document Interchange
Example 10.20
1 0 obj
% Structure element
<< /Type /StructElem
/S /P
% Structure type
/P …
% Parent in structure hierarchy
/K << /Type /MCR
/Pg 2 0 R
% Page containing marked-content sequence
/MCID 0
% Marked-content identifier
>>
/Lang ( en-US )
% Language specification for this element
>>
endobj
2 0 obj
% Page object
<< /Type /Page
/Contents 3 0 R
% Content stream
…
>>
endobj
3 0 obj
% Page's content stream
<< /Length … >>
stream
BT
/P << /MCID 0 >>
% Start of marked-content sequence
BDC
( See you later, or as Arnold would say, ) Tj
/Span << /Lang ( es-MX ) >> % Start of nested marked-content sequence
BDC
( Hasta la vista . ) Tj
EMC
% End of nested marked-content sequence
EMC
% End of marked-content sequence
ET
endstream
endobj
If only part of the page content is contained in the structure hierarchy, and the
structured content is nested within nonstructured content to which a different
language specification applies, the structure element’s language specification
takes precedence. In Example 10.21, the page’s content stream consists of a
marked-content sequence that specifies Spanish as its language by means of the
Span tag with a Lang property. Nested within it is content that is part of a struc-
941
SECTION 10.8
Accessibility Support
ture element (indicated by the MCID entry in that property list), and the language
specification that applies to the latter content is that of the structure element,
English.
Example 10.21
1 0 obj
% Structure element
<< /Type /StructElem
/S /P
% Structure type
/P …
% Parent in structure hierarchy
/K << /Type /MCR
/Pg 2 0 R
% Page containing marked-content sequence
/MCID 0
% Marked-content identifier
>>
/Lang ( en-US )
% Language specification for this element
>>
endobj
2 0 obj
% Page object
<< /Type /Page
/Contents 3 0 R
% Content stream
…
>>
endobj
3 0 obj
% Page's content stream
<< /Length … >>
stream
/Span << /Lang ( es-MX ) >>
% Start of marked-content sequence
BDC
( Hasta la vista, ) Tj
/P << /MCID 0 >>
% Start of structured marked-content sequence,
BDC
% to which structure element's language applies
( as Arnold would say. ) Tj
EMC
% End of structured marked-content sequence
EMC
% End of marked-content sequence
endstream
endobj
In other words, a language identifier attached to a marked-content sequence with
the Span tag specifies the language for all text in the sequence except for nested
marked content that is contained in the structure hierarchy (in which case the
structure element’s language applies) and except where overridden by language
specifications for other nested marked content.
942
CHAPTER 10
Document Interchange
Multi-language Text Arrays
A multi-language text array (PDF 1.5) allows multiple text strings to be specified,
each in association with a language identifier. (See the Alt entry in Tables 9.9 and
9.12 for examples of its use.) The array contains pairs of strings:
• The first string in each pair is an ASCII string language identifier. A given lan-
guage identifier may not appear more than once in the array; any unrecognized
language identifier should be ignored. An empty string specifies default text to
be used when no matching language identifier is found in the array.
• The second byte string is text associated with the language.
Example 10.22
[ (en-US) (My vacation) (fr) (mes vacances) ( ) (default text) ]
When a consumer application searches a multi-language text array to find text for
a given language, it should look for an exact (though case-insensitive) match be-
tween the given language’s identifier and the language identifiers in the array. If
no exact match is found, prefix matching is attempted in increasing array order: a
match is declared if the given identifier is a leading, case-insensitive, substring of
an identifier in the array, and the first post-substring character in the array iden-
tifier is a hyphen. For example, given identifier en matches array identifier en-US,
but given identifier en-US matches neither en nor en-GB. If no exact or prefix
match can be found, the default text (if any) should be used.
10.8.2
Alternate Descriptions
PDF documents can be enhanced by providing alternate descriptions for images,
formulas, or other items that do not translate naturally into text. Alternate de-
scriptions are human-readable text that could, for example, be vocalized by a
text-to-speech engine for the benefit of users with visual impairments.
An alternate description can be specified for the following items:
• A structure element (see Section 10.6.1, “Structure Hierarchy”), through an Alt
entry in the structure element dictionary
• (PDF 1.5) A marked-content sequence (see Section 10.5, “Marked Content”),
through an Alt entry in a property list attached to the marked-content sequence
with a Span tag.
943
SECTION 10.8
Accessibility Support
• Any type of annotation (see Section 8.4, “Annotations”) that does not already
have a text representation, through a Contents entry in the annotation dic-
tionary
For annotation types that normally display text, that text (specified in the
Contents entry of the annotation dictionary) is the natural source for vocalization
purposes. For annotation types that do not display text, a Contents entry (PDF
1.4) can optionally be included to specify an alternate description. Sound annota-
tions, which are vocalized by default and therefore need no alternate description
for that purpose, can include a Contents entry specifying a description to be dis-
played in a pop-up window for the benefit of users with hearing impairments.
In addition, an alternate name can be specified for an interactive form field (see
Section 8.6, “Interactive Forms”), to be used in place of the actual field name
wherever the field must be identified in the user interface (such as in error or sta-
tus messages referring to the field). This alternate name, specified in the optional
TU entry of the field dictionary, can be useful for vocalization purposes.
Alternate descriptions are text strings, which may be encoded in either
PDFDocEncoding or Unicode character encoding. As described in Section , “Text
String Type,” Unicode defines an escape sequence for indicating the language of
the text. This mechanism enables the alternate description to change from the
language specified by the prevailing Lang entry (as described in the preceding
section).
When applied to structure elements, the text is considered to be a word or phrase
substitution for the current element. For example, if each of two (or more) ele-
ments in a sequence has an Alt entry in its dictionary, they should be treated as if
a word break is present between them. The same would apply to consecutive
marked-content sequences.
Note: The Alt entry in property lists can be combined with other entries, as shown in
Example 10.23.
Example 10.23
/Span << /Lang (en-us) /Alt (six-point star) >> BDC (✡) Tj EMC
944
CHAPTER 10
Document Interchange
10.8.3
Replacement Text
Just as alternate descriptions can be provided for images and other items that do
not translate naturally into text (as described in the preceding section), replace-
ment text can be specified for content that does translate into text but that is rep-
resented in a nonstandard way. These nonstandard representations might
include, for example, glyphs for ligatures or custom characters, or inline graphics
corresponding to letters in an illuminated manuscript or to dropped capitals.
Replacement text can be specified for the following items:
• A structure element (see Section 10.6.1, “Structure Hierarchy”), by means of
the optional ActualText entry (PDF 1.4) of the structure element dictionary.
• (PDF 1.5) A marked-content sequence (see Section 10.5, “Marked Content”),
through an ActualText entry in a property list attached to the marked-content
sequence with a Span tag.
The ActualText value is not a description but a replacement for the content, pro-
viding text that is equivalent to what a reader with sight would see when viewing
the content. In contrast to the value of Alt, which is considered to be a word or
phrase substitution, the value of ActualText is considered to be a character substi-
tution for the structure element or marked-content sequence. Thus, if each of two
(or more) consecutive structure or marked-content sequences has an ActualText
entry, they should be treated as if no word break is present between them.
The following example shows the use of replacement text to indicate the correct
character content in a case where hyphenation changes the spelling of a word (in
German, up until recent spelling reforms, the word “Drucker” when hyphenated
was rendered as “Druk-” and “ker”).
Example 10.24
(Dru) Tj
/Span
<</Actual Text (c) >>
BDC
(k-) Tj
EMC
(ker) '
Like alternate descriptions (and other text strings), replacement text, if encoded
in Unicode, may include an escape sequence for indicating the language of the
text, overriding the prevailing Lang entry (see Section , “Text String Type”).
945
SECTION 10.8
Accessibility Support
10.8.4
Expansion of Abbreviations and Acronyms
Abbreviations and acronyms can pose a problem for text-to-speech engines.
Sometimes the full pronunciation for an abbreviation can be divined without aid.
For example, a dictionary search will probably reveal that “Blvd.” is pronounced
“boulevard” and that “Ave.” is pronounced “avenue.” However, some abbreviations
are difficult to resolve, as in the sentence “Dr. Healwell works at 123 Industrial
Dr.” For this reason, the expansion of an abbreviation or acronym can be speci-
fied for the following items:
• Marked-content sequences, through an E property (PDF 1.4) in a property list
attached to the sequence with a Span tag, as shown in Example 10.25
• Structure elements, through an E entry (PDF 1.5) in the structure element dic-
tionary
Example 10.25
BT
/Span << /E ( Doctor ) >>
BDC
( Dr. ) Tj
EMC
( Healwell works at 123 Industrial ) Tj
/Span << /E ( Drive ) >>
BDC
( Dr. ) Tj
EMC
ET
The E value (a text string) is considered to be a word or phrase substitution for
the tagged text and therefore should be treated as if a word break separates it from
any surrounding text. Like other text strings, the expansion text, if encoded in
Unicode, may include an escape sequence for indicating the language of the text
(see Section , “Text String Type”).
Some abbreviations or acronyms are conventionally not expanded into words.
For the text “CBS,” for example, either no expansion should be supplied (leaving
its pronunciation up to the text-to-speech engine) or, to be safe, the expansion
“C B S” should be specified.
946
CHAPTER 10
Document Interchange
10.9
Web Capture
Web Capture is a PDF 1.3 feature that allows information from Internet-based or
locally resident HTML, PDF, GIF, JPEG, and ASCII text files to be imported into
a PDF file. This feature is implemented in Acrobat 4.0 and later viewers by a Web
Capture plug-in extension (sometimes called AcroSpider). The information in
the Web Capture data structures enables viewer applications to perform the fol-
lowing operations:
• Save locally and preserve the visual appearance of material from the Web
• Retrieve additional material from the Web and add it to an existing PDF file
• Update or modify existing material previously captured from the Web
• Find source information for material captured from the Web, such as the URL
(if any) from which it was captured
• Find all material in a PDF file that was generated from a given URL
• Find all material in a PDF file that matches a given digital identifier (MD5
hash)
The information needed to perform these operations is recorded in two data
structures in the PDF file:
• The Web Capture information dictionary holds document-level information
related to Web Capture.
• The Web Capture content database keeps track of the material retrieved by Web
Capture and where it came from, enabling Web Capture to avoid downloading
material that is already present in the file.
The following sections provide a detailed overview of these structures. See
Appendix C for information about implementation limits in Web Capture.
Note: The following discussion centers on HTML and GIF files, although Web Cap-
ture handles other file types as well.
10.9.1
Web Capture Information Dictionary
The optional SpiderInfo entry in the document catalog (see Section 3.6.1, “Docu-
ment Catalog”) holds an optional Web Capture information dictionary containing
document-level information related to Web Capture. Table 10.37 shows the con-
tents of this dictionary.
947
SECTION 10.9
Web Capture
TABLE 10.37 Entries in the Web Capture information dictionary
KEY TYPE
VALUE
V
number
(Required) The Web Capture version number. For PDF 1.3, the version number is 1.0.
Note: This value is a single real number, not a major and minor version number. Thus, for
example, a version number of 1.2 would be considered greater than 1.15.
C
array
(Optional) An array of indirect references to Web Capture command dictionaries (see
“Command Dictionaries” on page 957) describing commands that were used in building
the PDF file. The commands appear in the array in the order in which they were executed
in building the file.
10.9.2
Content Database
Web Capture retrieves HTML files from URLs and converts them to PDF. The re-
sulting PDF file may contain the contents of multiple HTML pages. Conversely,
since HTML pages do not have a fixed size, a single HTML page may give rise to
multiple PDF pages. To keep track of the correspondences, Web Capture main-
tains a content database that maps URLs and digital identifiers to PDF objects
such as pages and XObjects. By looking up digital identifiers in the database, Web
Capture can determine whether newly downloaded content is identical to content
already retrieved from a different URL. Thus, it can perform optimizations such
as storing only one copy of an image that is referenced by multiple HTML pages.
Web Capture’s content database is organized into content sets. Each content set is
a dictionary holding information about a group of related PDF objects generated
from the same source data. Content sets are of two subtypes: page sets and image
sets. When Web Capture converts an HTML file to PDF pages, for example, it cre-
ates a page set to hold information about the pages. Similarly, when it converts a
GIF image to one or more image XObjects, it creates an image set describing
those XObjects.
The content set corresponding to a given data source can be accessed in either of
two ways:
• By the URLs from which it was retrieved
• By a digital identifier generated from the source data itself (see “Digital Identi-
fiers” on page 950)
The URLS and IDS entries in a PDF document’s name dictionary (see Section 3.6.3,
“Name Dictionary”) contain name trees mapping URLs and digital identifiers, re-
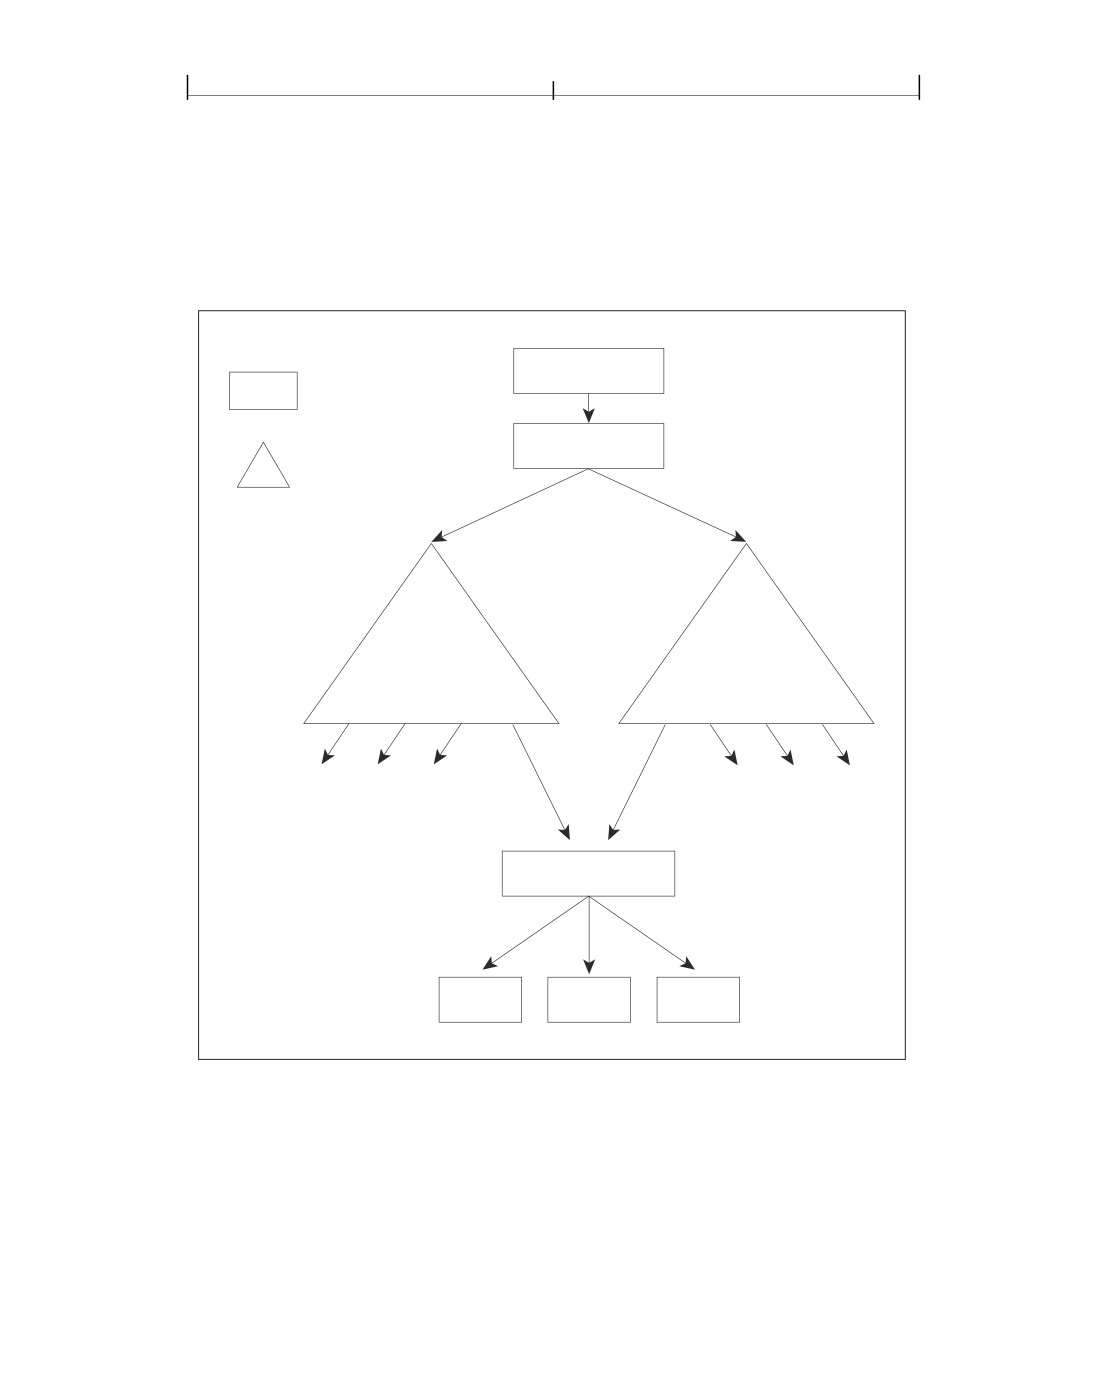
spectively, to Web Capture content sets. Figure 10.1 shows a simple example. An
948
CHAPTER 10
Document Interchange
HTML file retrieved from the URL < http://www.adobe.com/> has been converted
to three pages in the PDF file. The entry for that URL in the URLS name tree
points to a page set containing the three pages. Similarly, the IDS name tree con-
tains an entry pointing to the same page set, associated with the digital identifier
calculated from the HTML source (the string shown in the figure as 904B…1EA2).
Document catalog
Dictionary
Name dictionary
Name tree
URLS
IDS
904B…1EA2
Page set
Page
Page
Page
FIGURE 10.1 Simple Web Capture file structure
Entries in the URLS and IDS name trees may refer to an array of content sets
instead of just a single content set. The content sets need not have the same sub-
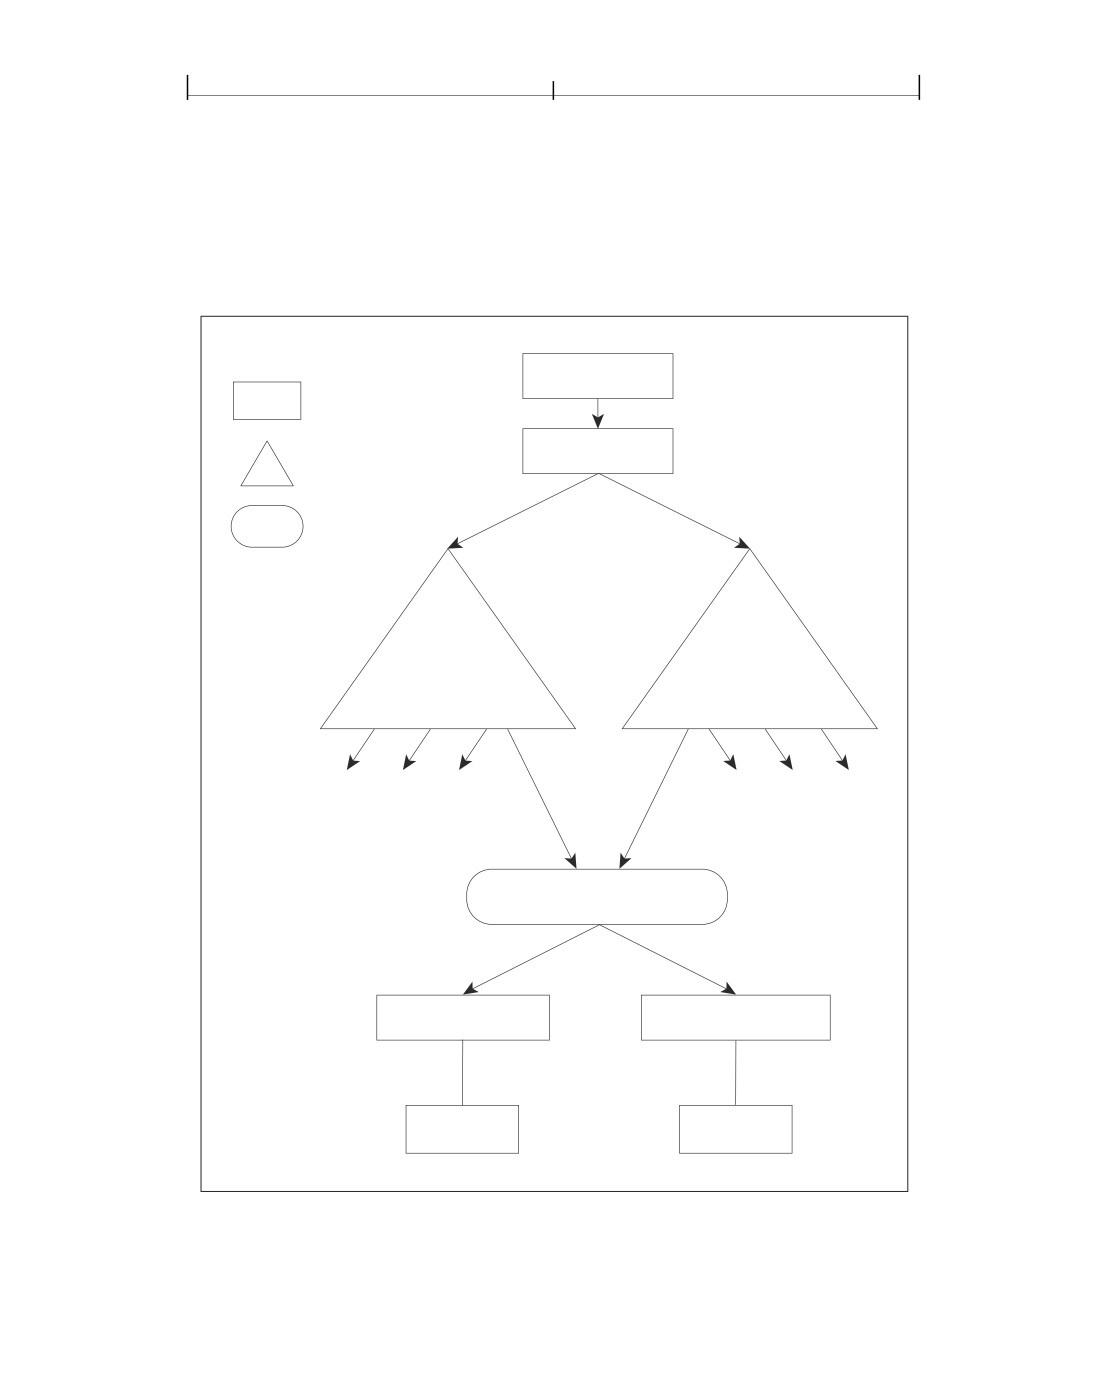
type, but may include both page sets and image sets. In Figure 10.2, for example, a
GIF file has been retrieved from a URL (< http://www.adobe.com/getacro.gif >)
949
SECTION 10.9
Web Capture
and converted to a single PDF page. As in Figure 10.1, a page set has been created
to hold information about the new page. However, since the retrieval also
resulted in a new image XObject, an image set has also been created. Instead of
pointing directly to a single content set, the URLS and IDS entries point to an
array containing both the page set and the image set.
Document catalog
Dictionary
Names dictionary
Name tree
Array
URLS
IDS
BF70…14D8
Content set array
Page set
Image set
Page
Image XObject
FIGURE 10.2 Complex Web Capture file structure
950
CHAPTER 10
Document Interchange
URL Strings
URLs associated with Web Capture content sets must be reduced to a predictable,
canonical form before being used as keys in the URLS name tree. The following
steps describe how to perform this reduction, using terminology from Internet
RFCs 1738, Uniform Resource Locators, and 1808, Relative Uniform Resource Lo-
cators (see the Bibliography). This algorithm is relevant for HTTP, FTP, and file
URLs:
1. If the URL is relative, make it absolute.
2. If the URL contains one or more number sign characters ( # ), strip the leftmost
number sign and any characters after it.
3. Convert the scheme section to lowercase ASCII.
4. If there is a host section, convert it to lowercase ASCII.
5. If the scheme is file and the host is localhost, strip the host section.
6. If there is a port section and the port is the default port for the given protocol
(80 for HTTP or 21 for FTP), strip the port section.
7. If the path section contains dot ( . ) or double-dot ( . . ) subsequences, transform
the path as described in section 4 of RFC 1808.
Note: Because the percent character ( % ) is unsafe according to RFC 1738 and is
also the escape character for encoded characters, it is not possible in general to dis-
tinguish a URL with unencoded characters from one with encoded characters. For
example, it is impossible to decide whether the sequence %00 represents a single
encoded null character or a sequence of three unencoded characters. Hence, no
number of encoding or decoding passes on a URL can ever cause it to reach a stable
state. Empirically, URLs embedded in HTML files have unsafe characters encoded
with one encoding pass, and Web servers perform one decoding pass on received
paths (though CGI scripts can make their own decisions). Canonical URLs are thus
assumed to have undergone one and only one encoding pass. A URL whose initial
encoding state is known can be safely transformed into a URL that has undergone
only one encoding pass.
Digital Identifiers
Digital identifiers associated with Web Capture content sets by the IDS name tree
are generated using the MD5 message-digest algorithm (described in Internet
951
SECTION 10.9
Web Capture
RFC 1321, The MD5 Message-Digest Algorithm; see the Bibliography). The exact
data passed to the algorithm depends on the type of content set and the nature of
the identifier being calculated.
For a page set, the source data is passed to the MD5 algorithm first, followed by
strings representing the digital identifiers of any auxiliary data files (such as im-
ages) referenced in the source data, in the order in which they are first referenced.
(If an auxiliary file is referenced more than once, its identifier is passed only the
first time.) This produces a composite identifier representing the visual appear-
ance of the pages in the page set. Two HTML source files that are identical, but
for which the referenced images contain different data—for example, if they have
been generated by a script or are pointed to by relative URLs—do not produce the
same identifier.
Note: When the source data is taken from a PDF file, the identifier is generated sole-
ly from the contents of that file; there is no auxiliary data. (See also implementation
note 164 in Appendix H.)
A page set can also have a text identifier, calculated by applying the MD5 algo-
rithm to just the rendered text present in the source data. For an HTML file, for
example, the text identifier is based solely on the text between markup tags; no
images are used in the calculation.
For an image set, the digital identifier is calculated by passing the source data for
the original image to the MD5 algorithm. For example, the identifier for an image
set created from a GIF image is calculated from the contents of the GIF.
Unique Name Generation
In generating PDF pages from a data source, Web Capture converts items such as
hypertext links and HTML form fields into corresponding named destinations
and interactive form fields. These items must have names that do not conflict
with those of existing items in the file. Also, when updating the file, Web Capture
may need to locate all destinations and fields constructed for a given page set.
Accordingly, each destination or field is given a unique name that is derived from
its original name but constructed so that it avoids conflicts with similarly named
items in other page sets.
Note: As used here, the term name refers to a string, not a name object.
952
CHAPTER 10
Document Interchange
The unique name is formed by appending an encoded form of the page set’s digi-
tal identifier string to the original name of the destination or field. The identifier
string must be encoded to remove characters that have special meaning in desti-
nations and fields. For example, since the period character ( . ) is used as the field
separator in interactive form field names, it must not appear in the identifier por-
tion of the unique name; it is therefore encoded internally as two bytes, 92 and
112, corresponding to the ASCII characters \p . Note that since the backslash
character ( \ ) has special meaning for the syntax of string objects, it must be pre-
ceded by another backslash when written in the PDF file. For example, if the orig-
inal digital identifier string were
alpha . beta
it would be encoded internally as
alpha \ pbeta
and written in the PDF file as
( alpha \ \ pbeta )
Similarly, the null character (character code 0) is encoded internally as the two
bytes 92 and 48, corresponding to the ASCII characters \0. If the original digital
identifier string were
alphaØbeta
(where Ø denotes the null character), it would be encoded internally as
alpha \ 0beta
and written in the PDF file as
( alpha \ \ 0beta )
Finally, the backslash character itself is encoded internally as the two bytes 92 and
92, corresponding to the characters \\. In written form, each of these in turn
requires a preceding backslash. Thus, the digital identifier string
alpha \ beta
would be encoded internally as
alpha \ \ beta
and written in the PDF file as
( alpha \ \ \ \ beta )
953
SECTION 10.9
Web Capture
If the name is used for an interactive form field, there is an additional encoding to
ensure uniqueness and compatibility with interactive forms. Each byte in the
source string, encoded as described above, is replaced by two bytes in the destina-
tion string. The first byte in each pair is 65 (corresponding to the ASCII character
A) plus the high-order 4 bits of the source byte; the second byte is 65 plus the low-
order 4 bits of the source byte.
10.9.3
Content Sets
A Web Capture content set is a dictionary describing a set of PDF objects gener-
ated from the same source data. It may include information common to all the
objects in the set as well as about the set itself. Table 10.38 shows the contents of
this type of dictionary.
Page Sets
A page set is a content set containing a group of PDF page objects generated from
a common source, such as an HTML file. The pages are listed in the O array (see
Table 10.38) in the same order in which they were initially added to the file. A
single page object may not belong to more than one page set. Table 10.39 shows
the content set dictionary entries specific to this type of content set.
The optional TID (text identifier) entry may be used to store an identifier gener-
ated from the text of the pages belonging to the page set (see “Digital Identifi-
ers” on page 950). This identifier may be used, for example, to determine
whether the text of a document has changed. A text identifier may not be
appropriate for some page sets (such as those with no text) and should be omit-
ted in these cases.
TABLE 10.38 Entries common to all Web Capture content sets
KEY
TYPE
VALUE
Type
name
(Optional) The type of PDF object that this dictionary describes; if present, must be
SpiderContentSet for a Web Capture content set.
S
name
(Required) The subtype of content set that this dictionary describes:
SPS
(“Spider page set”) A page set
SIS
(“Spider image set”) An image set
954
CHAPTER 10
Document Interchange
KEY
TYPE
VALUE
ID
byte string
(Required) The digital identifier of the content set (see “Digital Identifiers” on page
950). If the content set has been located by means of the URLS name tree, this allows its
related entry in the IDS name tree to be found.
O
array
(Required) An array of indirect references to the objects belonging to the content set.
The order of objects in the array is undefined in general but may be restricted by spe-
cific content set subtypes.
SI
dictionary
(Req uired) A source information dictionary (see Section 10.9.4, “Source Information”)
or array
or an array of such dictionaries, describing the sources from which the objects belong-
ing to the content set were created.
CT
ASCII string
(Optional) The content type, an ASCII string characterizing the source from which the
objects belonging to the content set were created. The string should conform to the
content type specification described in Internet RFC 2045, Multipurpose Internet Mail
Extensions (MIME) Part One: Format of Internet Message Bodies (see the Bibliography).
For example, for a page set consisting of a group of PDF pages created from an HTML
file, the content type would be text / html.
TS
date
(Optional) A time stamp giving the date and time at which the content set was created.
TABLE 10.39 Additional entries specific to a Web Capture page set
KEY
TYPE
VALUE
S
name
(Required) The subtype of content set that this dictionary describes; must be SPS (“Spi-
der page set”) for a page set.
T
text string
(Optional) The title of the page set, a text string representing it in human-readable
form.
TID
byte string
(Optional) A text identifier generated from the text of the page set, as described in
“Digital Identifiers” on page 950.
Image Sets
An image set is a content set containing a group of image XObjects generated
from a common source, such as multiple frames of an animated GIF image. (Web
Capture 4.0 always generates a single image XObject for a given image.) A single
XObject may not belong to more than one image set. Table 10.40 shows the con-
tent set dictionary entries specific to this type of content set.
955
SECTION 10.9
Web Capture
TABLE 10.40 Additional entries specific to a Web Capture image set
KEY
TYPE
VALUE
S
name
(Required) The subtype of content set that this dictionary describes; must be SIS (“Spider
image set”) for an image set.
R
integer
(Required) The reference counts (see below) for the image XObjects belonging to the im-
or array
age set. For an image set containing a single XObject, the value is simply the integer
reference count for that XObject. If the image set contains multiple XObjects, the value is
an array of reference counts parallel to the O array (see Table 10.38 on page 953); that is,
each element in the R array holds the reference count for the image XObject at the corre-
sponding position in the O array.
Each image XObject in an image set has a reference count indicating the number
of PDF pages referring to that XObject. The reference count is incremented
whenever Web Capture creates a new page referring to the XObject (including
copies of already existing pages) and decremented whenever such a page is
destroyed. (The reference count is incremented or decremented only once per
page, regardless of the number of times the XObject may be referenced by that
same page.) When the reference count reaches 0, it is assumed that there are no
remaining pages referring to the XObject and that it can be removed from the im-
age set’s O array. (See implementation note 165 in Appendix H.)
10.9.4
Source Information
The SI entry in a content set dictionary (see Table 10.38 on page 953) identifies
one or more source information dictionaries containing information about the lo-
cations from which the source data for the content set was retrieved. Table 10.41
shows the contents of this type of dictionary.
TABLE 10.41 Entries in a source information dictionary
KEY
TYPE
VALUE
AU
ASCII string
(Required) An ASCII string or URL alias dictionary (see “URL Alias Dictionaries,” be-
or dictionary
low) identifying the URLs from which the source data was retrieved.
TS
date
(Optional) A time stamp giving the most recent date and time at which the content set’s
contents were known to be up to date with the source data.
E
date
(Optional) An expiration stamp giving the date and time at which the content set’s con-
tents should be considered out of date with the source data.
956
CHAPTER 10
Document Interchange
KEY
TYPE
VALUE
S
integer
(Optional) A code indicating the type of form submission, if any, by which the source
data was accessed (see “Submit-Form Actions” on page 703):
0
Not accessed by means of a form submission
1
Accessed by means of an HTTP GET request
2
Accessed by means of an HTTP POST request
This entry should be present only in source information dictionaries associated with
page sets. Default value: 0.
C
dictionary
(Optional; must be an indirect reference) A command dictionary (see “Command Dic-
tionaries” on page 957) describing the command that caused the source data to be
retrieved. This entry should be present only in source information dictionaries associ-
ated with page sets.
In the simplest case, the content set’s SI entry just contains a single source infor-
mation dictionary. However, it is not uncommon for the same source data to be
accessible from two or more unrelated URLs. When Web Capture detects such a
condition (by comparing digital identifiers), it generates a single content set from
the source data, containing just one copy of the relevant PDF pages or image
XObjects, but creates multiple source information dictionaries describing the
separate ways in which the original source data can be accessed. It then stores an
array containing these multiple source information dictionaries as the value of
the SI entry in the content set dictionary.
A source information dictionary’s AU (aliased URLs) entry identifies the URLs
from which the source data was retrieved. If there is only one such URL, a simple
string suffices as the value of this entry. If multiple URLs map to the same loca-
tion through redirection, the AU value is a URL alias dictionary representing
them (see “URL Alias Dictionaries,” below).
Note: For file size efficiency, it is recommended that the entire URL alias dictionary
(excluding the URL strings) be represented as a direct object because its internal
structure should never be shared or externally referenced.
The TS (time stamp) entry allows each source location associated with a content
set to have its own time stamp. This is necessary because the time stamp in the
content set dictionary (see Table 10.38 on page 953) merely refers to the creation
date of the content set. A hypothetical “Update Content Set” command might re-
set the time stamp in the source information dictionary to the current time if it
found that the source data had not changed since the time stamp was last set.
957
SECTION 10.9
Web Capture
The E (expiration) entry specifies an expiration date for each source location
associated with a content set. If the current date and time are later than those
specified, the contents of the content set should be considered out of date with
the original source.
URL Alias Dictionaries
When a URL is accessed via HTTP, a response header may be returned indicating
that the requested data is at a different URL. This redirection process may be re-
peated in turn at the new URL and can potentially continue indefinitely. It is not
uncommon to find multiple URLs that all lead eventually to the same destination
through one or more redirections. A URL alias dictionary represents such a set of
URL chains leading to a common destination. Table 10.42 shows the contents of
this type of dictionary.
TABLE 10.42 Entries in a URL alias dictionary
KEY
TYPE
VALUE
U
ASCII
(Required) The destination URL to which all of the chains specified by the C entry lead.
string
C
array
(Optional) An array of one or more arrays of strings, each representing a chain of URLs
leading to the common destination specified by U.
The C (chains) entry should be omitted if the URL alias dictionary contains only
one URL. If C is present, its value is an array of arrays, each representing a chain
of URLs leading to the common destination. Within each chain, the URLs are
stored as ASCII strings in the order in which they occur in the redirection se-
quence. The common destination (the last URL in a chain) may be omitted, since
it is already identified by the U entry. (See implementation note 166 in Appendix
H.)
Command Dictionaries
A Web Capture command dictionary represents a command executed by Web
Capture to retrieve one or more pieces of source data that were used to create new
pages or modify existing pages. The entries in this dictionary represent
parameters that were originally specified interactively by the user who requested
that the Web content be captured. This information is recorded so that the com-
958
CHAPTER 10
Document Interchange
mand can subsequently be repeated to update the captured content. Table 10.43
shows the contents of this type of dictionary.
TABLE 10.43 Entries in a Web Capture command dictionary
KEY
TYPE
VALUE
URL
ASCII string
(Required) The initial URL from which source data was requested.
L
integer
(Optional) The number of levels of pages retrieved from the initial URL. Default
value: 1.
F
integer
(Optional) A set of flags specifying various characteristics of the command (see
Table 10.44). Default value: 0.
P
string or stream
(Optional) Data that was posted to the URL.
CT
ASCII string
(Optional) A content type describing the data posted to the URL. Default value:
application / x−www−form−urlencoded.
H
string
(Optional) Additional HTTP request headers sent to the URL.
S
dictionary
(Optional) A command settings dictionary containing settings used in the con-
version process (see “Command Settings” on page 960).
The URL entry specifies the initial URL for the retrieval command. The L (levels)
entry specifies the number of levels of pages requested to be retrieved from this
URL. If the L entry is omitted, its value is assumed to be 1, denoting retrieval of
the initial URL only.
The value of the command dictionary’s F entry is an unsigned 32-bit integer con-
taining flags specifying various characteristics of the command. Bit positions
within the flag word are numbered from 1 (low-order) to 32 (high-order).
Table 10.44 shows the meanings of the flags; all undefined flag bits are reserved
and must be set to 0.
TABLE 10.44 Web Capture command flags
BIT POSITION
NAME
MEANING
1
SameSite
If set, pages were retrieved only from the host specified in the initial URL.
2
SamePath
If set, pages were retrieved only from the path specified in the initial URL
(see below).
959
SECTION 10.9
Web Capture
BIT POSITION
NAME
MEANING
3
Submit
If set, the command represents a form submission (see below).
The SamePath flag, if set, indicates that pages were retrieved only if they were in
the same path specified in the initial URL. A page is considered to be in the same
path if its scheme and network location components (as defined in Internet RFC
1808, Relative Uniform Resource Locators) match those of the initial URL and its
path component matches up to and including the last forward slash ( / ) character
in the initial URL. For example, the URL
http : / / www. adobe . com / fiddle / faddle / foo . html
is considered to be in the same path as the initial URL
http : / / www. adobe . com / fiddle / initial . html
The comparison is case-insensitive for the scheme and network location compo-
nents and case-sensitive for the path component.
If the Submit flag is set, the command represents a form submission. If no P
(posted data) entry is present, the submitted data is encoded in the URL (an
HTTP GET request). If P is present, the command represents an HTTP POST
request. In this case, the value of the Submit flag is ignored. If the posted data is
small enough, it may be represented by a string. For large amounts of data, a
stream is recommended because it can be compressed.
The CT (content type) entry is relevant only for POST requests. It describes the
content type of the posted data, as described in Internet RFC 2045, Multipurpose
Internet Mail Extensions (MIME), Part One: Format of Internet Message Bodies
(see the Bibliography).
The H (headers) entry specifies additional HTTP request headers that were sent
in the request for the URL. Each header line in the string is terminated with a car-
riage return and a line feed, as in this example:
( Referer : http : / / frumble . com \ 015 \ 012From : veeble @ frotz . com \ 015 \ 012 )
The HTTP request header format is specified in Internet RFC 2616, Hypertext
Transfer Protocol—HTTP/1.1 (see the Bibliography).
960
CHAPTER 10
Document Interchange
The S (settings) entry specifies a command settings dictionary (see the next sec-
tion). Holding settings specific to the conversion engines. If this entry is omitted,
default values are assumed. It is recommended that command settings dictionar-
ies be shared by any command dictionaries that use the same settings.
Command Settings
The S (settings) entry in a command dictionary contains a command settings
dictionary, which holds settings for conversion engines used in converting the
results of the command to PDF. Table 10.45 shows the contents of this type of dic-
tionary.
TABLE 10.45 Entries in a Web Capture command settings dictionary
KEY
TYPE
VALUE
G
dictionary
(Optional) A dictionary containing global conversion engine settings relevant to all con-
version engines. If this entry is absent, default settings are used.
C
dictionary
(Optional) Settings for specific conversion engines. Each key in this dictionary is the
internal name of a conversion engine (see below). The associated value is a dictionary
containing the settings associated with that conversion engine. If the settings for a par-
ticular conversion engine are not found in the dictionary, default settings are used.
Each key in the C dictionary is the internal name of a conversion engine, which
should be a name object of the following form:
/ company : product : version : contentType
where
company is the name (or abbreviation) of the company that created the conver-
sion engine.
product is the name of the conversion engine. This field may be left blank, but
the trailing colon character ( : ) is still required.
version is the version of the conversion engine.
contentType is an identifier for the content type that the settings are associated
with. This is required because some converters may handle multiple content
types.
961
SECTION 10.9
Web Capture
For example:
/ ADBE : H2PDF : 1 . 0 : HTML
Note that all fields in the internal name are case-sensitive. The company field
must conform to the naming guidelines described in Appendix E. The values of
the other fields are unrestricted, except that they must not contain a colon.
Note: It must be possible to make a deep copy of a command settings dictionary
without explicit knowledge of the settings it may contain. To facilitate this operation,
the directed graph of PDF objects rooted by the command settings dictionary must
be entirely self-contained; that is, it must not contain any object referred to from
elsewhere in the PDF file.
10.9.5
Object Attributes Related to Web Capture
A given page object or image XObject can belong to at most one Web Capture
content set, called its parent content set. However, the object has no direct pointer
to its parent content set. Such a pointer might present problems for an application
that traces all pointers from an object to determine, for example, what resources
the object depends on. Instead, the object’s ID entry (see Table 3.27 on page 145
and Table 4.39 on page 340) contains the digital identifier of the parent content
set, which can be used to locate the parent content set via the IDS name tree in the
document’s name dictionary. (If the IDS entry for the identifier contains an array
of content sets, the parent can be found by searching the array for the content set
whose O entry includes the child object.)
In the course of creating PDF pages from HTML files, Web Capture frequently
scales the contents down to fit on fixed-sized pages. The PZ (preferred zoom)
entry in a page object (see “Page Objects” on page 144) specifies a magnification
factor by which the page can be scaled to undo the downscaling and view the
page at its original size. That is, when the page is viewed at the preferred magnifi-
cation factor, one unit in default user space corresponds to one original source
pixel.
962
CHAPTER 10
Document Interchange
10.10
Prepress Support
This section describes features of PDF that support prepress production work-
flows:
• The specification of page boundaries governing various aspects of the prepress
process, such as cropping, bleed, and trimming (Section 10.10.1, “Page Bound-
aries”)
• Facilities for including printer’s marks, such as registration targets, gray ramps,
color bars, and cut marks to assist in the production process (Section 10.10.2,
“Printer’s Marks”)
• Information for generating color separations for pages in a document (Section
10.10.3, “Separation Dictionaries”)
• Output intents for matching the color characteristics of a document with those
of a target output device or production environment in which it will be printed
(Section 10.10.4, “Output Intents”)
• Support for the generation of traps to minimize the visual effects of misregis-
tration between multiple colorants (Section 10.10.5, “Trapping Support”)
• The Open Prepress Interface (OPI) for creating low-resolution proxies for high-
resolution images (Section 10.10.6, “Open Prepress Interface (OPI)”)
10.10.1
Page Boundaries
A PDF page may be prepared either for a finished medium, such as a sheet of
paper, or as part of a prepress process in which the content of the page is placed
on an intermediate medium, such as film or an imposed reproduction plate. In
the latter case, it is important to distinguish between the intermediate page and
the finished page. The intermediate page may often include additional
production-related content, such as bleeds or printer marks, that falls outside the
boundaries of the finished page. To handle such cases, a PDF page can define as
many as five separate boundaries to control various aspects of the imaging
process:
• The media box defines the boundaries of the physical medium on which the
page is to be printed. It may include any extended area surrounding the
finished page for bleed, printing marks, or other such purposes. It may also
Большое спасибо!
Ваше мнение очень важно для нас.
Нет комментариевНе стесняйтесь поделиться с нами вашим ценным мнением.
Текст